
Inspired by "Jev" (1), an AI model specialized in decision-making, a number of downloadable open-weight Jev models—which I will refer to here as Open-Jev—have been emerging. Today, I will pick five Open-Jev models and compare them with the original Jev to examine their characteristics. Since open-weight models can be downloaded and run on your local PC, there is zero cost compared to using Jev via an API, and all data remains entirely on your local PC. Consequently, they can be used even in environments with strict security requirements, making them extremely convenient. Without further ado, let's get started.
1.What is Open-Jev?
AI models specialized in tasks that answer through intuitive judgment are sometimes called "System one" models. Jev, which debuted on September 15, 2026, is a prime example of such a model. Since then, several open-weight models with capabilities similar to Jev have emerged. While their architectures are not necessarily similar to Jev's, I refer to these open-weight System 1 models as Open-Jev and plan to use them going forward. For this experiment, I have lined up five Open-Jev models available on Ollama (2), as shown below.
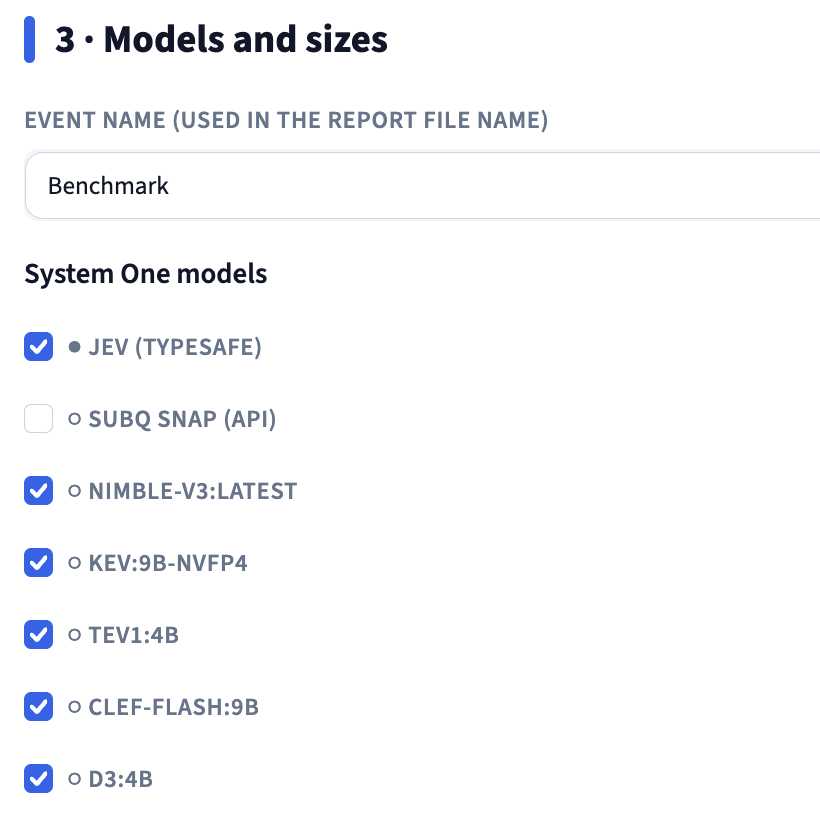
Let's immediately test how close these five Open-Jev models can get to the original Jev in terms of accuracy and computation speed.
2.Experimenting with Bank Complaint Analysis
The task we are tackling this time is an experiment analyzing 100 samples of customer complaints submitted to a bank to determine which financial product each individual complaint pertains to (3). Although I have conducted this experiment before, this is my first time trying it with Open-Jev models. Because it is a task that can be answered intuitively, I believe it is well-suited for Open-Jev, which are System one models. The actual prompt used is shown below. Since the complaints are written in English, the prompt is also in English. This prompt was automatically generated by a Large Language Model (LLM) after reading the sample data to match its content.
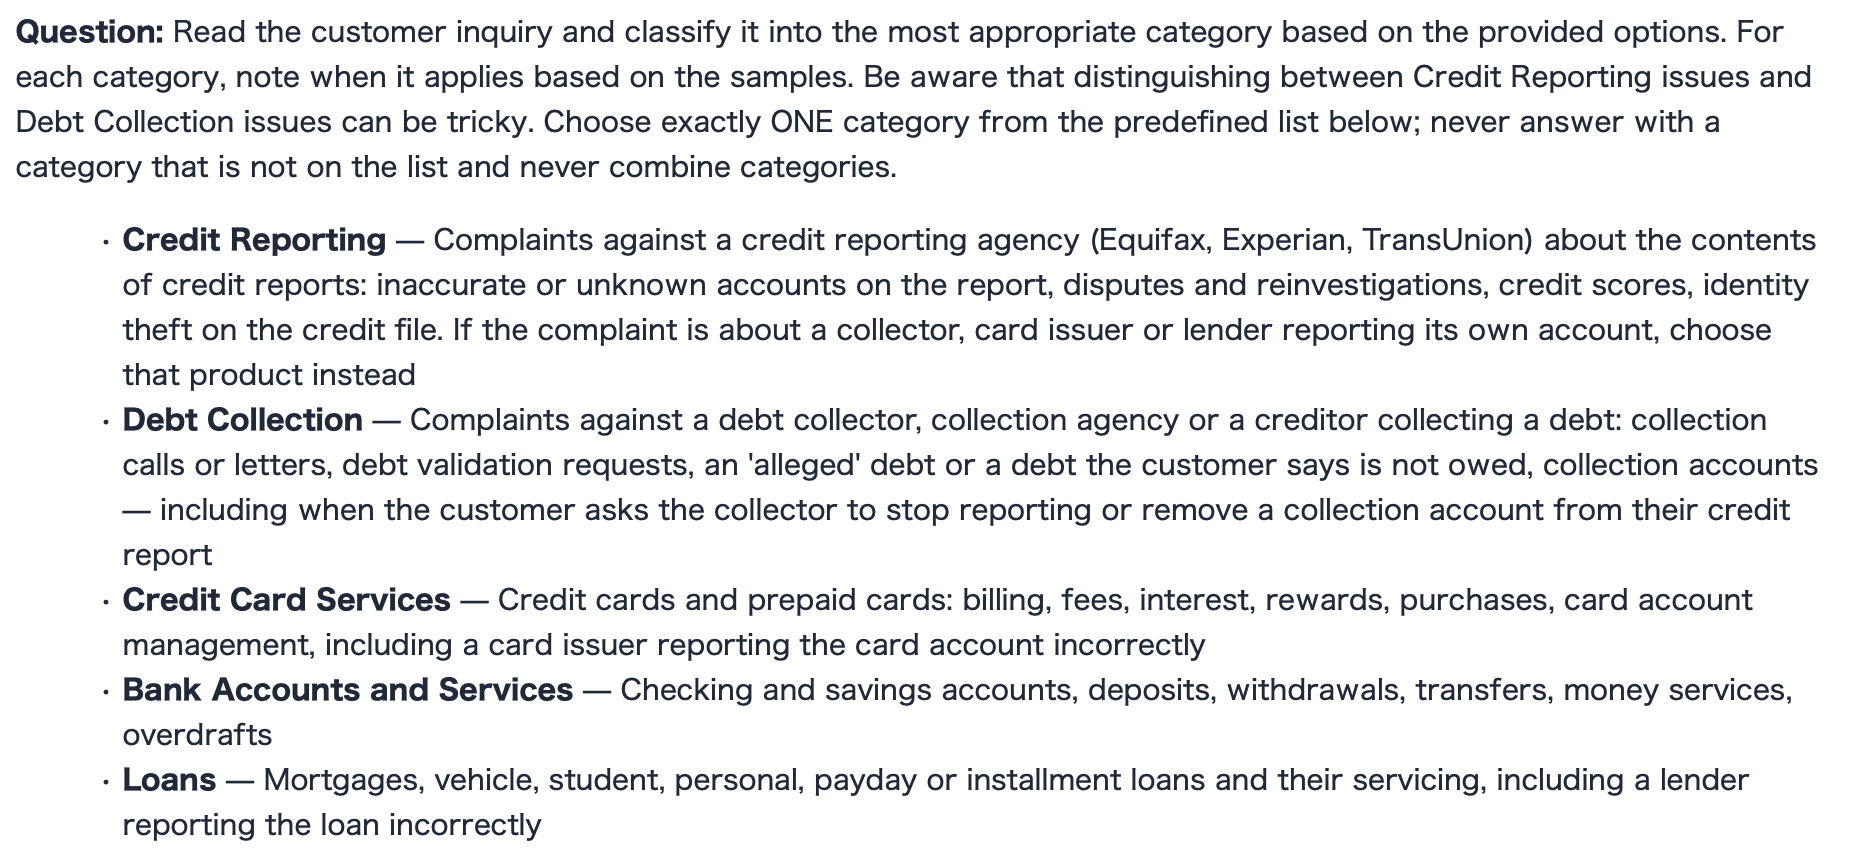
Prompt
The 100 customer complaint samples used this time contain an equal distribution of the five financial products mentioned above. Let's see how well Open-Jev can identify which of the five financial products each customer complaint is directed at.
3.Accuracy, Computation Speed, and Confidence Score
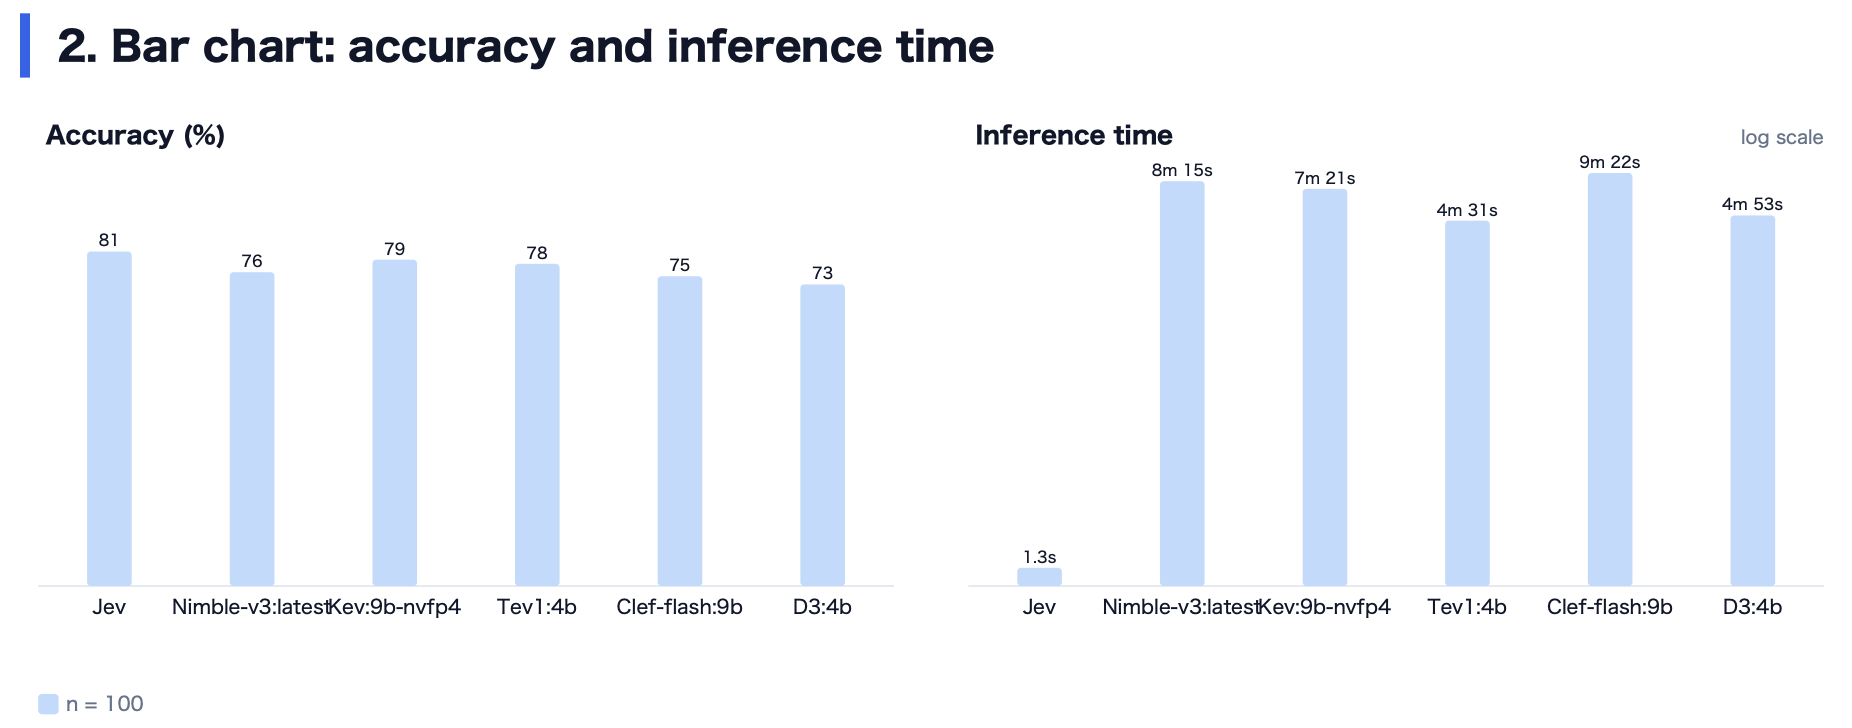
Now let's look at the experimental results. First, regarding accuracy, Jev took the top spot with 81% accuracy. That is to be expected from the original model. Most of the other Open-Jev models achieved accuracy in the high 70% range. I think they put up a very good fight. However, in terms of computation speed, while Jev took about one-hundredth of a second per sample, even the fastest Open-Jev model, Tev1:4B, took 2.7 seconds, requiring significantly more time. Here, the original Jev won by a landslide. That said, Open-Jev runs on a local PC, and this computation speed depends on the hardware used for this experiment—a MacBook Air M4 with 24GB of RAM. Naturally, as hardware performance improves, the speed will also increase, so that point needs to be taken into account.
For System one models, accuracy is not the only thing that matters. How confidently a decision is output—referred to as the "confidence score" or "reliability"—is crucial when advancing AI-driven workflow automation. Here, I will benchmark against Jev to see what characteristics each Open-Jev model possesses.
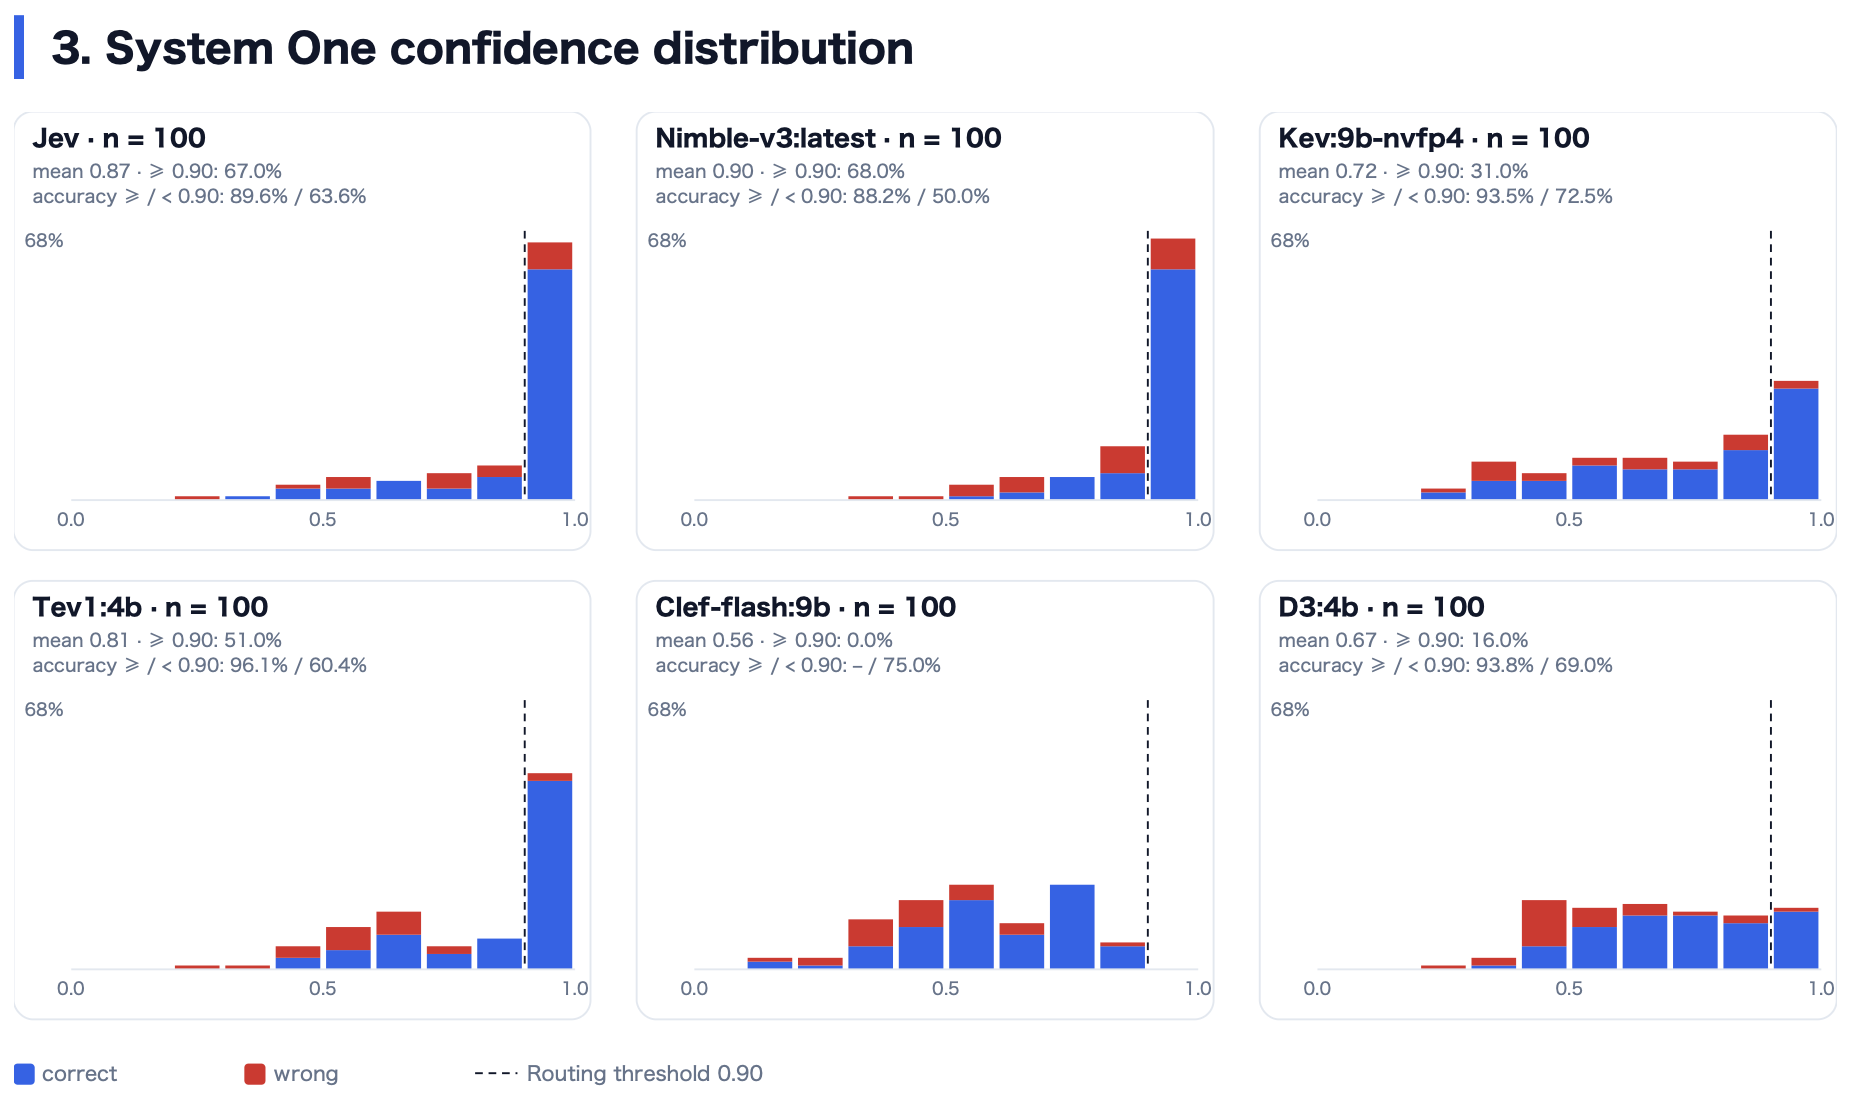
First, let's look at the confidence distribution of Jev in the upper left. The horizontal axis of the graph represents the confidence score, with each sample assigned a value between 0.0 and 1.0. There is a tall bar on the right side of the graph, which represents the distribution of samples with a confidence score of 0.9 or higher. This bar contains 67% of the total samples, meaning that if a threshold is set at a confidence score of 0.9, more than two-thirds of the samples will fall into this category. Blue indicates correct answers, while red indicates errors. Since the rightmost bar is not entirely blue, the accuracy is not 100%, but there is no doubt that it boasts high accuracy. It can be inferred that at a confidence threshold of 0.9, Jev clearly distinguishes between confident decisions and uncertain ones.
The models with confidence distributions similar to Jev are Nimble-v3:latest and Tev1:4b. Both include over 50% of the samples at the 0.9 confidence threshold, and the accuracy of those samples is also high. The other Open-Jev models have flatter confidence distributions, suggesting they are unable to effectively separate confident decisions at a confidence level of 0.9 or above. Therefore, to advance AI-driven automation, choosing either Nimble-v3:latest or Tev1:4b would be ideal. Please see here for more detailed experimental results.
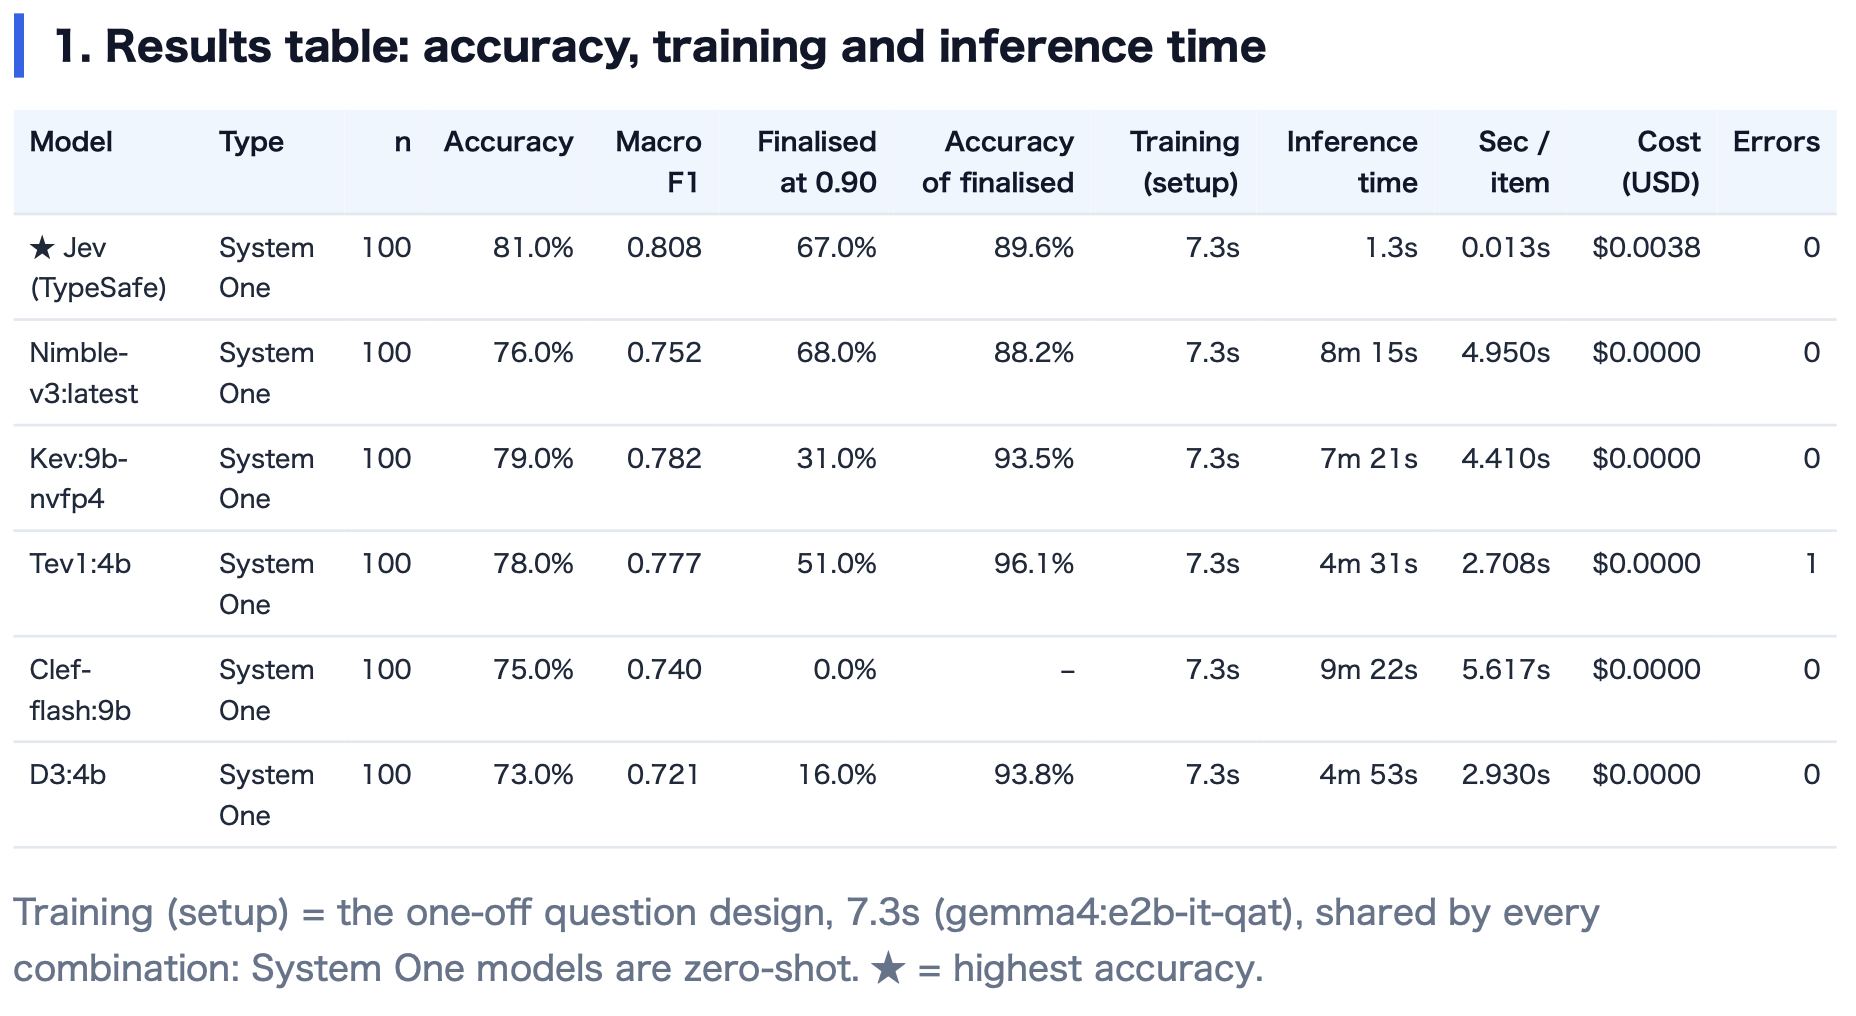
What did you think? I believe Open-Jev demonstrated performance comparable to the original Jev. Currently, since Jev can only be used via an API, there are likely many cases where it cannot be used in environments with strict security requirements. In such situations, considering Open-Jev is well worth it. The fact that it incurs no cost is another advantage. To increase computation speed, however, it will likely be necessary to prepare a high-powered GPU.
The development of Open-Jev has only just begun. As high-performance models are expected to emerge one after another in the future, we at Toshi Stats intend to actively adopt Open-Jev as well. Stay tuned!
You can enjoy our video news “ToshiStats AI Weekly Review” from this link.
1) Introducing System One Models & Jev, Sep 15 2026, Diogo Almeida, founder, TypeSafe
2) Ollama now supports Jev-style decision models, Sep 29, 2026
3) Consumer Financial Protection Bureau
Copyright © 2026 ToshiStats Co., Ltd. All right reserved.
Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.