Why "Jev-as-a-Judge" is a Game Changer for AI-Driven Automation

A "System One Model" known as "Jev" (1) is currently drawing significant attention, leading many to suggest that full-scale AI-driven automation is about to begin. In this article, taking the classification of bank customer complaints as our theme, we explore how applying "Jev" can make automation successful.


1.Measuring Prediction Accuracy

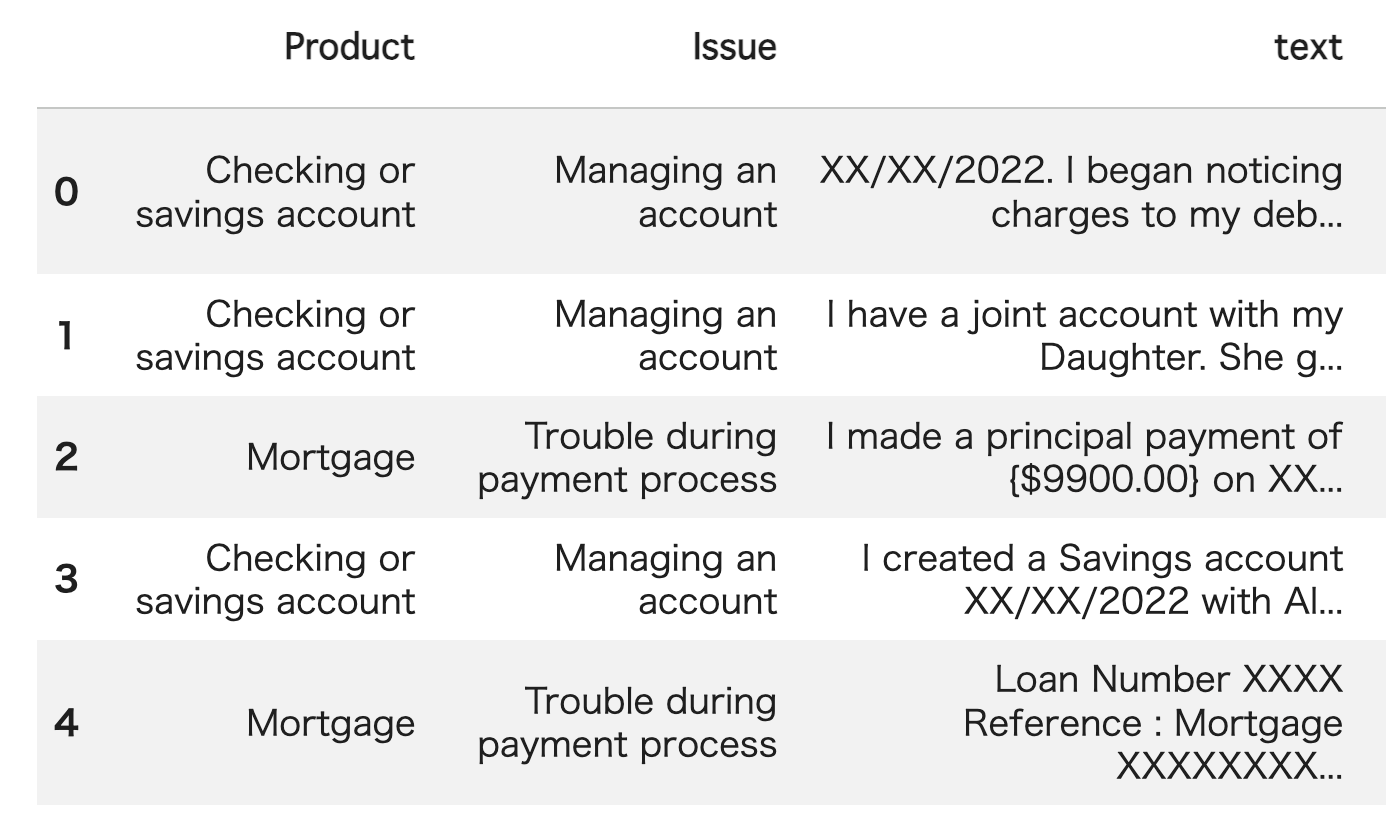
The dataset prepared for this evaluation consists of US bank customer complaints (2). Using "Jev," we tackled a classification task to predict which financial product each individual complaint pertains to. We built a prediction application as shown below and compared the accuracy across five AI models, including "Jev."
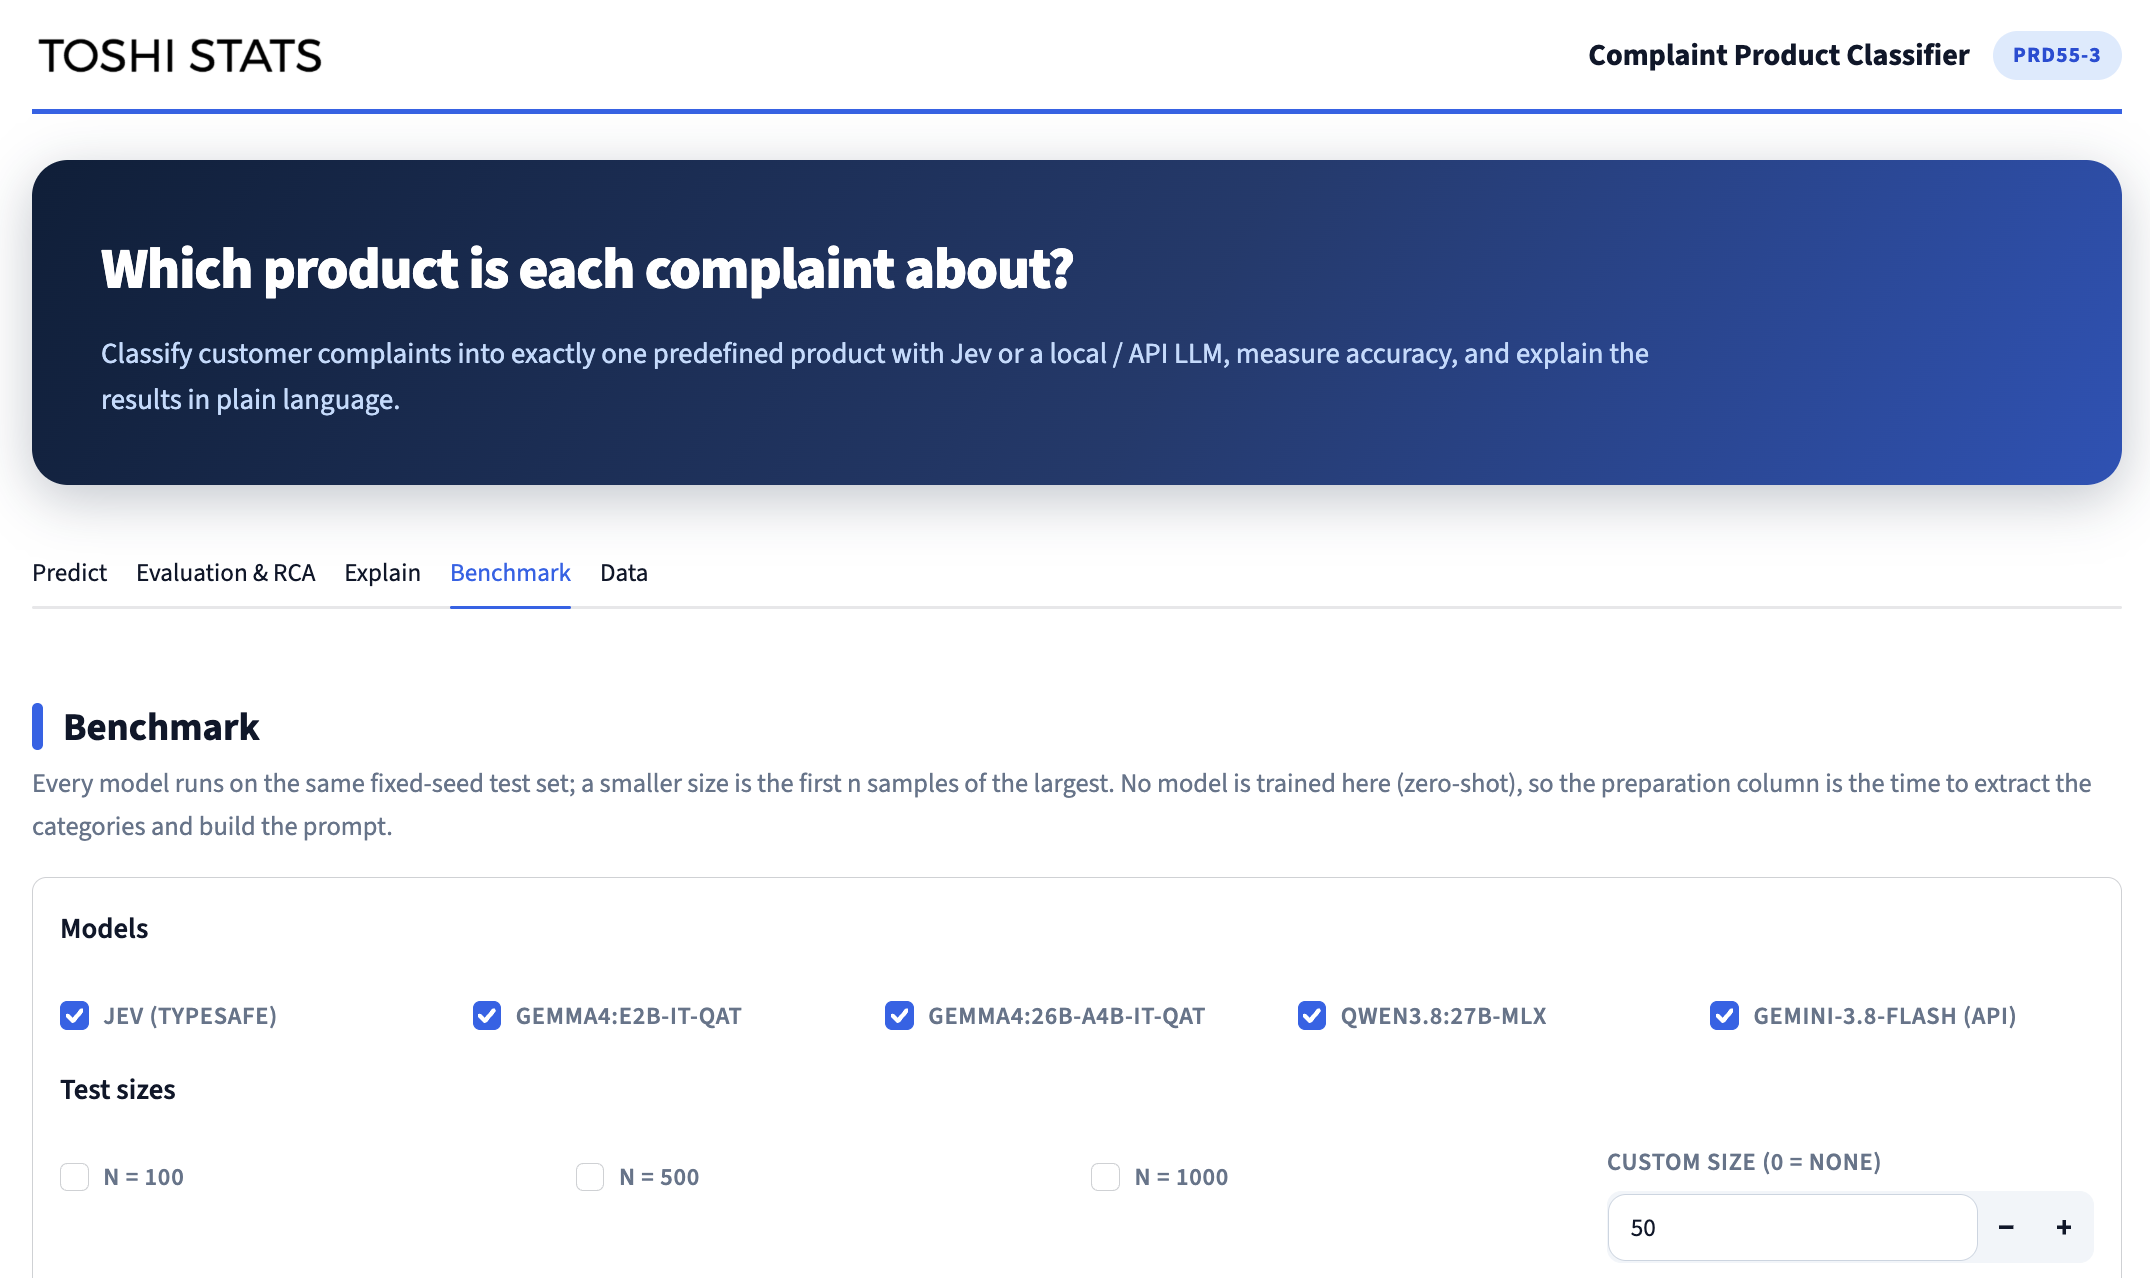
The task requires selecting one out of the following six financial products. A total of 50 samples were classified.
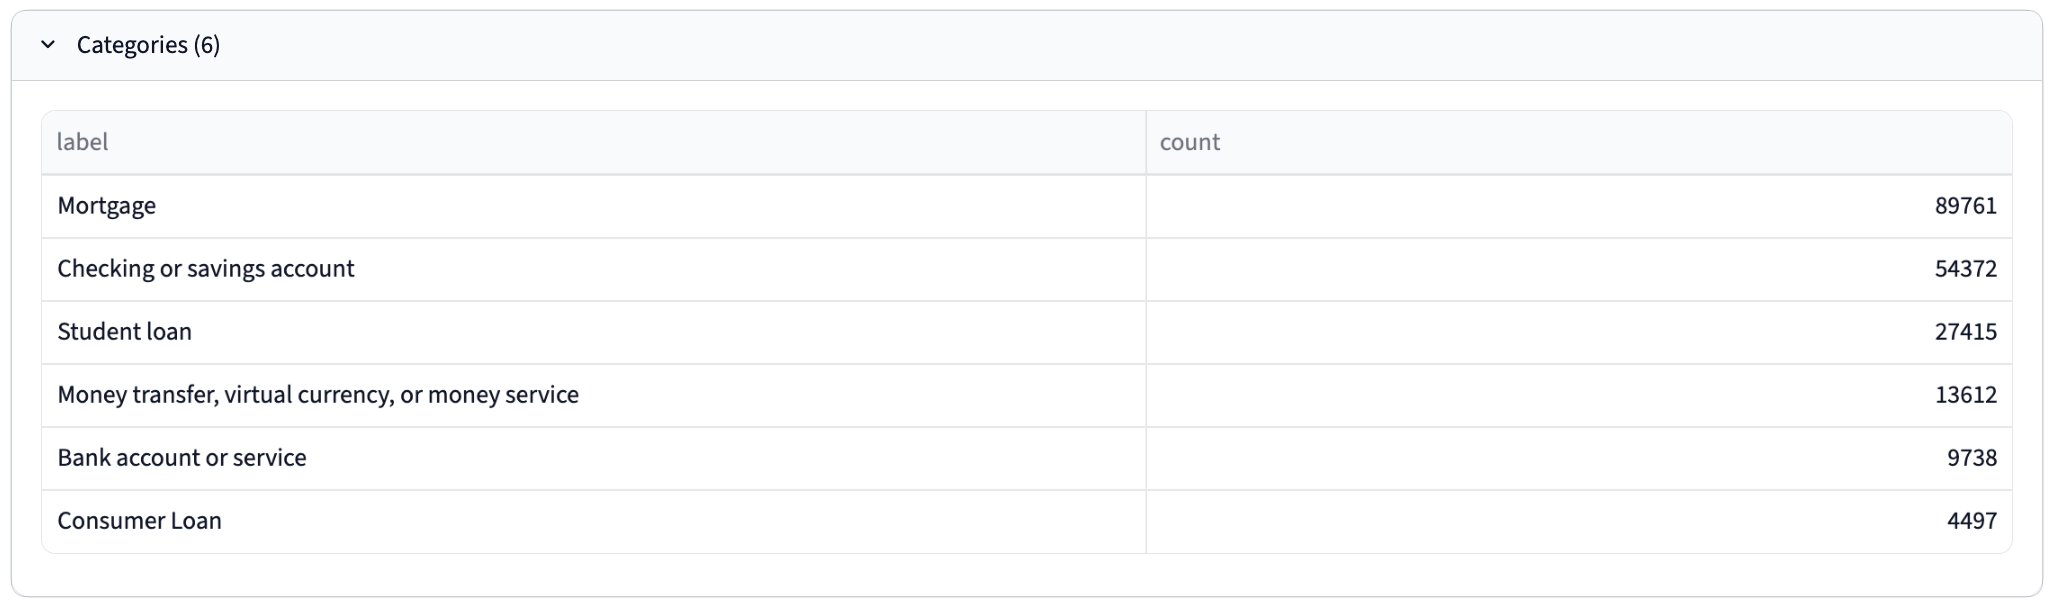
List of financial products to choose from

As shown below, "Jev" achieved an accuracy of 90%, standing toe-to-toe with the other models, while completely outperforming them in computational speed. The architecture—which returns only the prediction result without generating natural language text—is clearly proving effective here. Truly impressive.
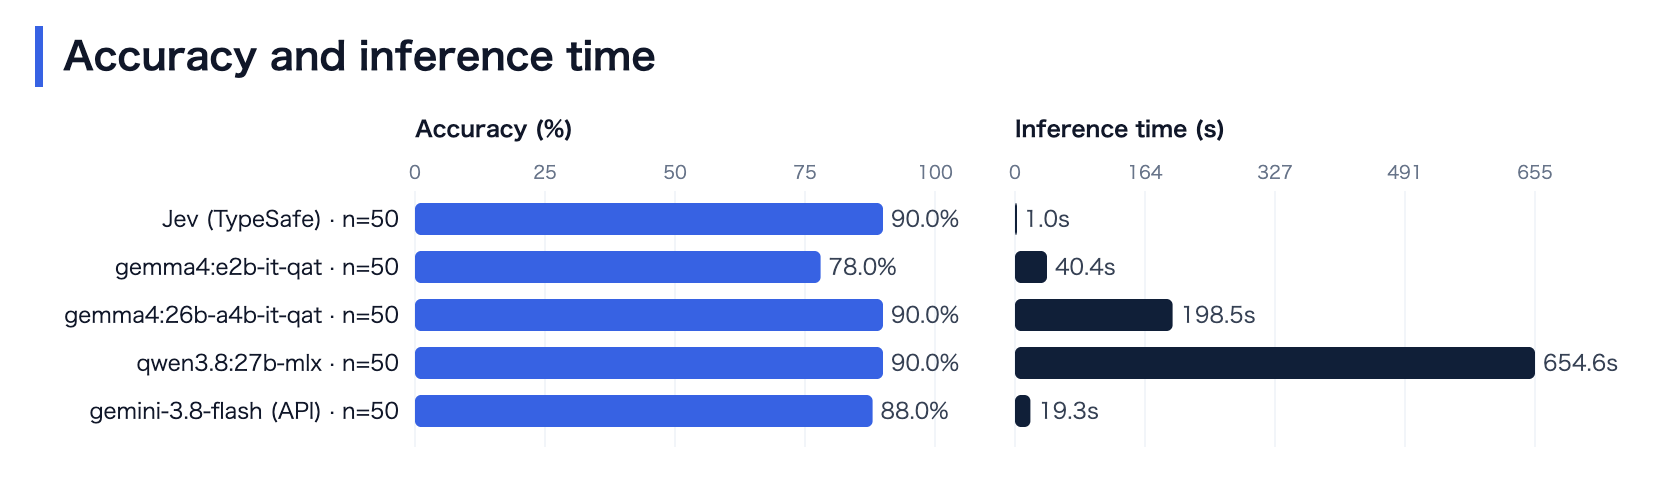
Comparison with other AI models


2. Identifying Target Samples for Automation Using Prediction Confidence

A major feature of "Jev" is its ability to simultaneously calculate a prediction confidence score. For predictions made with high certainty, the confidence score approaches 1. Therefore, we use this confidence metric to select only the samples about which "Jev" is genuinely confident as targets for automation. In this test, 1,000 samples were evaluated. We set only the samples with a confidence score of 1 as candidates for automation. The qualifying sample count was 788, yielding an accuracy of 95.1%. While this accuracy is already solid, mapping legacy category names that "Jev" did not select to their updated counterparts (as product names were updated over the course of the long-term data collection period) brings the accuracy up to 98.2%. In other words, the error rate for samples targeted for automation drops below 2%, making them ideal candidates for automated processing. A summary of the results is shown below
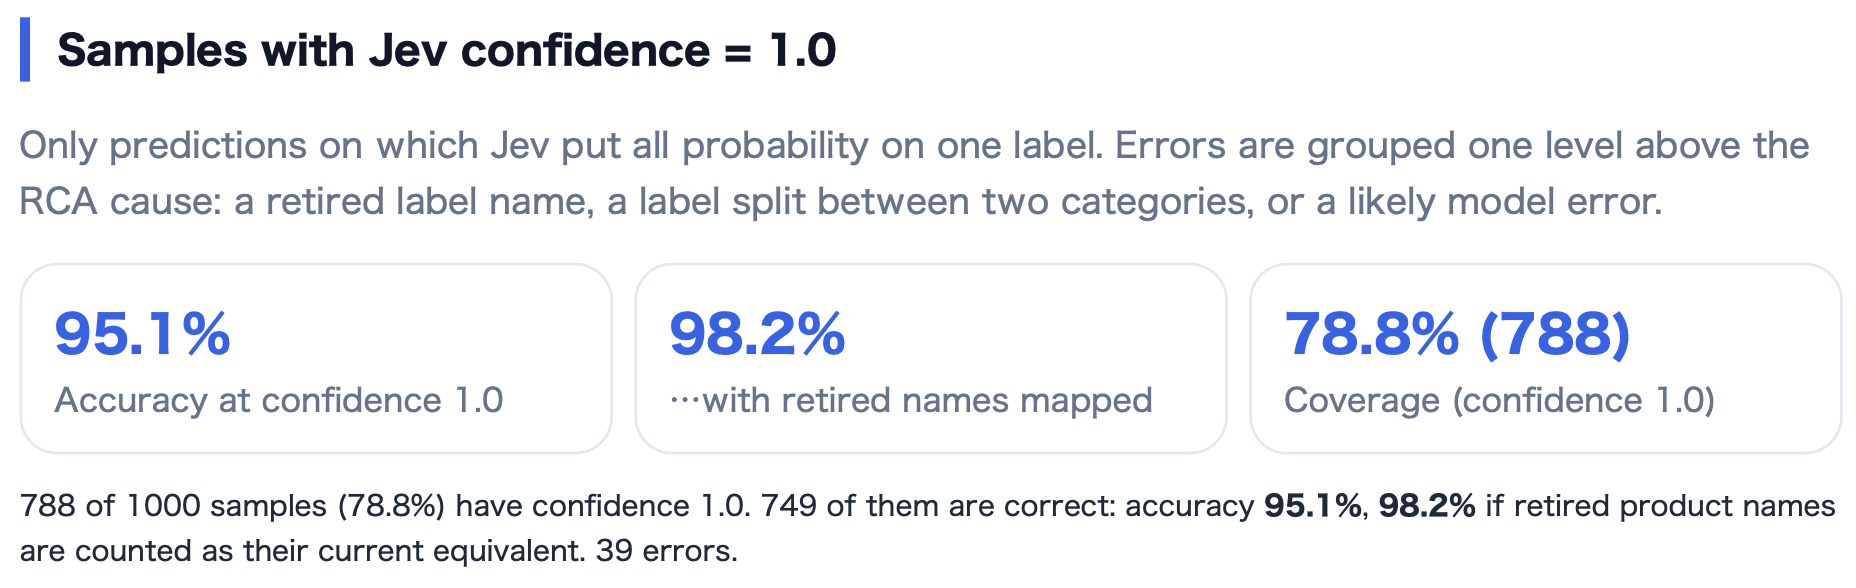
Analysis results for samples with confidence = 1


3.Implementation Workflow for AI-Driven Automation

We found that "Jev" can effectively identify which samples to automate. In this experiment, samples with a confidence score of 1 accounted for roughly 80% of the total, with an error rate of about 2%. By designing an operation that routes the remaining 20% to human review (Human-in-the-loop), an operational productivity boost of approximately 5x compared to pre-automation levels can be expected. Naturally, results depend on the incoming data, and several points require evaluation—such as whether a 2% error rate is acceptable. Nevertheless, as the precision of confidence scoring is expected to improve in the future, right now is the best time to consider automation powered by "Jev." The automation workflow is as follows
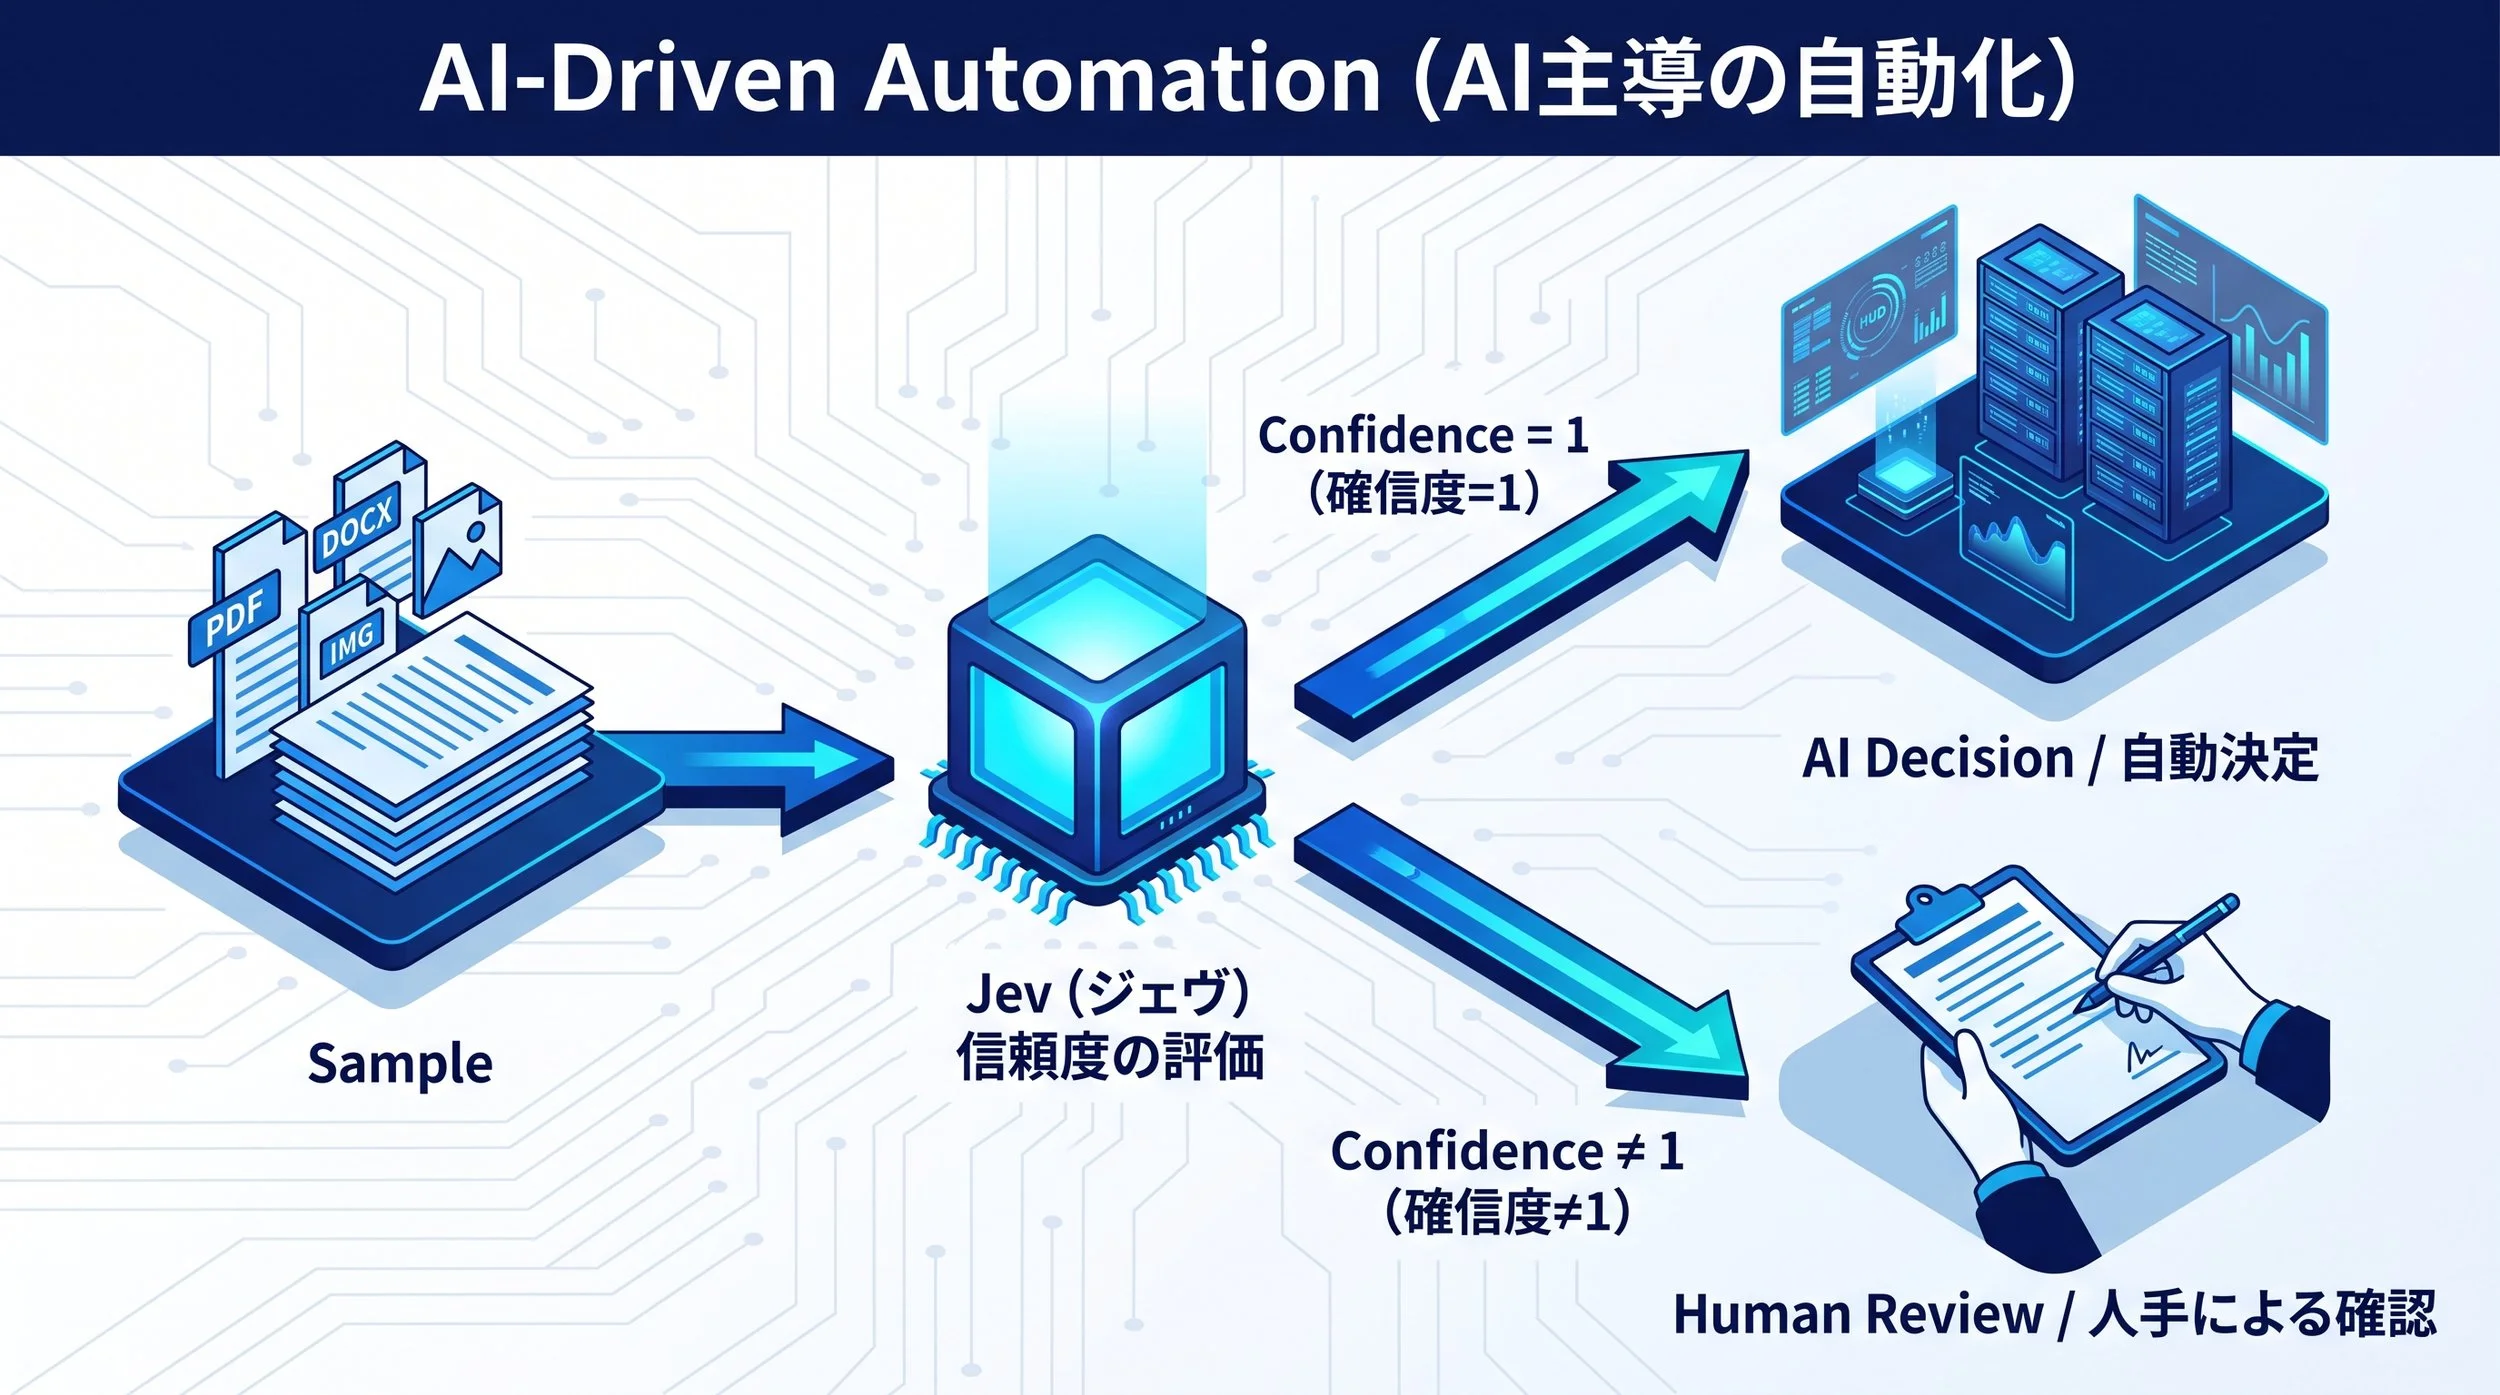
Automation workflow using "Jev"


What did you think? Entrusting decision-making tasks to Jev in place of humans is referred to as "Jev-as-a-Judge." As the accuracy of "Jev-as-a-Judge" continues to advance, business process automation driven by AI may take substantial leaps forward. There is plenty of reason for optimism.


Here at Toshi Stats, we plan to continue exploring various applications of "Jev-as-a-Judge." Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link.

1) Introducing System One Models & Jev, August 15 2026, Diogo Almeida, founder, TypeSafe
2) Consumer Financial Protection Bureau

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Is the Era of True AI Automation Already Upon Us?

"Jev," a frontier model developed with business workflow automation in mind, has been released by TypeSafe AI (1) and has become a hot topic in the AI community. Rather than generating text like traditional LLMs, it is designed from the ground up to be used for classification and discriminative tasks aimed at decision-making. Today, I'd like to take a look at it right away and explore how it can be utilized in practical business operations.


1. Features of "Jev"

First, let’s take a look at TypeSafe AI's website:

TypeSafe AI is releasing our first System One Model: a new class of frontier models built to make fast, structured decisions that software can use directly.

Our first public model is Jev, available today in early access.

As stated, "fast, structured decisions" appears to be the key phrase. When considering workflow automation, the required output for each task is often not a paragraph of text, but rather a determination of "whether it meets specific requirements or not," along with a confidence score. For example, when a financial institution receives a document from a customer, it needs to determine whether it is a complaint. The outcome is a binary choice: "Complaint" or "Not a Complaint." Special handling is required only if it is classified as a "Complaint." No generated prose is needed in the output. In this way, "Jev" is a frontier model specialized for decision-making and is optimized for business process automation.

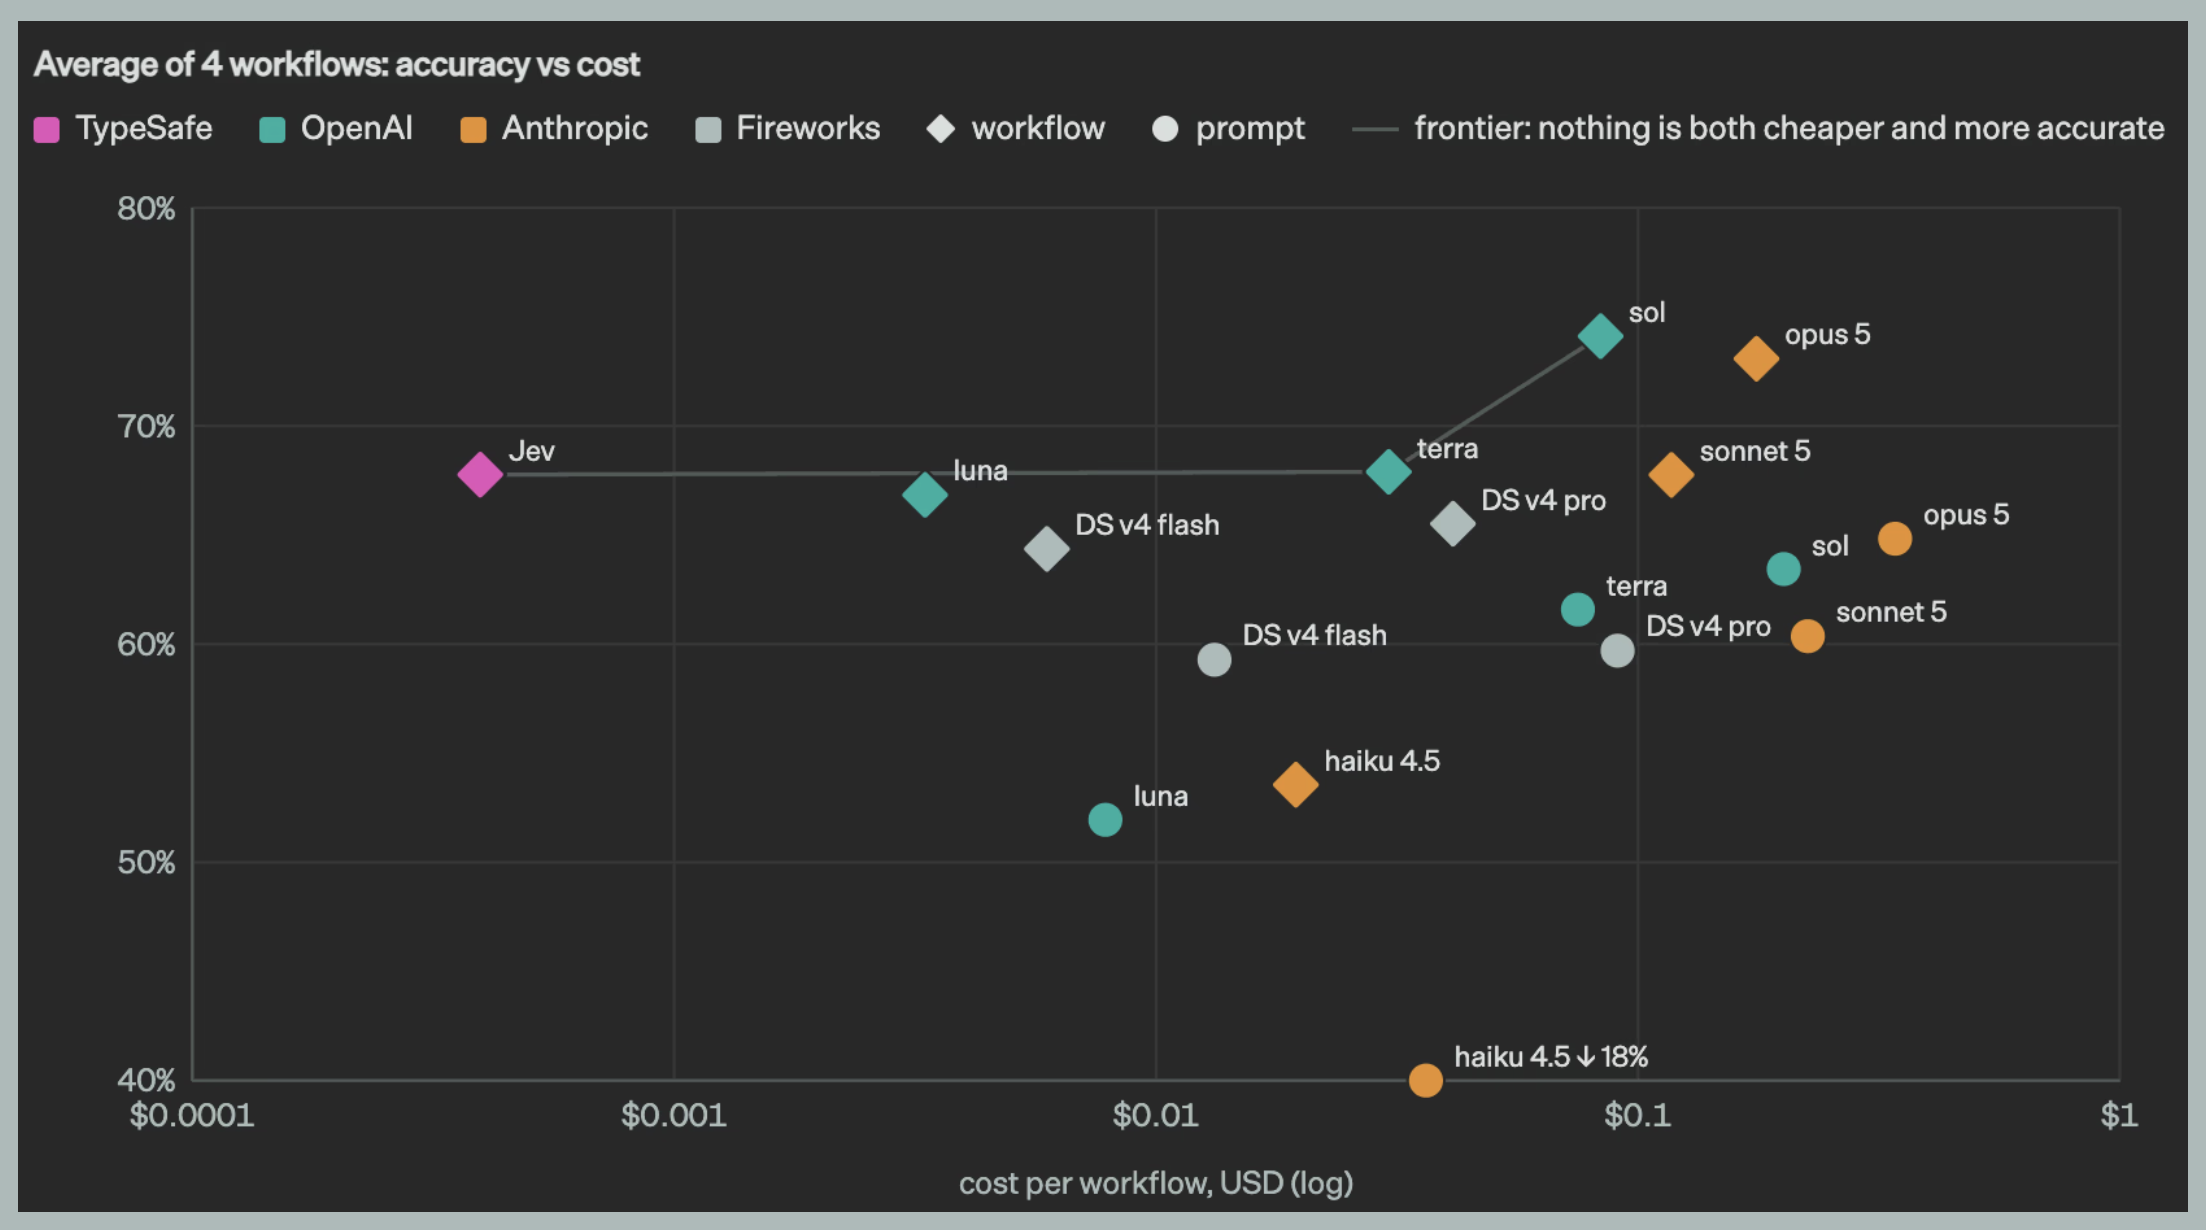
So, how accurate is "Jev"? TypeSafe AI ran several models, including "Jev," through identical workflows to evaluate how they perform compared to the average of the most capable models (in this case, Astra and Fable). Below is the comparison chart. You can see that "Jev" is positioned at the far top-left, indicating that it maintains high performance at a very low cost.

Accuracy and Cost


2. Reliability Is Key to Full Automation

High performance at low cost makes it ideal for workflow automation. However, to achieve full automation without human intervention, the issue of "hallucinations" must be resolved. This refers to generative AI unintentionally producing false information. Although recent LLMs have seen improvements, hallucinations have not dropped to zero. As things stand, human review remains indispensable. TypeSafe AI claims that "Jev" can reduce errors to zero, as outlined below. The following note appears on TypeSafe AI’s website:

Our number is not empirical. Schema matching is guaranteed, thus we can confidently add 0% into the plots.

Error Rate Comparison

If this is true, it will be a game changer for workflow automation. Feedback and evaluations from various users will be eagerly anticipated going forward. It certainly looks promising.


3. Applying Workflow Automation to Any Scenario

Conventional workflow automation has traditionally been "rule-based," inevitably requiring human intervention whenever rules were ambiguous or judgment was necessary. "Jev," however, is a frontier model capable of making decisions autonomously. Furthermore, because it can also calculate confidence scores, uncertain judgments can be routed to humans. While approaches like "LLM as a judge" have previously delegated decisions to language models, human review was always mandatory, keeping a "Human-in-the-loop" structure strictly in place. With the arrival of "Jev," however, expectations for full automation are rising. Application examples of automation highlighted by TypeSafe AI include:

  • Recruiting

  • Lead generation

  • Customer support

  • Insurance claims

  • Financial crime

  • Legal and compliance

  • E-commerce marketplaces

  • Advertising

  • Risk assessment

  • Demand forecasting

...and more. It will be exciting to see how "Jev" evolves.


What do you think? This new type of frontier model could dramatically advance business process automation across enterprises. To close, I'd like to leave you with the words of TypeSafe AI:

“Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out.“

Here at Toshi Stats, we look forward to continuing our exploration of various applications for frontier models. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, to

1) Introducing System One Models & Jev, August 15 2026, Diogo Almeida, founder, TypeSafe

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

The Next Tabular Data Revolution: How ICL Delivers Accurate Predictions from Minimal Rows

Hello everyone. Another exciting week with multiple new generative AI models launched!

Yet, there is an interesting observation: most generative AI models are trained primarily on text-based data, and their capabilities are predominantly benchmarked against text-centric tasks such as coding. In contrast, tabular data—which dominates day-to-day enterprise operations—has seen comparatively little discussion in this space. Recently, however, several startups have started releasing dedicated generative AI foundation models for tabular data as open-weight models. Today, we focus on a numerical regression task to explore the true potential of this paradigm.


1. Nori V1 and How It Works

The foundation model highlighted today is Nori V1, developed by Synthefy. Synthefy is a high-momentum startup that recently closed a fresh funding round (1). Their website describes the release as follows:

"Nori V1 is the open-weight foundation model for tables. Apache 2.0 code and weights, free for commercial use."

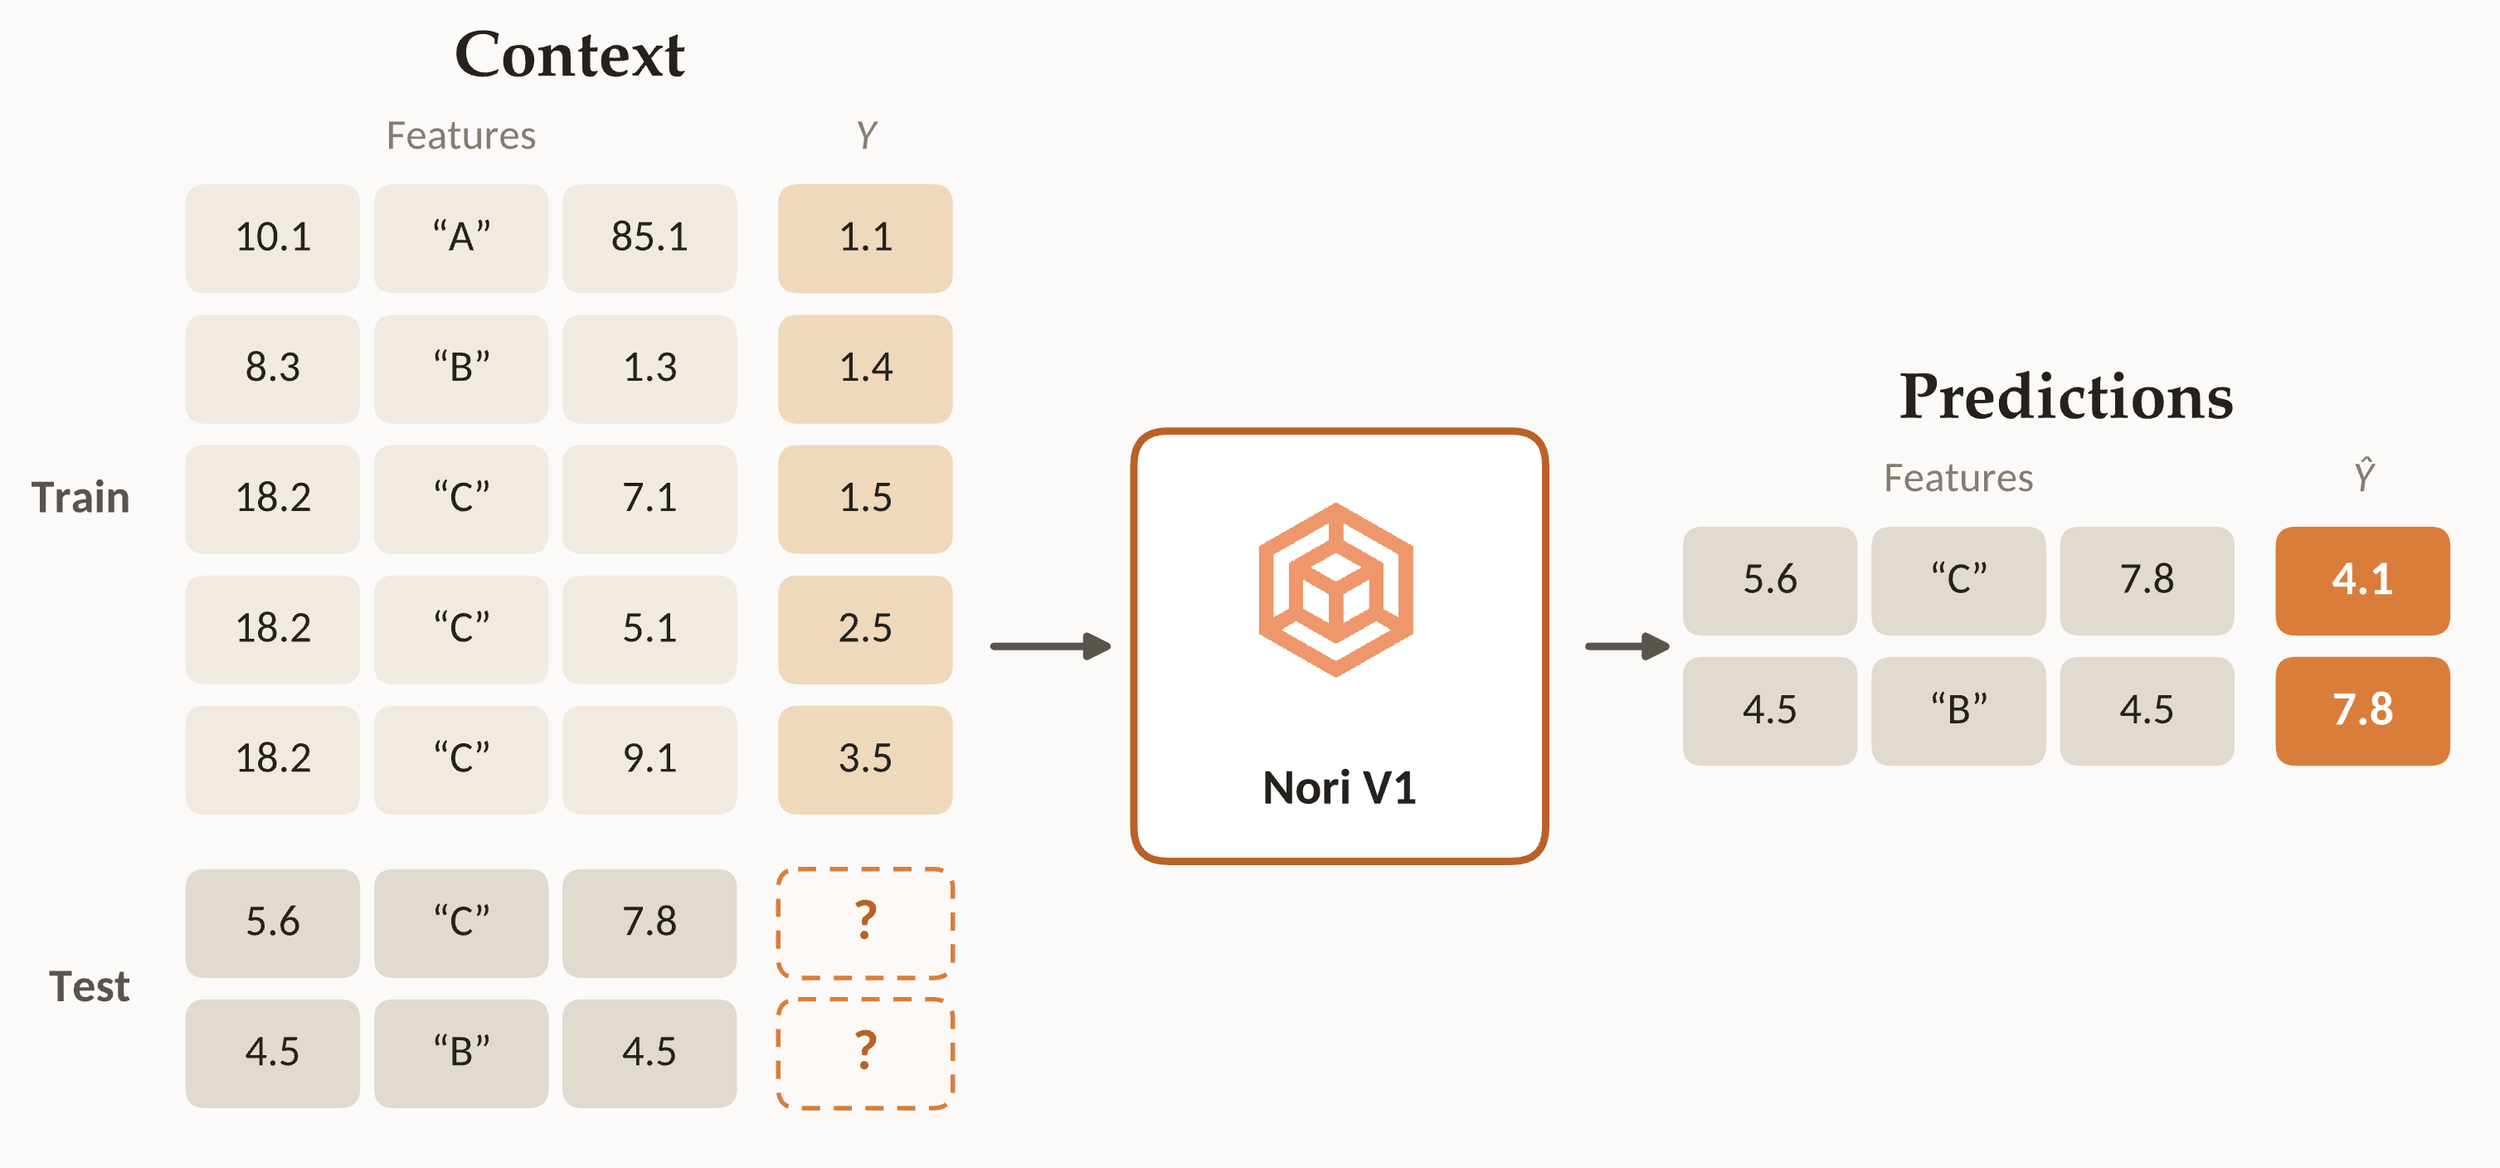
The secret behind its high accuracy is In-Context Learning (ICL), a topic touched upon previously. In terms of data pipeline, context is constructed by assembling labeled training data and presenting it to the model upfront to set up the baseline for inference. Next, the test data intended for prediction is provided.

In practice, both the training and test sets are bundled into a single massive prompt fed directly into Nori V1 to run inference. In this benchmark, the objective is predicting house prices—a standard regression task.

               In-Context Learning (ICL)

The defining characteristic of ICL is that it operates entirely out-of-the-box with zero fine-tuning required. This makes it accessible even to non-specialists. But does it truly maintain competitive accuracy? Let’s test it against real-world data.


2. Benchmarking Nori V1 on Kaggle Data

Accuracy was validated using a Kaggle benchmark: With 79 explanatory variables describing (almost) every aspect of residential homes in Ames, Iowa, this competition challenges you to predict the final price of each home. (2).

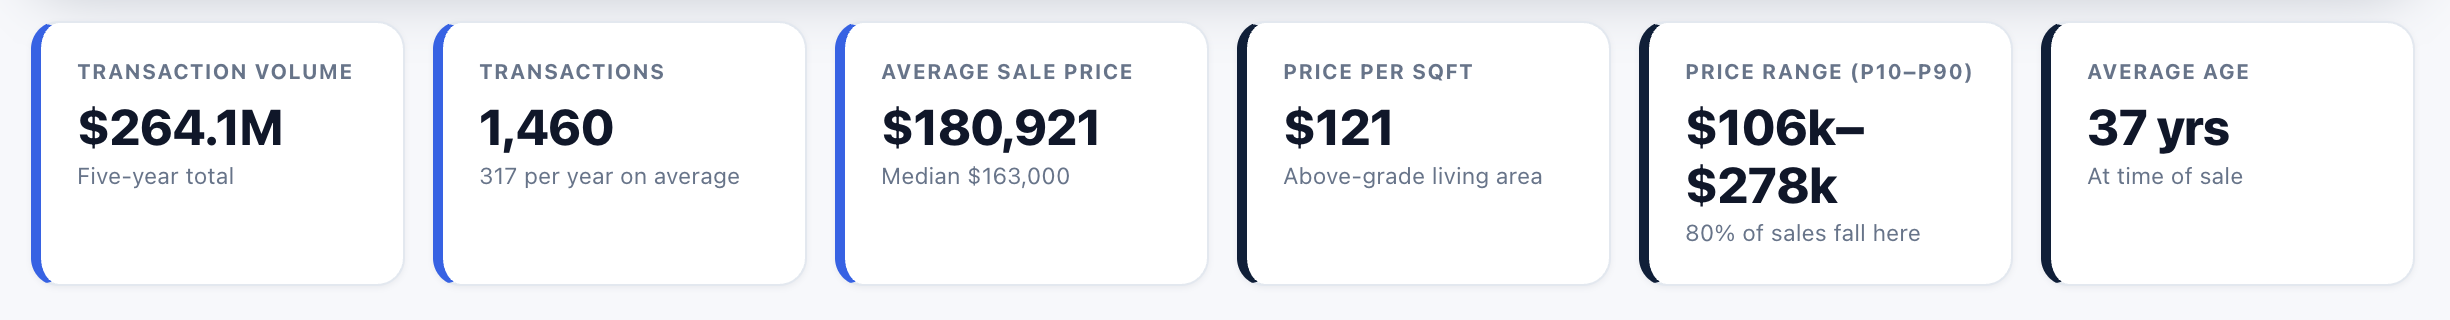
An overview of the dataset is provided below. With only 1,460 samples, this is hardly sufficient for training a machine learning prediction model. Let's see what level of accuracy can be achieved with a sample size like this.

‍  ‍             Overview of the Competition Data

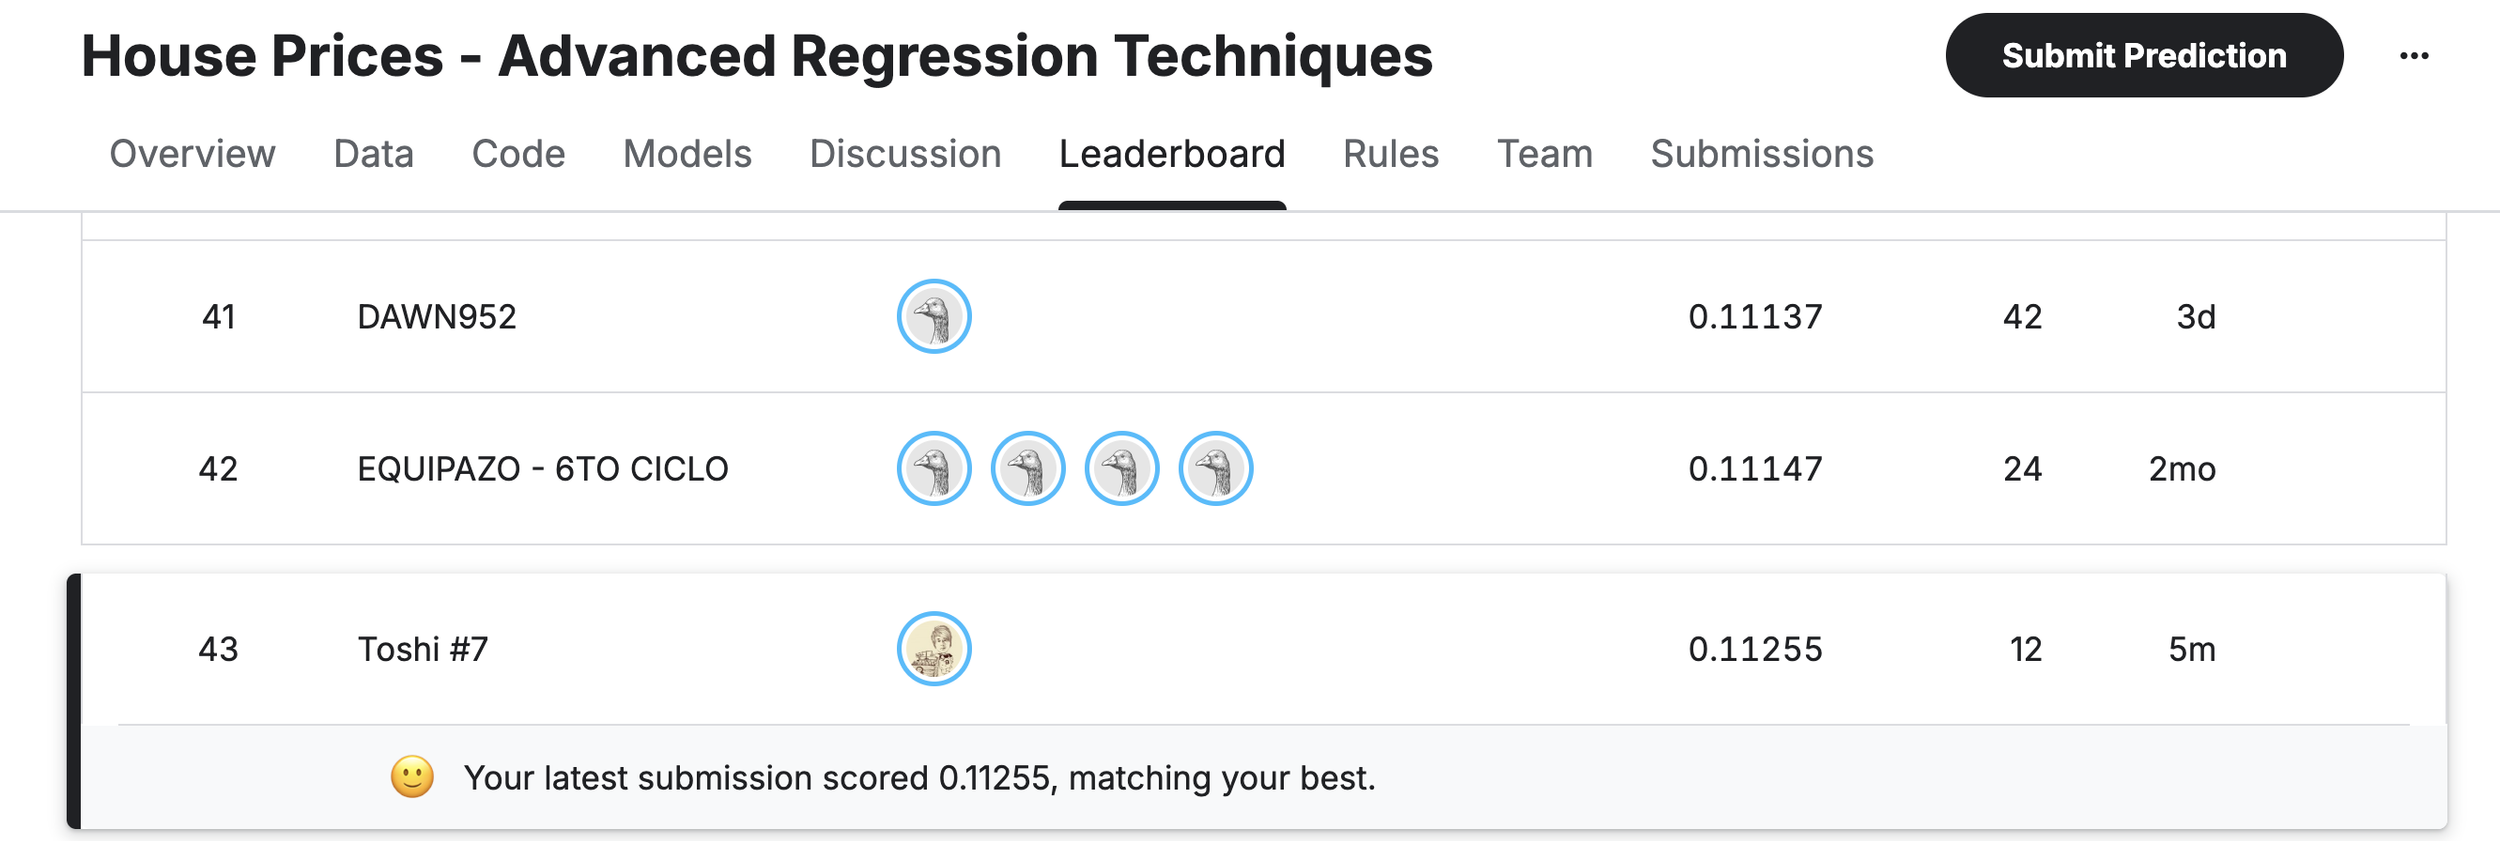
I evaluated the model's accuracy ceiling using 1,000 training samples and submitted the predictions to the Kaggle leaderboard. At the time of submission, the result placed 43rd out of 3,138 entries—within the top 1.4%—an outstanding outcome. Because no training was required, the process simply involved feeding the "1,000 reference samples + test data" into the model and submitting the output. It achieved the ideal balance: remarkable simplicity paired with high predictive accuracy.

The result placed 43rd out of 3,138 entries—within the top 1.4%.

With a modest total of 1,460 samples, conventional gradient boosting libraries like LightGBM often face constraints from data scarcity. In these low-sample regimes, Nori V1 proved remarkably effective.


3. Use Case: Tackling the Cold-Start Problem

If foundation models can deliver high predictive accuracy on scarce tabular data, the most immediate application is resolving the cold-start problem. In client consulting engagements, a frequent blocker is: "We are still accumulating data, so predictive modeling is off the table until our database grows."

With an ICL foundation model like Nori V1, teams can begin running predictions immediately on whatever preliminary data is available, driving earlier data-backed operational decisions across initiatives such as:

  • Launching new products or services

  • Entering new regional markets

  • Targeting uncharted customer segments

Where decision-makers previously had to rely on intuition due to limited baseline records, ICL tabular models provide a grounded foundation for rational decision-making from day one.

To wrap up, a quote from Synthefy captures the broader ambition:

"We are building Machine Intelligence for the class of decisions humans could never make at all."

At ToshiStats, we will continue pushing the boundaries of In-Context Learning (ICL) across tabular data science. Stay tuned!

You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Building Foundation Models for the World's Structured Data, August 18 2026, Synthefy
2) House Prices - Advanced Regression Techniques, kaggle

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Qwen3.8-Flash-Next: The Prelude to China's Next AI Leap!

Chinese AI models have been making remarkable leaps forward, and on August 26, 2026, a new AI was announced by Alibaba Cloud (1). It is called "Qwen3.8-Flash-Next," and it's touted to surpass the frontier model Opus4.6. Furthermore, its outstanding technology will reportedly be directly carried over to the next-generation Qwen4. Let's take a look right away!


1. Features of "Qwen3.8-Flash-Next"

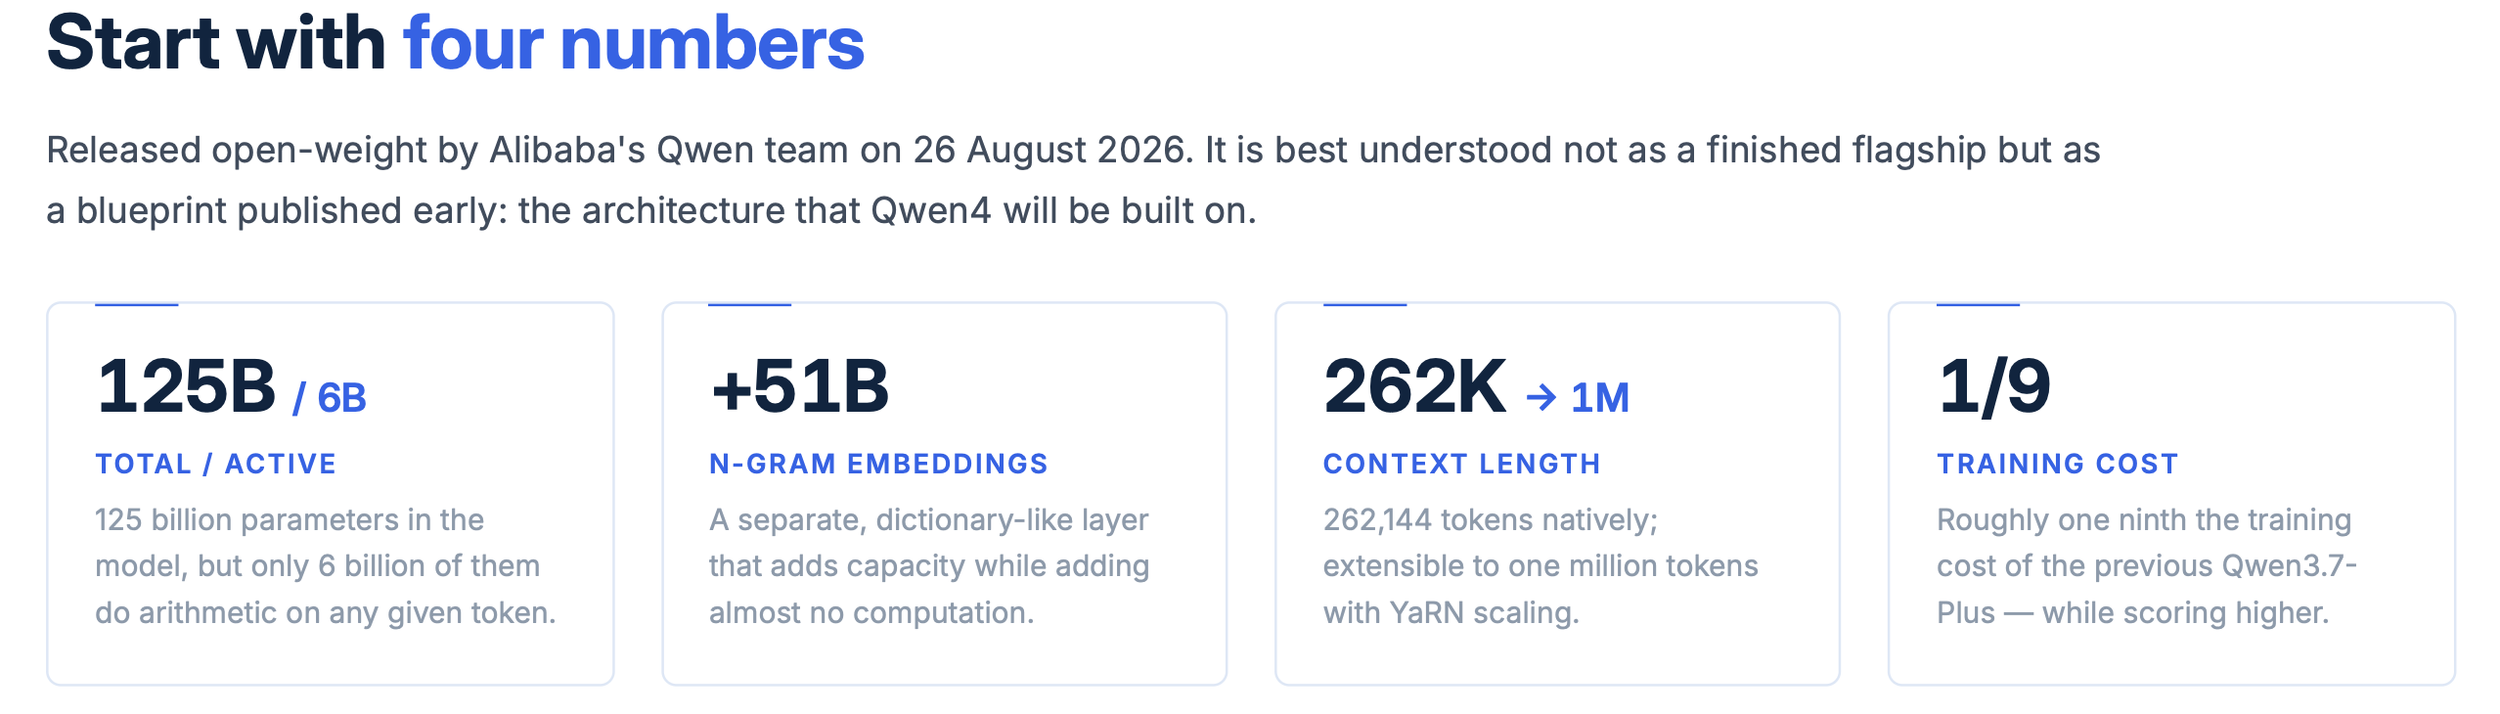
This model is a medium-scale AI model with 125 billion parameters. It adopts MoE (Mixture of Experts), and the actual active parameters are extremely small at 6 billion. Therefore, the calculation speed is presumed to be very fast. The context window is also large at 262,000 tokens, and it seems it can even be expanded to 1 million tokens. Compared to the previous generation model, the training cost is supposedly only 1/9th, making it a highly super-efficient model. However, it's a wonder how it manages to surpass Opus4.6 with a parameter count that is by no means massive. Let's explore the secret behind this.


2. Core Technology of "Qwen3.8-Flash-Next"

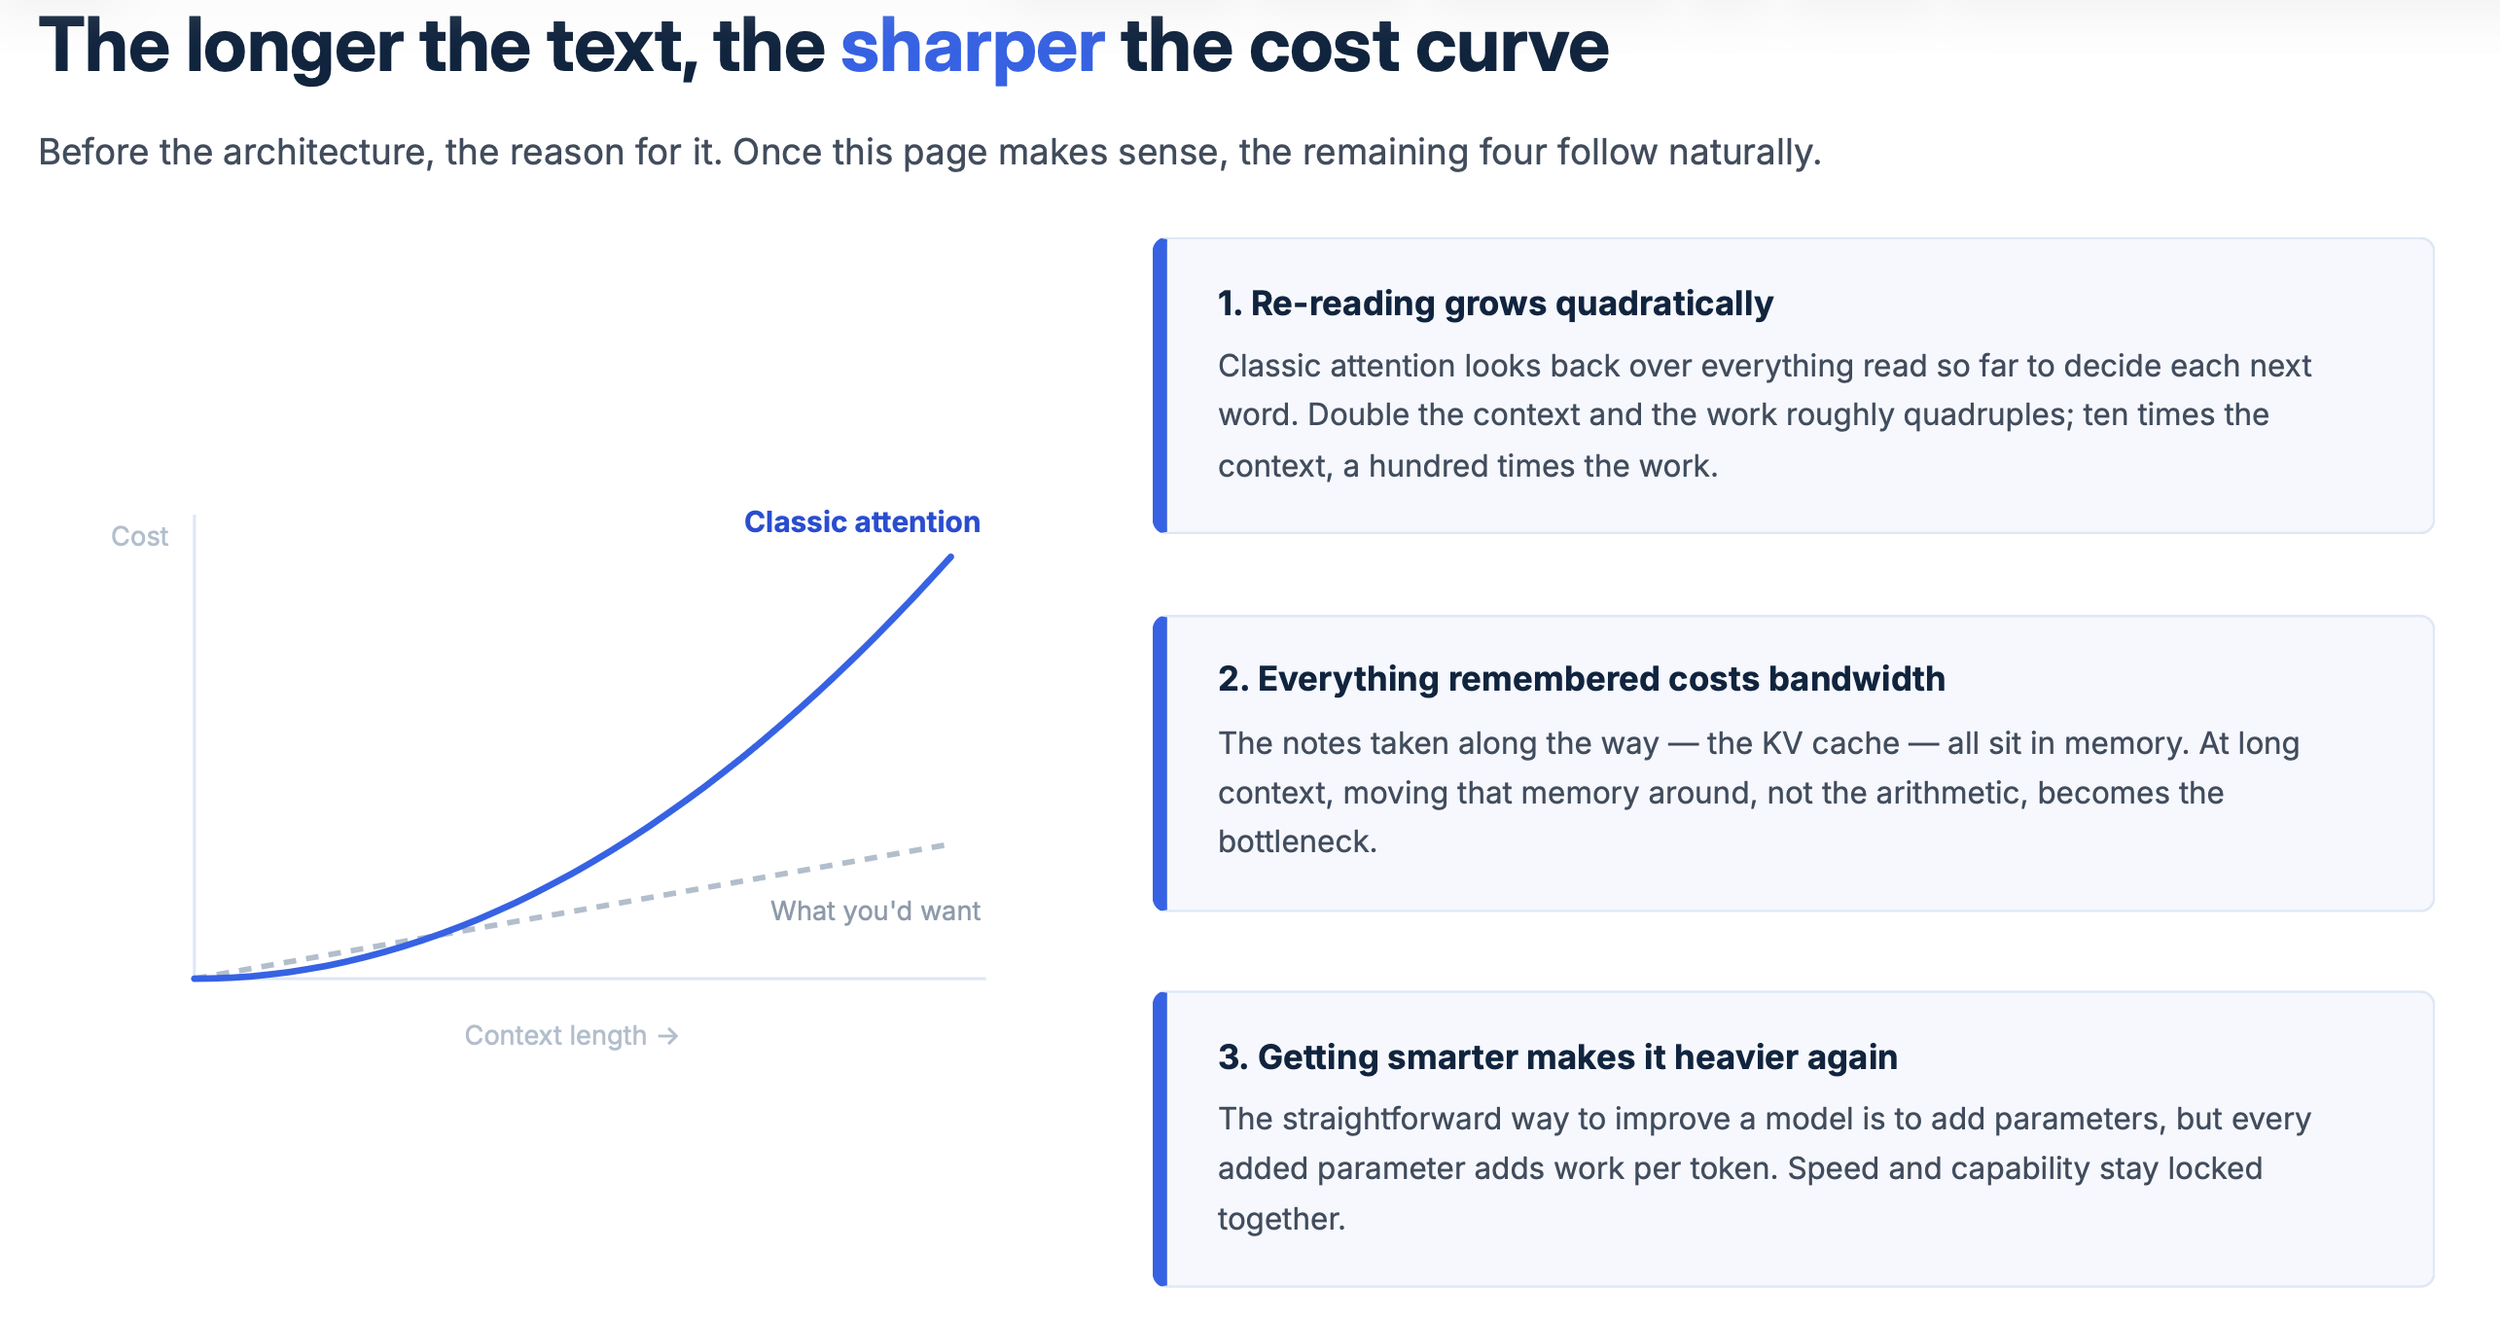
First, it is often said that to improve AI accuracy, the size must be increased. The wall developers hit there is that as the information to process increases, the AI suddenly becomes heavy. The main issue lies in the "attention mechanism" used by most AIs. This is a mechanism that calculates "how much attention should be paid to which information" while the data advances through each layer, but the sheer volume of calculation is massive. Wishing to "do something about this," Alibaba researchers seem to have applied great ingenuity to the "attention mechanism."

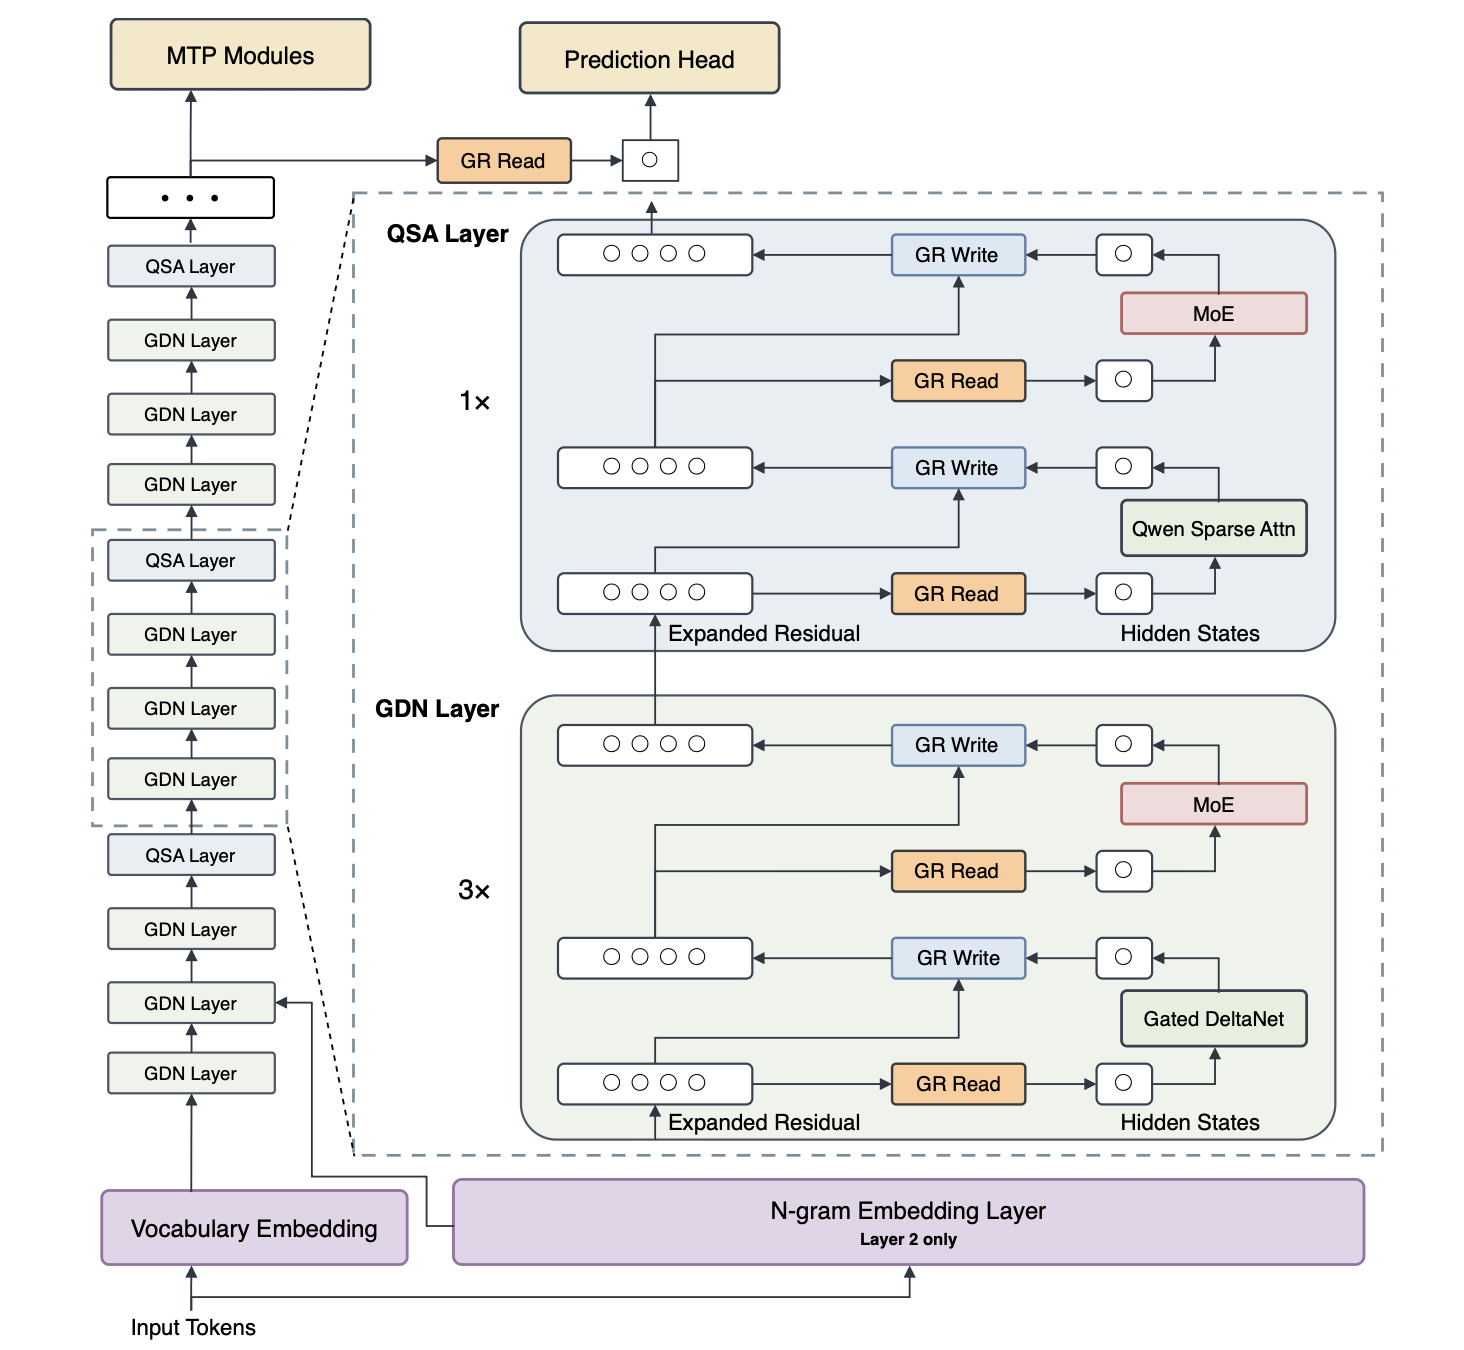
Here is the overall structural diagram of Qwen3.8-Flash-Next.

            Qwen3.8-Flash-Next

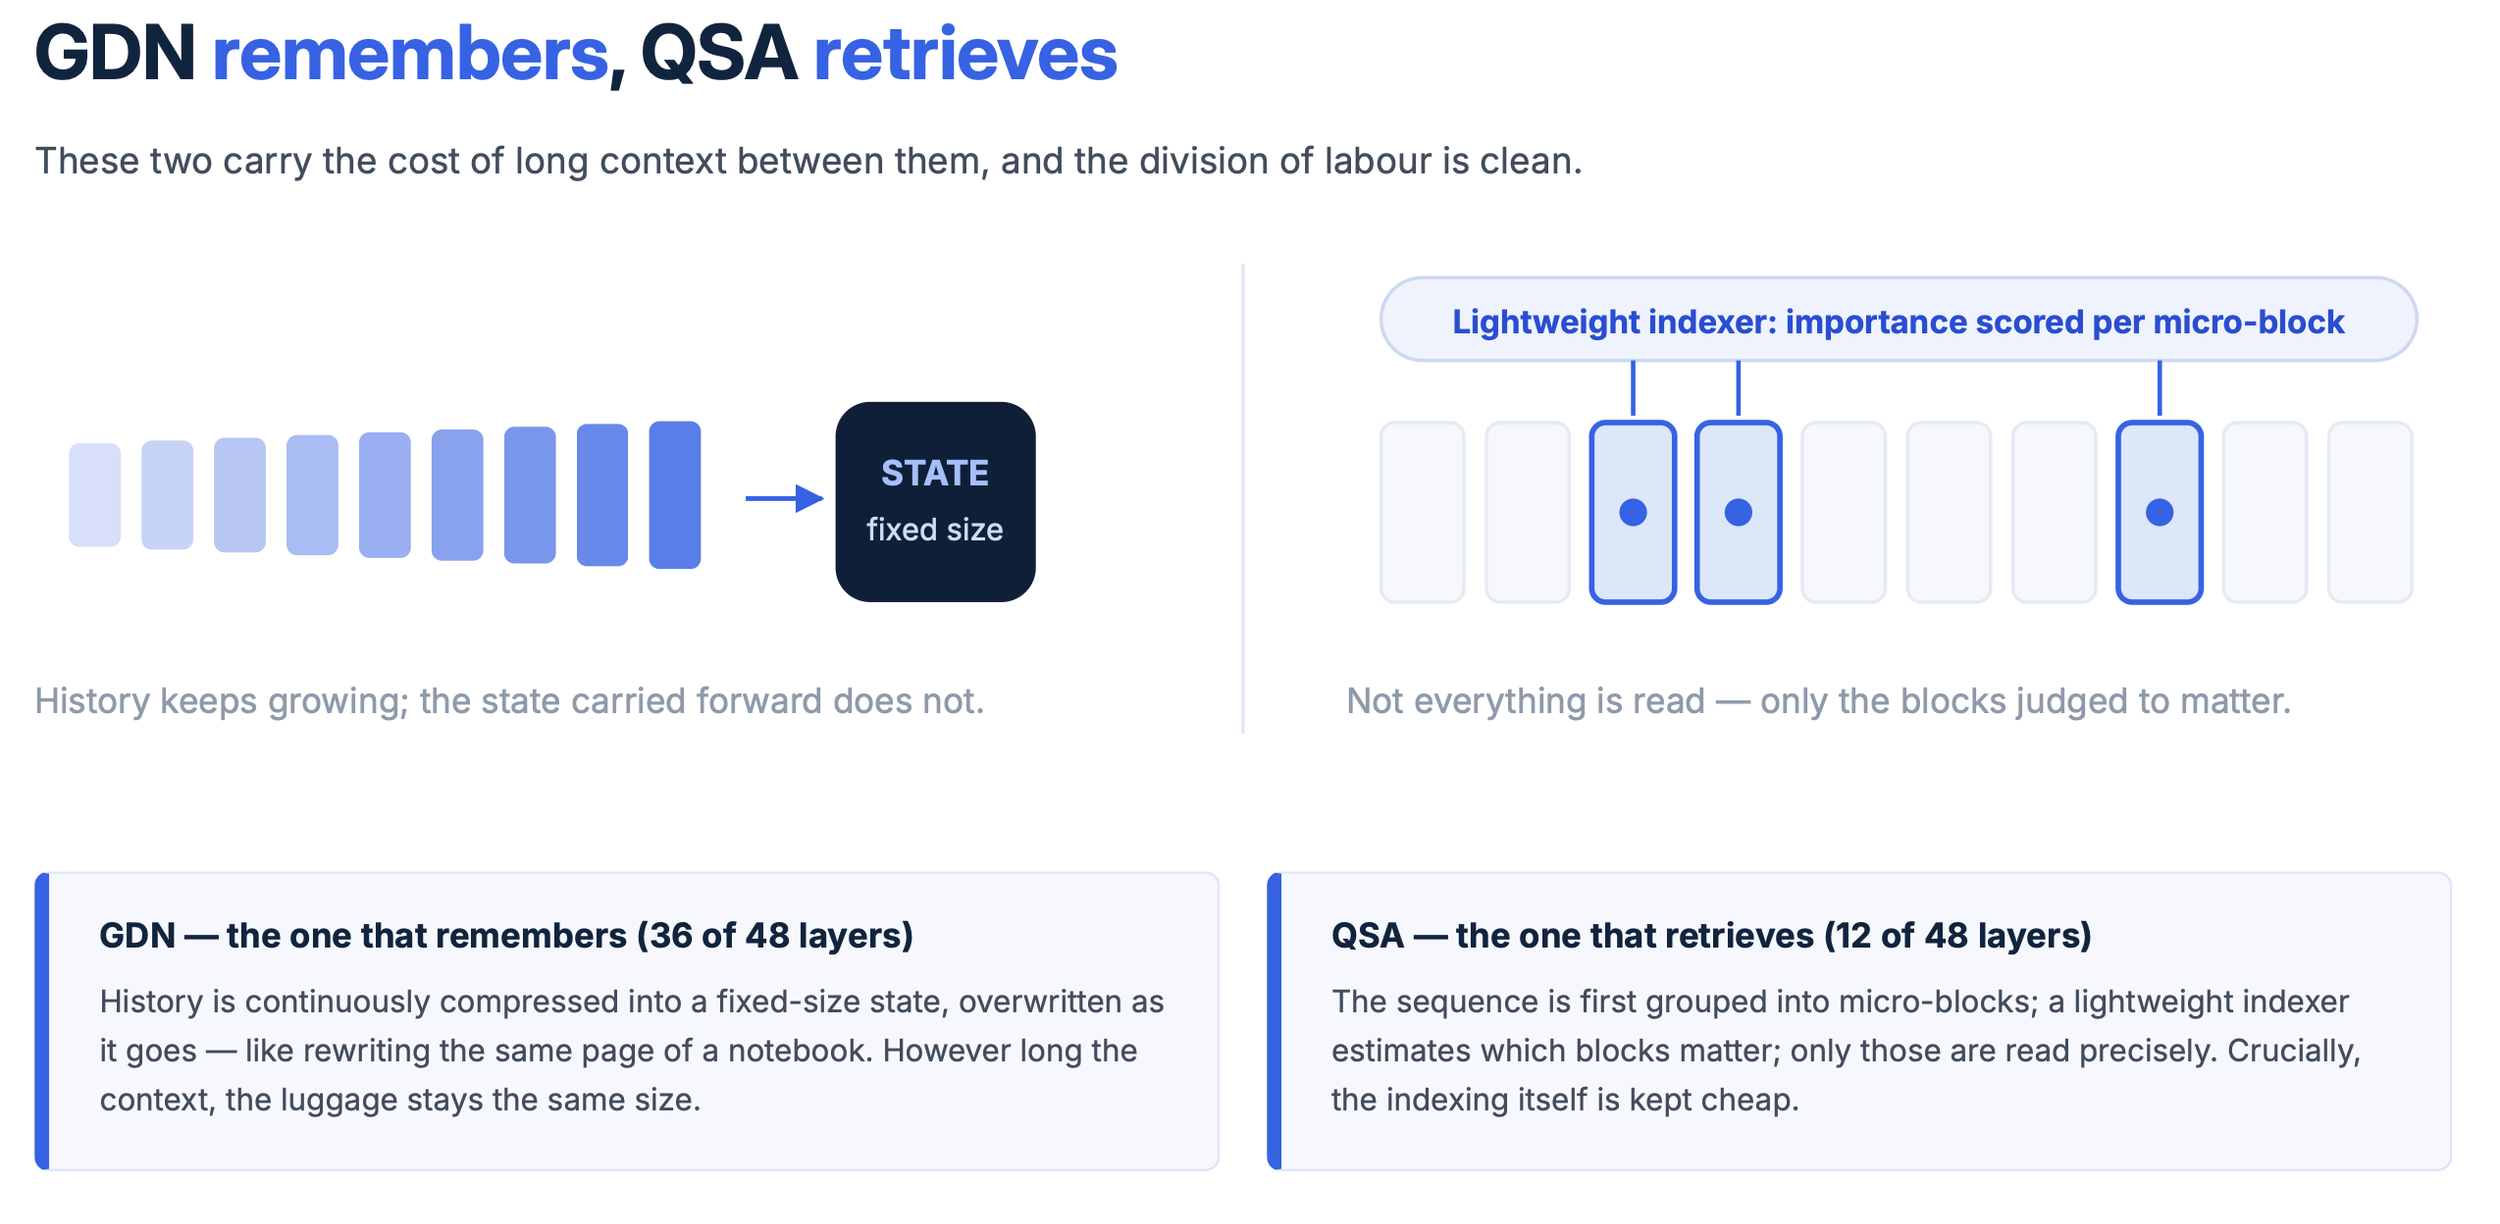
First, let's look at the attention mechanism. It has a structure of 48 layers in total, consisting of 12 sets of GDN (Gated DeltaNet) and QSA (Qwen Sparse Attention) in a 3:1 ratio. I think this exquisite combination is absolutely brilliant.

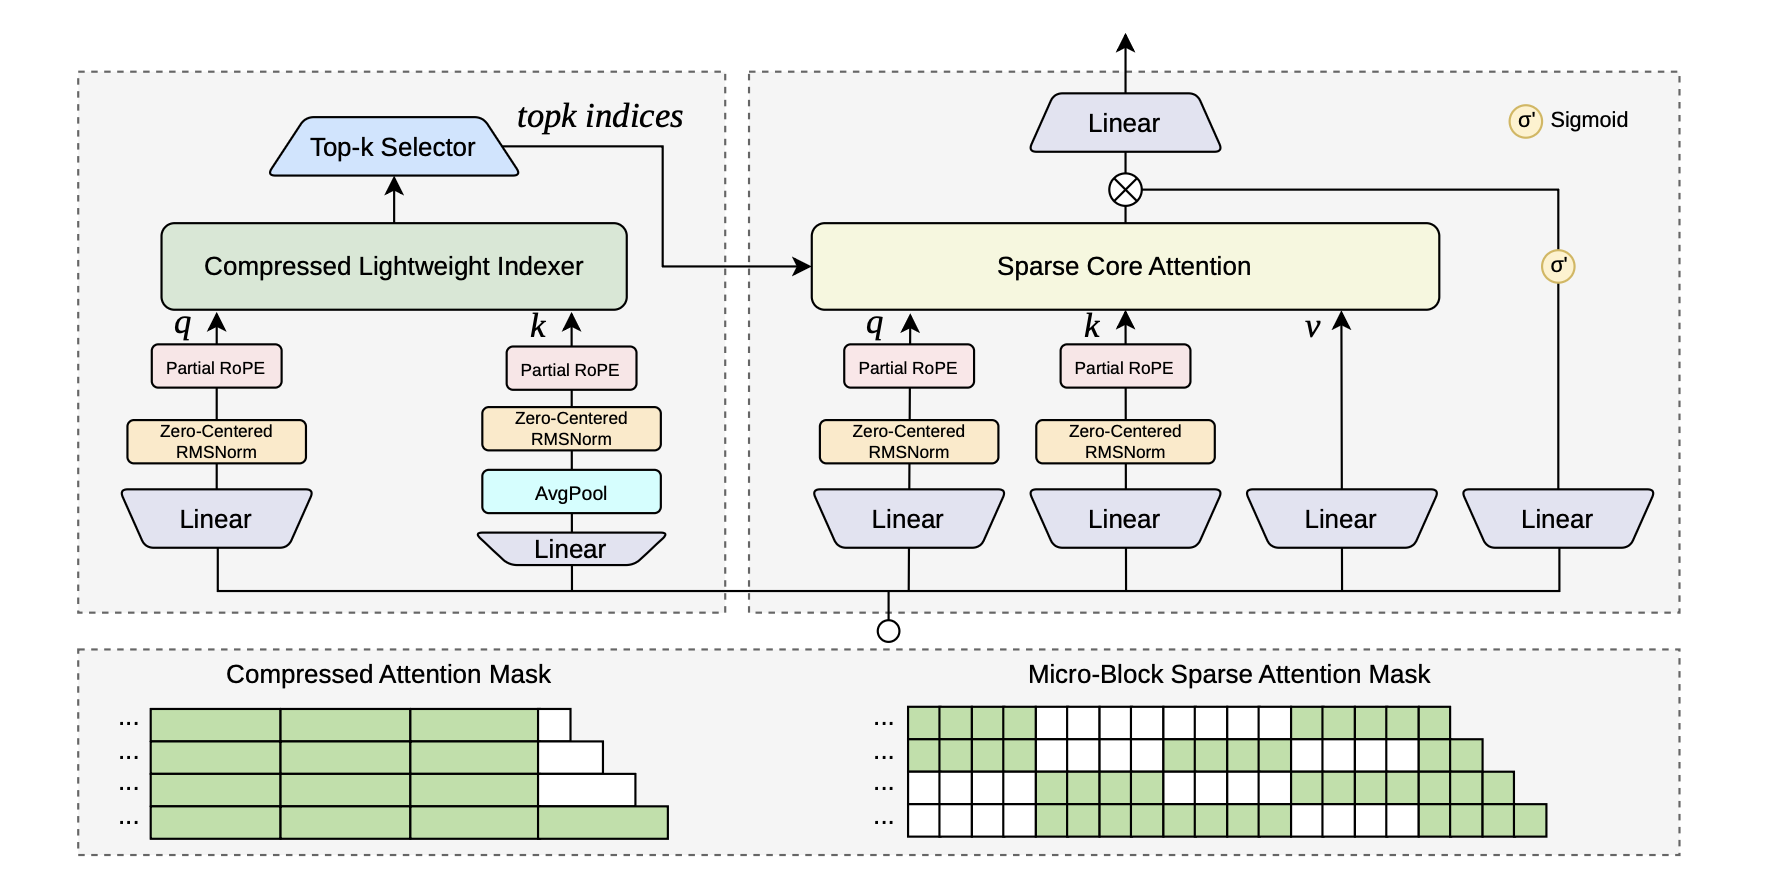
Now, I will explain GDN and QSA. To prevent calculations from becoming too heavy while maintaining accuracy, GDN features a mechanism where the computational volume doesn't increase significantly even if the length of the input tokens increases. That is wonderful, but as a trade-off, there are inevitably cases where accuracy drops. Thus, QSA is used to prevent this decline in accuracy. Normally, a method called "full attention," which looks at every single token, is used, but it has the drawback of bloated computational costs. Therefore, QSA keeps computational costs down by using a method of briefly skimming once, and then reading closely on the second pass.

                Qwen Sparse Attention (QSA)

The diagram above is the structural diagram of QSA. On the left side, the original token sequence is divided into chunks of, say, 16 or 64 tokens, and 'k' particularly important parts are selected. By expanding those specific parts back into the original token sequence, it becomes possible to increase computational efficiency without dropping accuracy. In the diagram on the bottom right showing the state of the tokens, the white sections are the sparse parts where no calculations are performed.

Summarizing GDN and QSA, it looks like the following. This attention mechanism might become a textbook example for AI development in the future.

                GDN and QSA

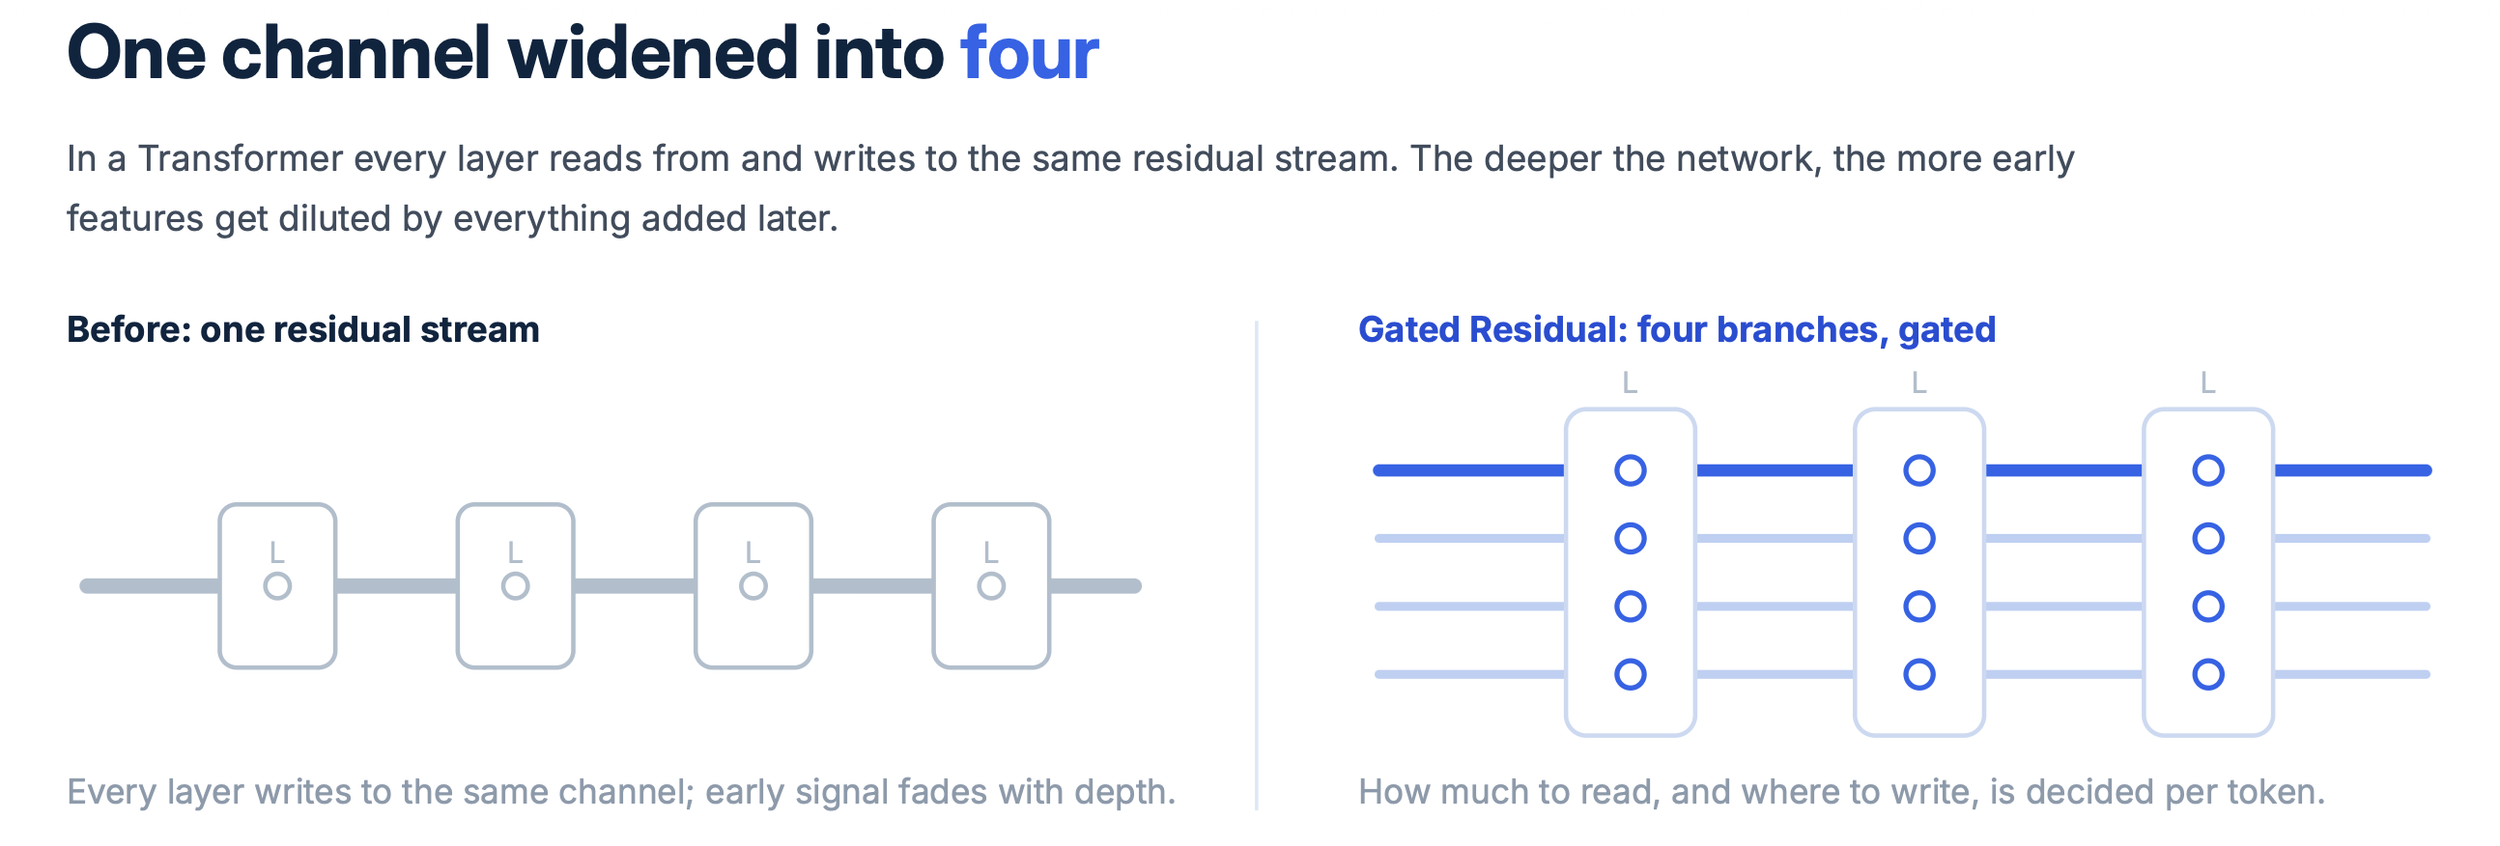
Additionally, the residual stream was expanded into a highly flexible one called "Gated Residual (GR)." Simply put, it means expanding the standard single flow of information into four, and further incorporating a mechanism that decides what information to read and where to write it. There is a mention of "GR Read/GR Write" in the overall structural diagram of Qwen3.8-Flash-Next above, and the read/write functions play an active role here. The residual stream became a de facto standard in the field of image recognition with a very famous 2015 paper called ResNet (2), but at the time, it was still a basic concept that simply added the original information to the information generated in each layer. This Gated Residual enables far more flexible information processing, and I was deeply moved to catch a glimpse of the technological progress made over this past decade.

               Gated Residual (GR)

Moreover, Qwen3.8-Flash-Next incorporates numerous other technologies, such as N-gram Embedding and the Muon optimization method. It seems that these ingenuities organically connect to give birth to a high-performance AI. I would like to share a sentence from the conclusion of their technical report:

The design reflects a conviction that architecture, efficiency, and optimization form one coupled system.


3. Performance of "Qwen3.8-Flash-Next"

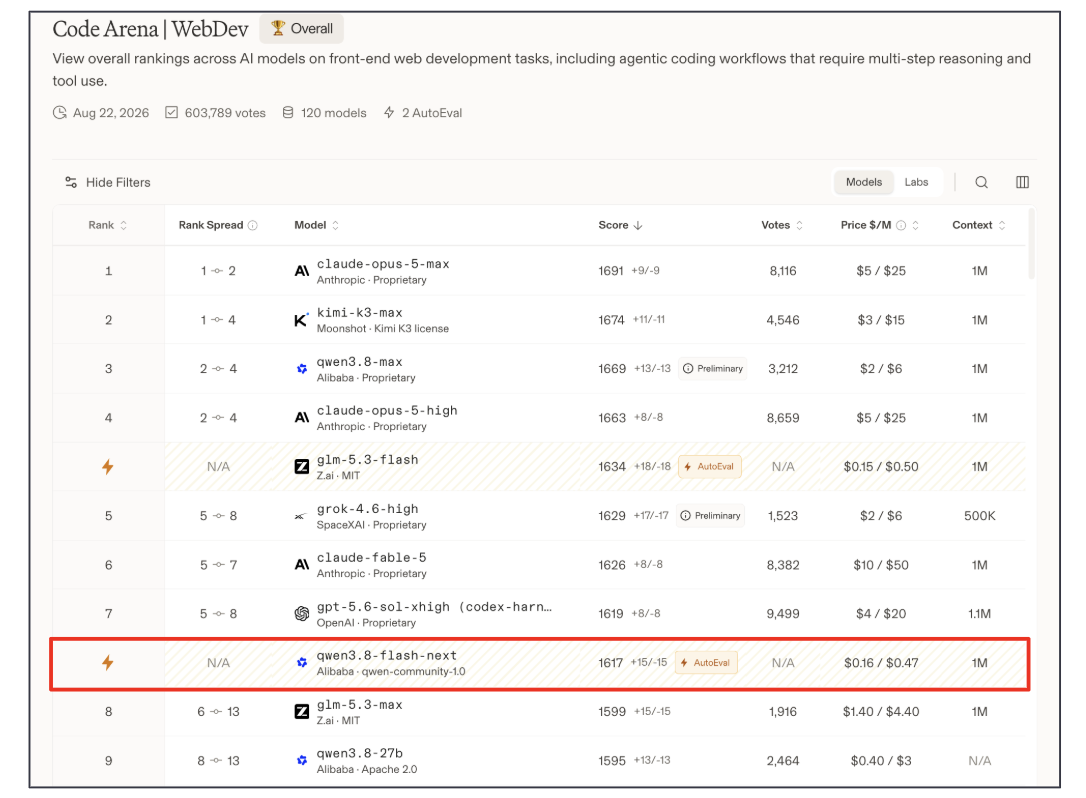
Now, what about the actual performance of "Qwen3.8-Flash-Next", which has pursued efficiency to such an extent? A third-party evaluation is necessary, so let's look at the leaderboard below (3).

                 Arena

"Qwen3.8-Flash-Next" is positioned around 8th place, and naturally, it sits above Opus4.6. As expected, the performance of this model is incredible. The models ranked higher than it are all super-large frontier models, with parameter counts exceeding 1 trillion. "Qwen3.8-Flash-Next", which achieved the ability to break into the top ranks with only 125 billion parameters, can truly be called a magnificent AI. Also, since this AI is a preview version for evaluating "Qwen4," I am already incredibly excited to see what kind of performance the next-generation "Qwen4" will achieve.


What did you think? This was the first time I fully covered a Chinese-made AI. I felt it was fantastic because a detailed technical report was published, allowing for more concrete technological discussions. Classic technologies like attention mechanisms and residual connections are very meticulously combined, highlighting the high technical prowess of the development team. I believe researchers around the world engaging in AI development moving forward will undoubtedly reference this report, and it will likely further accelerate the development of AI worldwide. We really can't take our eyes off AI right now.


At Toshi Stats, we plan to continue challenging ourselves to explore the mechanisms of AI. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) Qwen3.8-Flash-Next: A New Architecture, Towards Ultimate Cost-Efficiency, 26 Aug 2026, Alibaba Cloud
2) Deep Residual Learning for Image Recognition, 10 Dec 2015, Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun, Microsoft Research
3) Arena

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Exploring Tabular ICL: High-Precision Prediction Models for Small Datasets

Recently, I've been hearing a lot about models that perform tabular prediction using ICL (In-Context Learning). In addition to Google TabFM, which I introduced last time, several startups have also released ICL models. Therefore, I would like to compare them with LightGBM, a machine learning model I frequently use, to see where their strengths lie. Let's dive right into the details.


1. Applying ICL (In-Context Learning) to Tabular Data

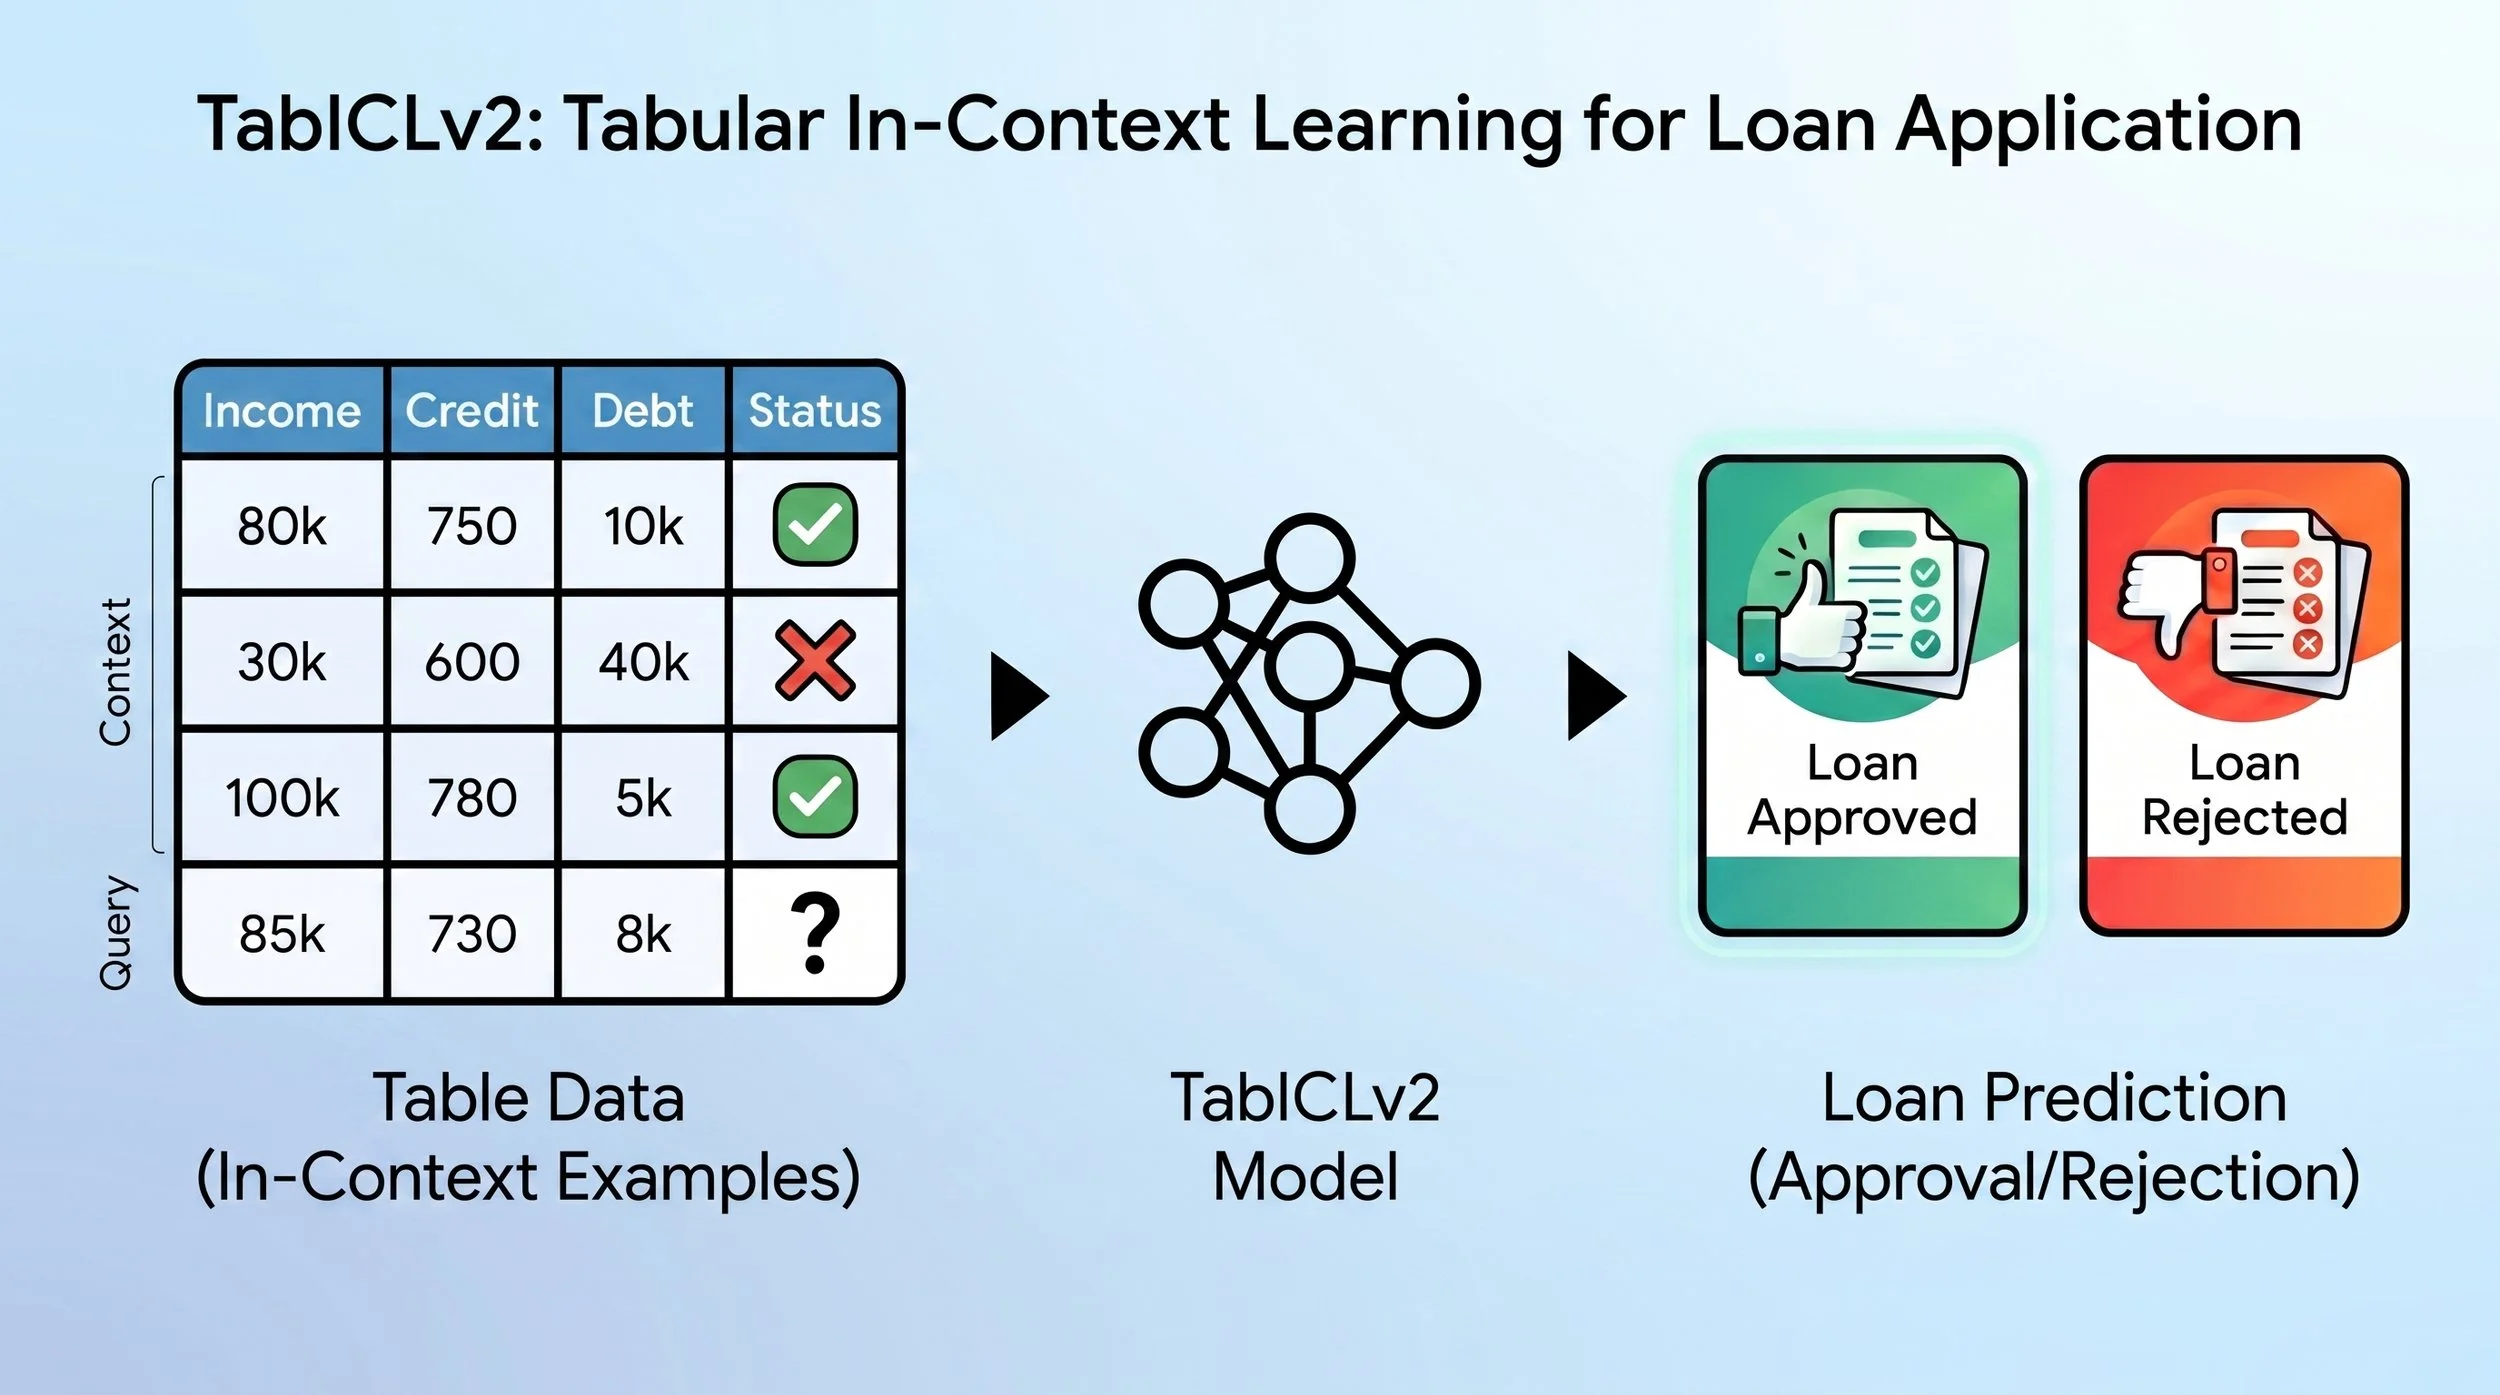
The selling point of ICL models is that they can be used straight out of the box without training. The chart below should make this specifically easier to understand.

‍  ‍      Applying ICL (In-Context Learning) to Tabular Data

First, regarding the input data, the context is key. This involves gathering data with already known outcomes and showing it to the model beforehand to prepare it for prediction. Next, the samples (queries) for the actual prediction are input, and the prediction is executed. In reality, as shown in the diagram, the context and the samples (queries) are combined and input into the ICL model as one large prompt. Since we will be predicting approval or rejection based on loan application data this time (3), it will be a binary classification prediction task. Now, let's actually experiment with some data.


2. Comparison between ICL Models and LightGBM

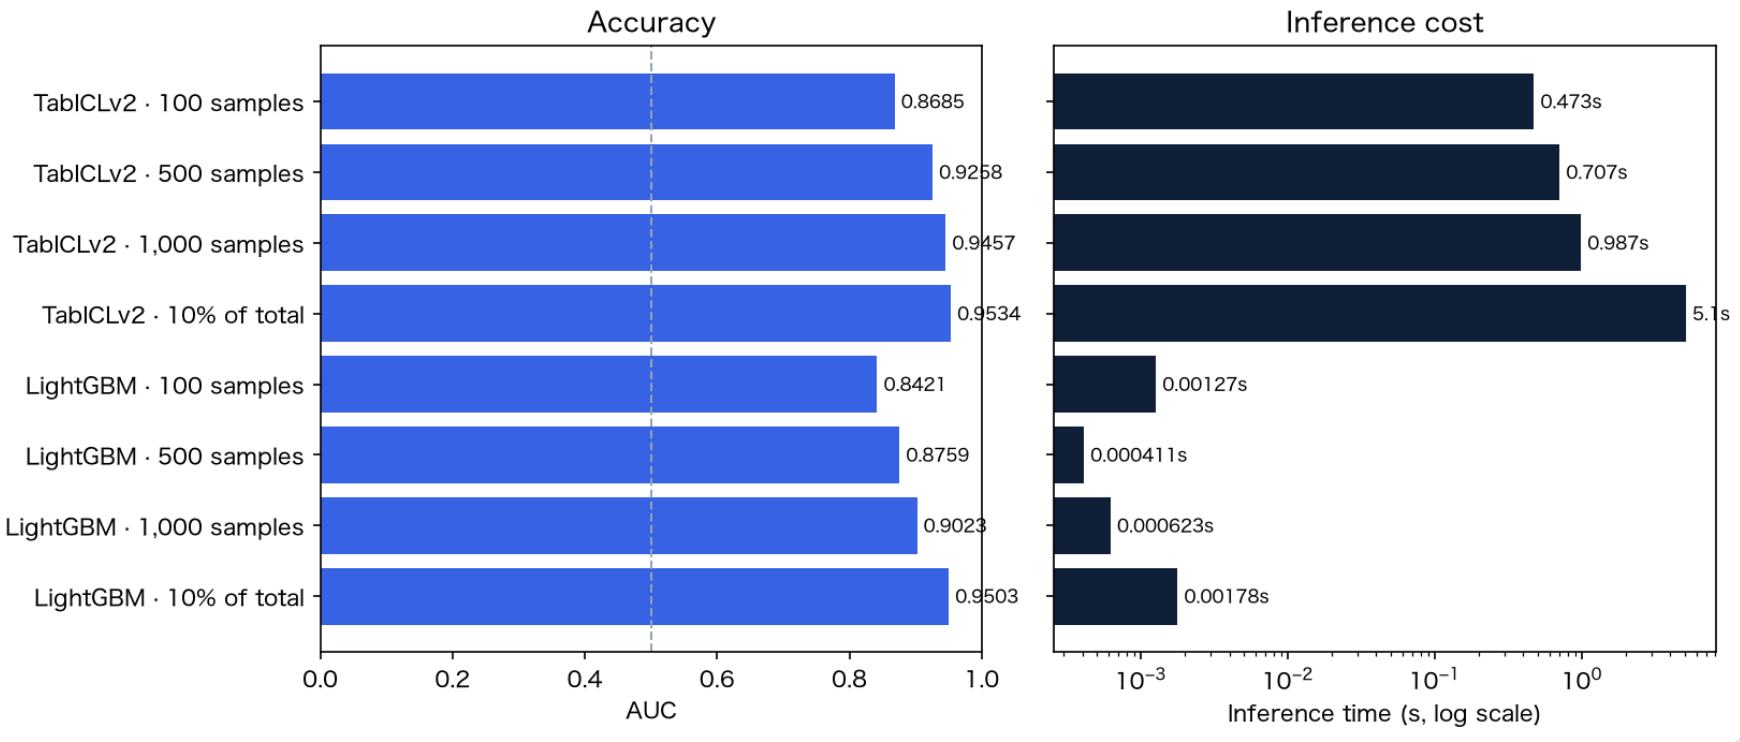
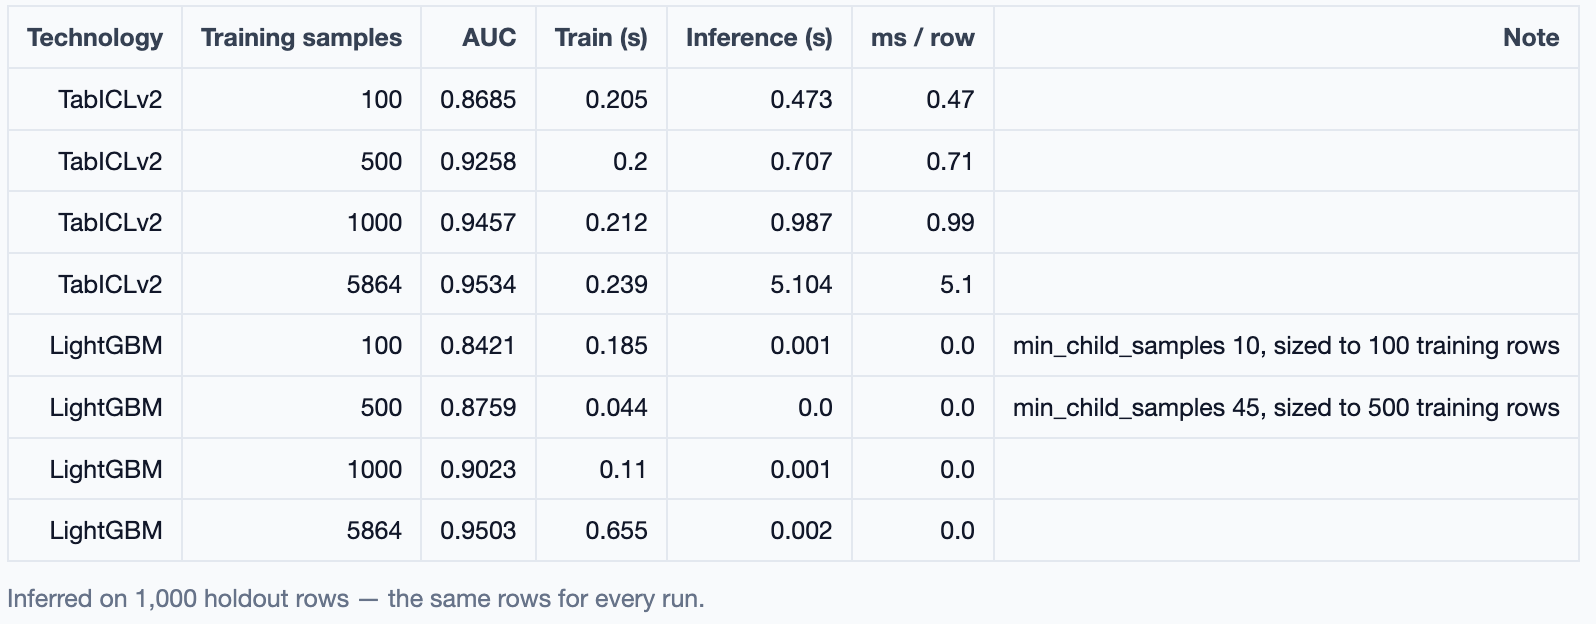
For this experiment, I used a model called TabICLv2 (1). It is lightweight, easy to use, and its availability under the BSD 3-Clause License is also appealing. I compared it with LightGBM (2), a gradient boosting machine learning model. I have been using LightGBM as my first-choice model for over five years. I'm excited to see how close TabICLv2 can get to this LightGBM. By the way, the hardware used this time is a MacBook Air M4 with 24GB of RAM. The results are as follows:

‍  ‍             TabICLv2 vs LightGBM

The most noticeable thing is the high accuracy of TabICLv2 with a training dataset of only 100 samples. While LightGBM requires model training before prediction, with 1,000 samples or fewer, the training data was simply too small, causing it to fall behind TabICLv2. The high accuracy with a small number of samples is due to the fact that TabICLv2 is a foundation model and has been thoroughly pre-trained. Because it possesses the necessary information for prediction from the start, it can predict without any issues even with a small number of samples. It's amazing!

‍  ‍               TabICLv2 vs LightGBM

However, in terms of cost (computation time), LightGBM has the advantage. When performing ICL (In-Context Learning) with TabICLv2, you end up inputting a large amount of context every time you make a prediction. If the context is around 1,000 samples, there is no particular problem in practice, but at 5,000 samples, the computation time becomes noticeable. Also, this time, the number of prediction samples is fixed at 1,000. In actual business operations, it often exceeds 10,000, so it is presumed that TabICLv2 would be difficult to use in cases requiring real-time processing.


3. When Should You Use an ICL Model?

Based on the above experimental results, I recommend trying out ICL models in the following cases:

  • When you want to execute predictions with a small amount of data on hand      The situation of "not being able to do anything until data accumulates" is often called the cold start problem. Immediately after launching a new product in finance, naturally, there is no data. In such cases, managing credit risk used to be difficult, but it seems ICL models can resolve this issue.

  • When there are no data analysis experts                     Training models like LightGBM still requires specialized knowledge. If you do not have such talent in-house, an ICL model, which completely eliminates the training process, becomes a reliable asset.

Conversely, if you have abundant data and data scientists in-house, LightGBM seems to have the upper hand. After all, having the right tool for the right job is important.


What did you think? Various new ICL-type models are being released, and I'm looking forward to future developments. At Toshi Stats, we plan to continue exploring the application of In-Context Learning (ICL) to tabular data. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) TabICLv2: A better, faster, scalable, and open tabular foundation model, Jingang Qu, David Holzmüller, Gaël Varoquaux, Marine Le Morvan, Feb 11, 2026
2) LightGBM, Microsoft Corporation
3) Loan Approval Prediction,  kaggle, Oct 1, 2024

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Deep Dive into TabFM: Is Google's New Foundation Model a Game-Changer for Tabular Data?

When predicting loan defaults or customer churn using tabular data such as Excel, it is common to use linear regression models or gradient boosting models. For this purpose, it is common sense that "a prediction model must be trained first." However, on June 30, 2026, Google released TabFM (Tabular Foundation Model) (1). Astonishingly, by using this model, predictions can be executed without any training whatsoever. Is such a thing really possible? Let's dive right into the details.


1. Prediction Tasks Using Tabular Data

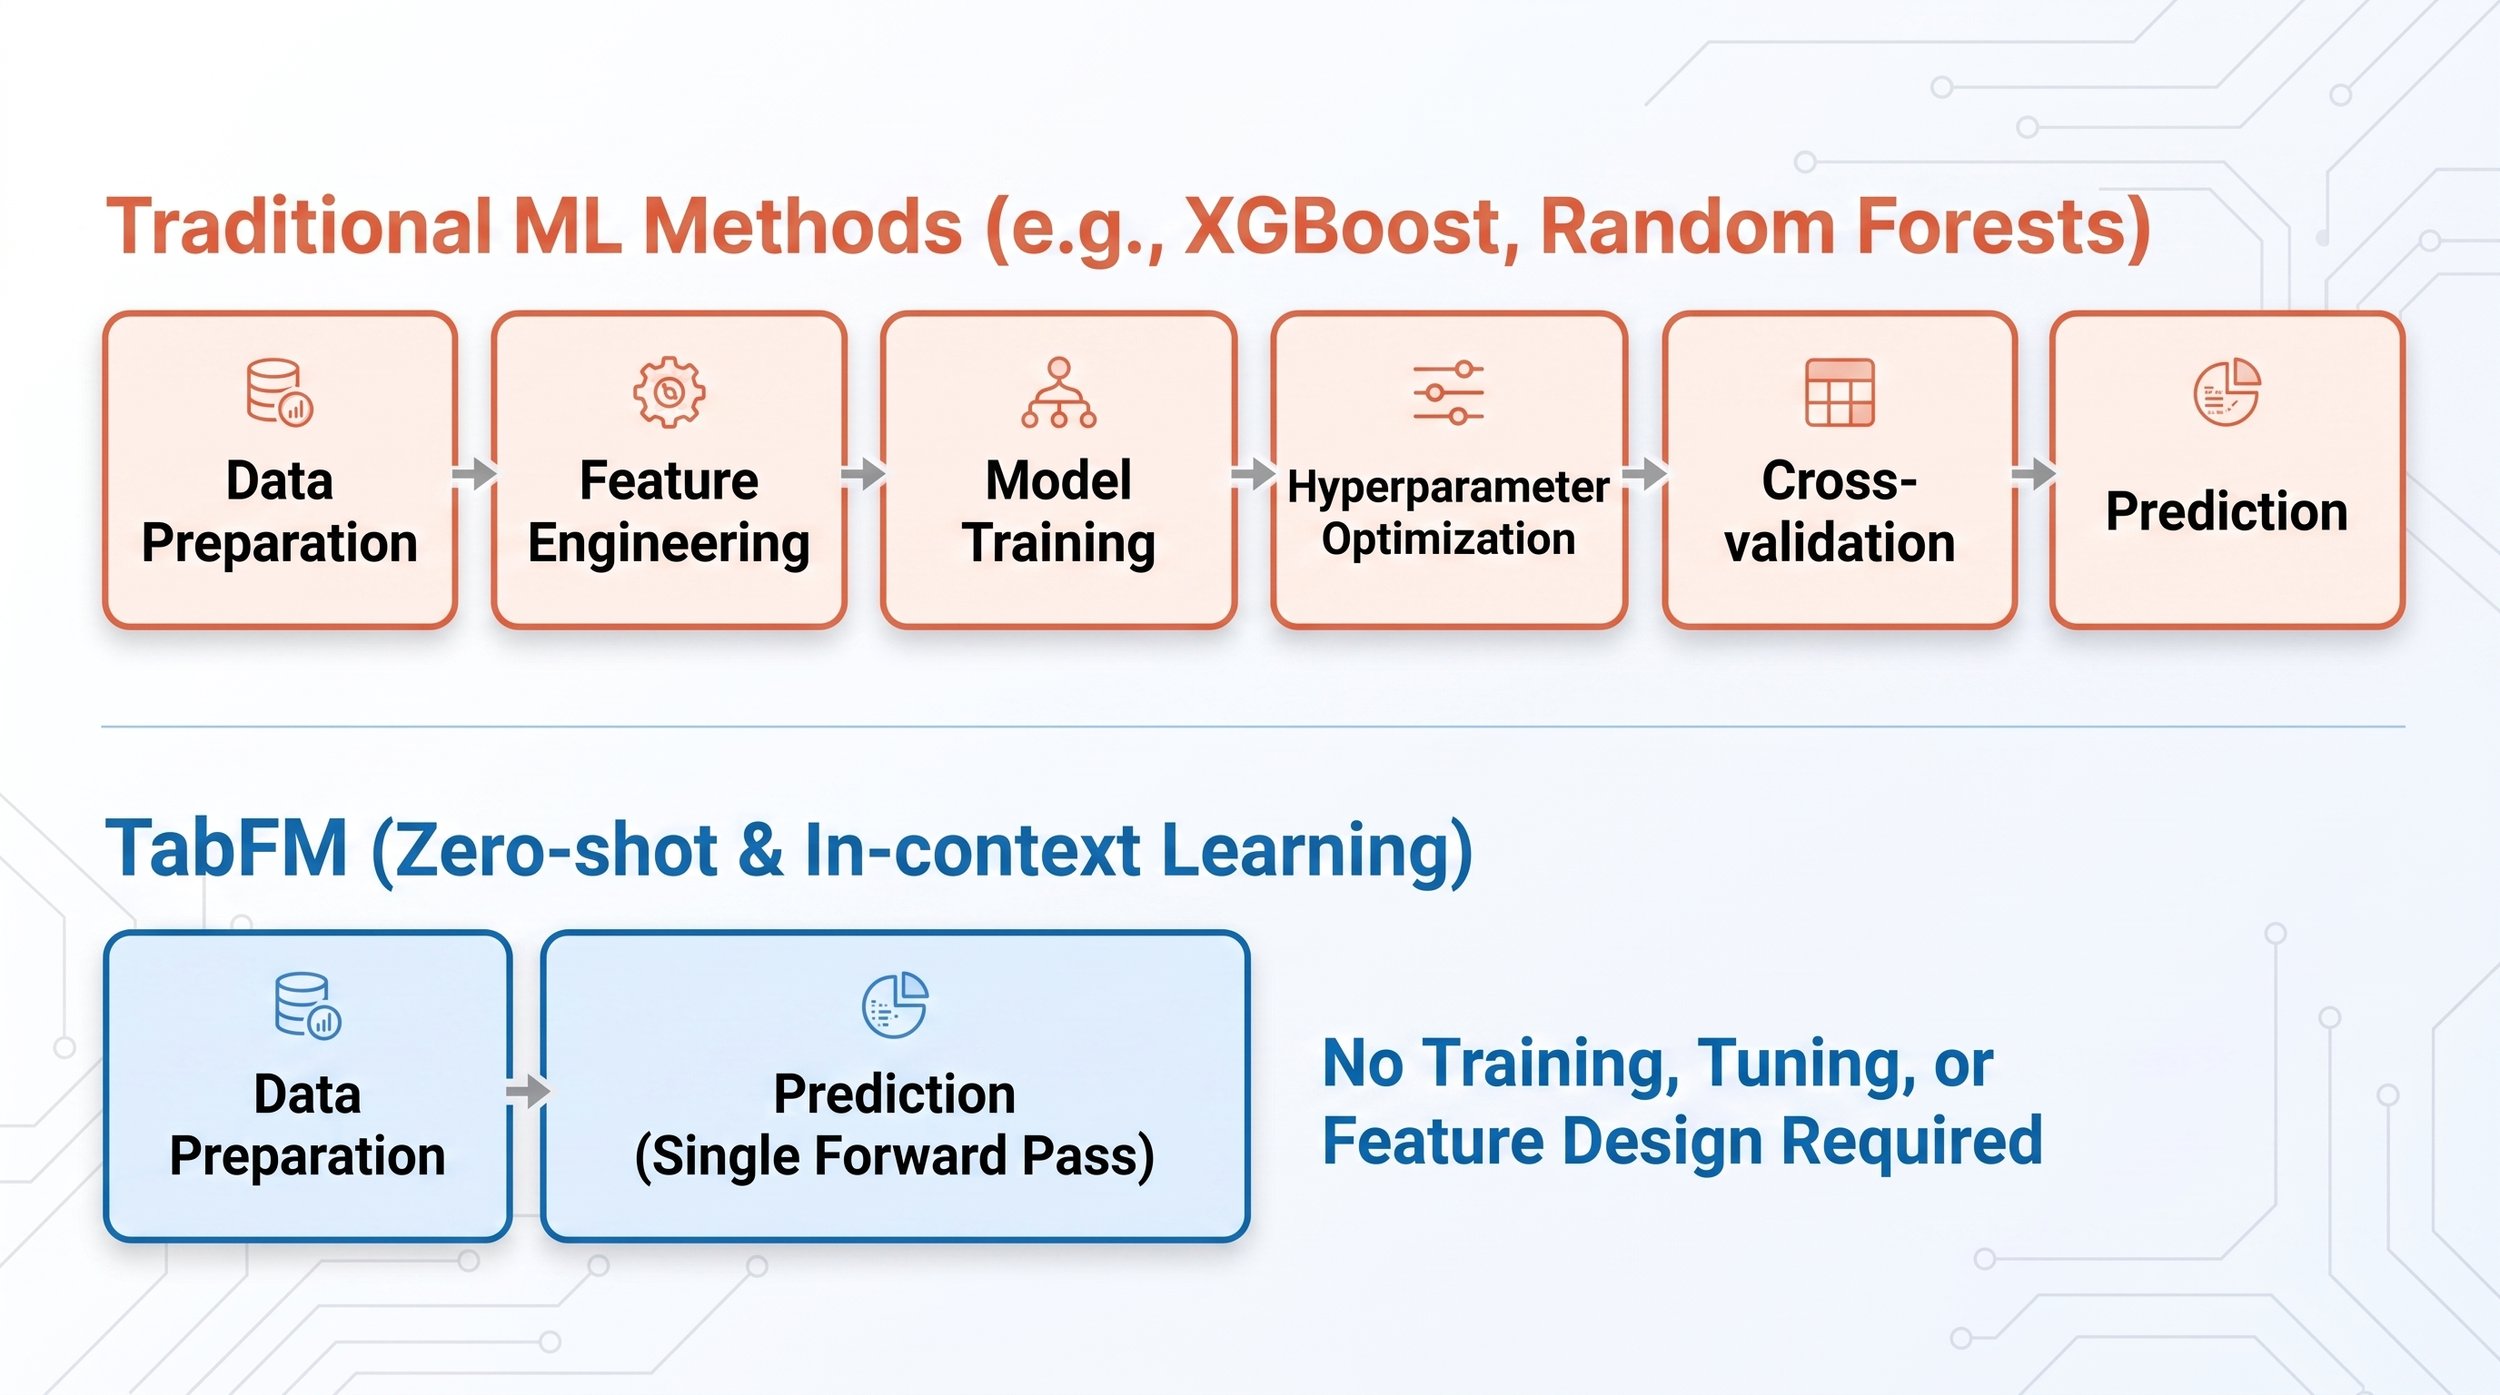
For predictions using tabular data, gradient boosting models like XGBoost have been commonly used. Data scientists invest their time in hyperparameter optimization and domain-specific feature engineering to extract reliable signals from the data. In competitions like Kaggle, being proficient in these techniques can be said to be the key to advancing to the top ranks. However, Google seems to be trying to change this landscape with its new foundation model, "TabFM". Google has declared the following:

“We introduce TabFM, a foundation model designed specifically for tabular data classification and regression. By framing tabular prediction as an ICL problem, TabFM eliminates the need for manual model training, hyperparameter tuning, and complex feature engineering. We are excited to share how this approach allows users to generate high-quality predictions on previously unseen tables in a single forward pass. “

To summarize, it looks like the following figure.

      Traditional supervised learning pipeline and TabFM's zero-shot inference

Indeed, almost all the processes that were necessary up until now are no longer needed. With this, even non-data scientists might be able to tackle prediction tasks using tabular data. But is that really possible?


2. The Architecture of TabFM

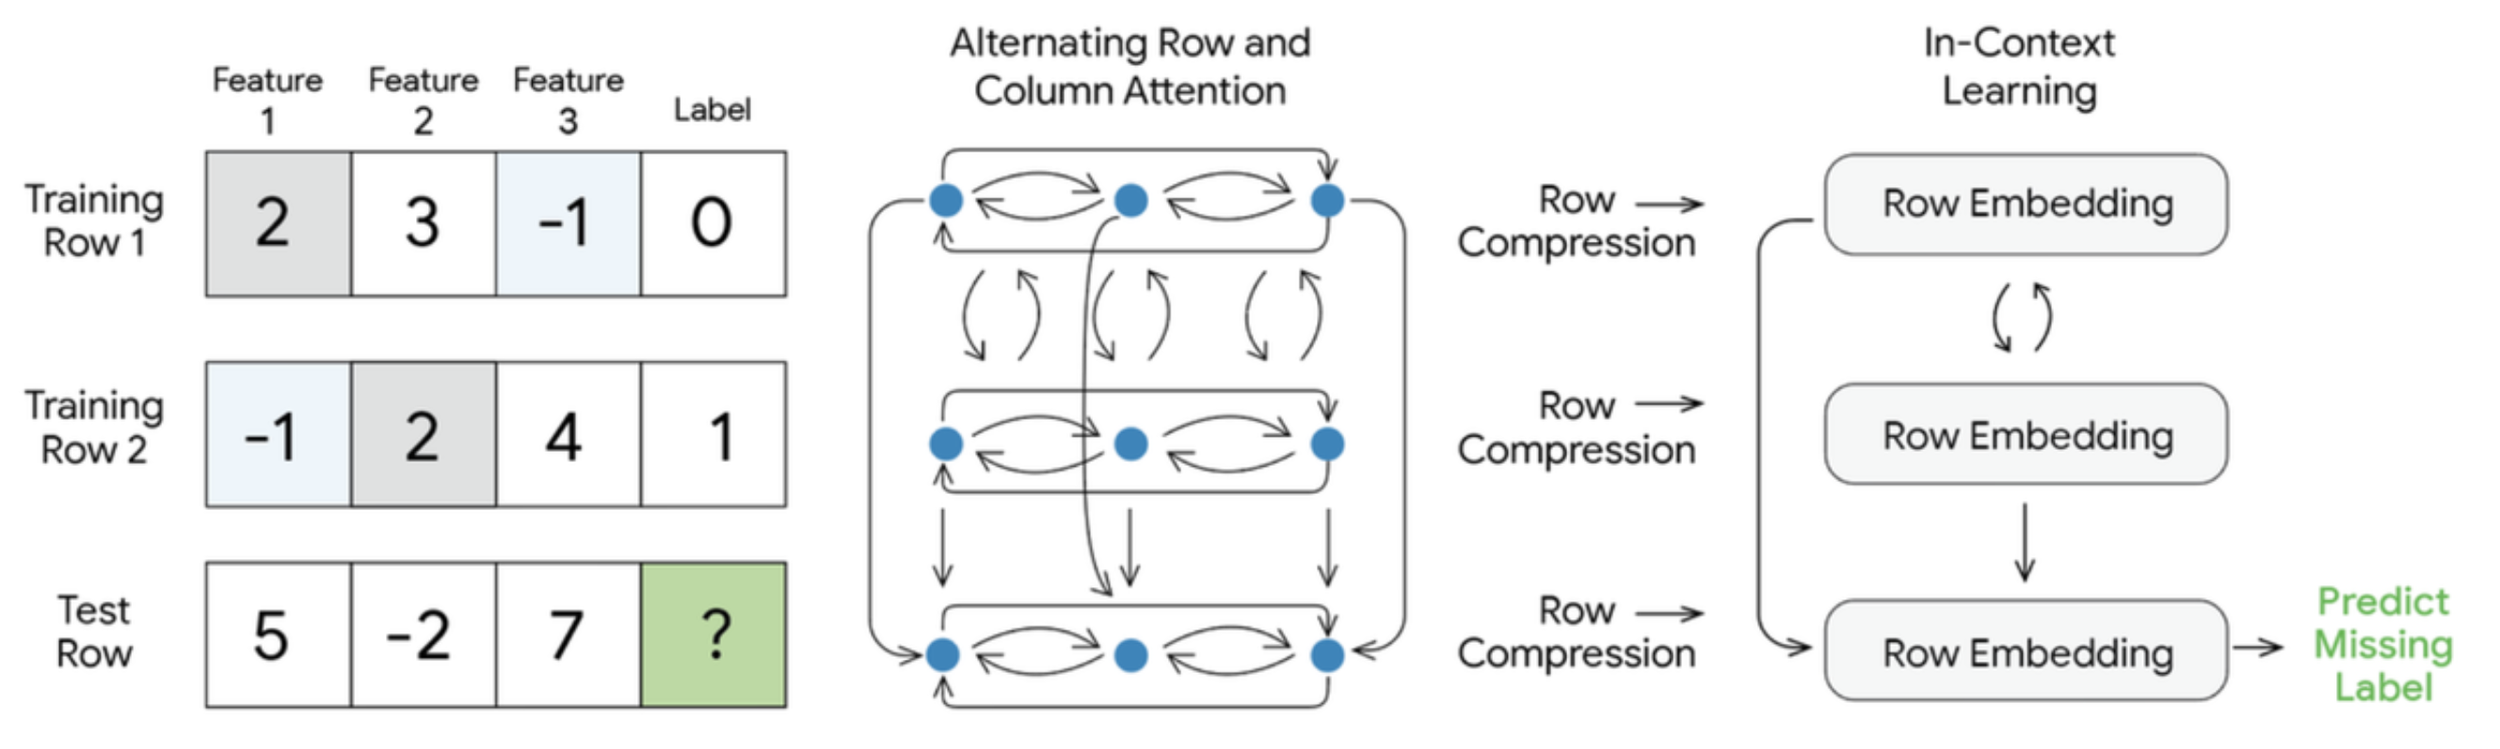
How is such a feat possible? The secret seems to lie in the architecture of TabFM. The figure below illustrates this.

            TabFM model architecture

Google explains it as follows

This architecture, visualized above, relies on three key mechanisms:

  • Alternating row and column attention: First, the raw table is processed through a multilayer attention module. Similar to TabPFN, this step applies alternating attention across both columns (features) and rows (examples). By continuously attending across these two dimensions, the model learns rich representations that natively capture complex feature interactions and dependencies. This deep contextualization effectively performs the heavy lifting that would otherwise require tedious manual feature crafting by data scientists.

  • Row compression: Following this contextualization, the rich, cross-attended information for each individual row is compressed into a single, dense vector representation.

  • In-context learning (ICL): Finally, a dedicated Transformer operates on this sequence of compressed embeddings. Adopting the highly efficient approach of TabICL, performing attention over these compressed row vectors — rather than the raw, uncompressed grid — drastically reduces the computation cost. This ensures the prediction step remains highly computationally efficient, even for much larger datasets.

It sounds somewhat complicated, but the bottom line is that it is "a method that applies attention across rows and columns, then compresses the rows, and finally treats the data table itself as a prompt, bringing it directly into prediction." Of course, pre-training is performed, but the data used for this is entirely synthetic. Please refer to the explanatory article for more details (1).


3. The Incredible Performance of TabFM

Now, let's take a look at TabFM's performance on the TabArena leaderboard (2). As shown below, it proudly holds the number one spot. Unfortunately, LightGBM, which I usually use, has sunk to the lower ranks. I was surprised to see such a huge gap. Since I wasn't particularly dissatisfied with LightGBM's performance, I never expected the difference to be this significant.

                  TabArena

Having been shown the performance of TabFM, I am now convinced that Google is absolutely serious about the following claim:

“This approach successfully eliminates the traditional bottlenecks of manual feature engineering, hyperparameter optimization, and repetitive model training, and consistently outperforms heavily tuned, industry-standard supervised algorithms.“

Seeing these results, I felt that a new wave of technology is approaching the realm of tabular data prediction as well.


What are your thoughts on this? This time, I introduced Google's TabFM technology, but looking at the technology more broadly, it can also be considered an application of In-Context Learning (ICL) to tabular data. In-Context Learning (ICL) is a technology cultivated within large language models, but its application might finally be expanding beyond text to various other fields. I am looking forward to seeing how it unfolds in the future. At Toshi Stats, we plan to continue challenging ourselves with the application of In-Context Learning (ICL) to tabular data. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) Introducing TabFM: A zero-shot foundation model for tabular data, Weihao Kong and Abhimanyu Das, Google Research, June 30, 2026
2)TabArena/leaderboard,  Hugging Face


Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

The AI Strategy for Churn Prediction: When to Use Open vs. Proprietary Models

Many of you might be struggling to decide which generative AI to choose, caught between high-performance but costly proprietary models (like the famous GPT and Opus) and cost-free open-weights models where it's uncertain just how many tasks they can handle. With Jensen Huang (Founder and CEO of NVIDIA) publishing a report on X titled "Open Weights and American AI Leadership" (1), the momentum supporting open-weights models has grown. Therefore, this time, I would like to actually run both models on a customer churn prediction task and compare which one is better.


1. Gemini 3.6 Flash and Gemma 4

Both models are from Google. Gemini 3.6 Flash (2) is a proprietary model that strikes a great balance between accuracy, speed, and cost, making it the perfect baseline for comparison. Gemma 4 (3) is an open-weights model, divided into five types based on its size. This time, keeping in mind running it on a PC without a GPU like a standard Windows PC, I would like to focus the comparison on the smallest Gemma 4 E2B QAT. This generative AI can even be deployed on small devices like mobile phones, and I am excited to see how well this model can hold its own against a large proprietary model. By the way, the PC I used is a MacBook Air M4-24GB. Let's get started!


2. Generating Special Offer Proposal Texts for Customers

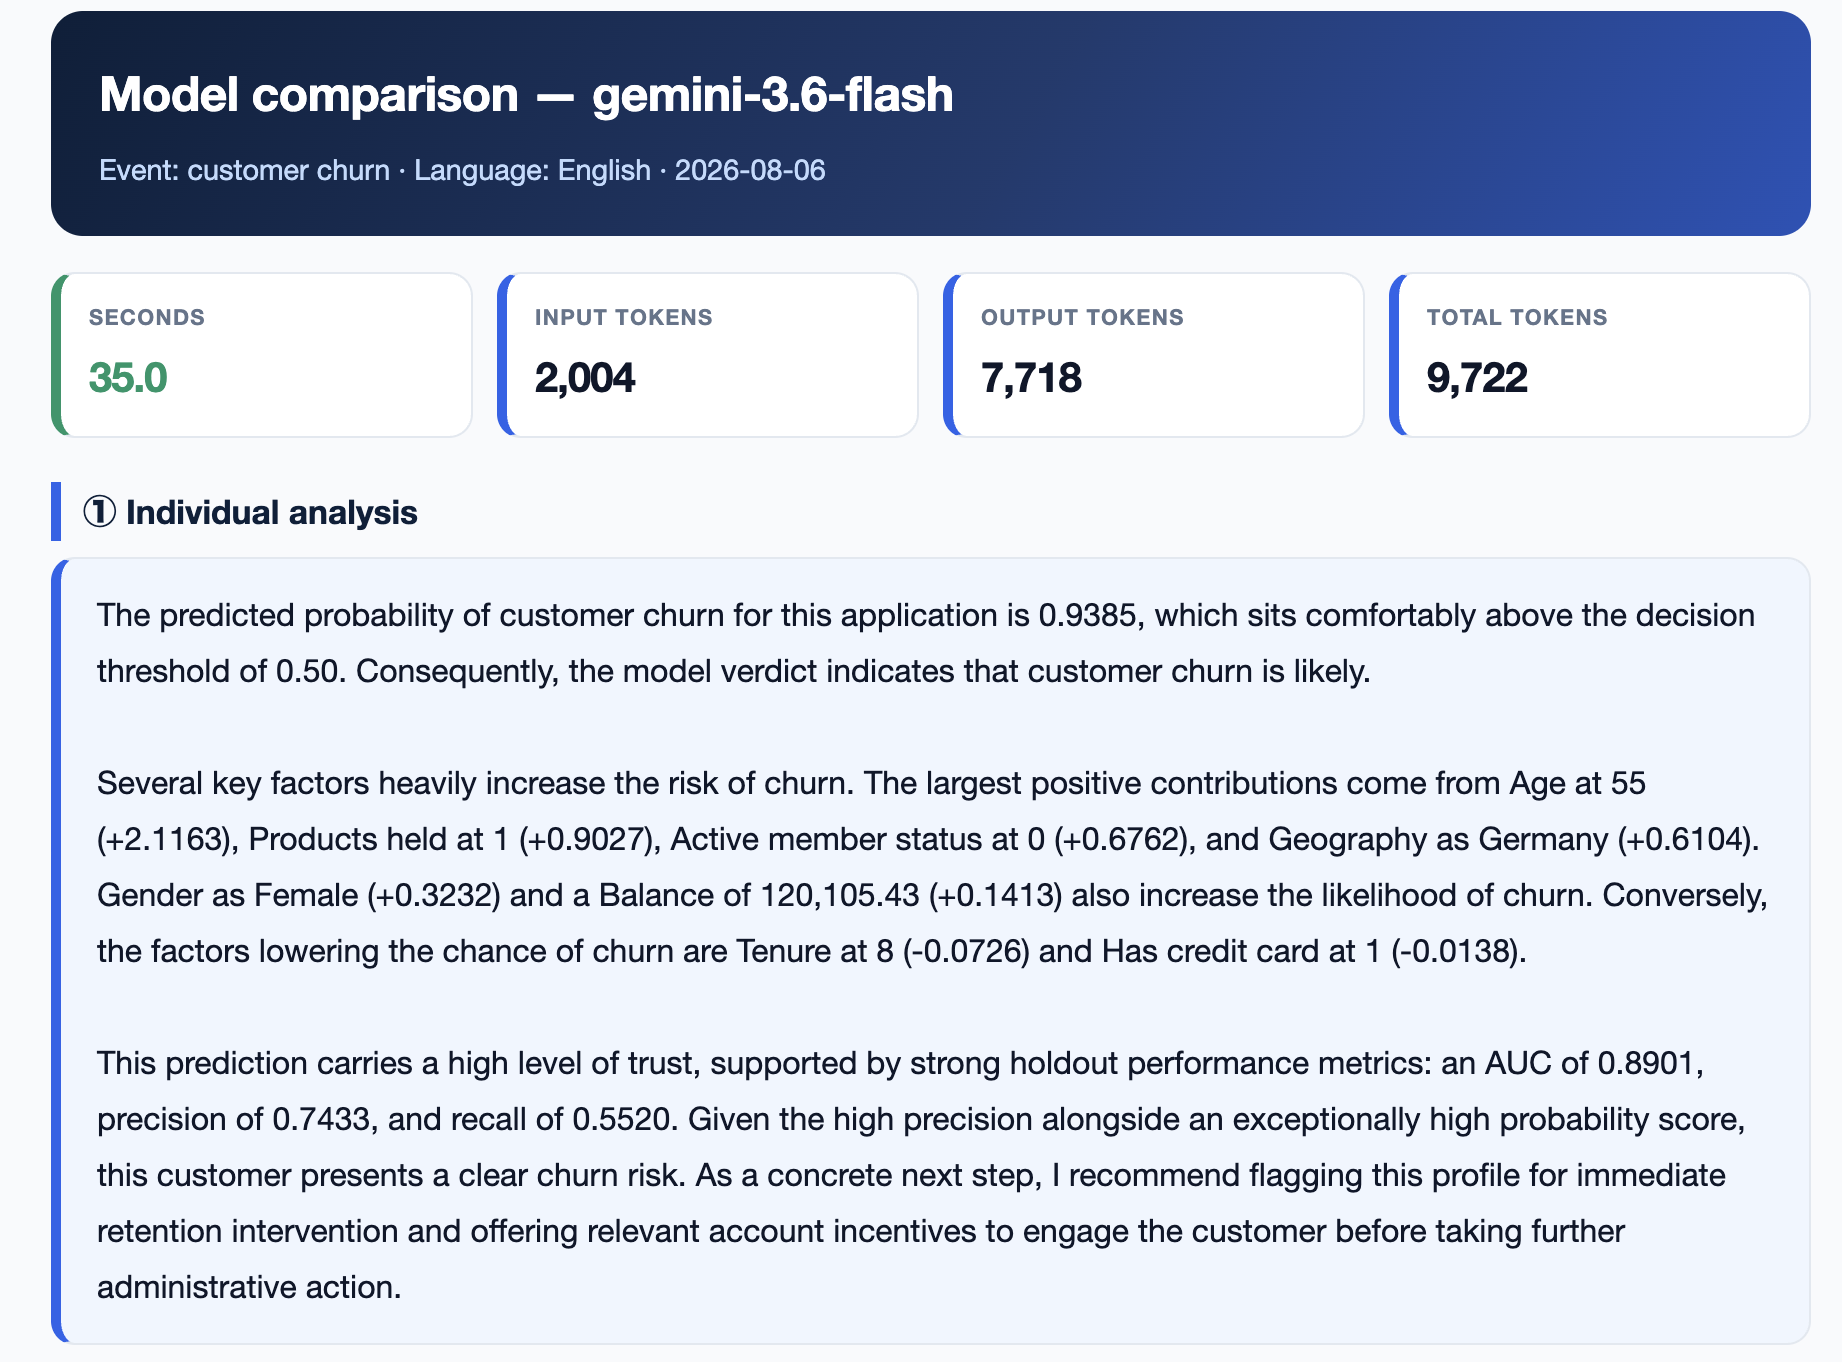
For the first experiment, I would like to actually try proposing preferential treatment to customers with a high probability of churning before they leave. The keys are: 1. Identifying customers who are likely to churn, and 2. Whether we can execute the notification of the preferential treatment offer in a timely manner. Here, we will leave 1 to a powerful machine learning library called LightGBM, and for 2, we will use generative AI to generate both the explanation of the analysis results and the notification letter to compare them. First, let's generate the analysis explanation text using Gemini 3.6 Flash as a baseline. The result is below. It is carefully explained in natural English.

‍ ‍ Analysis Explanation by Gemini 3.6 Flash

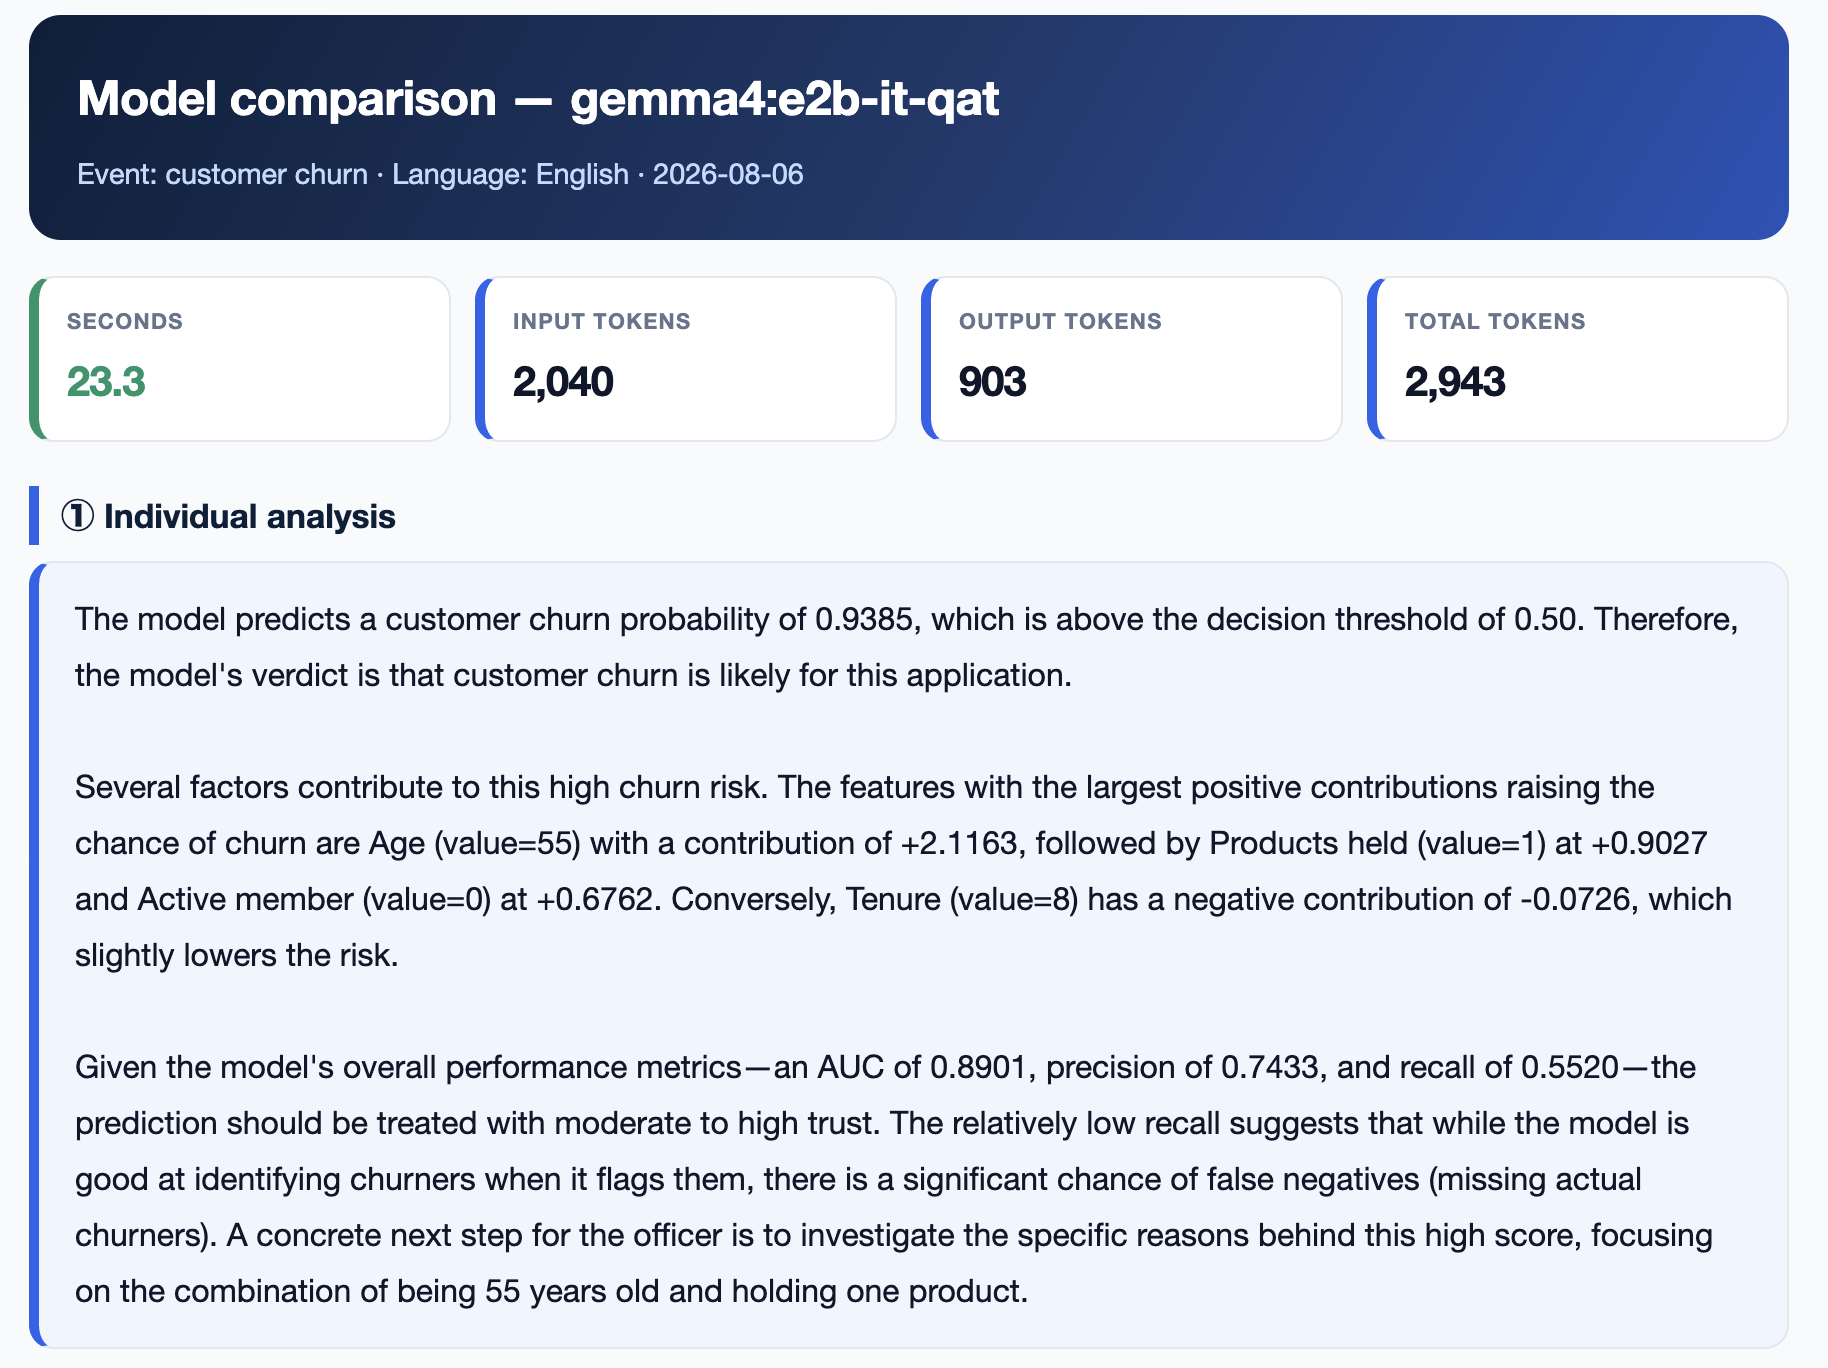
Next, let's try it with Gemma 4 E2B QAT. The results are as follows. This is also written in natural English. It's wonderful. Although it is the smallest model, it functions perfectly well. It looks like it could be immediately used in actual business operations. It is incredibly appreciated that a generative AI of this level can be used for free.

‍ ‍ Analysis Explanation by Gemma 4 E2B QAT

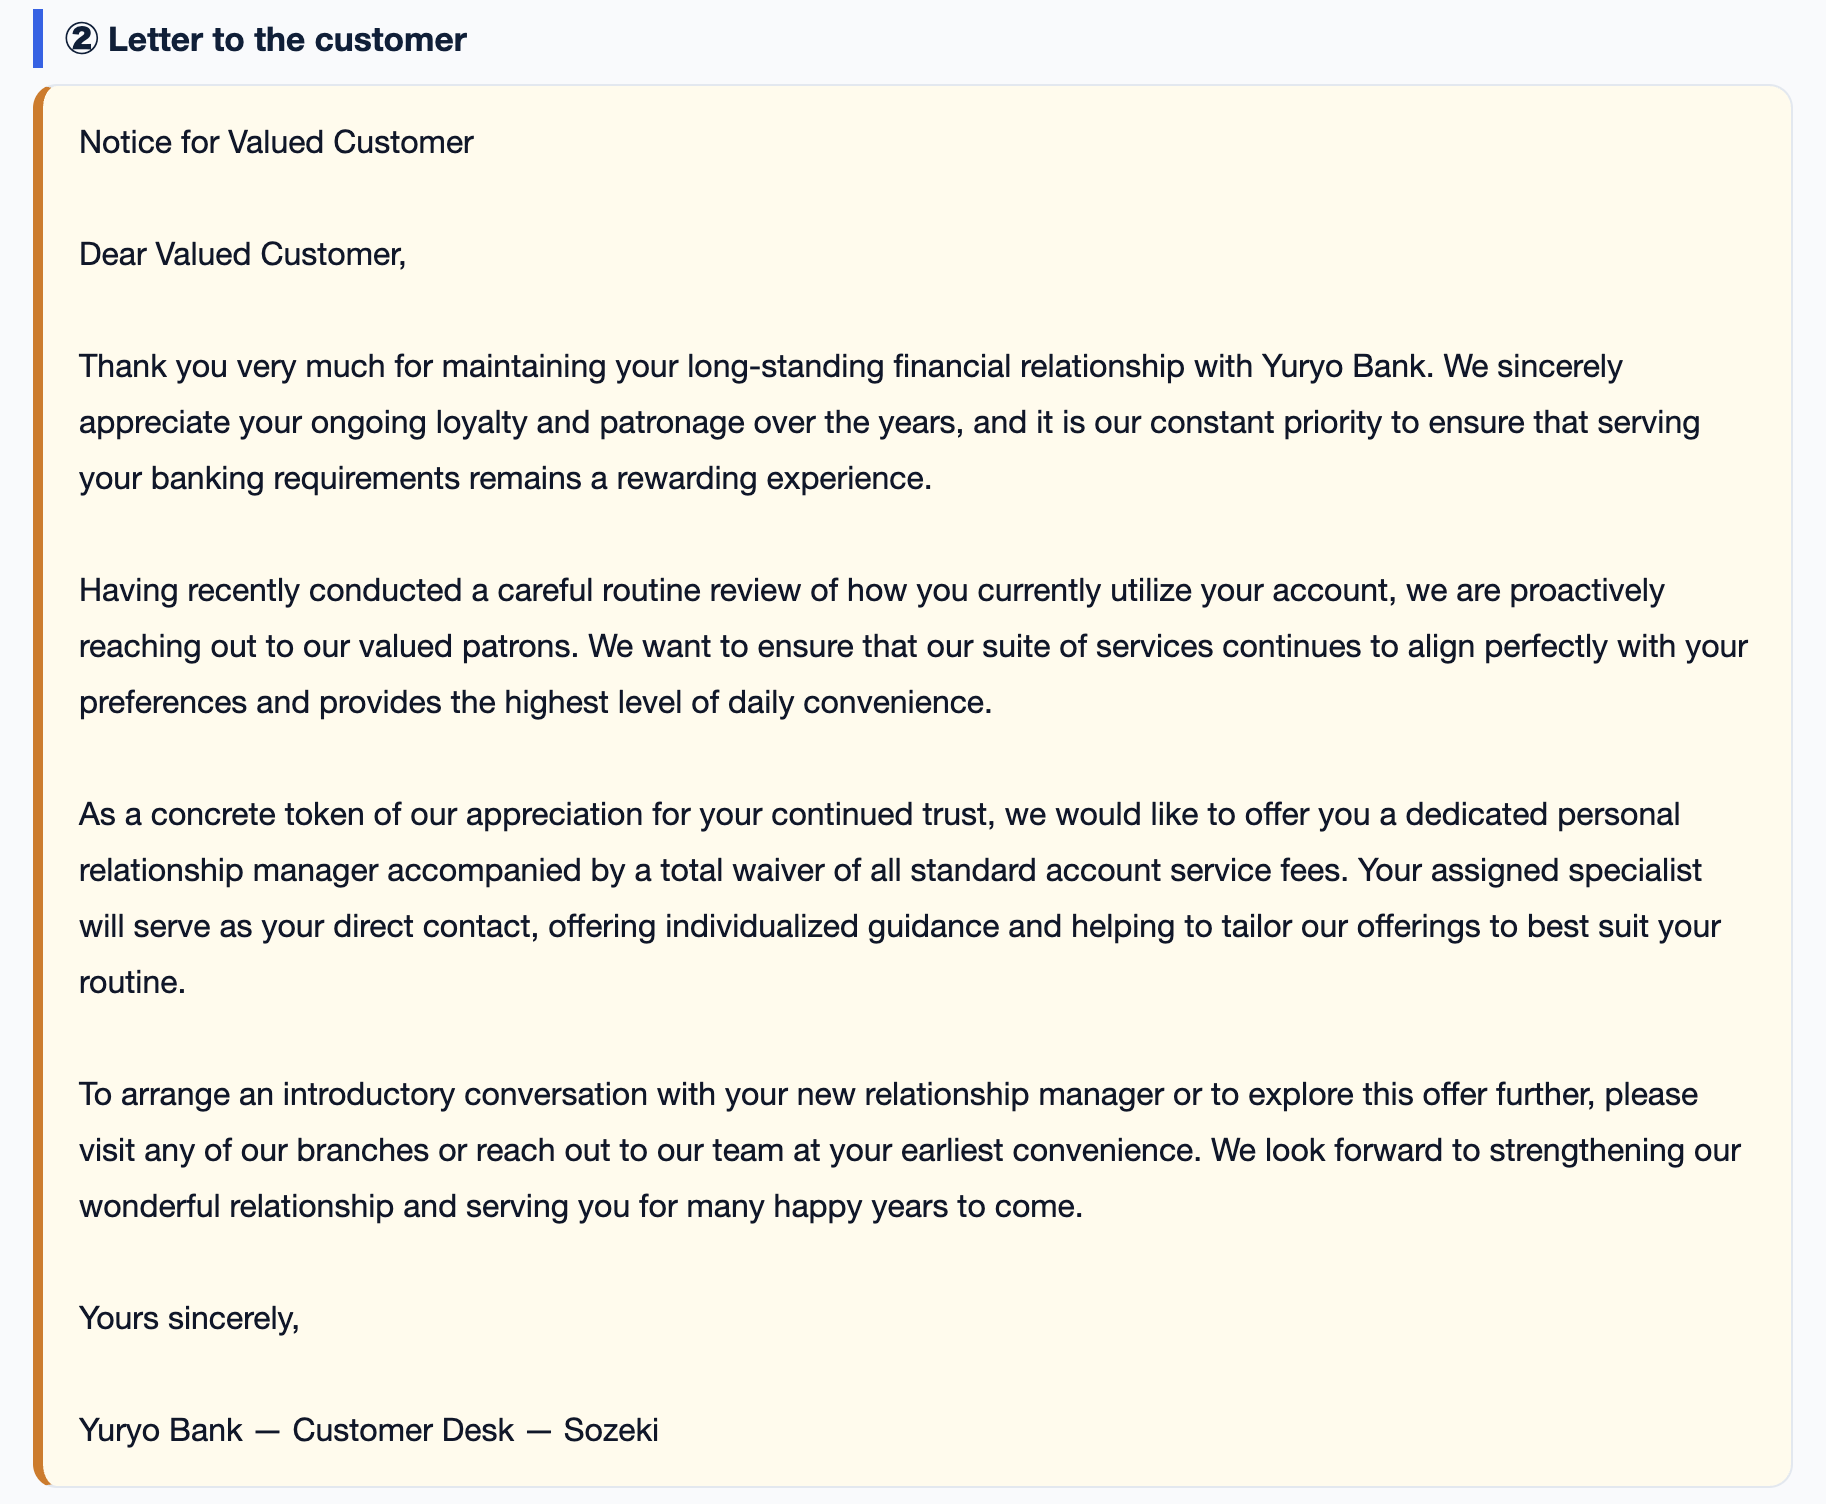
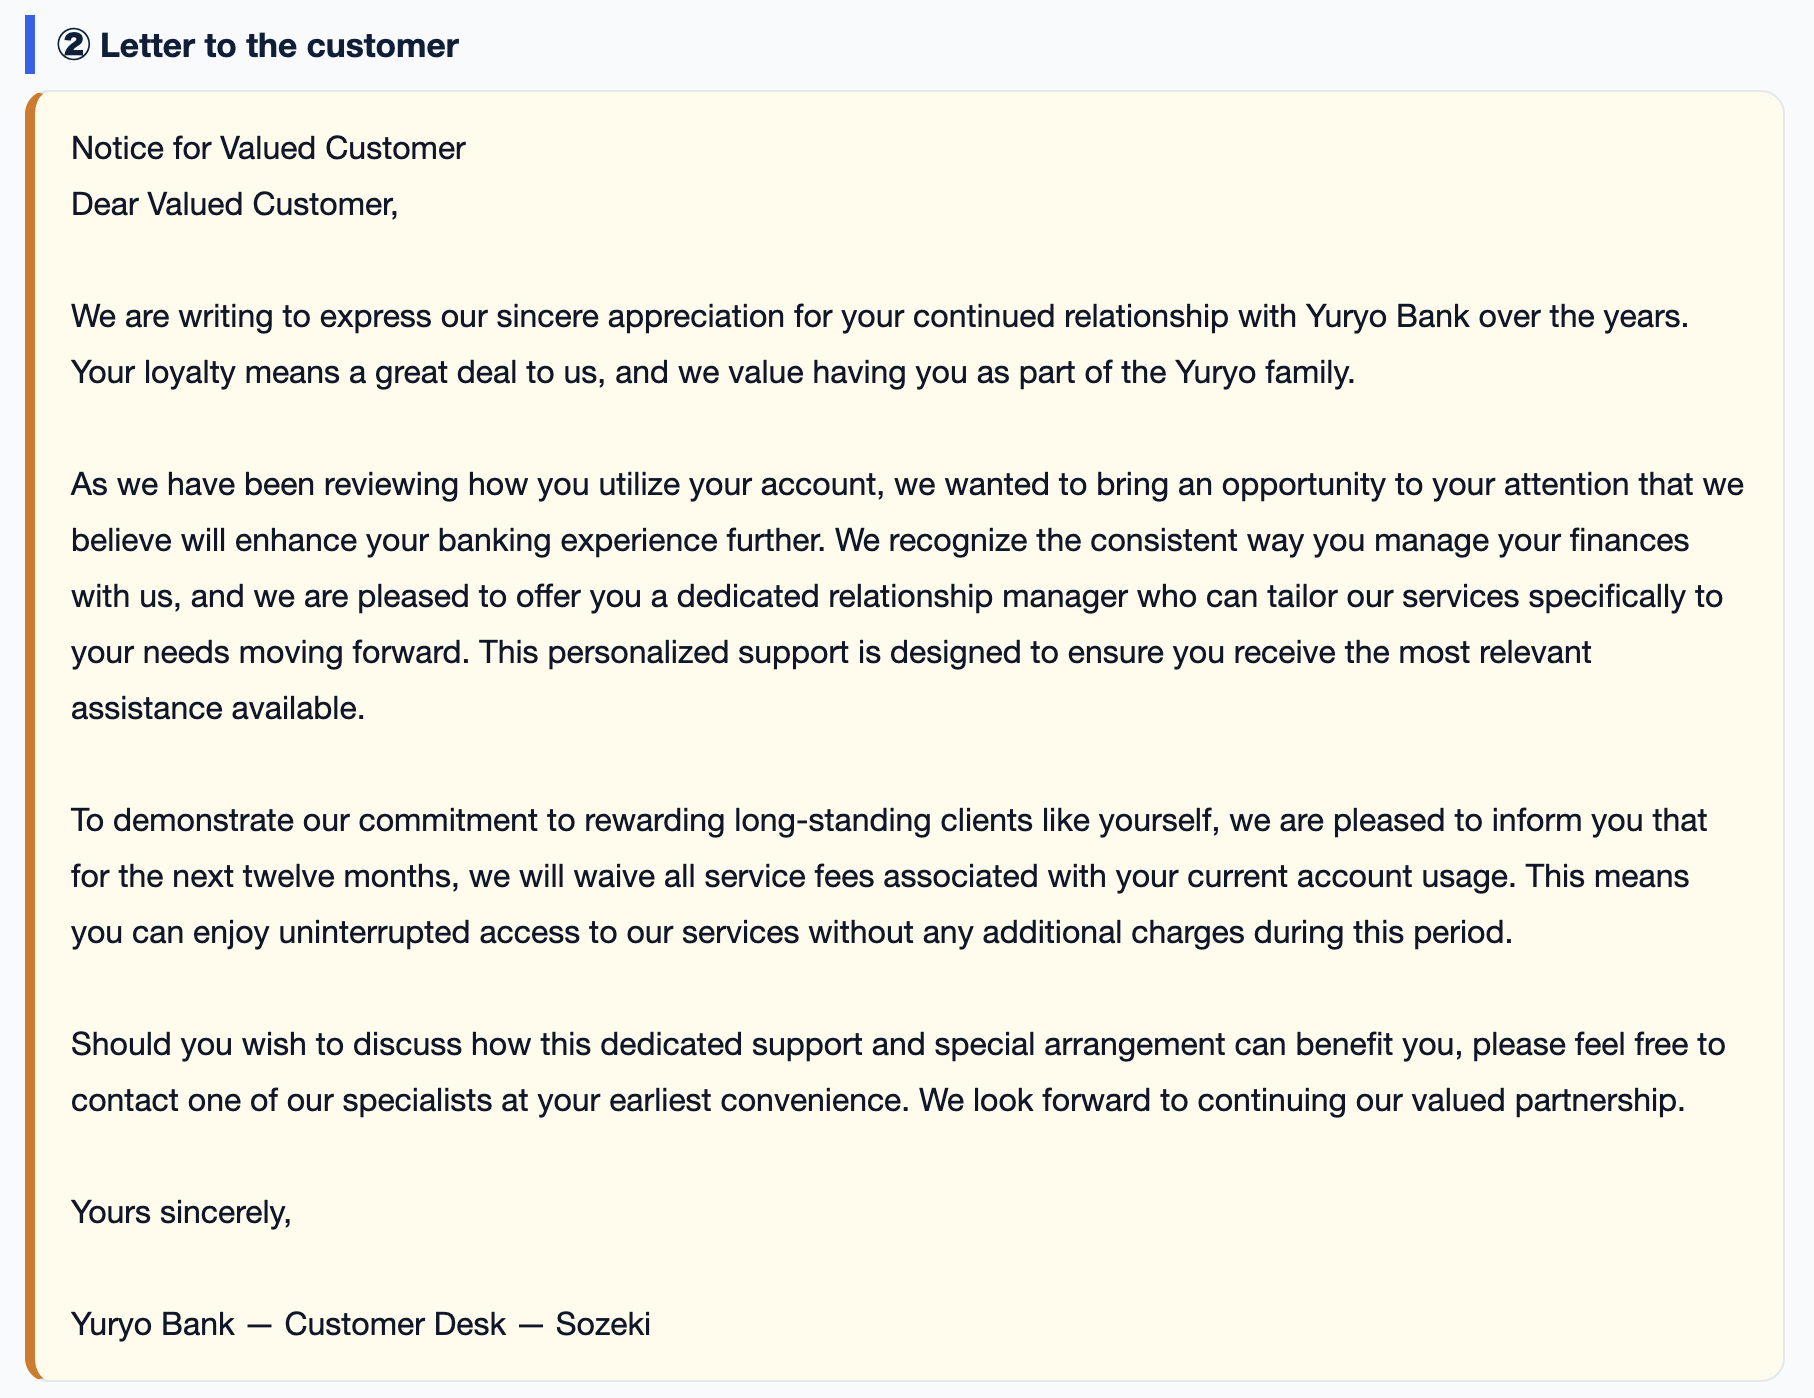
Now, I would like to create a notification letter for preferential treatment to prevent customers from churning. First up is Gemini 3.6 Flash, and as expected, it's perfect.

‍ ‍ Preferential Treatment Notification Letter by Gemini 3.6 Flash

Gemma 4 E2B QAT doesn't fall behind either. This is also written in natural Japanese and has sufficient content. With this, I think it has reached a quality that can be sent to customers. I am a bit moved that even an open-weights model can do this much.

‍ ‍ Preferential Treatment Notification Letter by Gemma 4 E2B QAT

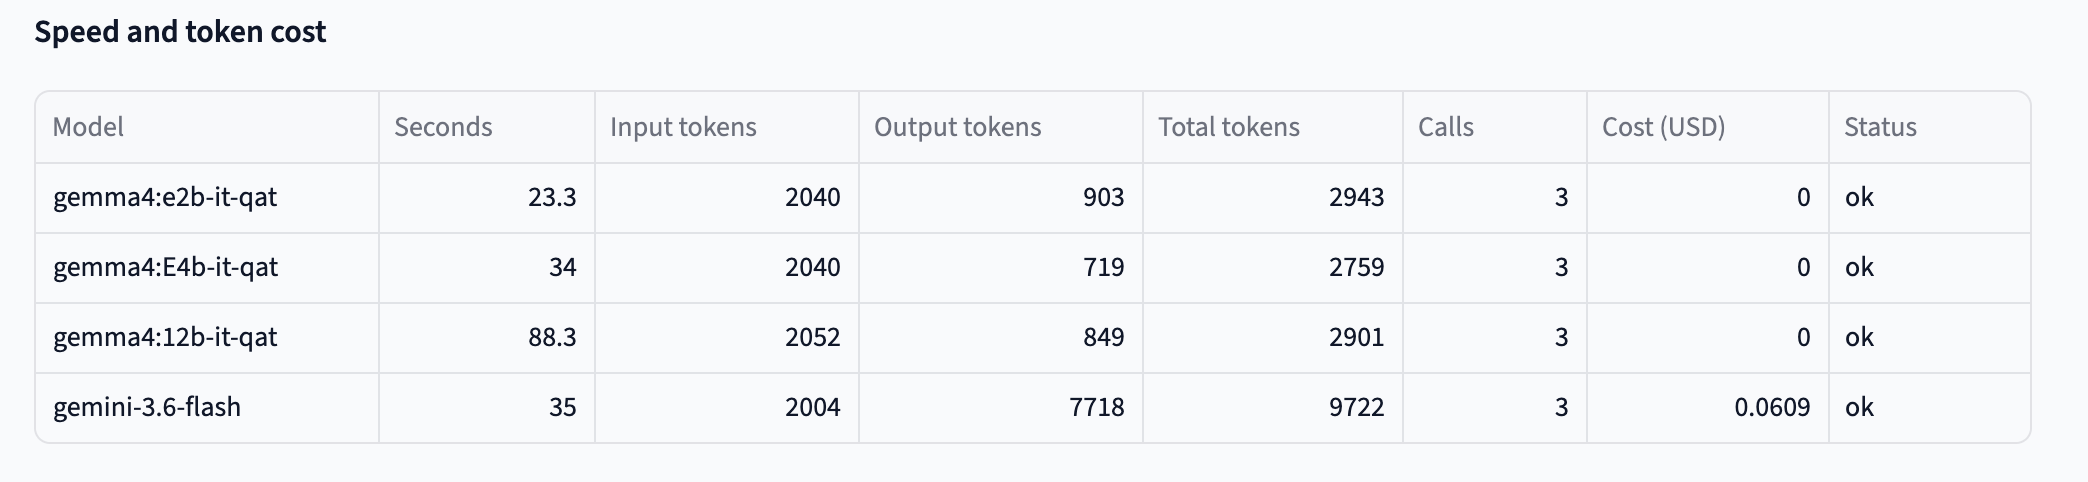
I have summarized the results here. I have added two open-weights models with slightly larger parameters here. The time taken for computation inevitably gets longer as the parameters increase. By the way, even if you use these models, naturally, there are no usage fees. That is the wonderful thing about open-weights models. Gemini 3.6 Flash is the only proprietary model, and it boasts extremely fast speeds. It fully demonstrated its performance here as well, recording the second-fastest speed. This is a point worth noting. However, it does incur a cost, so budget management is essential when a large amount of processing is required. This cost is calculated based on generating the three types of texts.

‍ ‍ Summary of the Text Generation Task


3. On-Demand Data Analysis

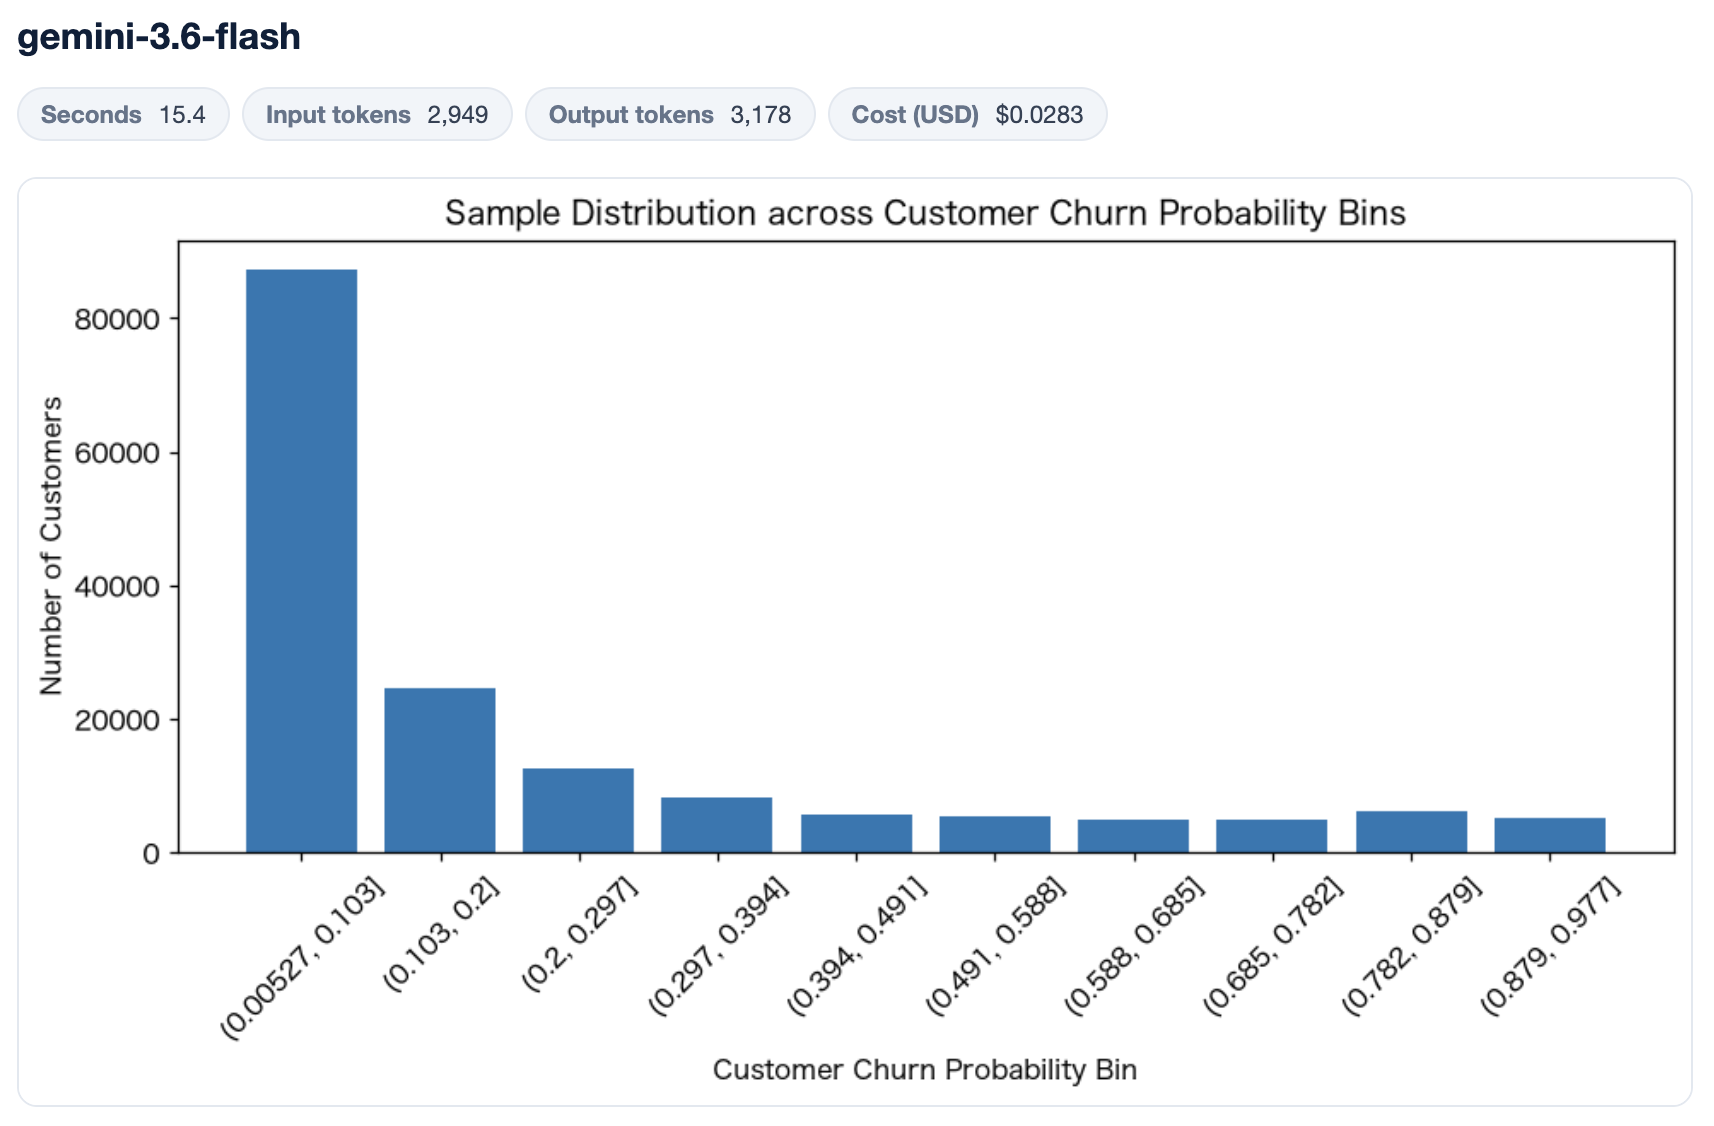
This time, I would like to provide data to the generative AI and execute data analysis. I will visualize what percentage of the total customers are likely to churn. This is information that marketing personnel would definitely want. Normally, this is a task performed by data scientists who can write Python, but this time I want to challenge how far we can take data analysis by giving instructions via prompts and having the generative AI generate the Python code. First, let's try it with Gemini 3.6 Flash. As expected, it turned out perfectly.

‍  ‍     Visualization of Customer Distribution by Gemini 3.6 Flash

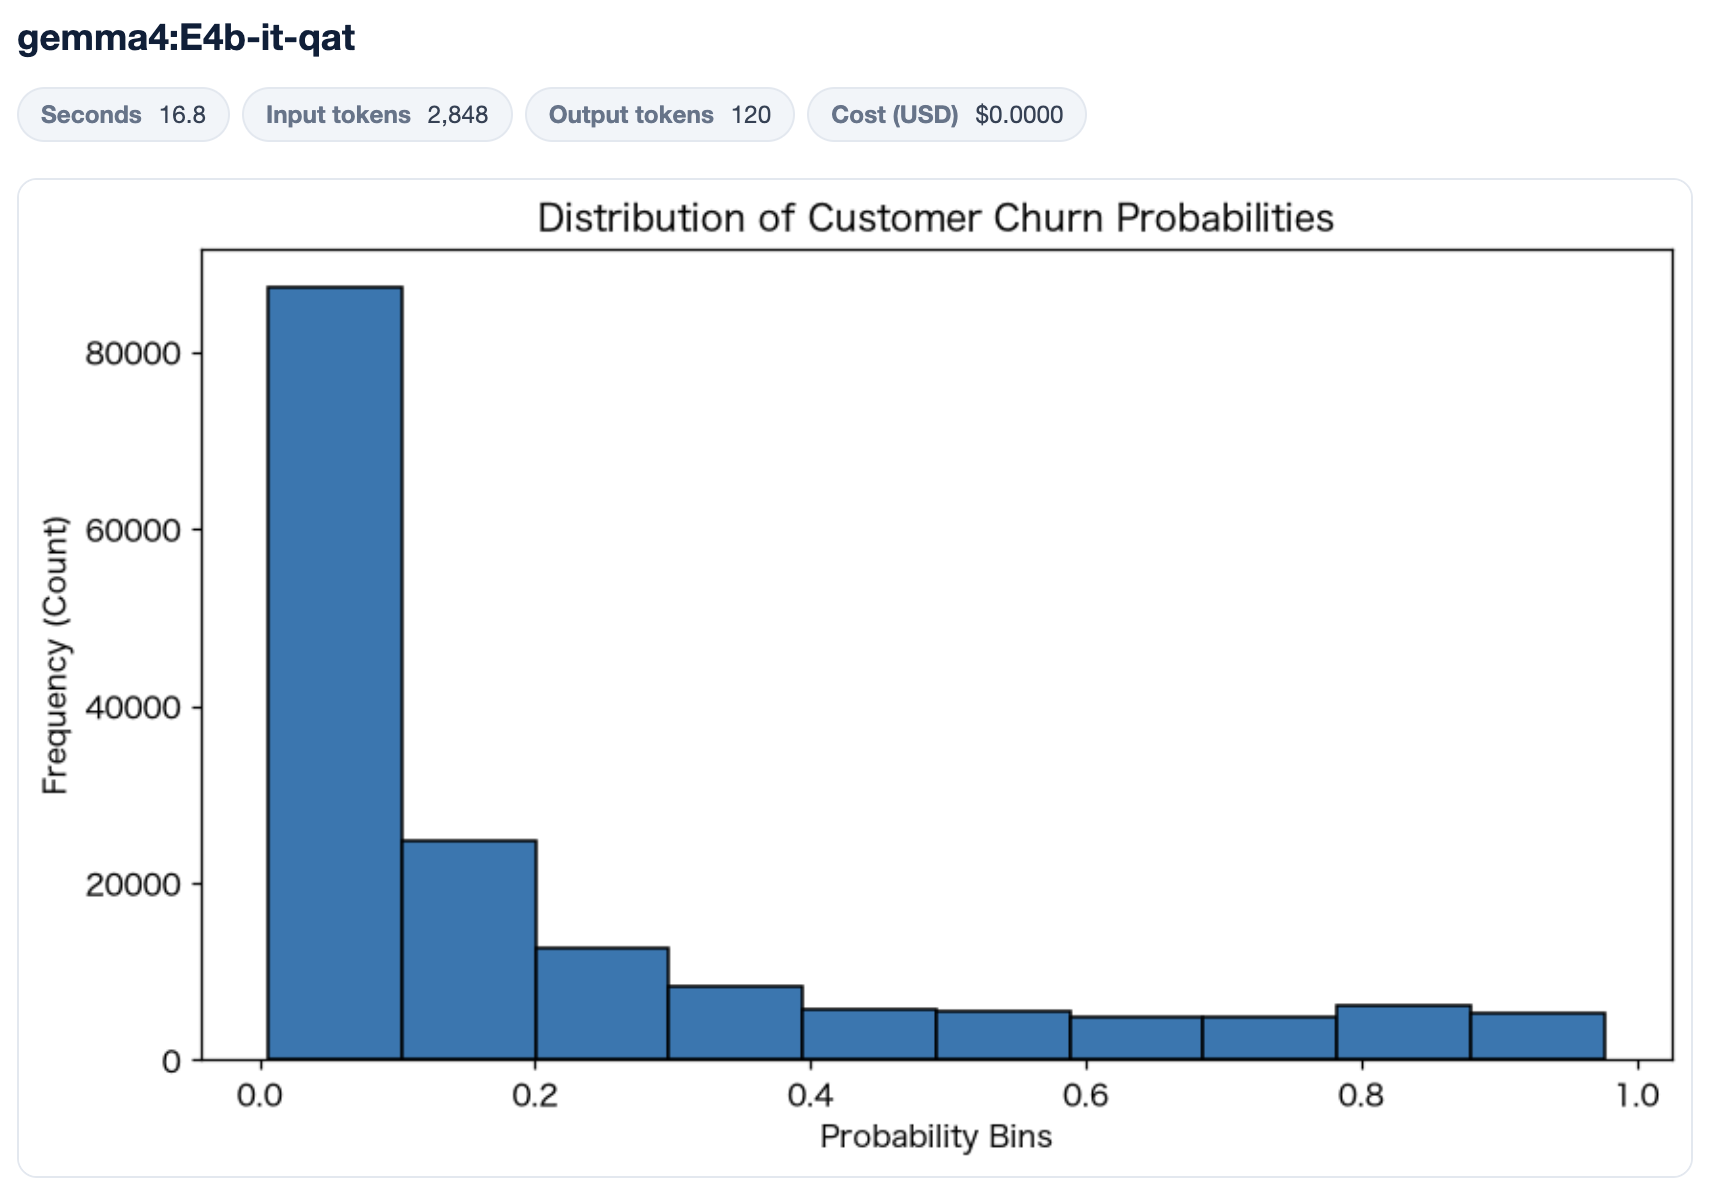
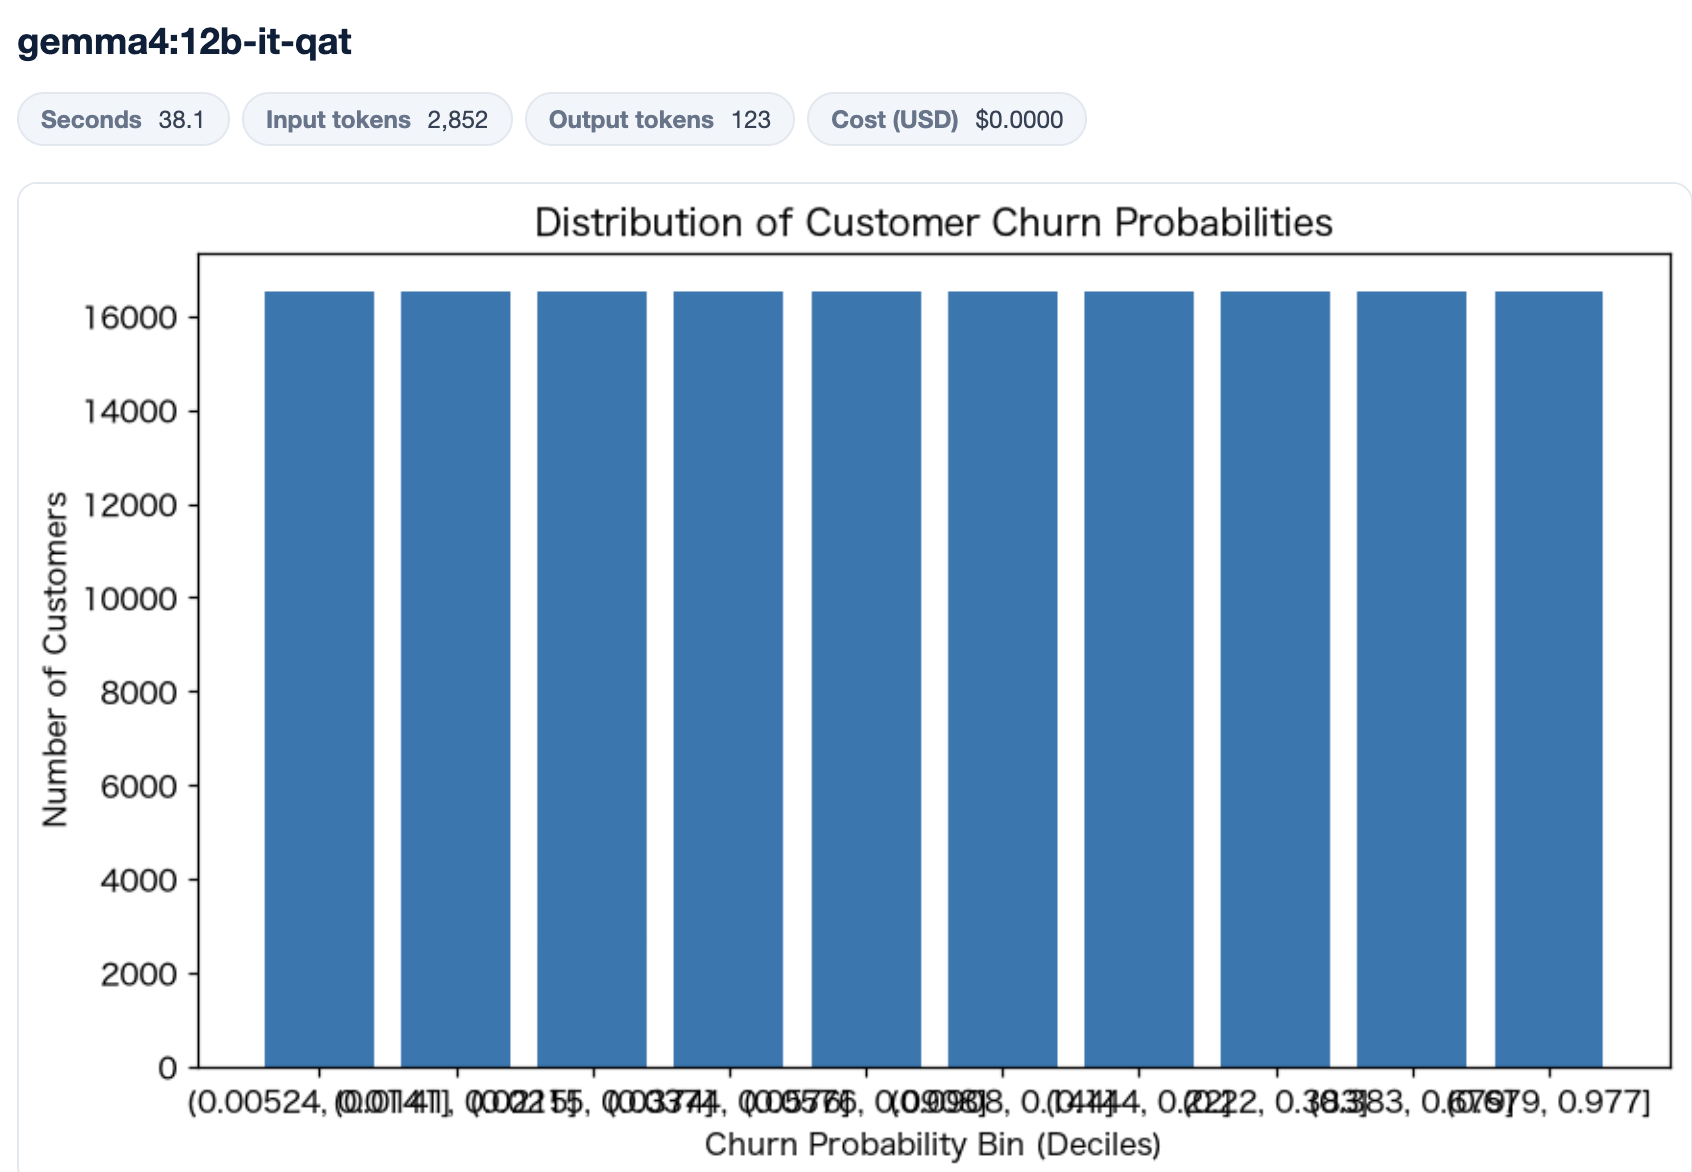
Next, I wanted to show the results for gemma4:E2b-it-qat, but unfortunately, it did not succeed after 3 attempts. It seems to have been a somewhat difficult task for a small generative AI. This time, all the prompt instructions were fixed and unchanged, but I think there is a possibility that even a small generative AI could succeed with some adjustments. The larger gemma4:E4b-it-qat worked out well, but gemma4:12b-it-qat failed as shown below. Code generation tasks might be quite a heavy burden for gemma4.

‍  ‍       Visualization of Customer Distribution by gemma4:E4b-it-qat

‍  ‍         Visualization of Customer Distribution by gemma4:12b-it-qat


What did you think? As we found out from this experiment, the cases where you would want to prioritize using an open-weights model are:

  • When handling confidential information and you want to complete the processing entirely on a local PC.

  • When budget management is strict and you cannot bear the costs.

  • When the task is centered around text generation.

Code generation tasks might reach a practical level if the prompts are adjusted. We at Toshi Stats will continue to take on these challenges. Stay tuned!

You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Open Weights and American AI Leadership, Jensen Huang (Founder and CEO of NVIDIA), July 24, 2026
2) Gemini 3.6 Flash Best for token efficiency in coding, knowledge work, and multimodal tasks, Google DeepMind
3) Gemma 4 QAT models: Optimizing model compression for mobile and laptop efficiency, Google, Jun 05, 2026

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Opus 5 is Here: The Ultimate Game Changer for Product Development

On July 24, 2026, Anthropic released its new generative AI, Opus5 (1). Shortly after that, a discussion about Opus5 by Boris Cherny, the developer of Claude Code, was published on YouTube (2). Because the content was highly informative, I would like to briefly summarize the main points and consider the implications for future product development.


1.Boris's Recommendations

First of all, Boris stated, "Opus5 can run continuously for weeks if you use the auto mode, which allows for continuous operation." In fact, in his own project, Opus5 has already been running for over two weeks and is still ongoing. If it can operate for such a long time, it seems capable of handling quite complex tasks. Since the continuous operation time of generative AI models half a year ago was said to be about 12 hours, this is a dramatic increase. Furthermore, to unlock the potential of Opus5, Boris emphasized two points: "give Opus5 tasks that seem a bit difficult" and "think about how to verify the results and outcomes." It seems better to just try it out and figure things out after observing Opus5's behavior. I felt he was emphasizing that things are quite different from half a year ago, noting things like, "It is not recommended for humans to predict specific instructions in advance because they are not always correct," and "Writing instructions too detailed gets in the way of bringing out Opus5's capabilities."


2.Opus5 is also good at understanding complex data

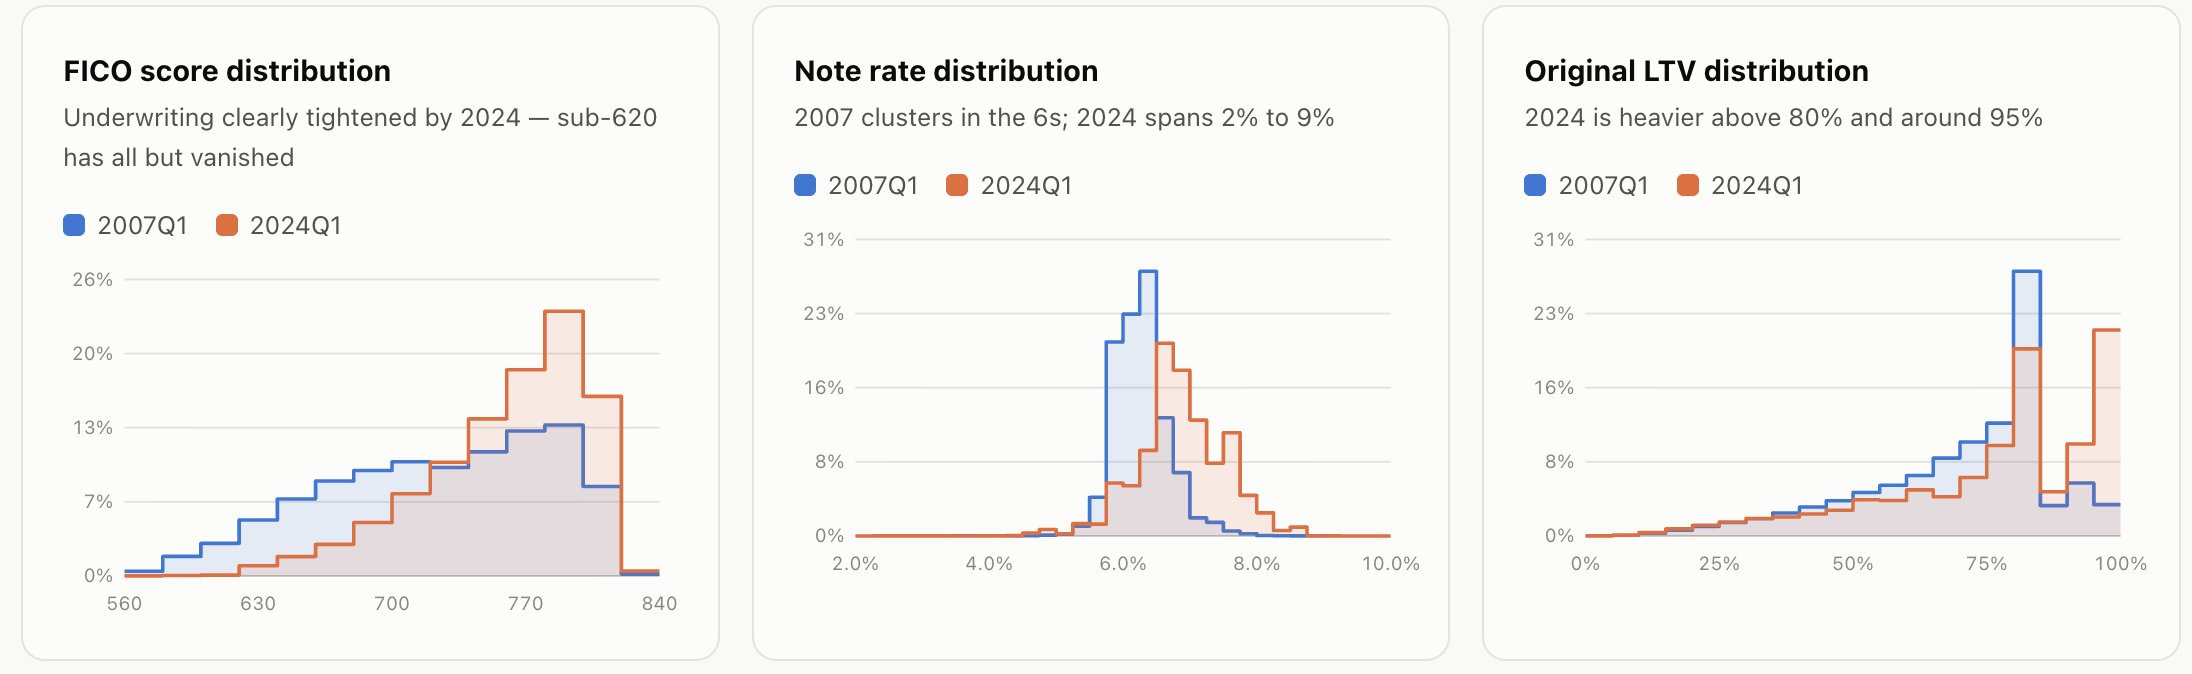
To test the method of "not writing detailed instructions" suggested by Boris, I obtained complex mortgage data, "Fannie Mae Single-Family Loan Performance" (3), and tried analyzing it using Opus5 on Claude Cowork. However, the prompt I provided was minimal, exactly as Boris suggested: "What is in the FannieMaeSingleFamilyLoan? Please explain it using graphs." Nevertheless, the analysis and graphs produced by Opus5 were excellent, as shown below. For example, it output the distribution of FICO and LTV. This makes it easy to compare with 17 years ago.

‍ ‍ FICO and LTV distribution status

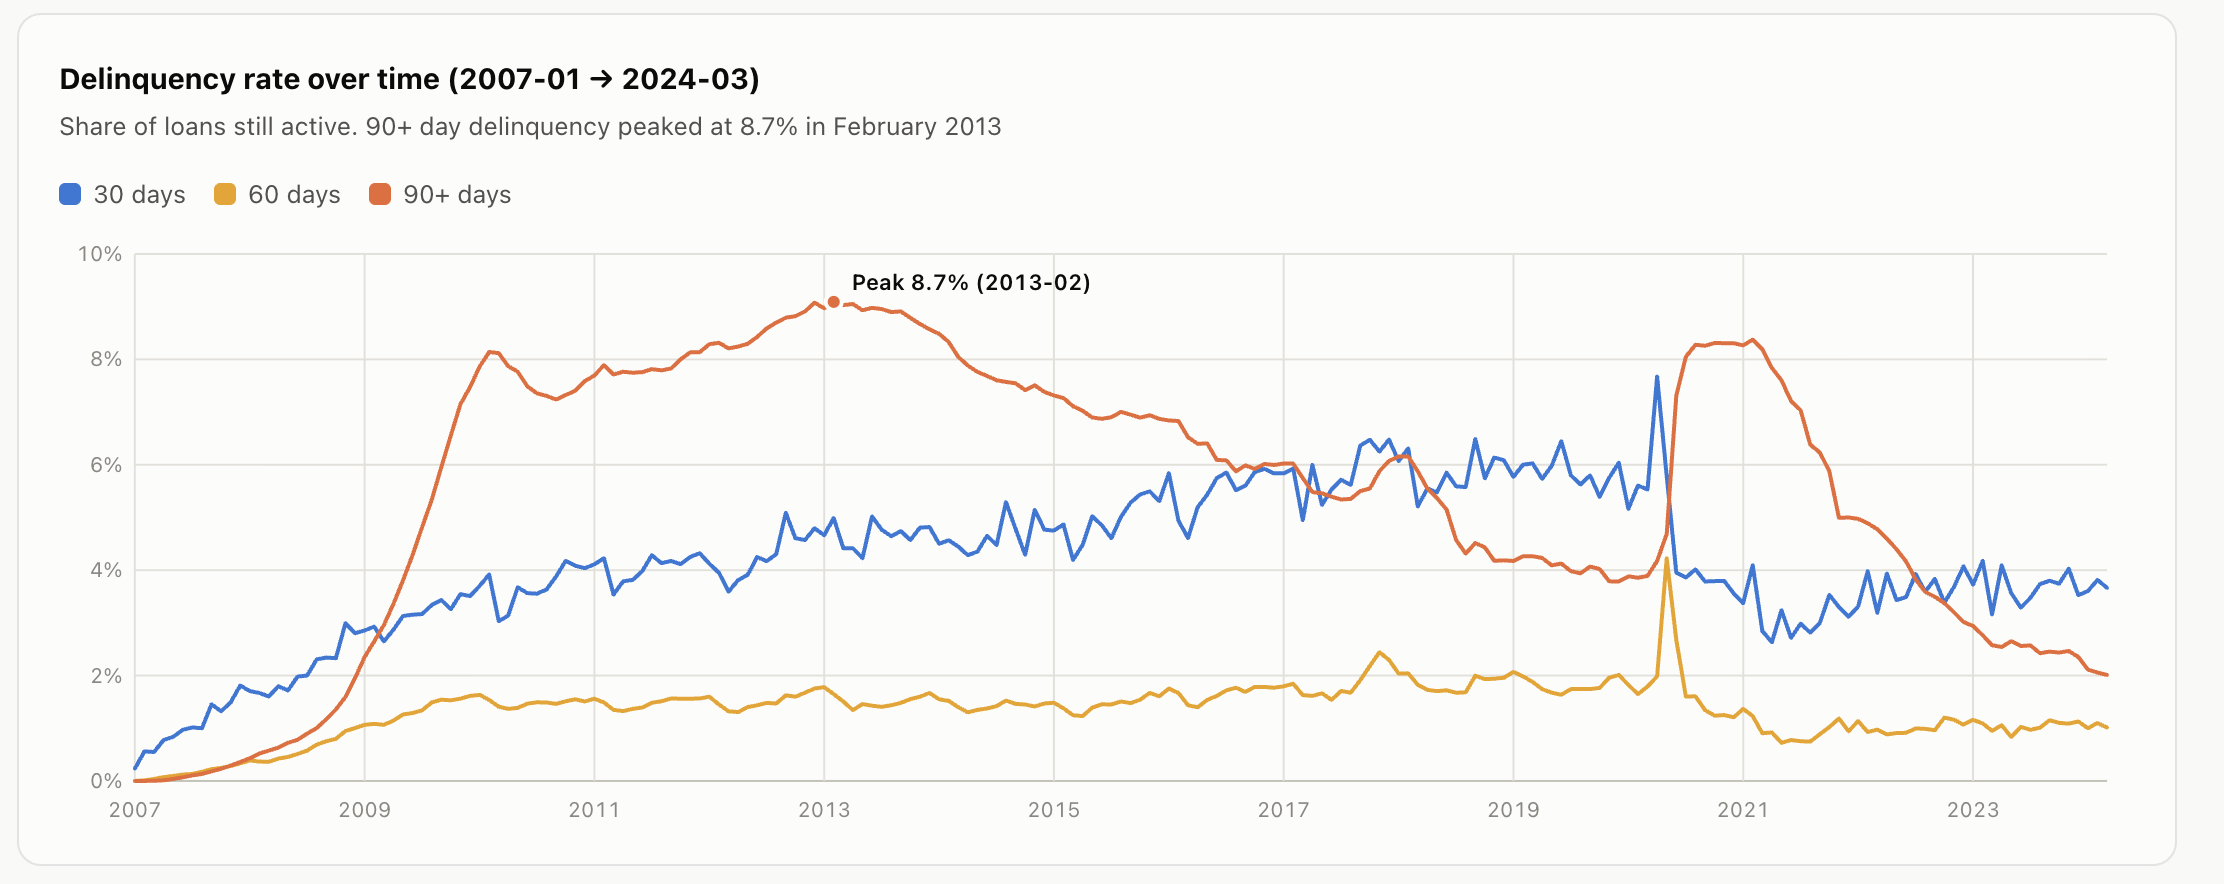
There is also a trend graph for the occurrence of past delinquent loans. Looking at this, you can immediately tell around when delinquencies peaked.

‍ ‍ Transition of delinquency rates

It also beautifully visualizes the relationship between each explanatory variable/feature and the default rate.

‍ ‍ Each explanatory variable/feature and default rate

Finally, it visualized defaults using a matrix of the two features most likely related to default: FICO and LTV. It's surprising that Opus5 can do this autonomously to this extent, even though I didn't give any specific instructions for it.

‍ ‍ FICO/LTV and default rate


3.Operating over 1,000 agents

Boris commented that he is "running over 1,000 agents." He mentioned he uses a feature in Claude Code called "Dynamic Workflows." He expressed the view that, theoretically speaking, this means performing test-time computing while automatically optimizing it. Indeed, coupled with the ability to run for long periods, this seems to be the key to improving accuracy. Unfortunately, I have not yet used "Dynamic Workflows," so I would like to give it a try next time. I am really looking forward to it, as it seems it will be highly effective, especially for complex data analysis tasks.


What do you think? Opus5 might indeed possess potential on a completely different dimension from conventional models. What caught my attention is that in "ARC-AGI 3," an evaluation test where the model has to solve unknown problems, Opus5's score has skyrocketed (1). I have high expectations that Opus5 will be able to distinguish and recognize even unprecedented patterns.

At Toshi Stats, we plan to continue tackling various tasks using Opus5. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Introducing Claude Opus 5,  Anthropic, July 24, 2026 
2) Boris Cherny: We Cut 80% of Claude Code’s Prompt, Y Combinator,  Jul 28, 2026
3) Fannie Mae Single-Family Loan Performance, kaggle

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Google's Gemma 4 E2B: The Ultimate Game Changer in On-Device AI

Have you ever worried about the next billing amount when running a generative AI for long hours? This is especially true since high-performance frontier models can easily run continuously for half a day or more. While we understand the incredible performance they offer, I'm sure many of you are wondering, "Isn't there a way to operate generative AI at a lower cost?" So, today, I would like to introduce "Gemma 4 E2B", an open-weight generative AI that you can download and use right on your local PC.


1. The Highly Anticipated Open-Weight Generative AI from Google: "Gemma 4 E2B"

Various AI companies have released open-weight generative AI models. My personal focus is on the Gemma series from Google, which is now in its 4th generation. It has steadily powered up with each generation, and among them, the performance of the smallest latest version, "Gemma 4 E2B QAT" (1), is particularly outstanding. This time, I built an application that predicts customer churn by combining machine learning with "Gemma 4 E2B QAT."

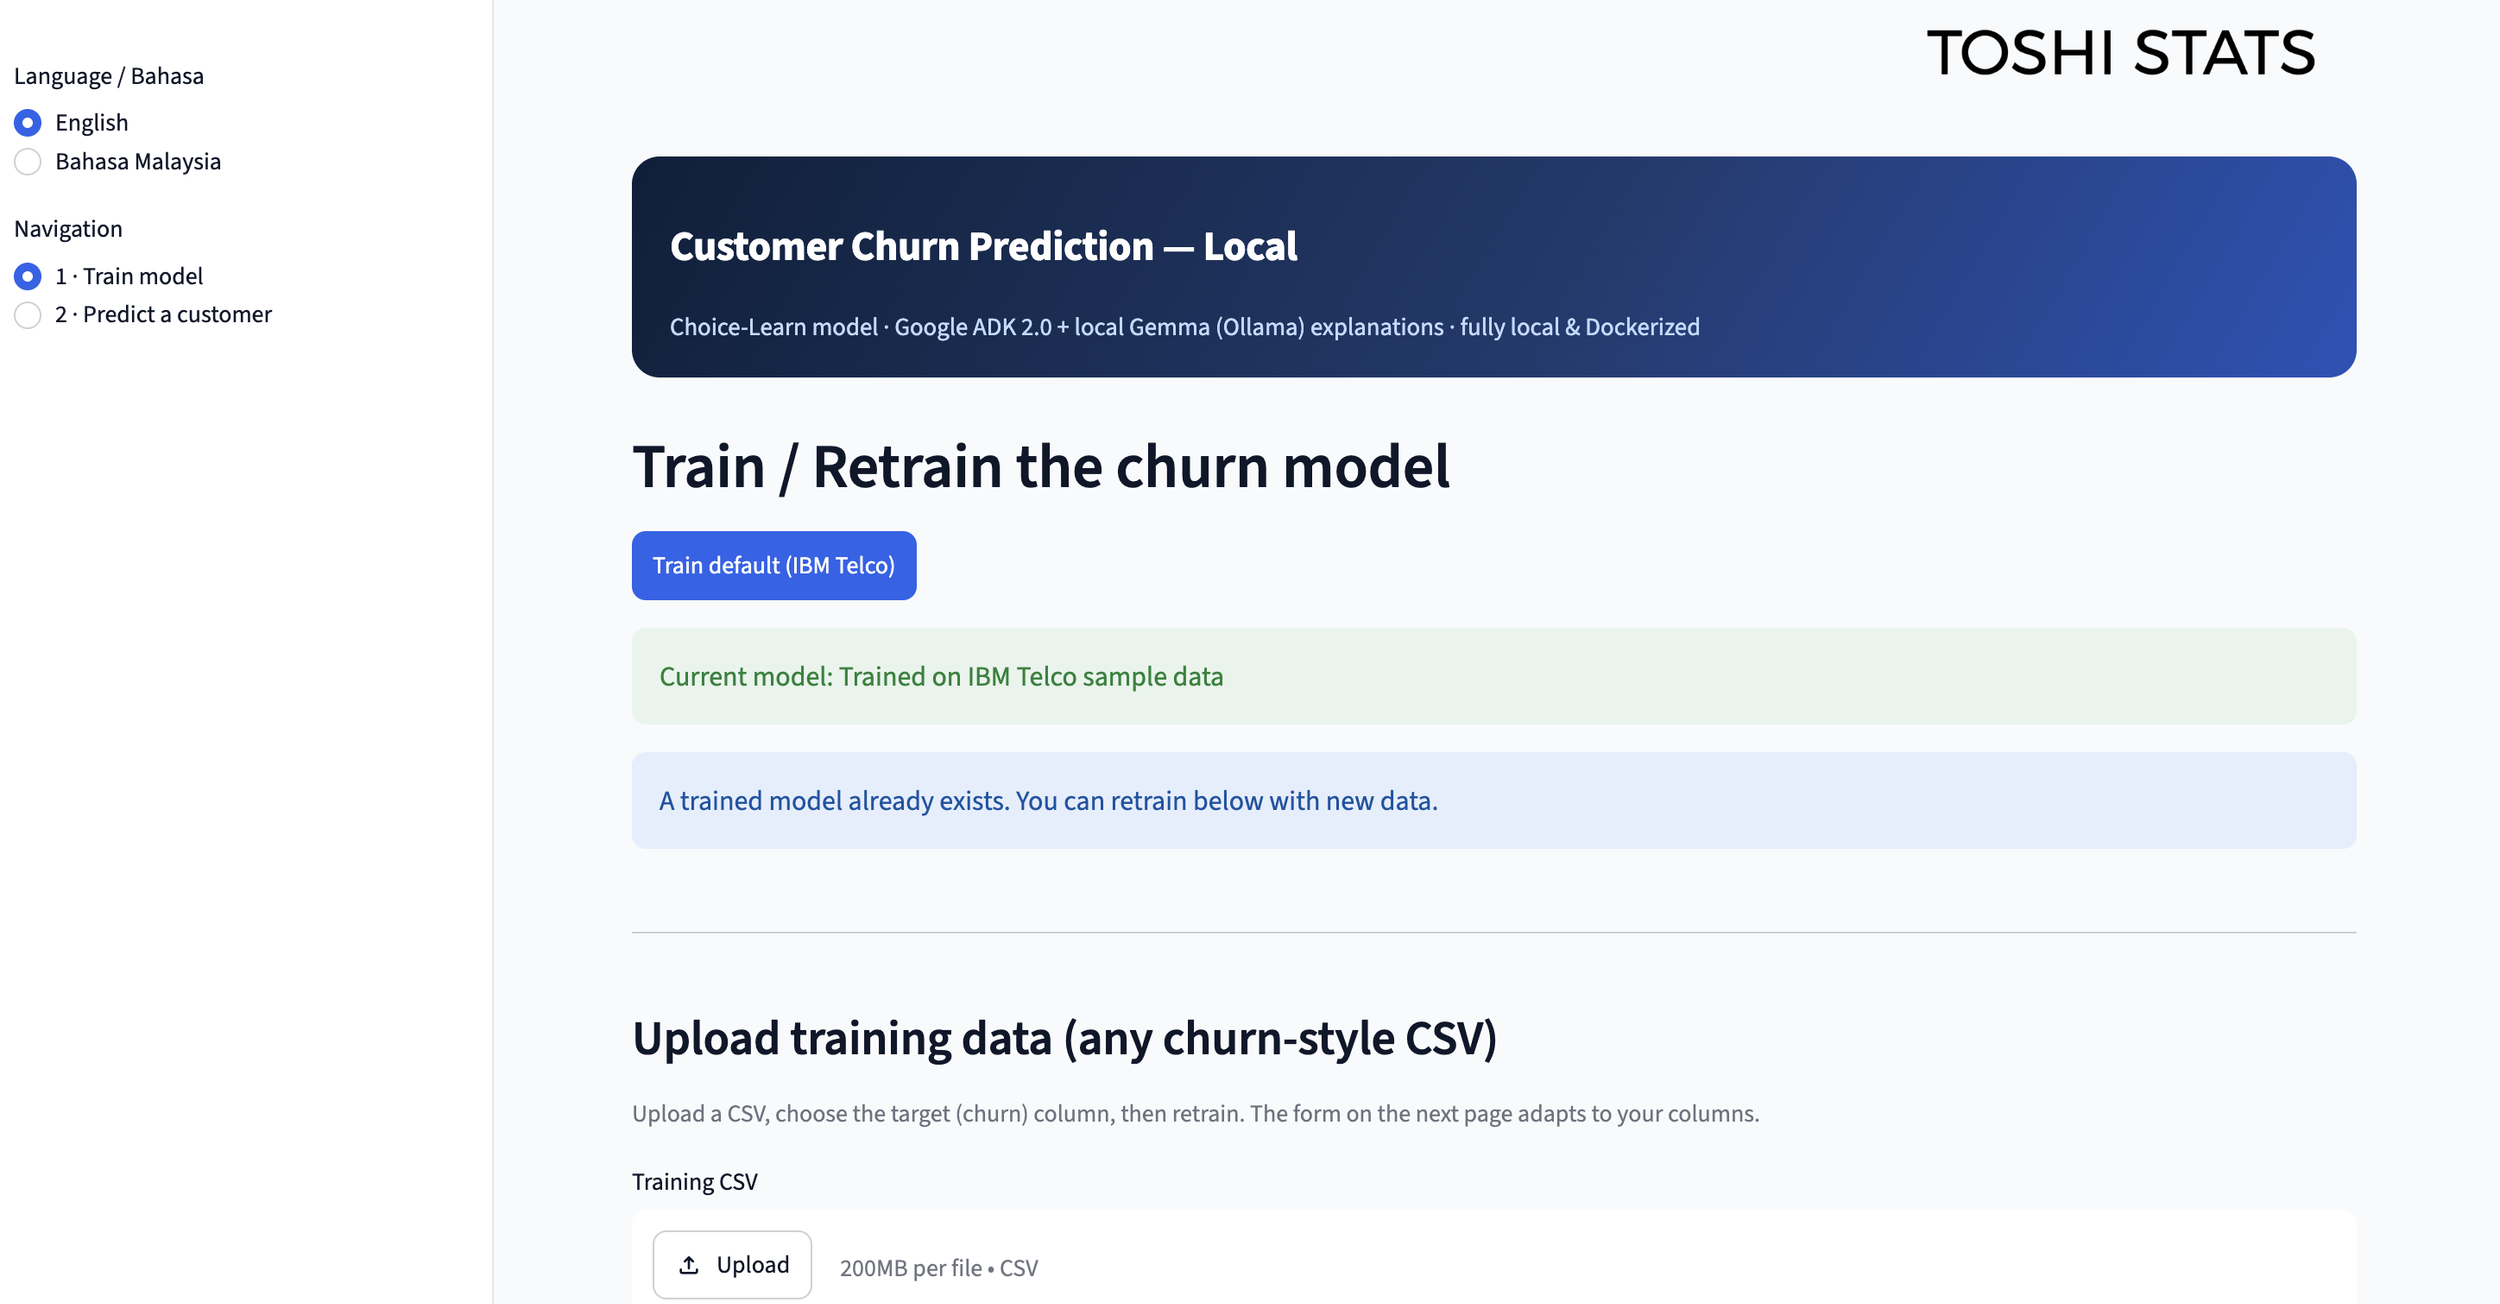
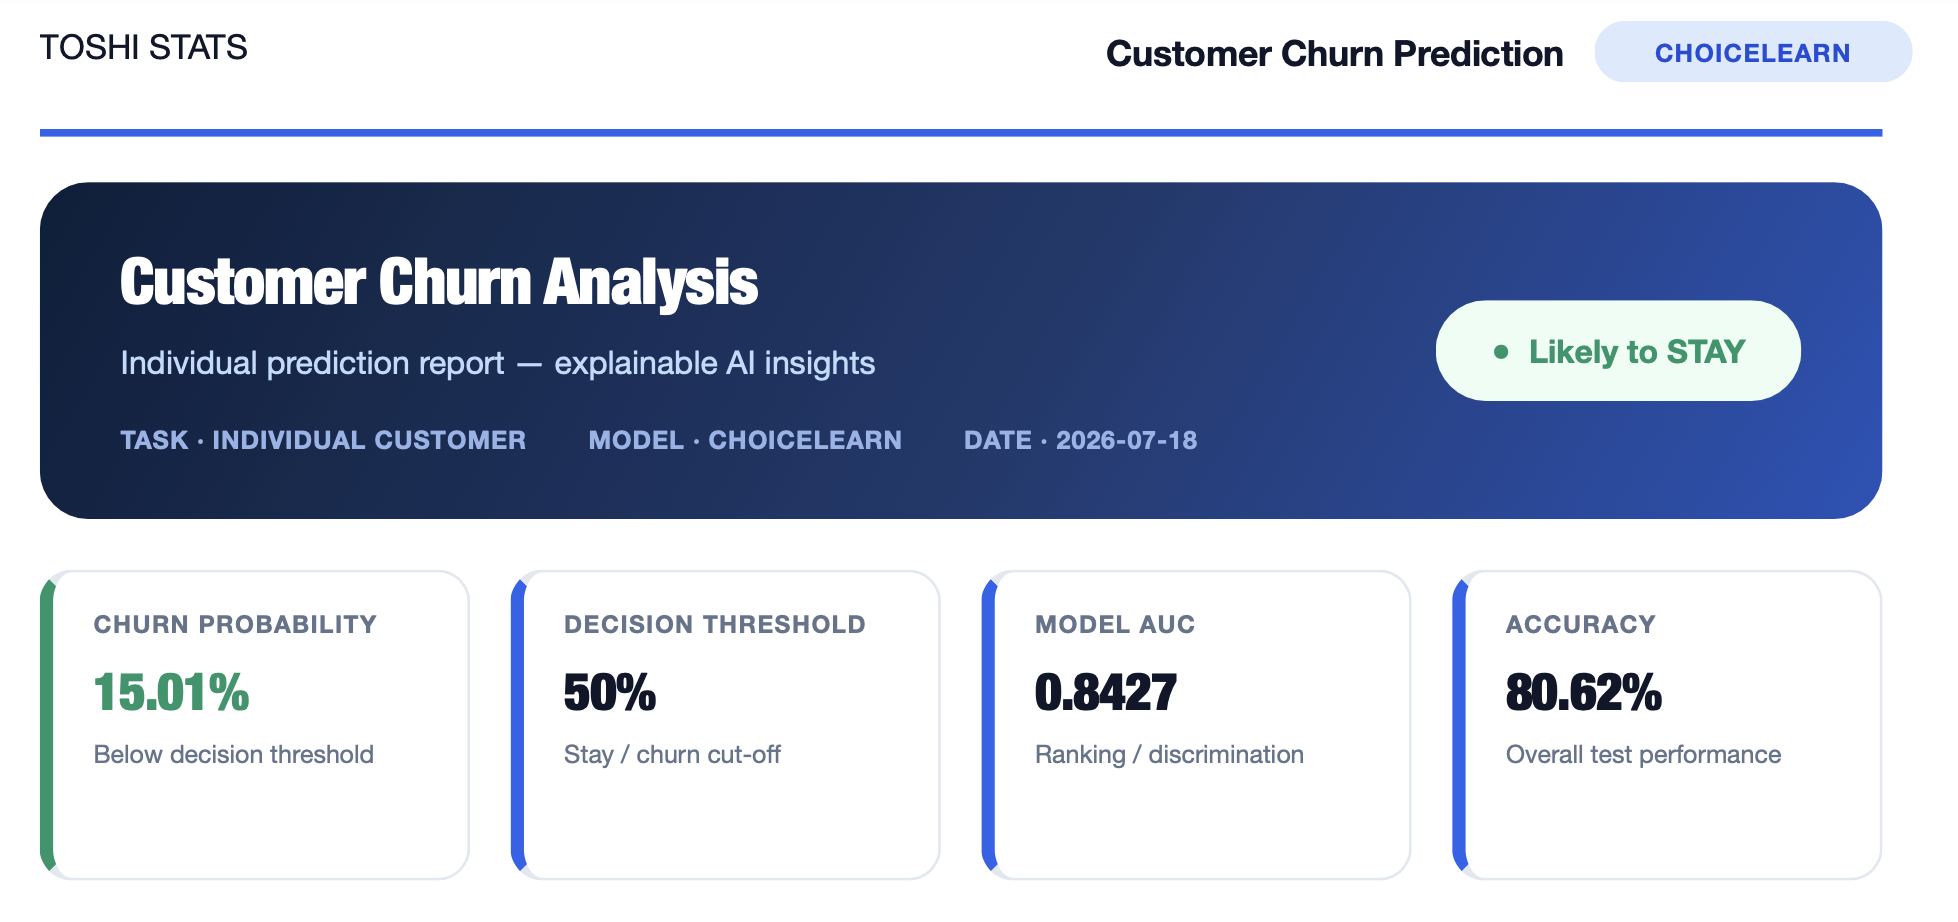
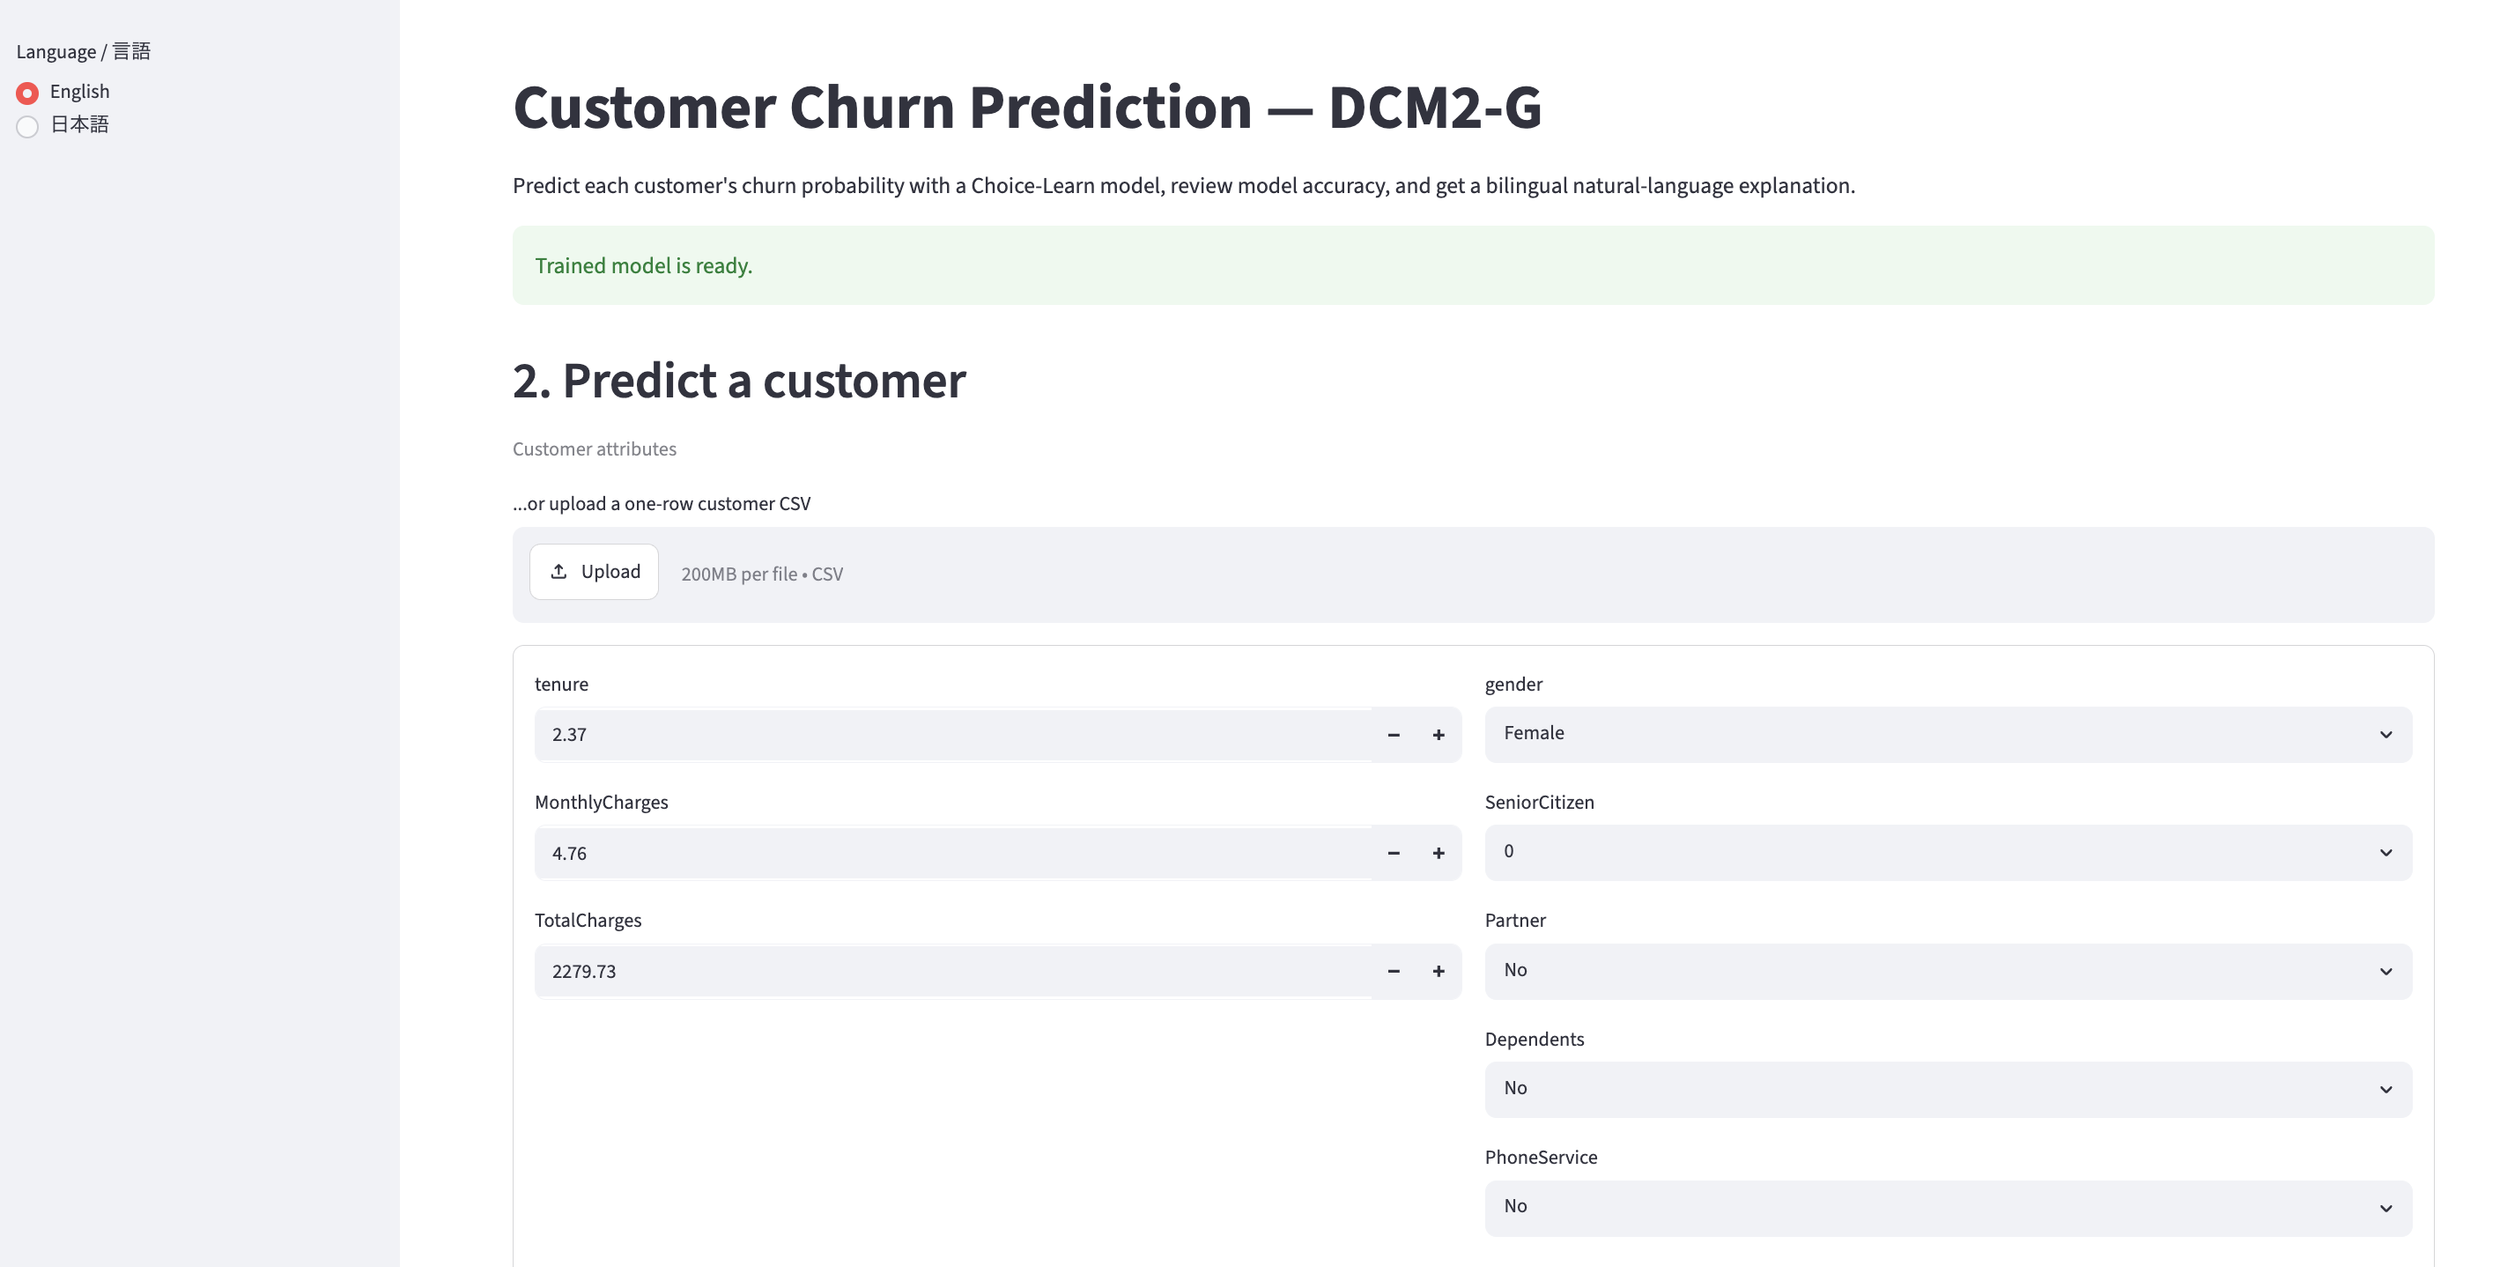
Here is its GUI. For this version, it features bilingual specifications supporting both English and Malay. This is the screen for training the machine learning model.

              Model Training Screen (English)]

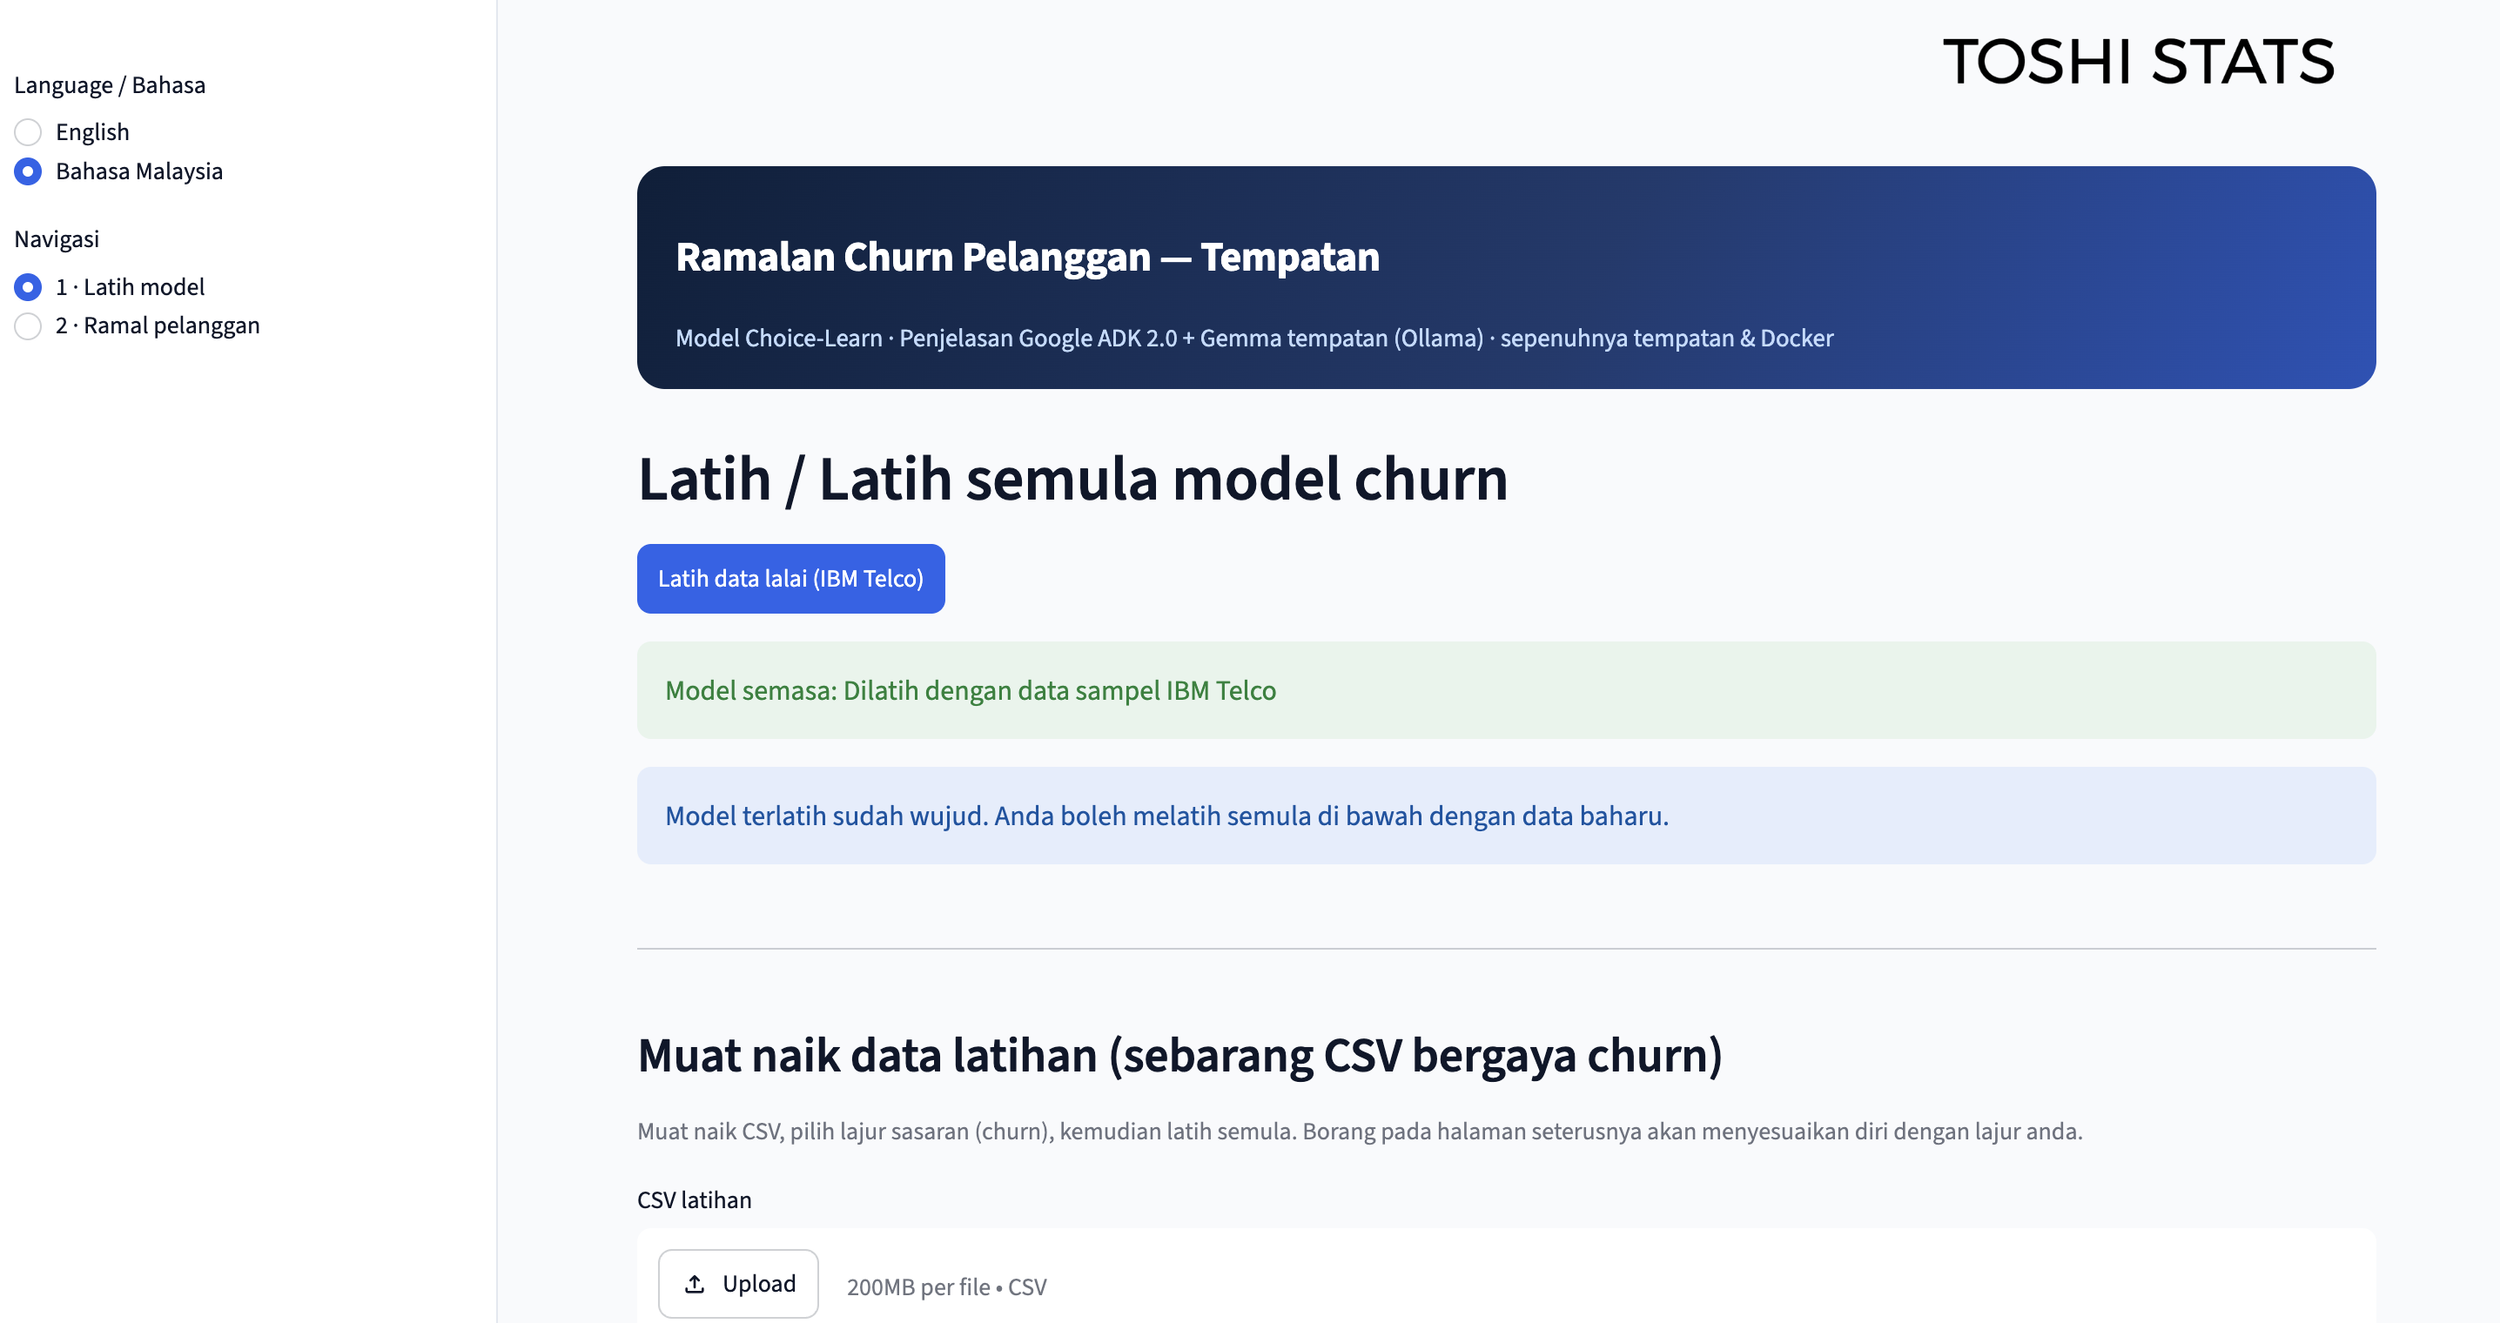
You can switch it to Malay as shown below. It makes it easy to use even in Kuala Lumpur, the capital of Malaysia!

                Model Training Screen (Malay)


2. Exploring the Probability of Individual Customer Churn

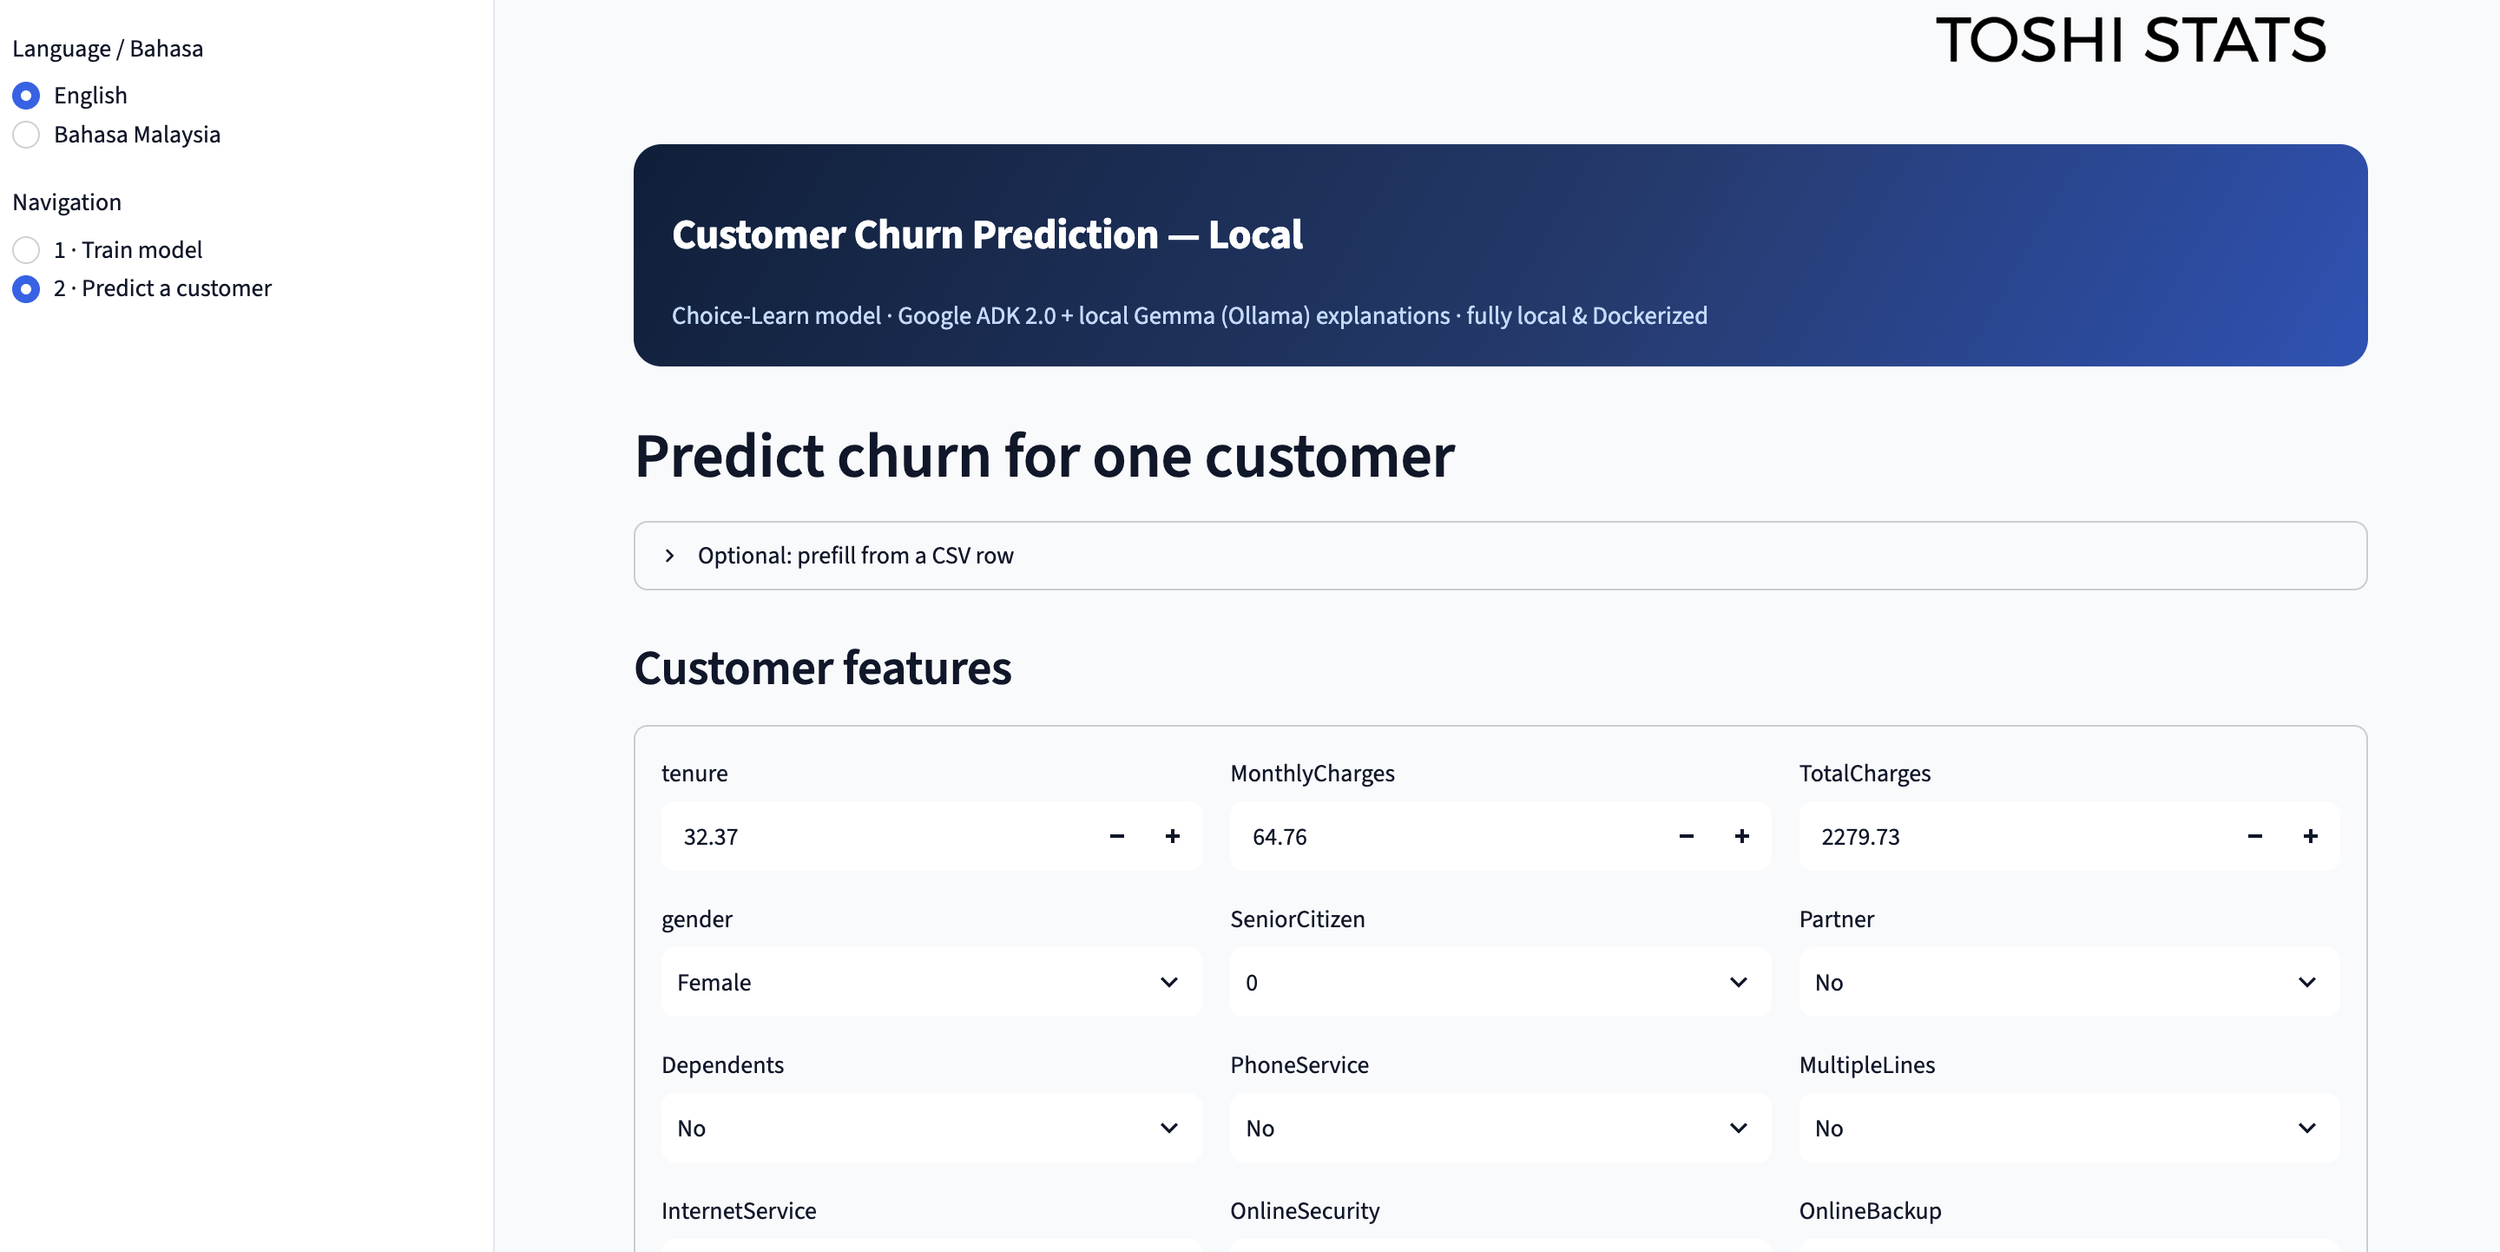
Now, let's get down to business. By inputting individual customer data into the machine learning model, you can calculate the probability of that customer churning. Here, the system is set so that if the probability is 50% or higher, the customer is predicted to churn. The churn probability for the customer shown on this screen is 15.01%, so they were judged as "will not churn."

                   Customer Data

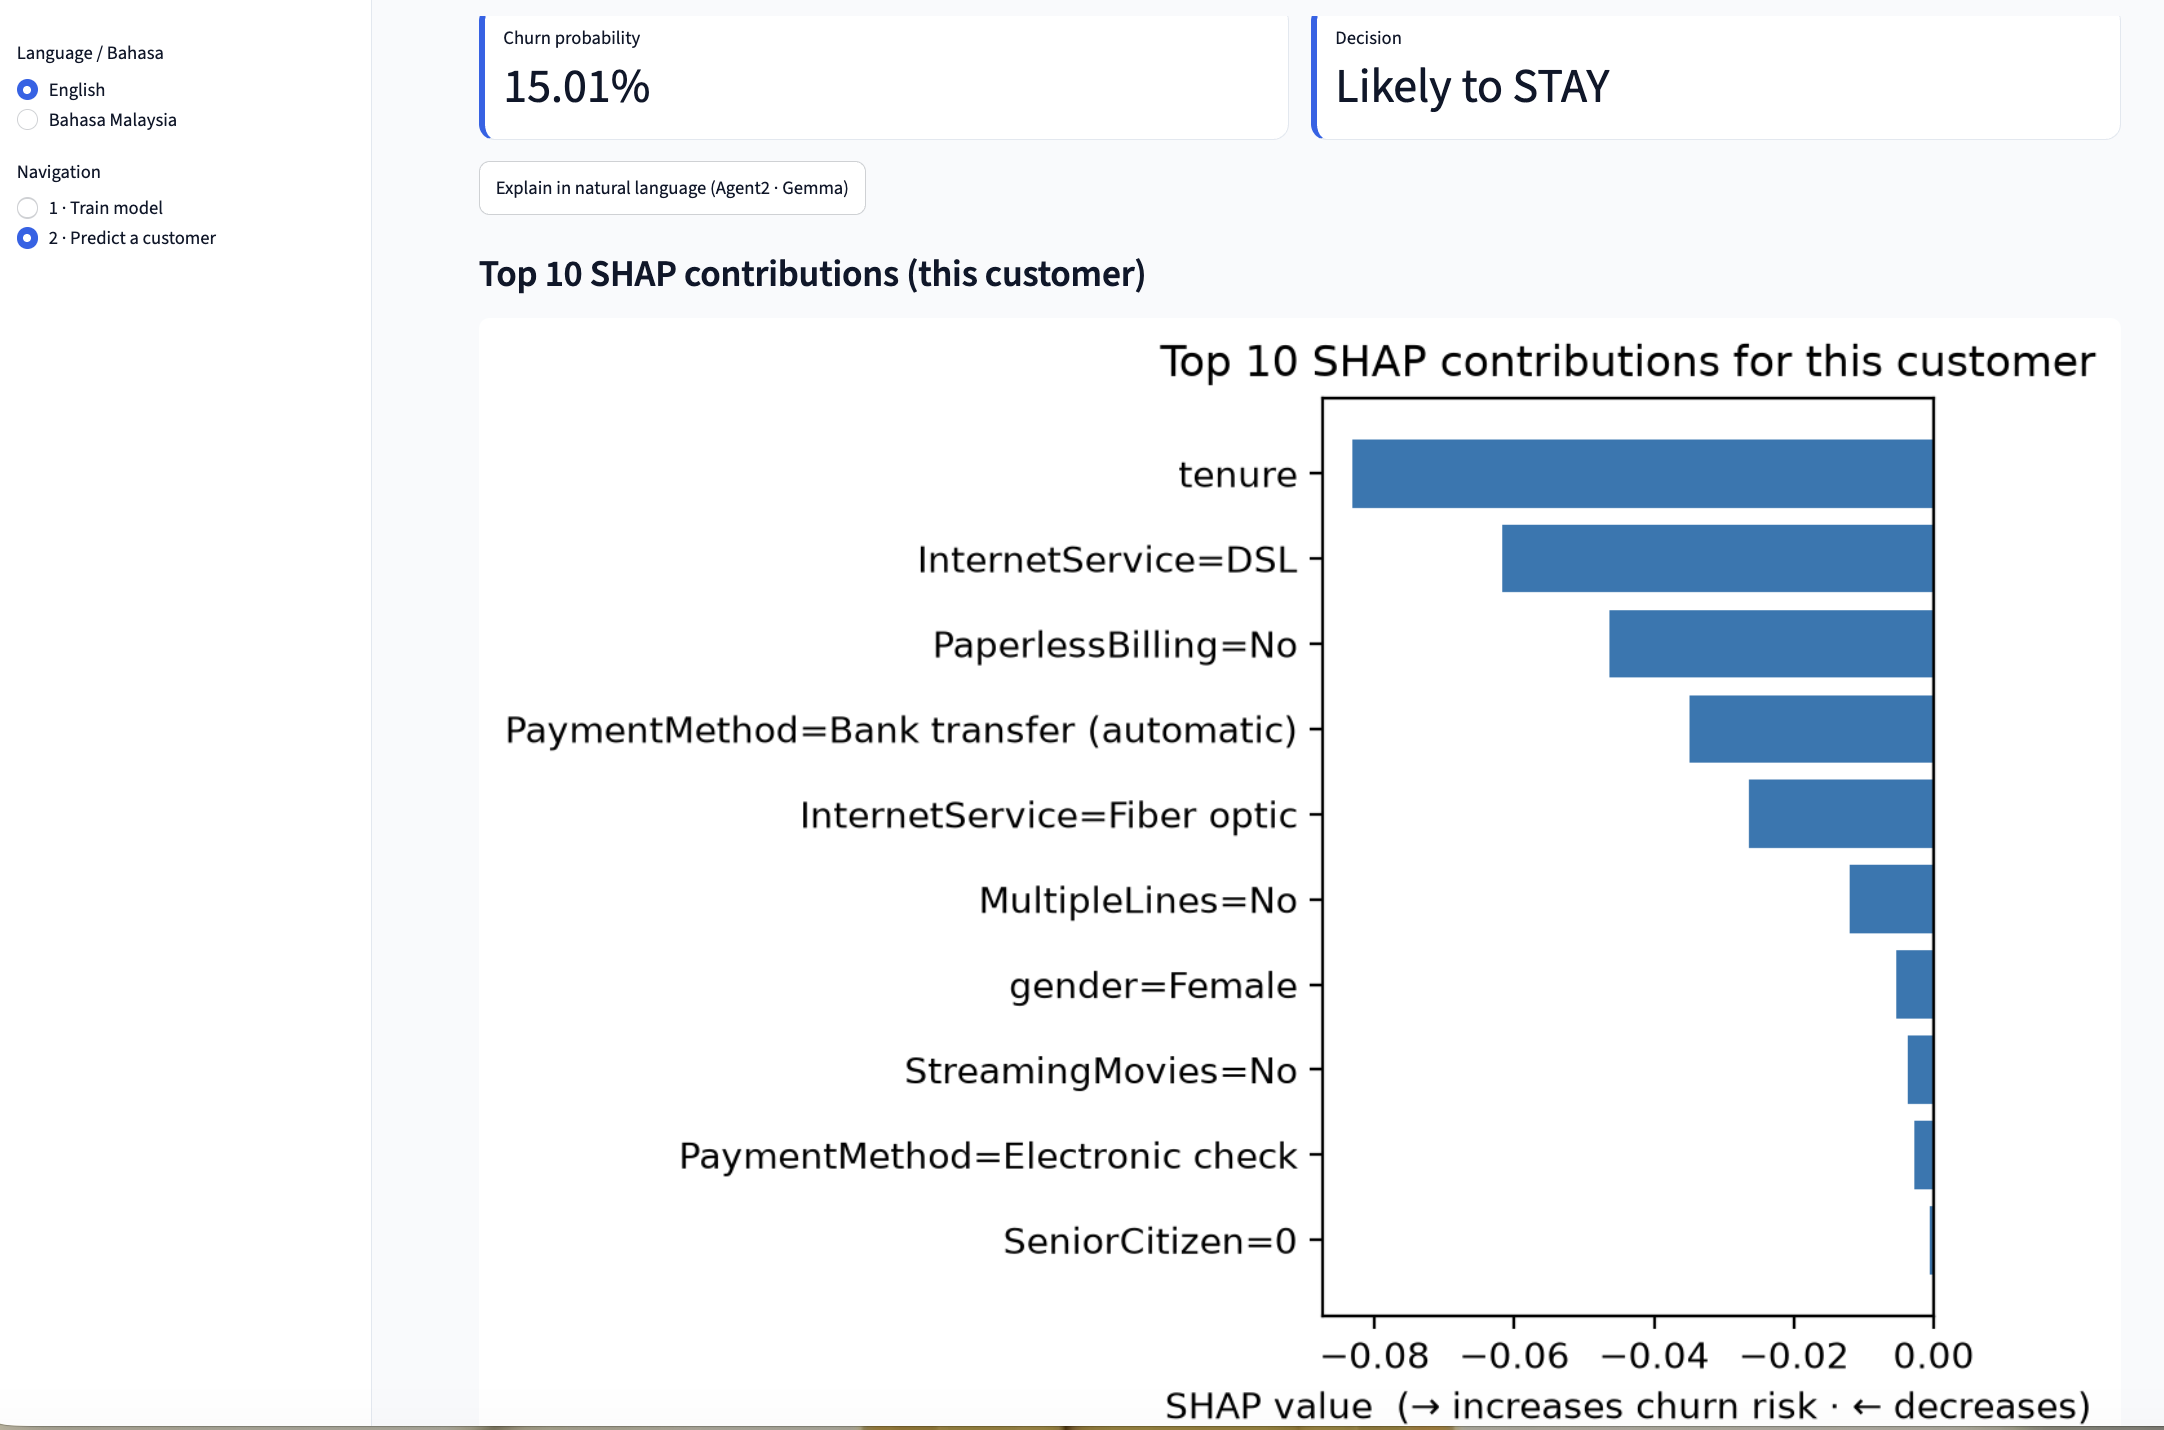
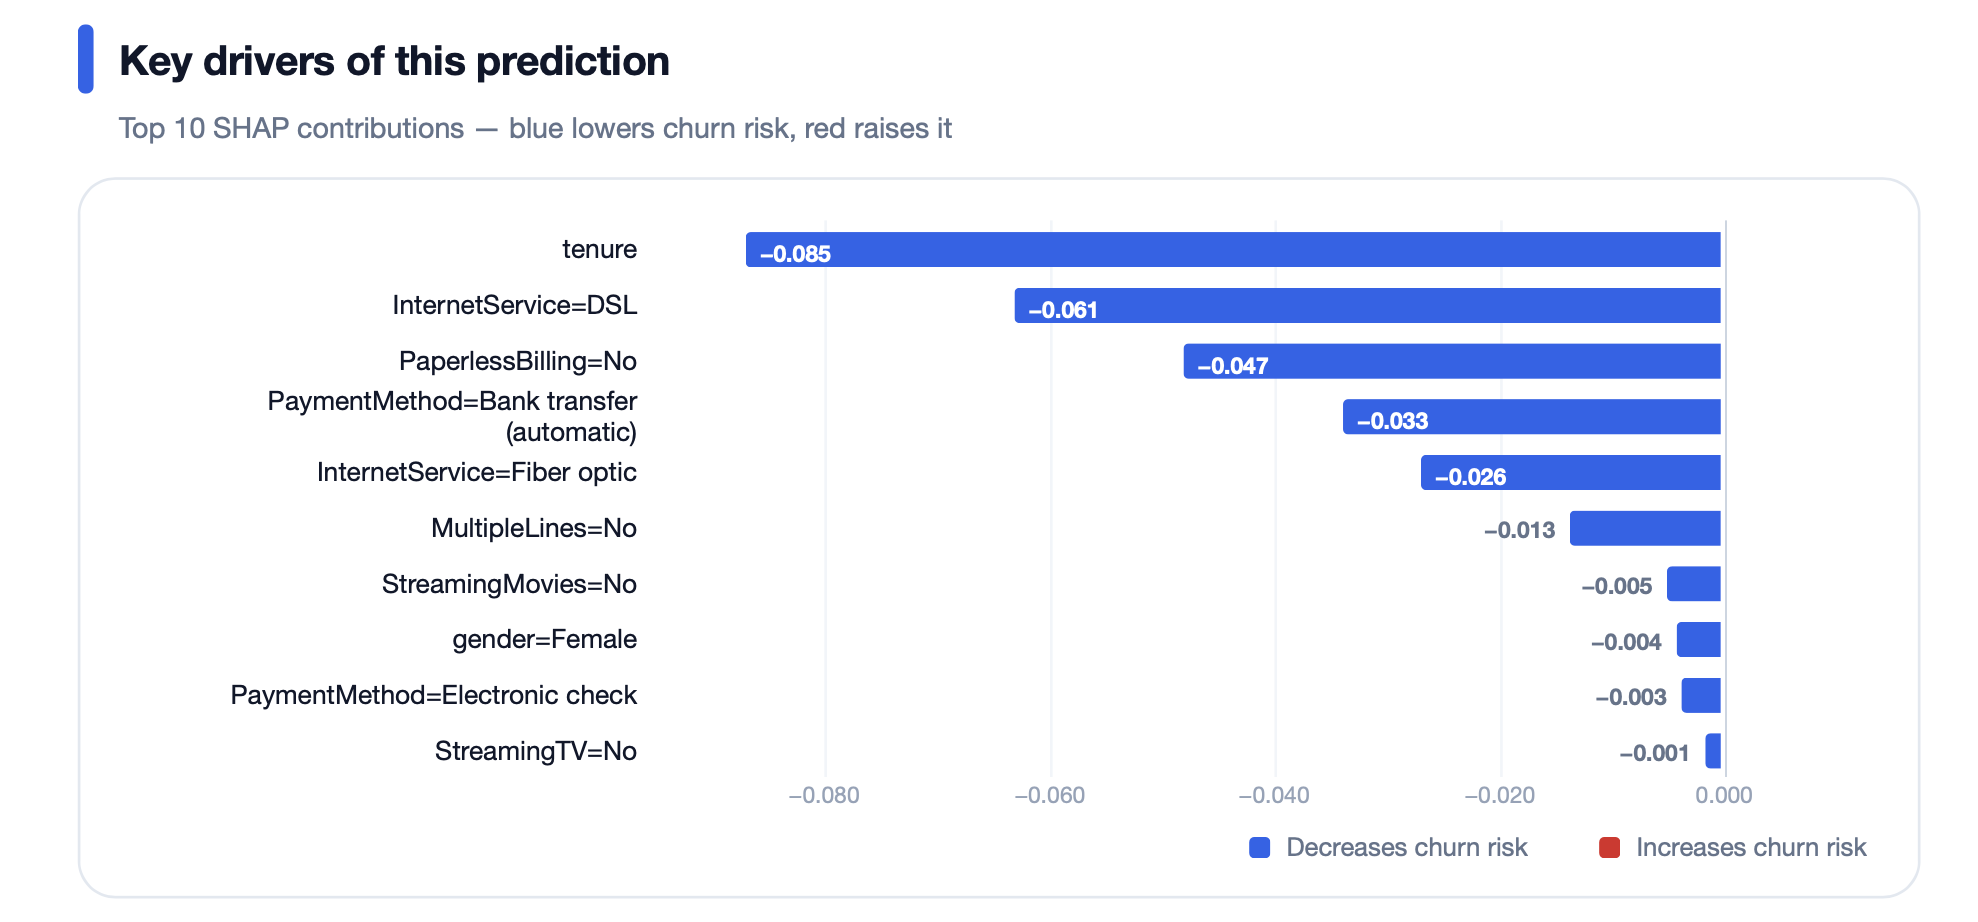
What's really important here is the reasoning behind why it decided they wouldn't churn. For this, a metric called SHAP (2) is employed. The graph below shows numerically and visually how much each feature contributed to the decision.

                Churn Probability and SHAP

However, the problem here is that SHAP is mostly well-known only to data scientists, and there's a high chance that ordinary business professionals aren't familiar with it at all. Therefore, simply saying "Please look at this graph" isn't very user-friendly.

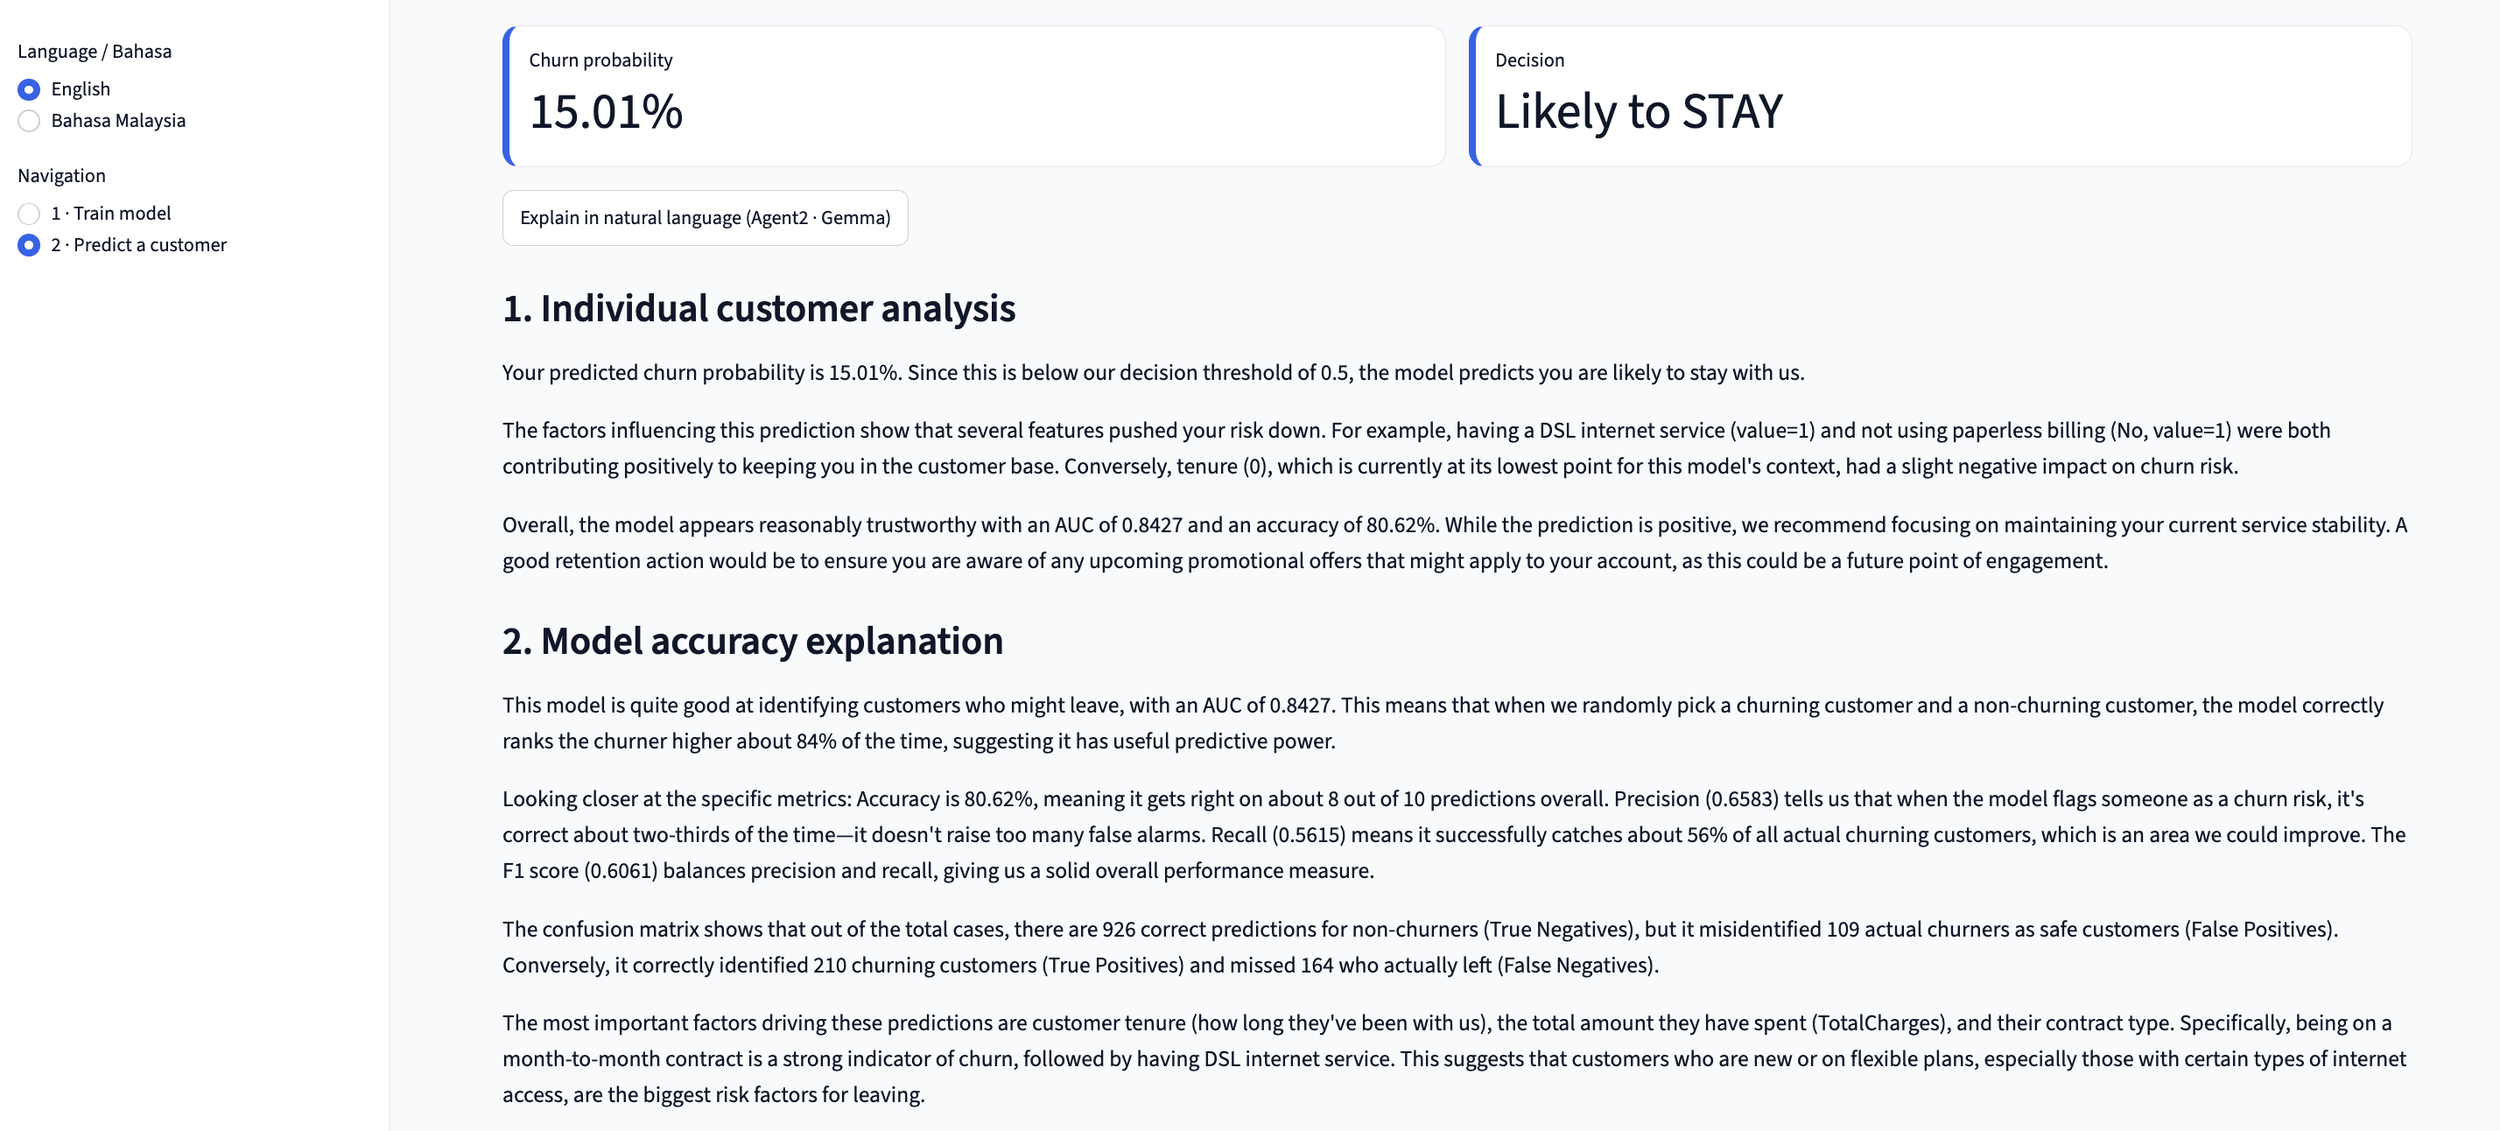
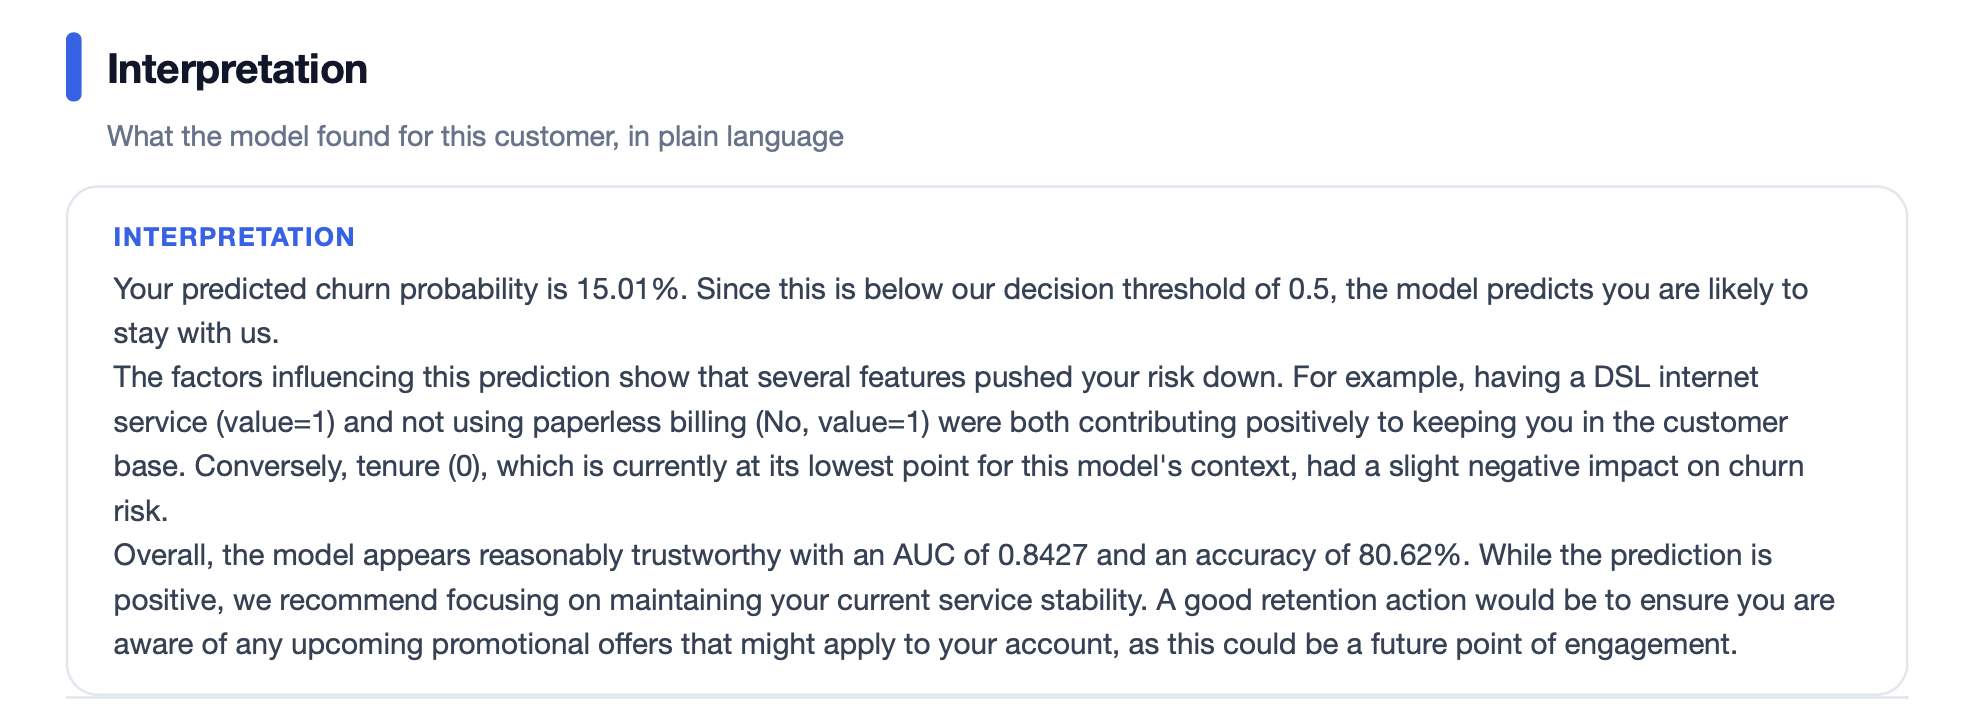
This is where today's star, "Gemma 4 E2B QAT," steps in. As shown below, it explains the "basis for the decision" and the "model's accuracy" in plain, easy-to-understand English. With this, even a SHAP beginner can use it with absolute confidence.

        Explanation of Decision Basis and Model Accuracy (English)

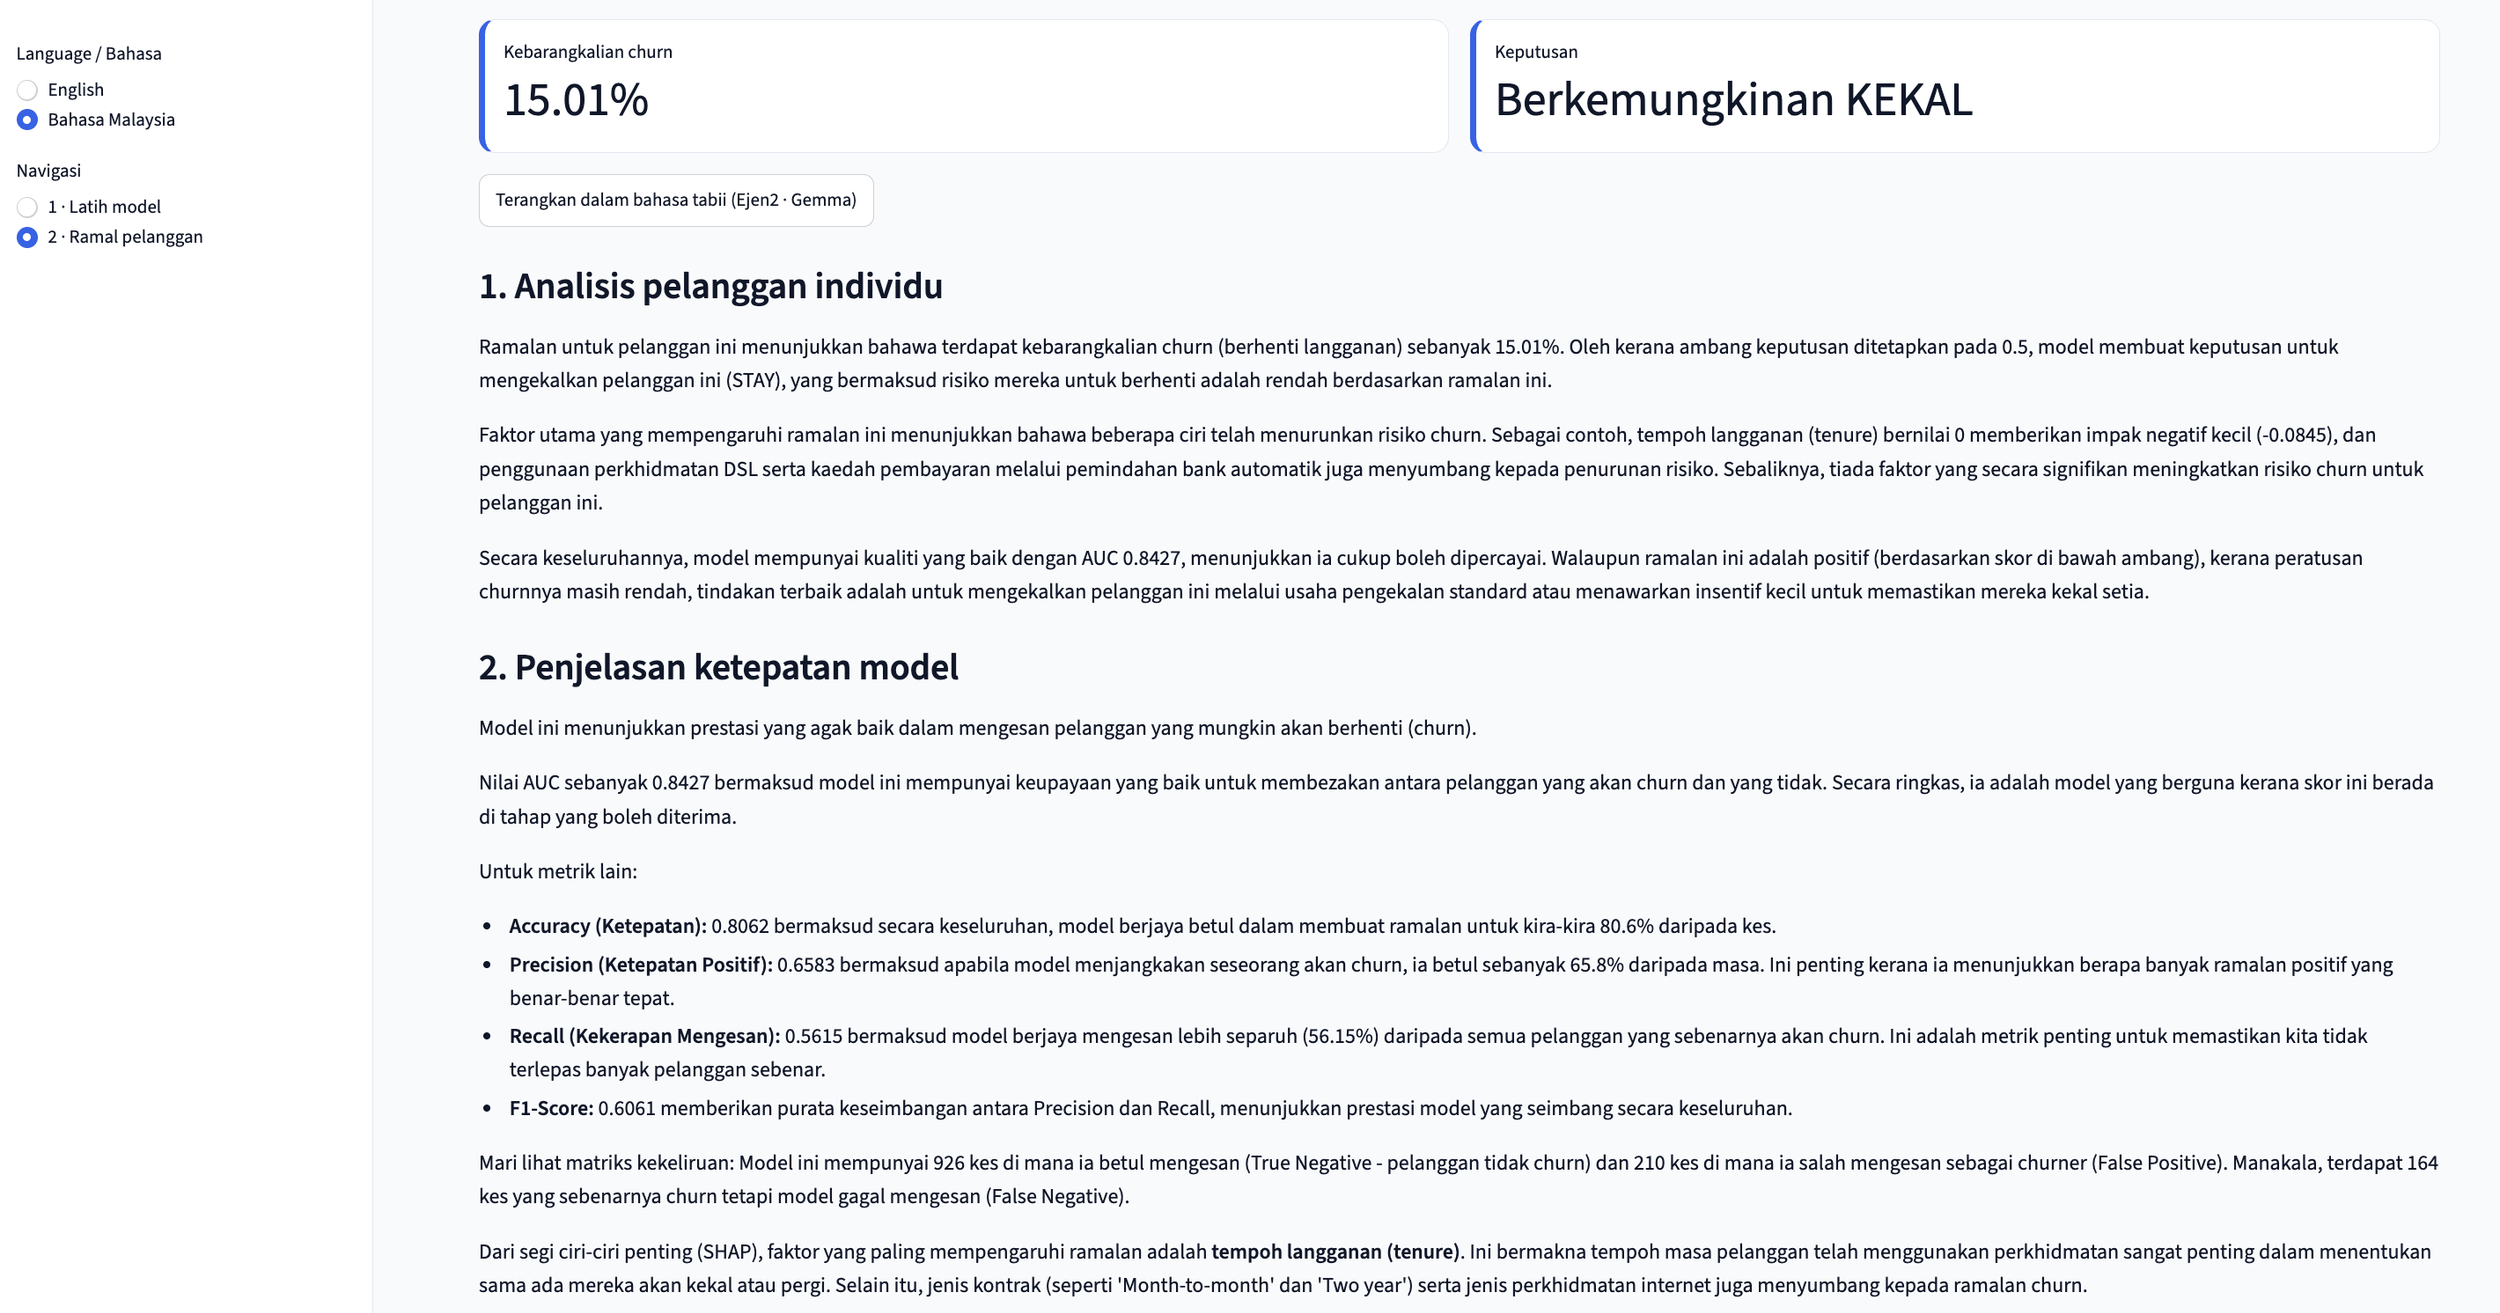
Of course, you can switch this to Malay. Generating this much explanatory text in two languages takes only about 35 seconds on a MacBook Air (M4 24GB). Even on a standard Windows PC, it can often be generated in under 5 minutes. Since "Gemma 4 E2B QAT" is compact, its processing speed is incredibly fast. It is well within practical levels for real-world use.

        Explanation of Decision Basis and Model Accuracy (Malay)


3. The Quality of the Explanatory Text is Also Excellent

The most important point today is: "How accurate is the text generated by Gemma 4 E2B QAT?"

Small-scale generative AIs often lack the accumulated internal information compared to massive frontier models, so in my past experience, I frequently felt they were difficult to use practically in business. However, with "Gemma 4 E2B QAT," such worries were completely unnecessary. This app can output the prediction results as a PDF, so let's use that to take a closer look.

Here is the SHAP graph that served as the basis for the decision. We naturally want to explain this graph in easy-to-understand English, right?

Here is the explanatory text. What do you think? It's written in clear English, with absolutely no grammatical errors or spelling mistakes. I believe it provides a highly logical explanation based on the SHAP data above. When I first read it myself, I was actually a bit moved, thinking, "Can this little generative AI really do this much?"


So, what do you think? There are zero fees for using generative AI in this app. No invoices will be generated. You can use it freely for as many hours as you like. Isn't that fantastic!

Of course, "Gemma 4 E2B QAT" is not omnipotent, so it is necessary to use it strategically in combination with frontier models like Fable5 depending on the situation. However, I am beyond delighted that this ultra-compact generative AI has become a viable option. I feel we should actively use it while fully leveraging its major advantages: being entirely free and allowing highly confidential information to remain securely locked within your PC.

At Toshi Stats, we will continue to tackle tasks in the marketing field using the power of "Machine Learning + Generative AI." Stay tuned!


1)  Gemma 4 QAT models: Optimizing model compression for mobile and laptop efficiency, 5 June 2026, Olivier Lacombe, Omar Sanseviero, Google DeepMind

2) Welcome to the SHAP documentation

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Beyond the Obvious: Unleashing the Fable5 AI's Blind Spot Pass as a Strategic Secret Weapon!

Anthropic’s new generative AI, Fable5, is available again and is currently being trialed worldwide. I have been taking on new challenges myself, but I often feel that even with ultra-high-performance generative AI, things don't go well if the user's prompts are vague. Rework occurs every single time, and I've constantly wondered, "Isn't there a better way to do this?" Recently, Anthropic engineer Thariq Shihipar shared a brilliant idea (1). This time, I would like to introduce the "Blind Spot Pass"—a method that helps us identify our blind spots in advance—and actually try using it.


1. Reduce the Unknowns

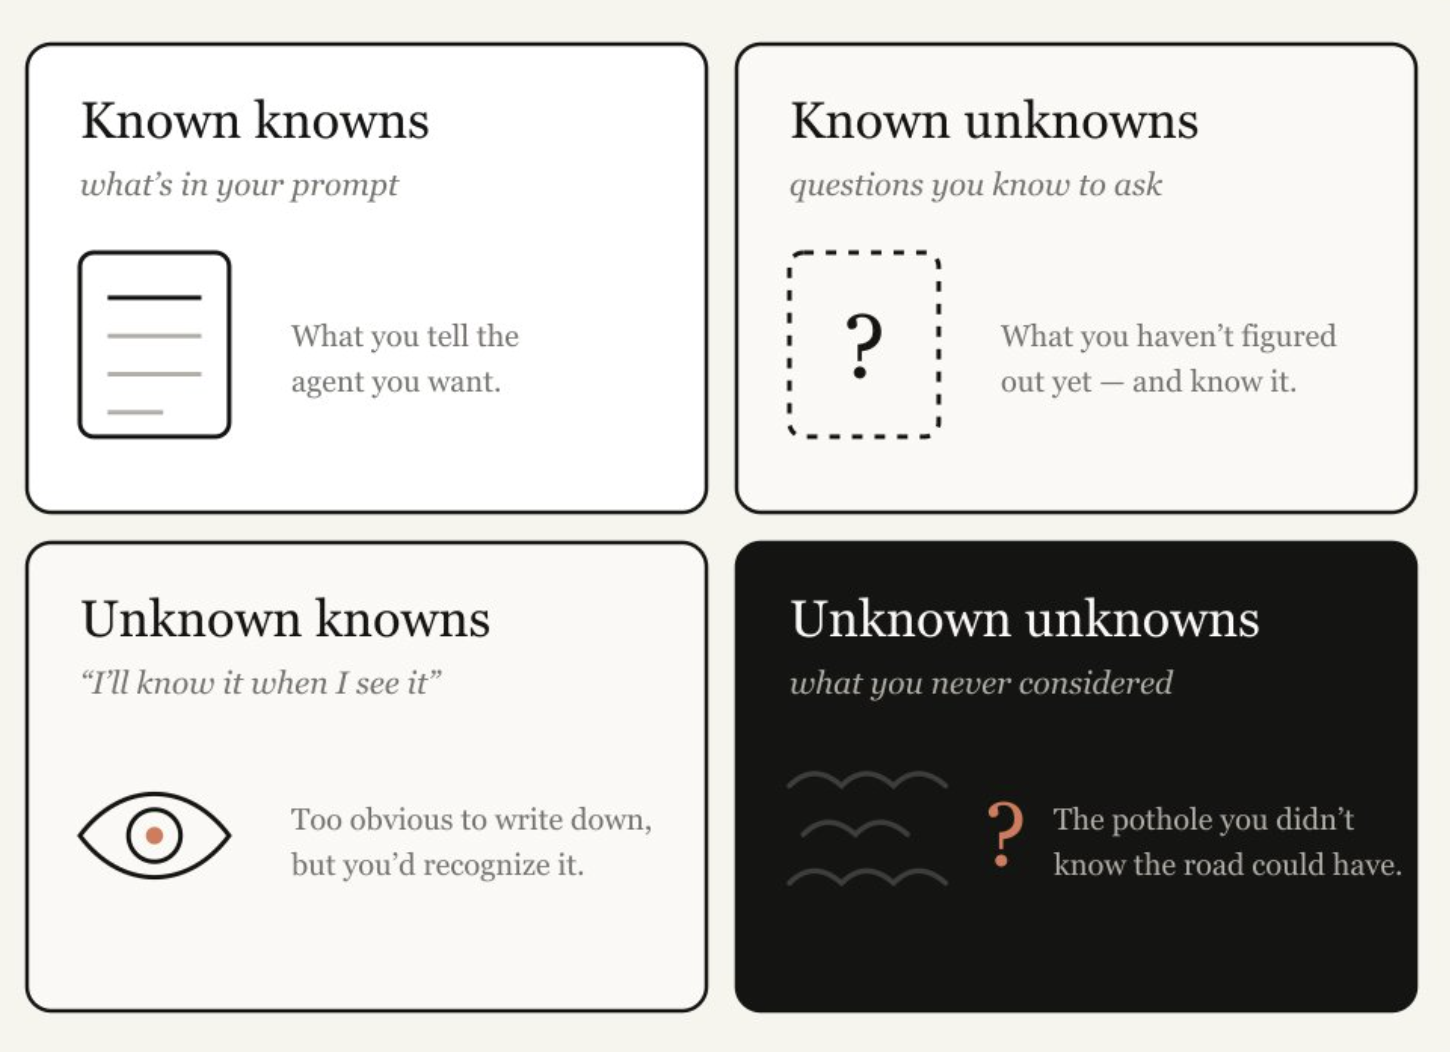
I believe the core of Thariq Shihipar's argument is the "unknown." When starting a project, we don't understand everything from the outset, and there are many unknowns. He categorizes our knowledge as follows:

  • Known Knowns: This is essentially what is in my prompt. What do I tell the agent that I want?

  • Known Unknowns: What haven't I figured out yet, but I’m aware that I haven’t?

  • Unknown Knowns: What's so obvious I’d never write it down, but would recognize it if I saw it?

  • Unknown Unknowns: What haven't I considered at all? What knowledge am I not aware of? Do I know how good something can be?

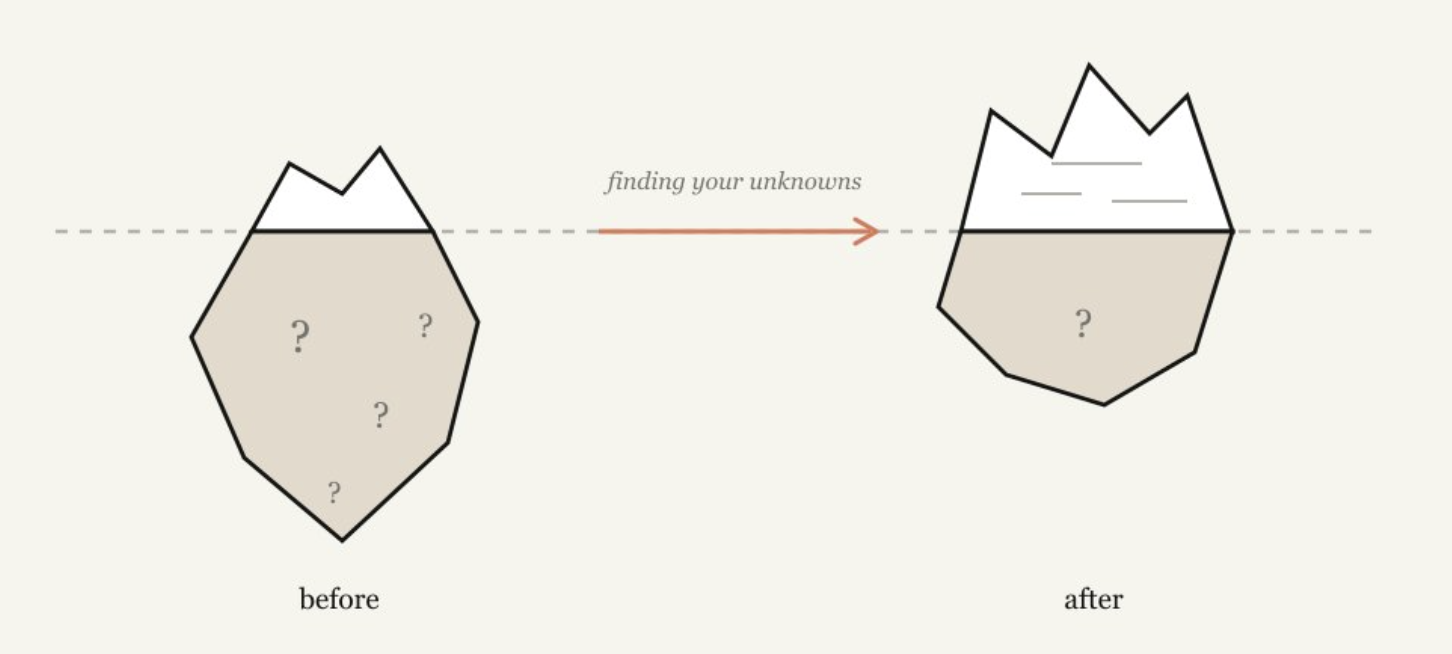
No matter how high-performing Fable5 is, if we—the ones giving the instructions—don't clearly understand what we want to do, we won't be able to push its capabilities to the limit. Therefore, before starting a project, we need to transition from a state of "many unknowns" on the left to a state of "few unknowns" on the right. He outlines a detailed process for this, but I would like to focus specifically on the "Blind Spot Pass," which reduces the "Unknown Unknowns."


2. How to Strategically Use a Customer Churn Prediction Model

Currently, I am developing a "customer churn prediction model" combining machine learning and generative AI, but I am pondering how best to apply it to actual business scenarios. I have thought about various approaches, but that doesn't mean there are no blind spots. So, I would like to immediately apply the "Blind Spot Pass" to Fable5 and uncover these blind spots. The actual method just requires using the following prompt. It's very simple!

“I am looking to develop a new customer churn prediction model to improve my business, but I have no prior knowledge of customer churn prediction or how to practically apply it in a business setting. Please conduct a 'Blind Spot Pass' to identify the relevant 'unknown unknowns' and help me write a better prompt.”

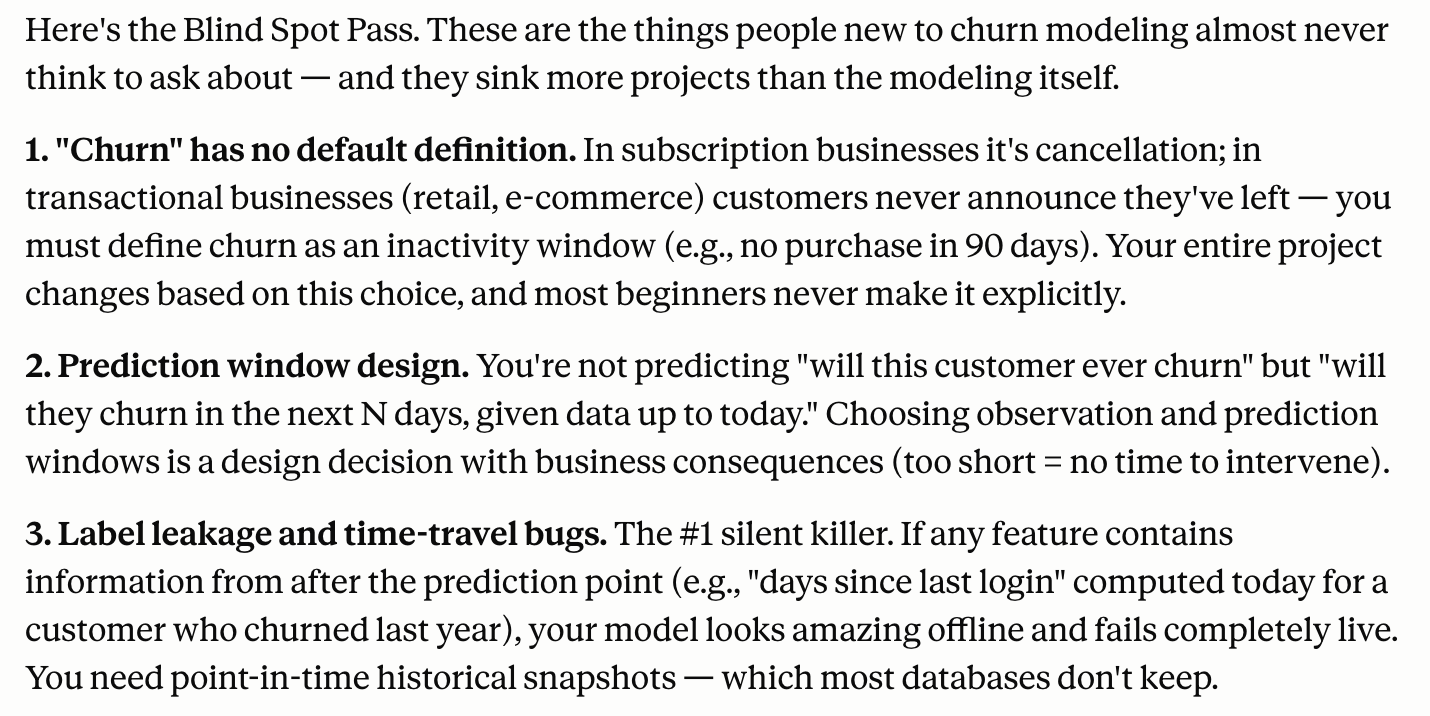
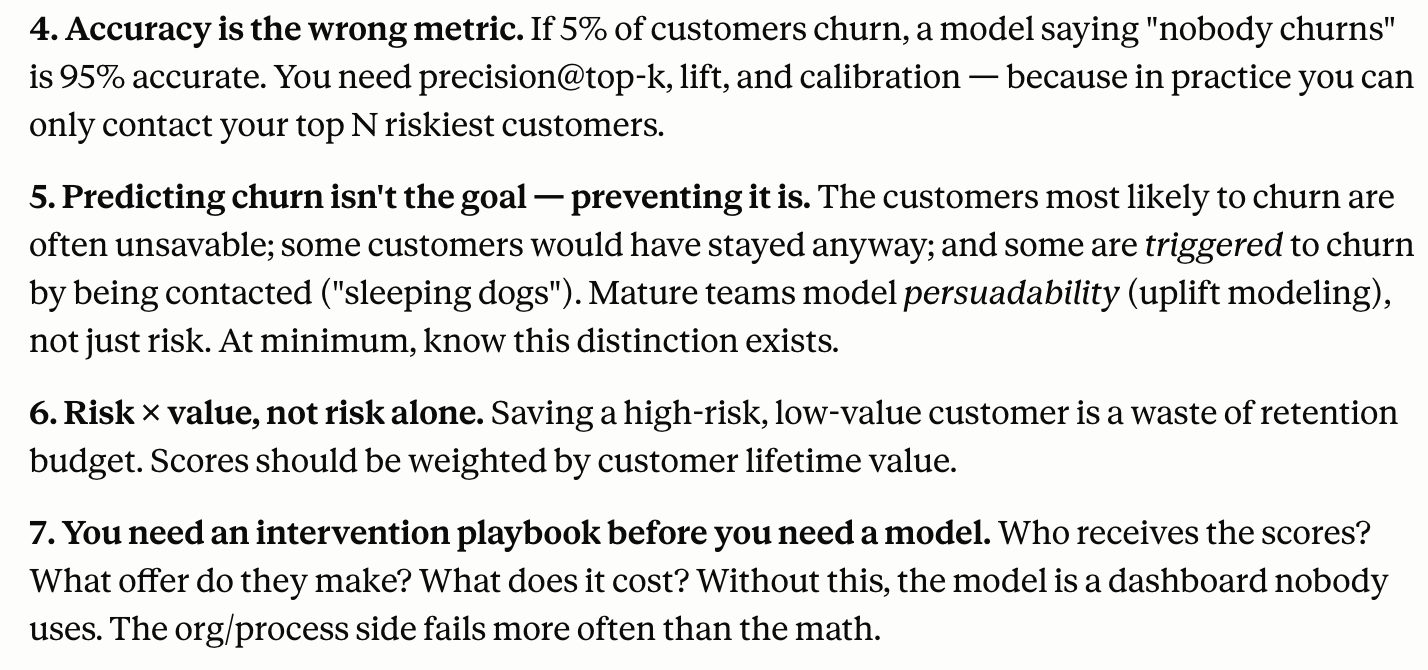
Within minutes, I received the following response. It's amazing!

With blind spots identified in such detail, I can proactively grasp potential stumbling blocks before actually writing the prompts, allowing me to write them much more clearly and effectively. Furthermore, when feedback comes from Fable5, I will be able to respond more accurately. Because the unknowns have been reduced, I can move forward with the project with confidence.


3. The "Blind Spot Pass" is Also Effective for Formulating Management Strategies

Because Thariq Shihipar is an engineer, his discussion centered around coding, but reducing unknowns is crucial in a variety of fields. Especially in management strategy formulation, where uncertainty is high, eliminating blind spots as early as possible is extremely important to prevent failures caused by "unforeseen circumstances." The development of the customer churn prediction model mentioned above shouldn't be viewed merely as a coding task, but rather as an action responding to the major management challenge of "increasing customer retention," making it a significant pillar of management strategy. If we consider management strategy after grasping the 11 points raised earlier, we will undoubtedly be able to build a more effective and refined strategy. I want to actively keep using this. The "Blind Spot Pass" serves as an incredibly reassuring partner, especially when taking on new challenges in uncharted territories.


What do you think? Just by tweaking your prompts slightly, the "Blind Spot Pass" seems poised to deliver tremendous results. Let me conclude with a quote from Thariq Shihipar:

"Fable is the first model where I find the quality of the work is bottlenecked by my ability to clarify its unknowns."

Here at Toshi Stats, we plan to take on various tasks using Fable5. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1)  A Field Guide to Fable: Finding Your Unknowns, 4,July 2026, Thariq Shihipar, Anthropic PBC

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

The Path to AGI : From Loops to Recursive Self-Improvement

Recently, "loops" seem to be coming up a lot in the agentic coding community. In programming, a loop typically means repeating the same process over and over using a for statement, but here it refers to AI agents repeatedly cycling through the same process. Because this is a highly important foundational technology for predicting the future development of AI, I'd like to dive right in and explore it.


1. Loops Are Becoming a Hot Topic

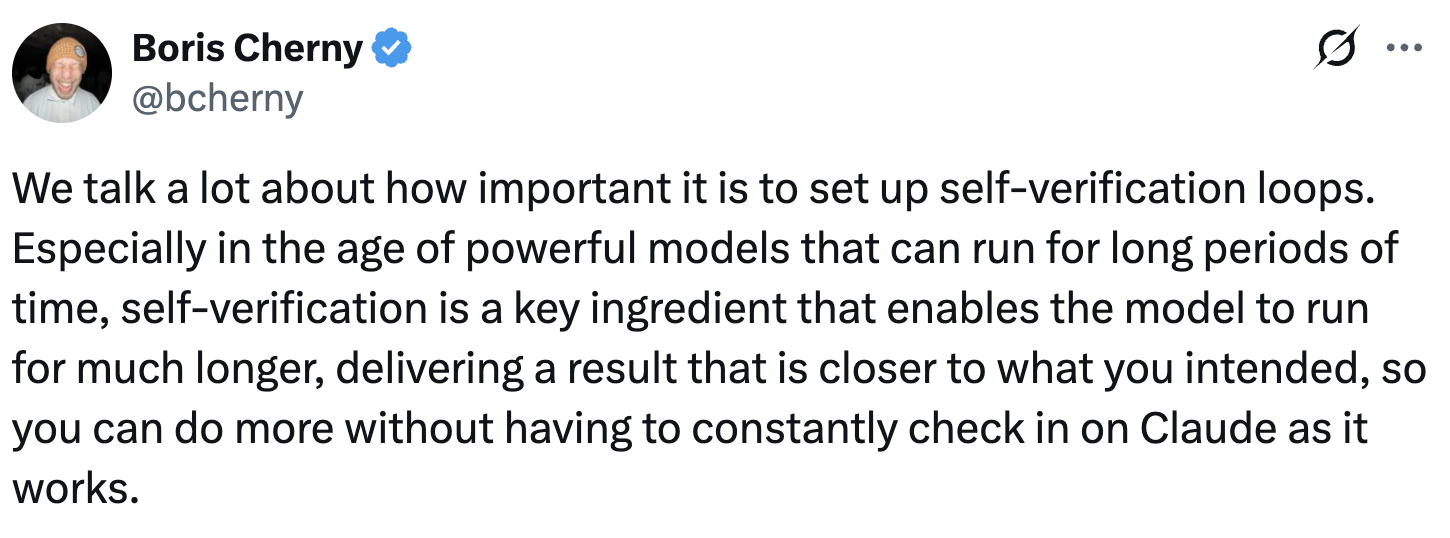
Boris Cherny, the creator of ClaudeCode, has recently been talking about the importance of "loops" in interviews and on X (1). It seems he himself has been getting most of his work done using loops lately. Given that the new generation of generative AI models can operate continuously for hours, it makes sense that they can churn through tasks using loops.


2. Feedback Descent

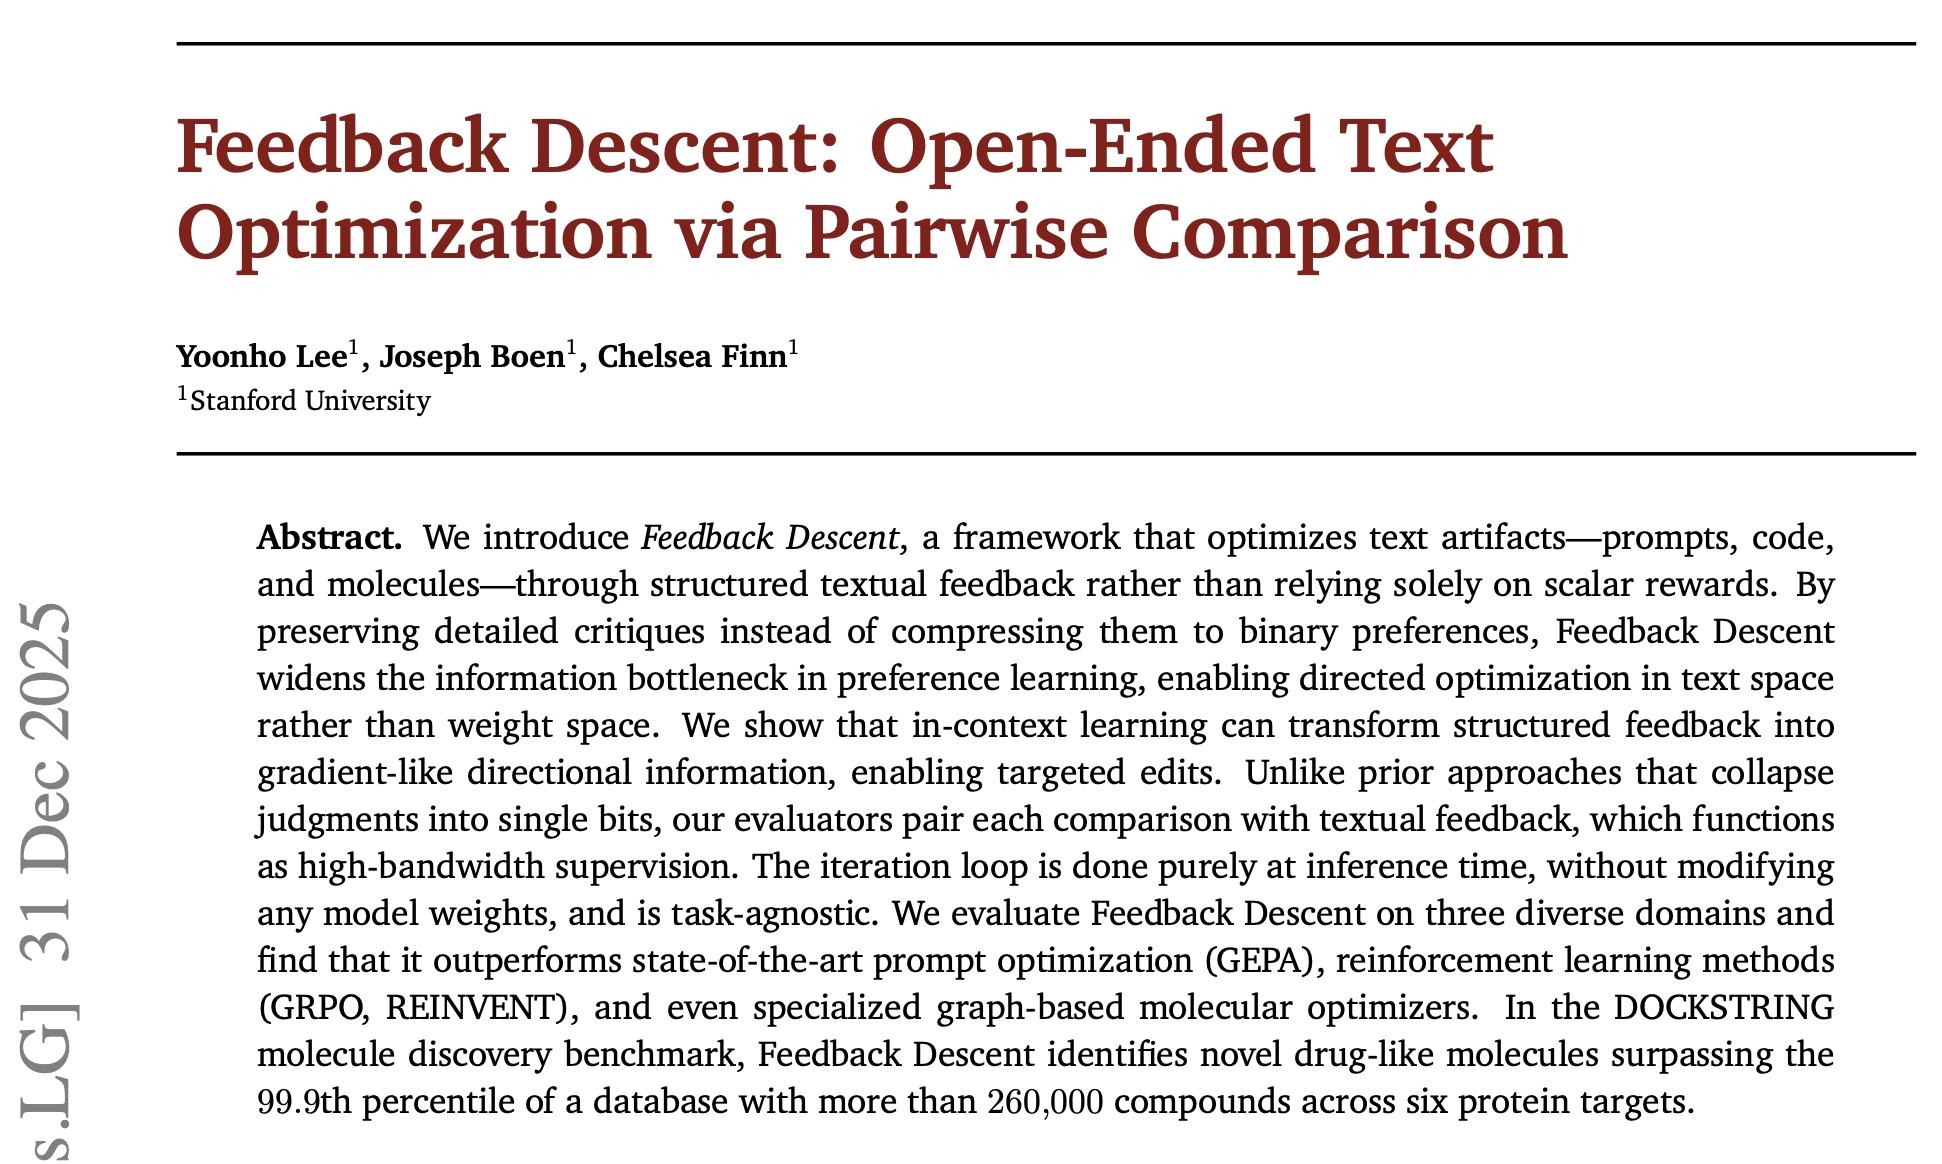
To dive deeper into loops theoretically, I would like to introduce a research paper. It outlines a method called Feedback Descent (2), which aims to optimize text generations using words in a semantic space.

                 Feedback Descent

In the world of machine learning, optimization is often done using "gradient descent," which utilizes the gradient of a loss function. In this method, however, feedback is received in text form and used as a hint to devise improvement strategies for the next loop. Therefore, I believe they borrowed the naming convention from the machine learning world to call it Feedback Descent.

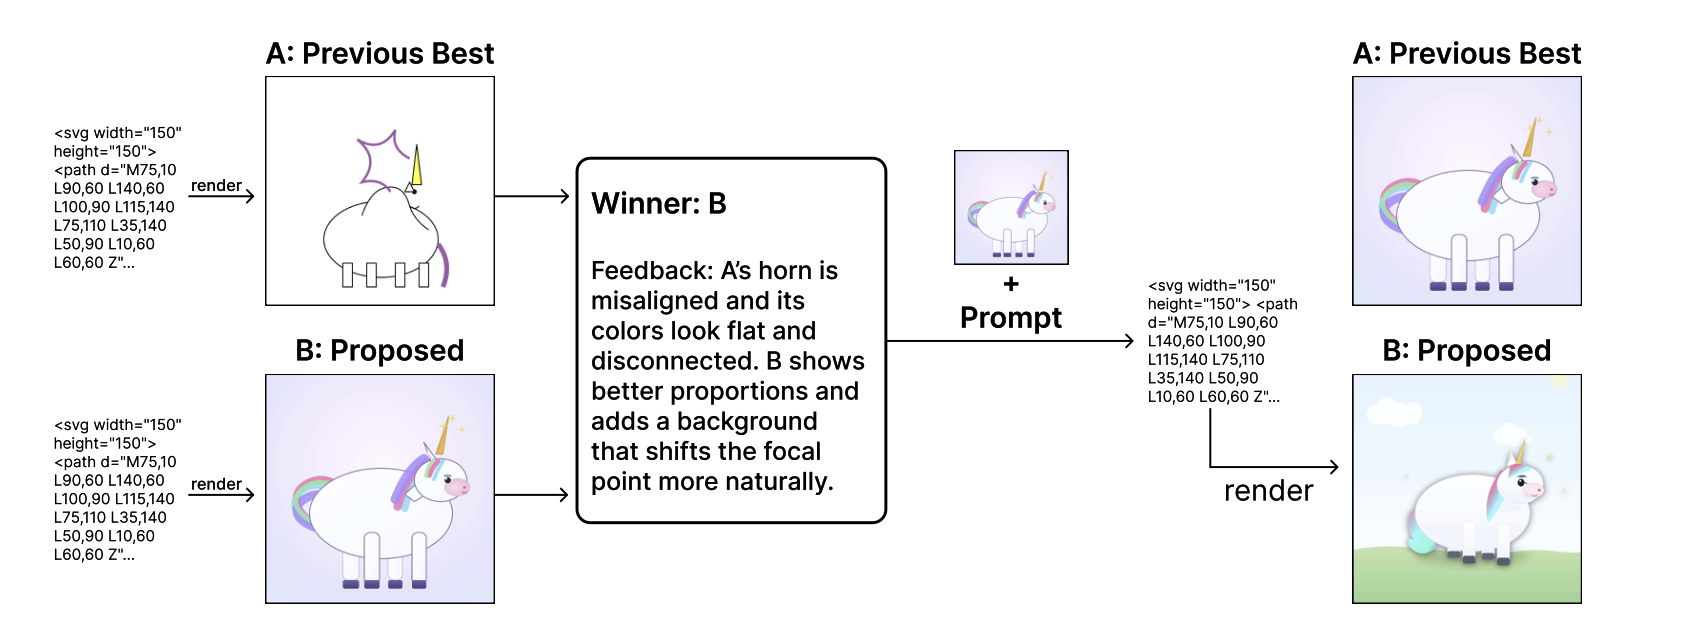
In the explanatory diagram below, Illustration A and Illustration B are compared as a pair, and the chosen one—along with the reason for its selection—is returned as text feedback. In the next loop, the prompt is devised based on that feedback, allowing for the creation of more accurate and effective prompts. This clearly defines the direction of prompt generation conducted in a loop. Brilliant!

           Text Optimization via Pairwise Comparison

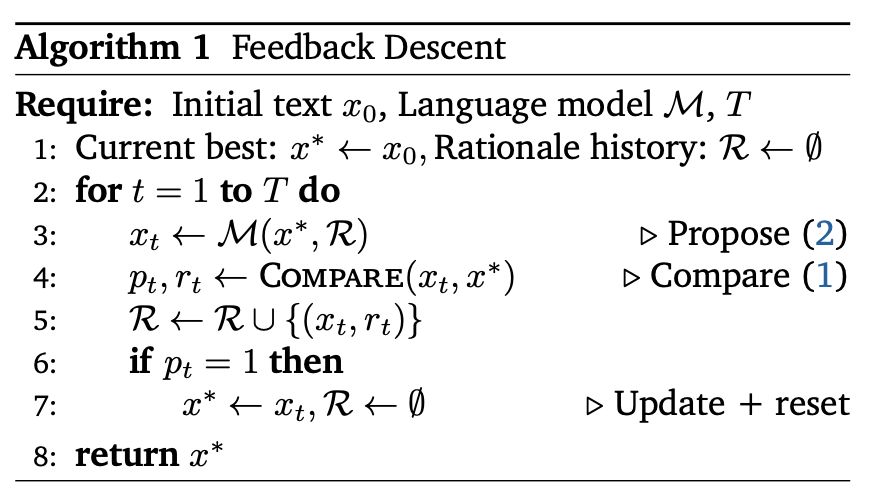
I have included the algorithm below. It features a very simple structure.

               Feedback Descent Algorithm


3. Recursive Self-Improvement

Algorithms that self-improve by running loops like Feedback Descent have been published one after another recently. Furthermore, with the emergence of the latest generative AIs like Fable5, AI agents can now operate for increasingly longer periods, and we can assume the effects of self-improvement will grow even larger. Ultimately, the method known as "Recursive Self-Improvement" will take root, and the performance of AI agents will likely increase exponentially without human intervention.

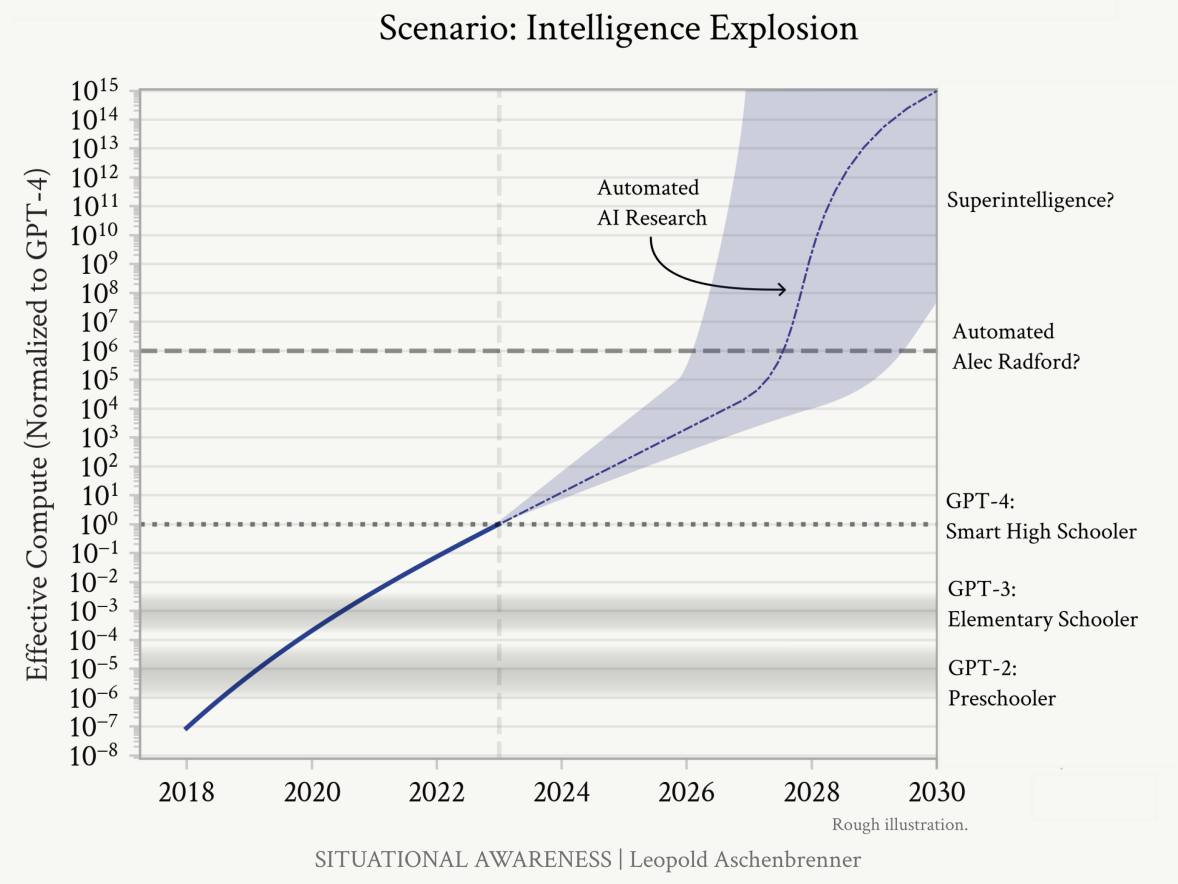
As a result, I believe we are finally approaching the era of AGI step by step. I am sure many of you recognize this graph. It is from a paper (3) released in June 2024 by former OpenAI researcher Leopold Aschenbrenner, predicting that an AGI rivaling the capabilities of human experts in various fields will arrive in 2027.

Actually, I featured this graph on my blog two years ago, in June 2024. Two years have passed since then, but I think that prediction is turning out to be quite accurate. It's truly amazing. I would like to share his words from two years ago here once more:

"Again, critically, don’t just imagine an incredibly smart ChatGPT: unhobbling gains should mean that this looks more like a drop-in remote worker, an incredibly smart agent that can reason and plan and error-correct and knows everything about you and your company and can work on a problem indepen-dently for weeks. We are on course for AGI by 2027. These AI systems will basically be able to automate basically all cognitive jobs (think: all jobs that could be done remotely).”


What did you think? I believe the fact that loops have recently become such a hot topic suggests we are steadily walking the path toward AGI. I am looking forward to the future progress of AI agents.

Here at Toshi Stats, we want to continue challenging new algorithms for "Recursive Self-Improvement." Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) https://x.com/bcherny/status/2064426115255730578
2) Feedback Descent: Open-Ended Text Optimization via Pairwise Comparison, Yoonho Lee, Joseph Boen, Chelsea Finn,  Stanford University,  31 Dec 2025    
3) SITUATIONAL AWARENESS: The Decade Ahead, Leopold Aschenbrenner, June 2024 

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Maximizing Customer Retention: Churn Prevention Strategies Using AI and Machine Learning

It is always sad when customers who have taken the time to purchase our products or services end up leaving. If possible, we want to catch the signs early and take action to prevent them from churning. However, identifying customers who are likely to churn beforehand is no easy task. That is why, this time, I tried creating a customer churn prediction model. I would like to take on the challenge of predicting and countering customer churn using machine learning and generative AI. For formulating the key churn prevention strategies, I used Gemini 3.5 Flash (1), which offers a fantastic balance of performance and cost. Let's get started.

Gemini 3.5 Flash


1. Customer Churn Prediction Model

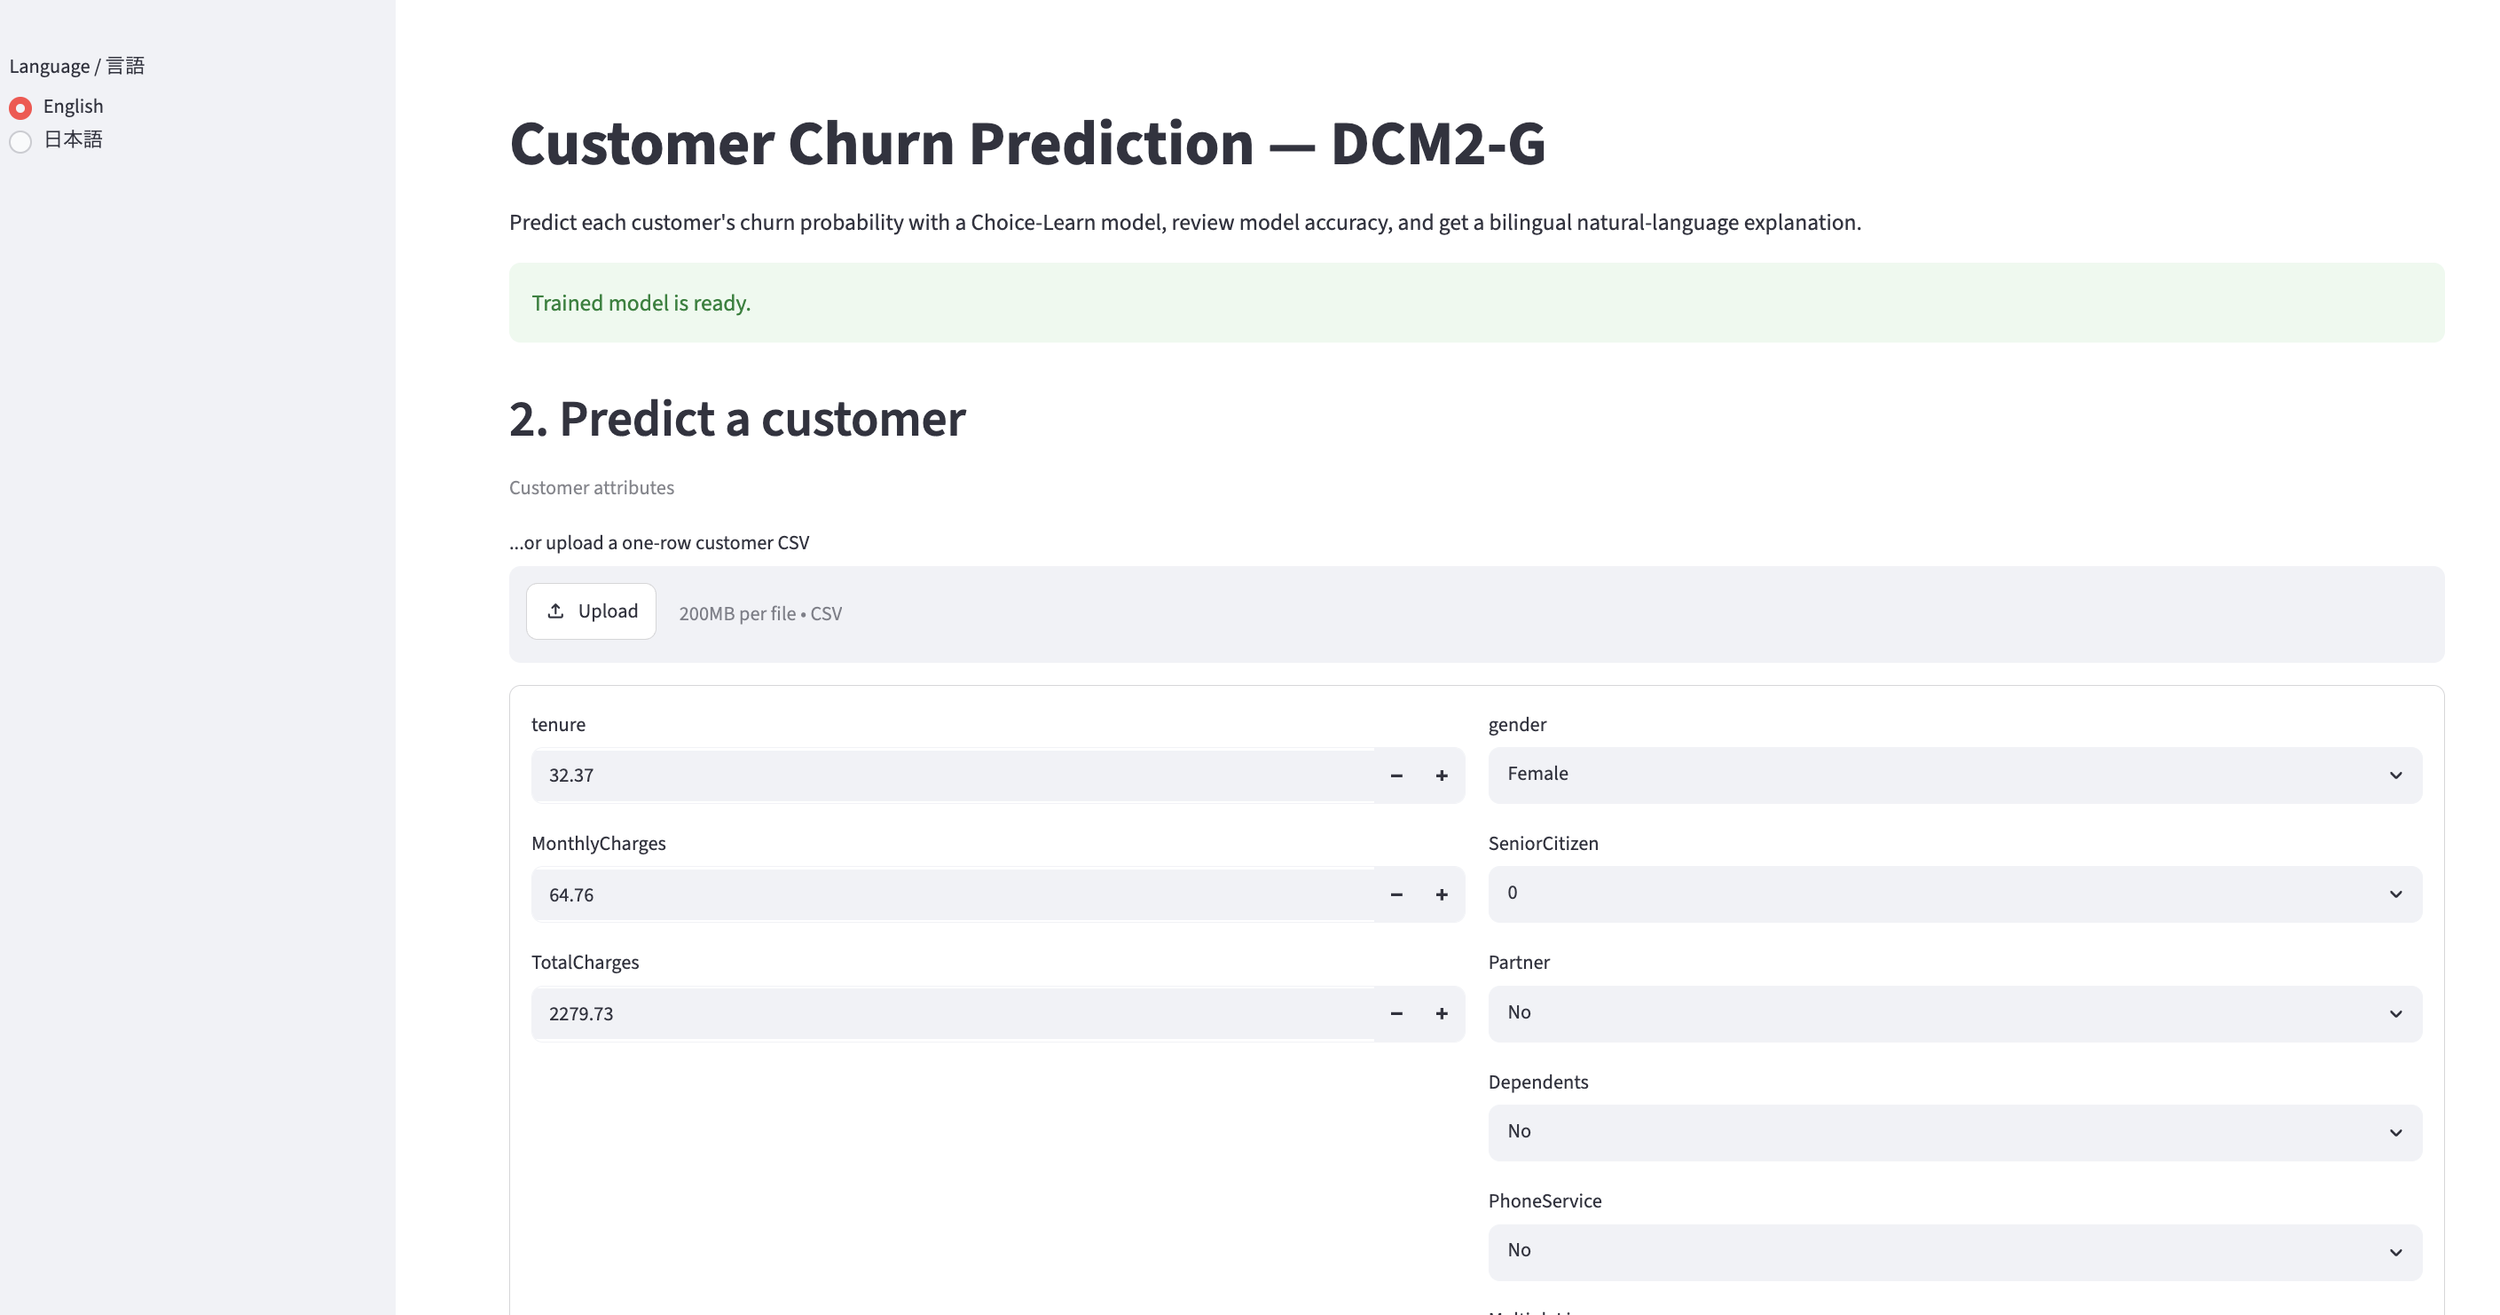
Using the created customer churn prediction model, let's first take a look at a general customer.

General Customer

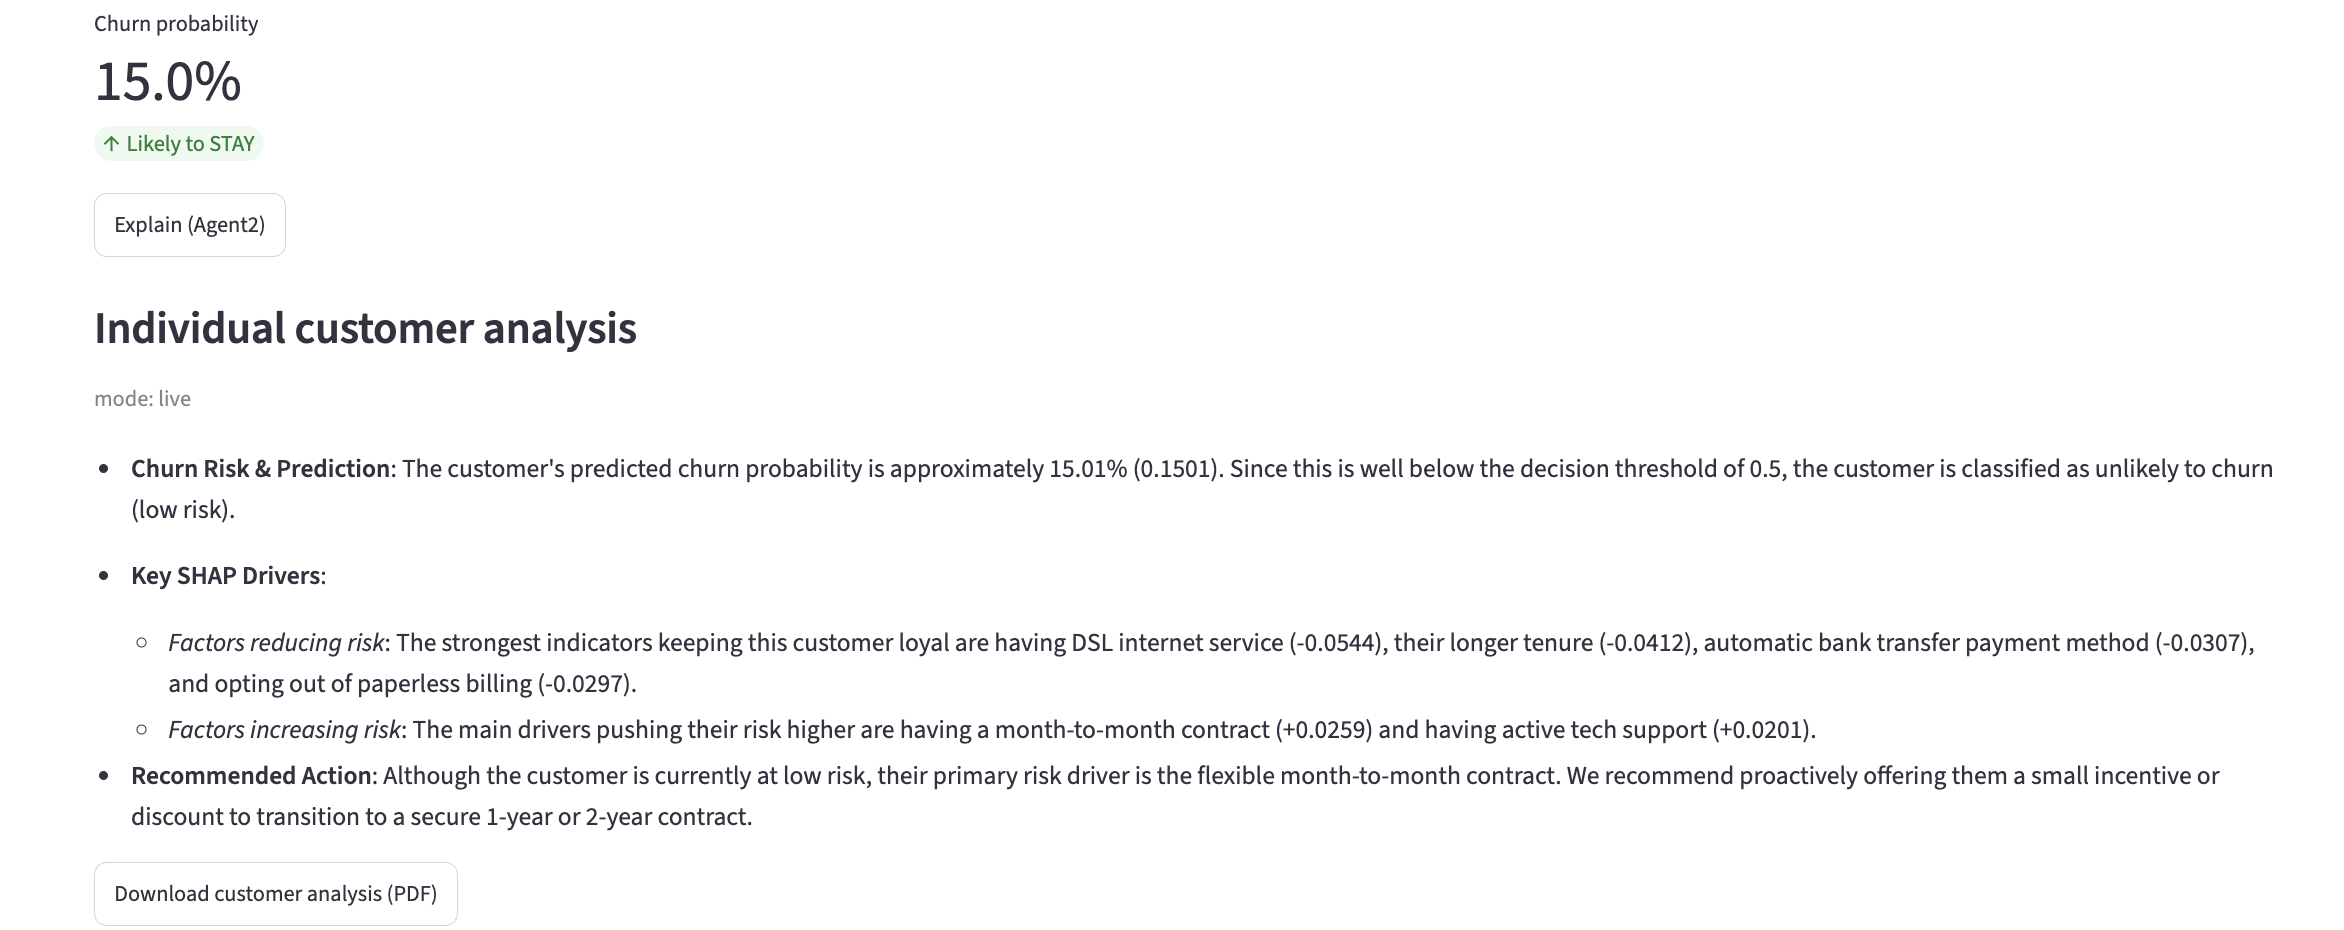
The churn probability is 15.0%, indicating a "high likelihood of continuation," so no countermeasures are needed at this time. That's a relief.

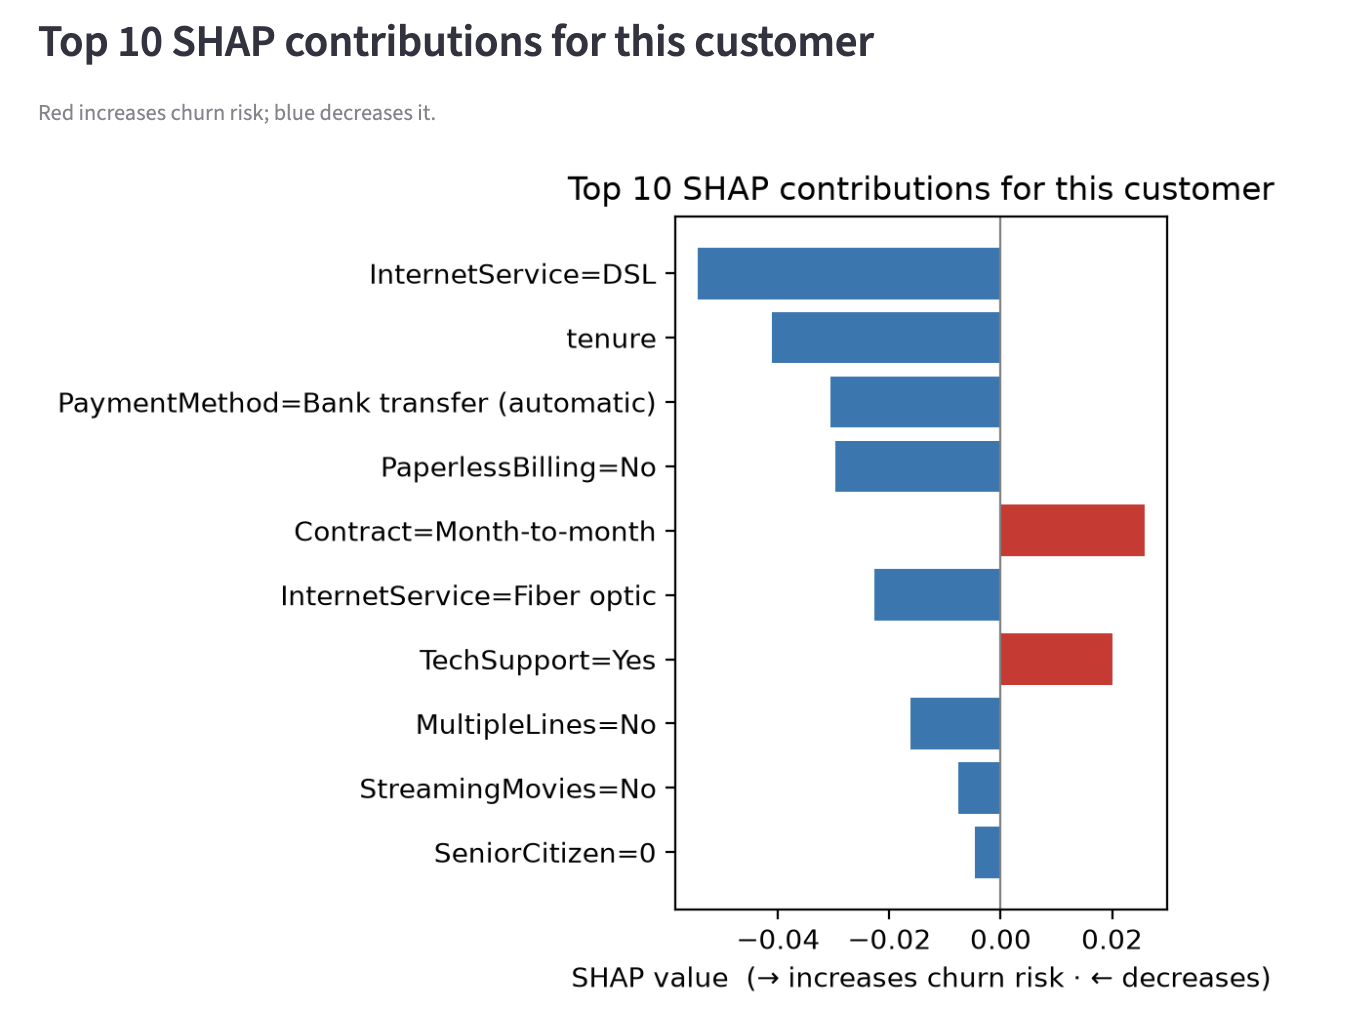
SHAP Analysis of a General Customer

At this point, some of you might be wondering, "But why did the model decide that the likelihood of continuation is high?" This is where "SHAP" (2), shown in the figure above, comes into play. Simply put, it is a "value that indicates which data influenced the model's decision and to what extent." The SHAP graph for this customer extends significantly to the left in the negative direction, indicating that the churn probability is low. SHAP values are assigned to individual customers and show why the model made its decision for each specific customer. It is very helpful for us when trying to understand the results.


2. How to Prevent Customer Churn

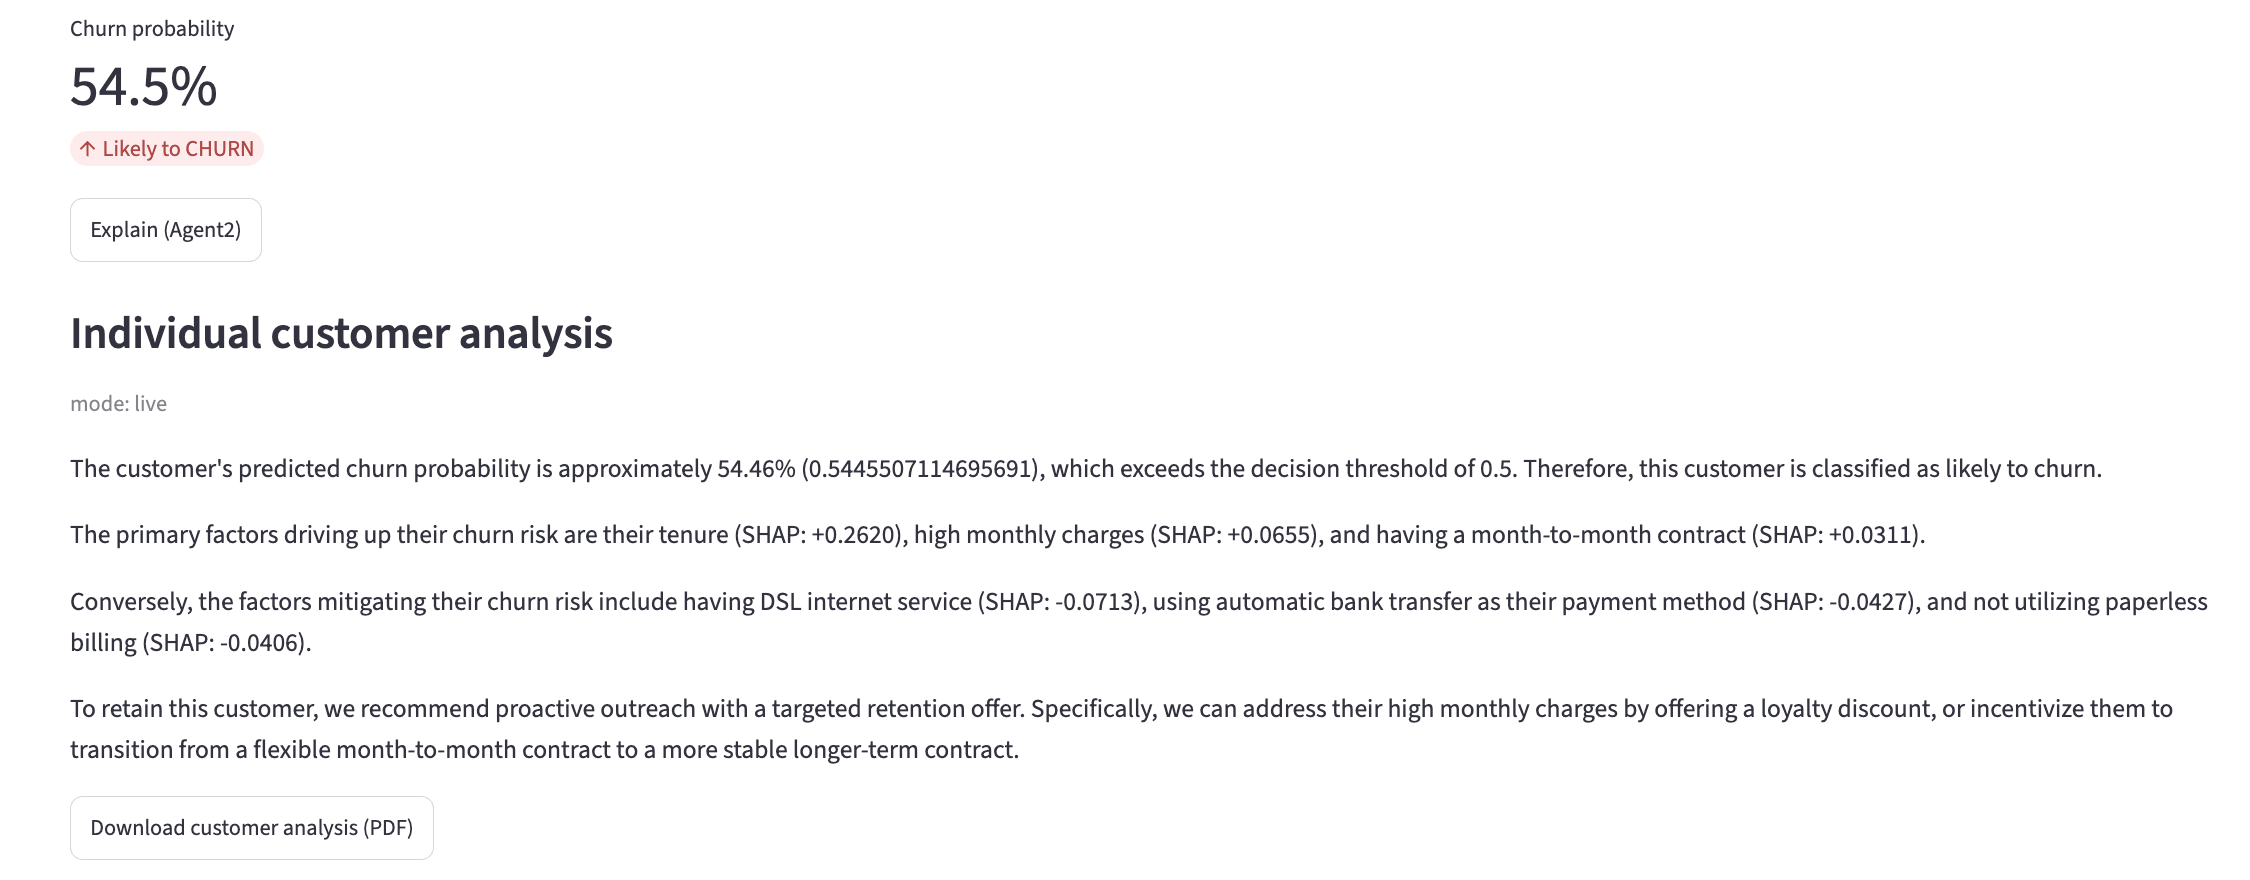
Now, let's look at a customer who is on the verge of churning. Unlike before, the churn probability is 54.5%, indicating a "high likelihood of churning," which suggests that some countermeasures are necessary.

Customer Likely to Churn

Analysis of a Customer Likely to Churn

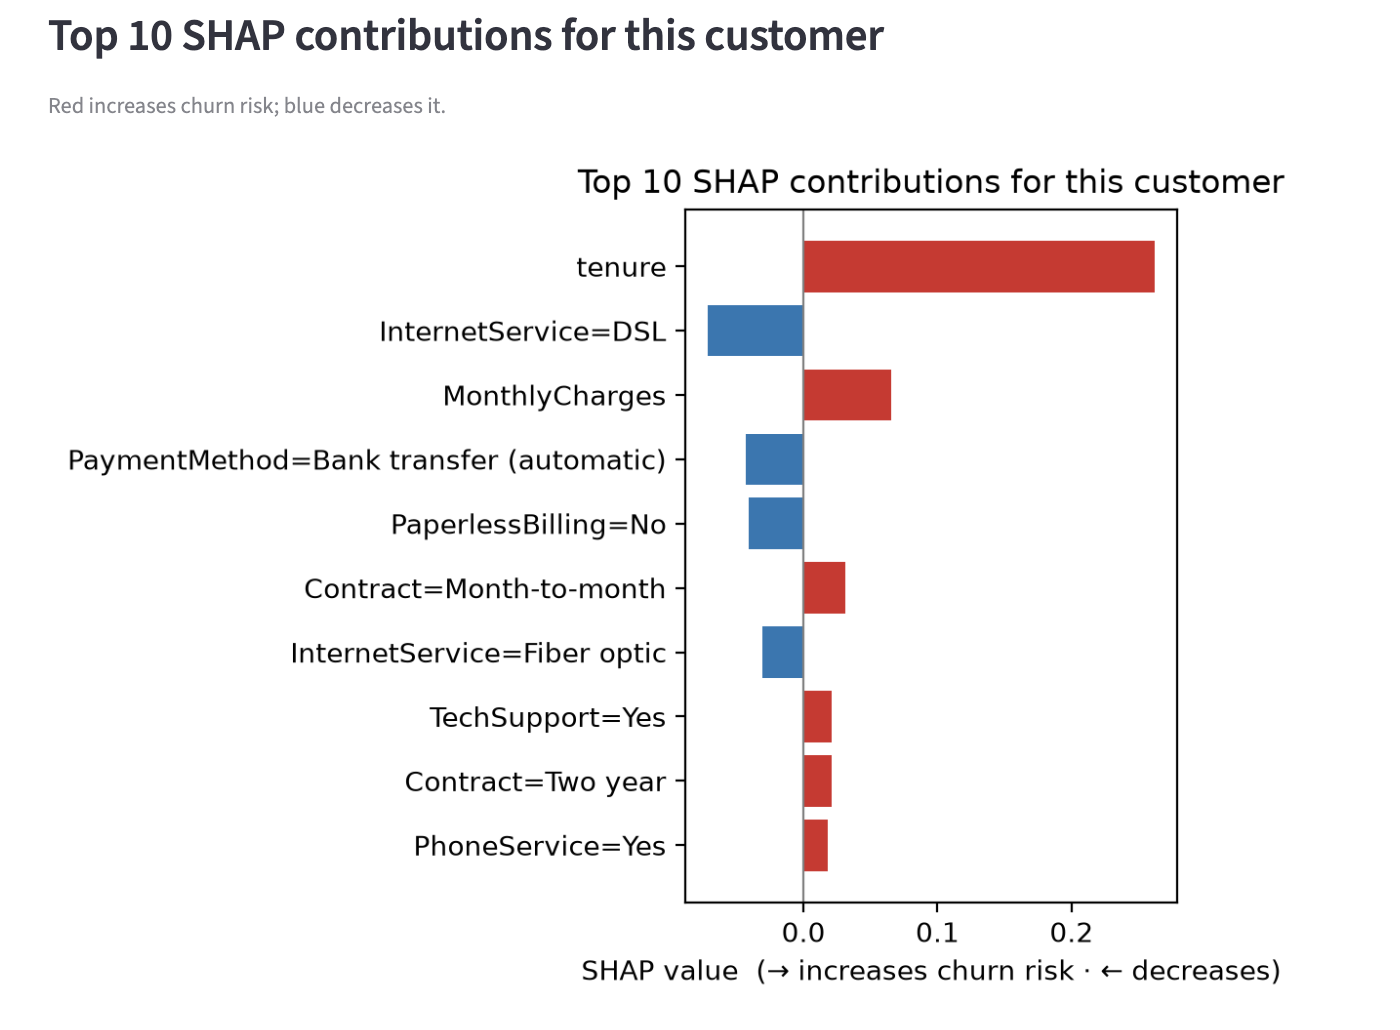
SHAP Analysis of a Customer Likely to Churn

You can see that the SHAP graph, unlike the previous one, extends significantly to the right. In particular, tenure and MonthlyCharges are large, serving as the main factors that increased this customer's churn probability.

Also, in the explanatory text for "Individual Customer Analysis," it states:

“To retain this customer, we recommend proactive outreach with a targeted retention offer. Specifically, we can address their high monthly charges by offering a loyalty discount, or incentivize them to transition from a flexible month-to-month contract to a more stable longer-term contract.”

This is a personalized retention measure for this specific customer. It is not a generic strategy. This is because, as stated in the explanation, it was created by the generative AI, Gemini 3.5 Flash, based on the individual customer's analysis results:

“The primary factors driving up their churn risk are their tenure (SHAP: +0.2620), high monthly charges (SHAP: +0.0655), and having a month-to-month contract (SHAP: +0.0311).”

It is trustworthy precisely because it is a measure tailored to the individual customer's situation. Fantastic!


3. For Further Development

In machine learning and AI, the quantity and quality of the input data are always the key. As these increase, diverse analyses become possible, and accuracy improves. In other words, I believe it is possible to elevate this into a marketing analytics platform in the future. I am really looking forward to its future developments. As the core technologies for this product development, I used Google Gemini 3.5 Flash for natural language processing, Choice-Learn for machine learning, and Google ADK for AI agent implementation. For app development, I am using ClaudeCode. These core technologies do not need to be fixed forever; I think it is best to flexibly use or replace them as needed. Since technological advancement is fast, I plan to adopt the optimal tools available at any given time.


What did you think? I felt that with "Machine Learning + AI," we can create fantastic products where they complement each other perfectly. I'm excited about future developments. Here at Toshi Stats, we plan to continue tackling tasks in the marketing field using "Machine Learning + AI." Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) Gemini 3.5 Flash Best for frontier performance across agents and coding,  Google DeepMind
2) Welcome to the SHAP documentation

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Can AI Agents Invent New Economics? The Future of Theory Generation

Economics offers many theories that are highly useful in business. For example, the economic theory awarded the 2020 Nobel Prize in Economics (1) actually made a massive contribution to the design of spectrum allocation auctions in the United States, successfully creating a market worth over 100 billion dollars. Therefore, this time, I created a simple app using the mathematical proof program LEAN (2) to experiment and see if an AI agent using LEAN can be applied to economics. Let's get right into it.


1. Overview of the Developed App

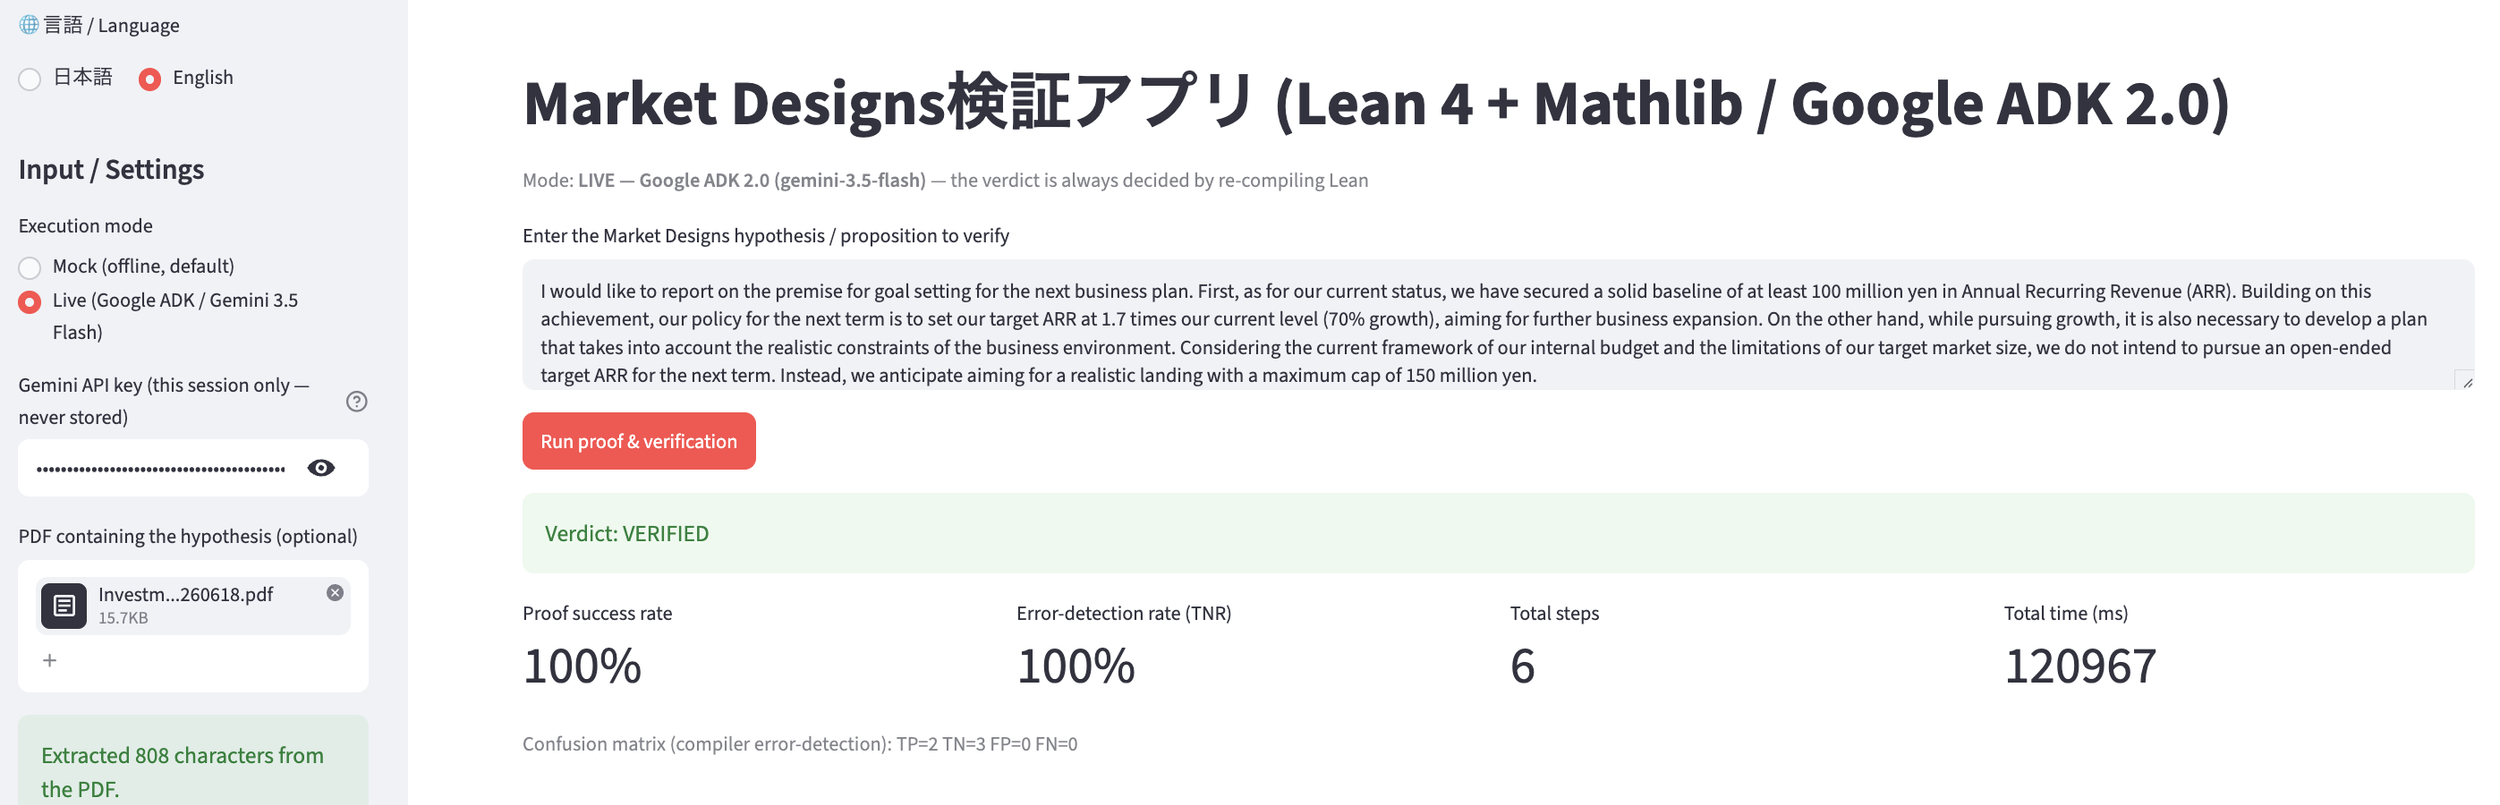
Here is the app's screen. Because of my interest in building new markets, I named it the "Market Designs Verification App." It takes economic propositions and hypotheses and uses LEAN to automatically determine if there are any logical contradictions. I used Google Gemini 3.5 Flash for the natural language processing and Google ADK for the AI agent implementation. For the app development itself, I used Claude Code.

               Market Designs Verification App

The proposition provided this time is as follows. It serves as an example of a simple business plan.

"I would like to report on the premise for goal setting for the next business plan. First, as for our current status, we have secured a solid baseline of at least 100 million yen in Annual Recurring Revenue (ARR). Building on this achievement, our policy for the next term is to set our target ARR at 1.7 times our current level (70% growth), aiming for further business expansion.

On the other hand, while pursuing growth, it is also necessary to develop a plan that takes into account the realistic constraints of the business environment. Considering the current framework of our internal budget and the limitations of our target market size, we do not intend to pursue an open-ended target ARR for the next term. Instead, we anticipate aiming for a realistic landing with a maximum cap of 150 million yen."

I want to verify this hypothesis using LEAN to confirm whether it is feasible. Of course, I want to avoid any hallucinations caused by the LLM.


2. Looking at the Analysis Report

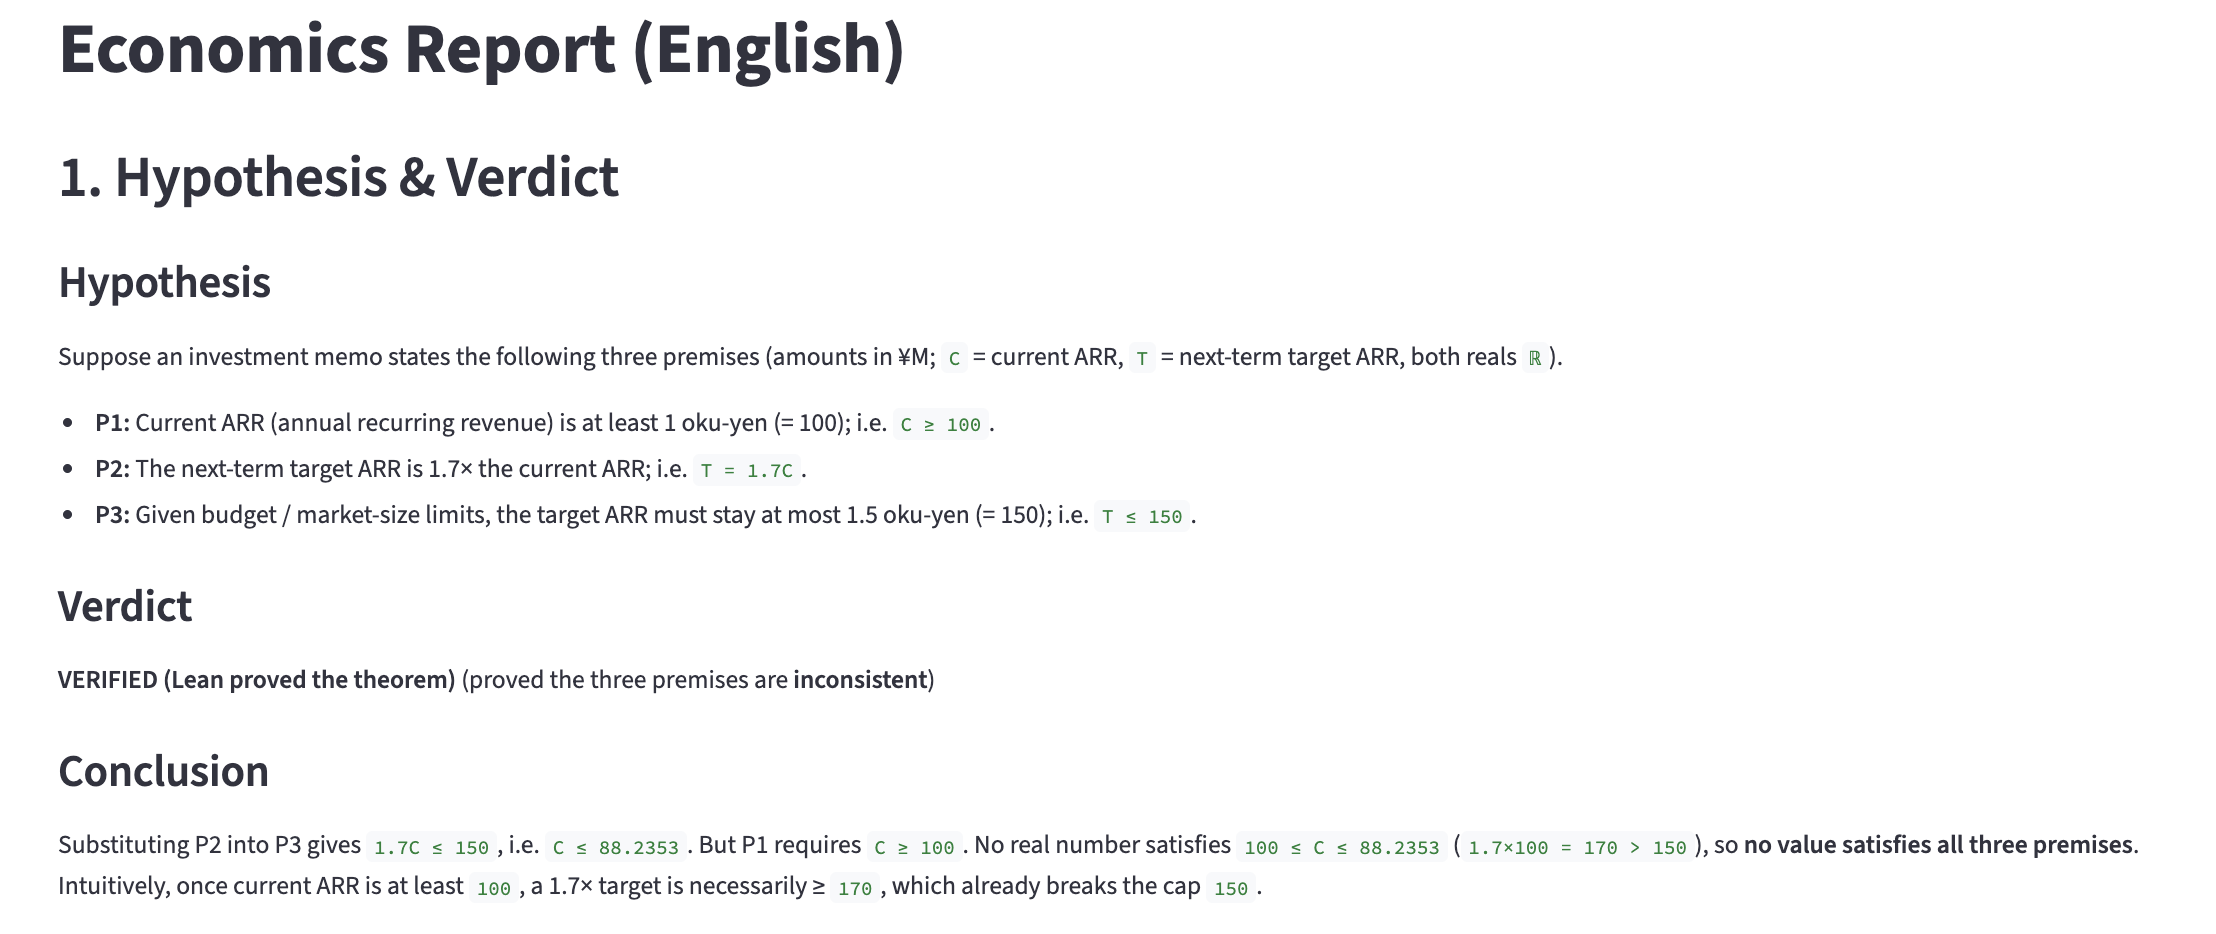
When executing this app, the following report was generated in about 3 minutes. Let's take a look. First, the hypothesis, judgment, and conclusion are summarized. The bottom line is that the growth target exceeds the constraints, meaning execution is impossible.

Final Report

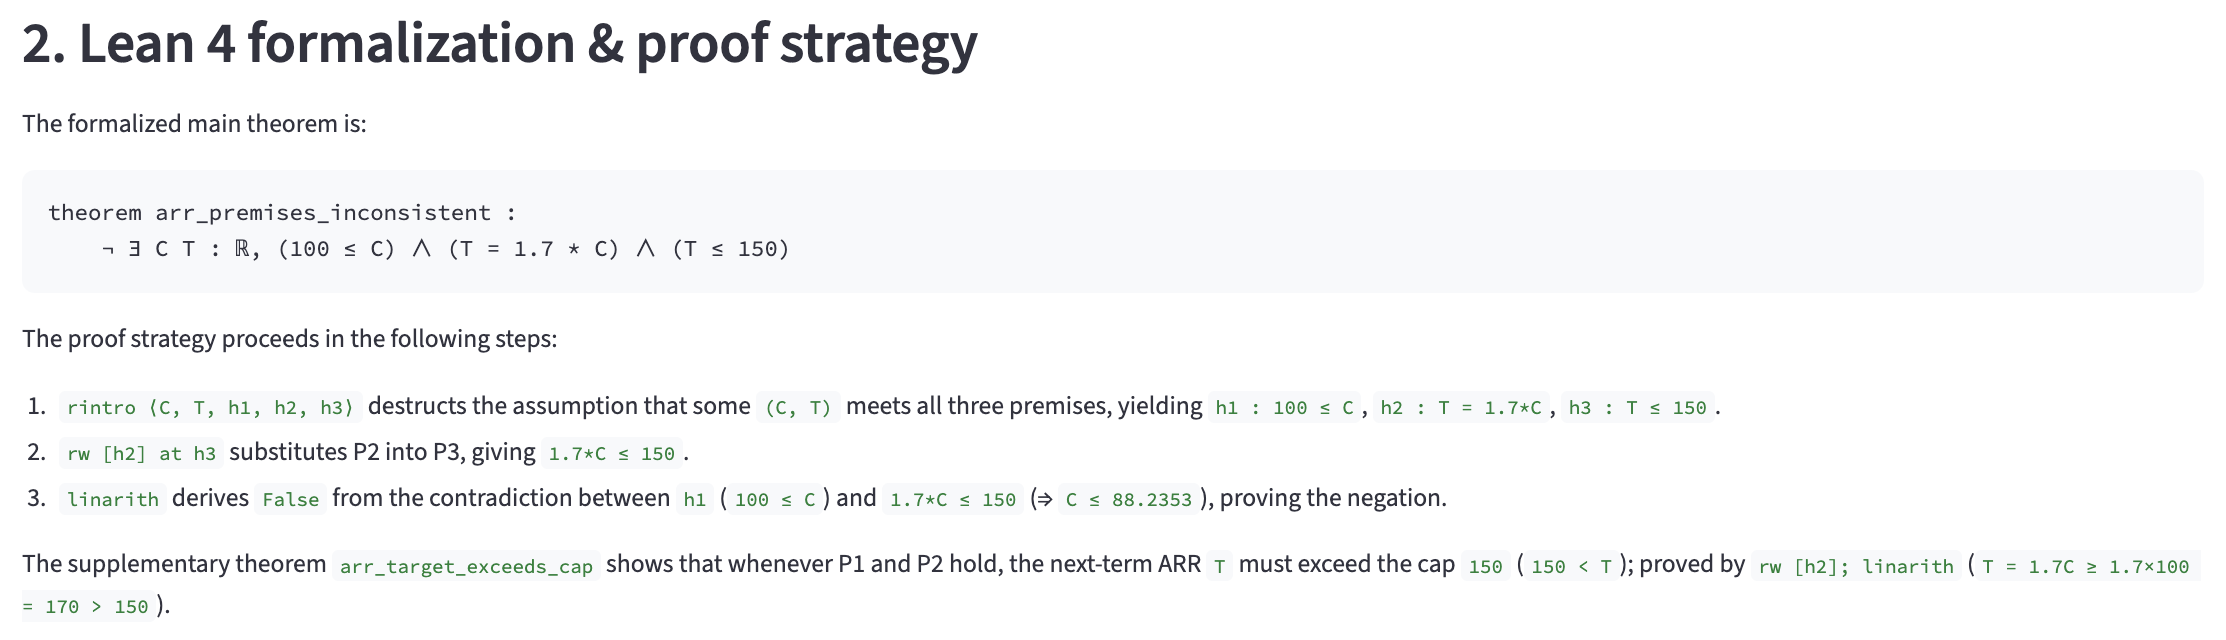
The actual verification process using LEAN is displayed. It is a bit complex.

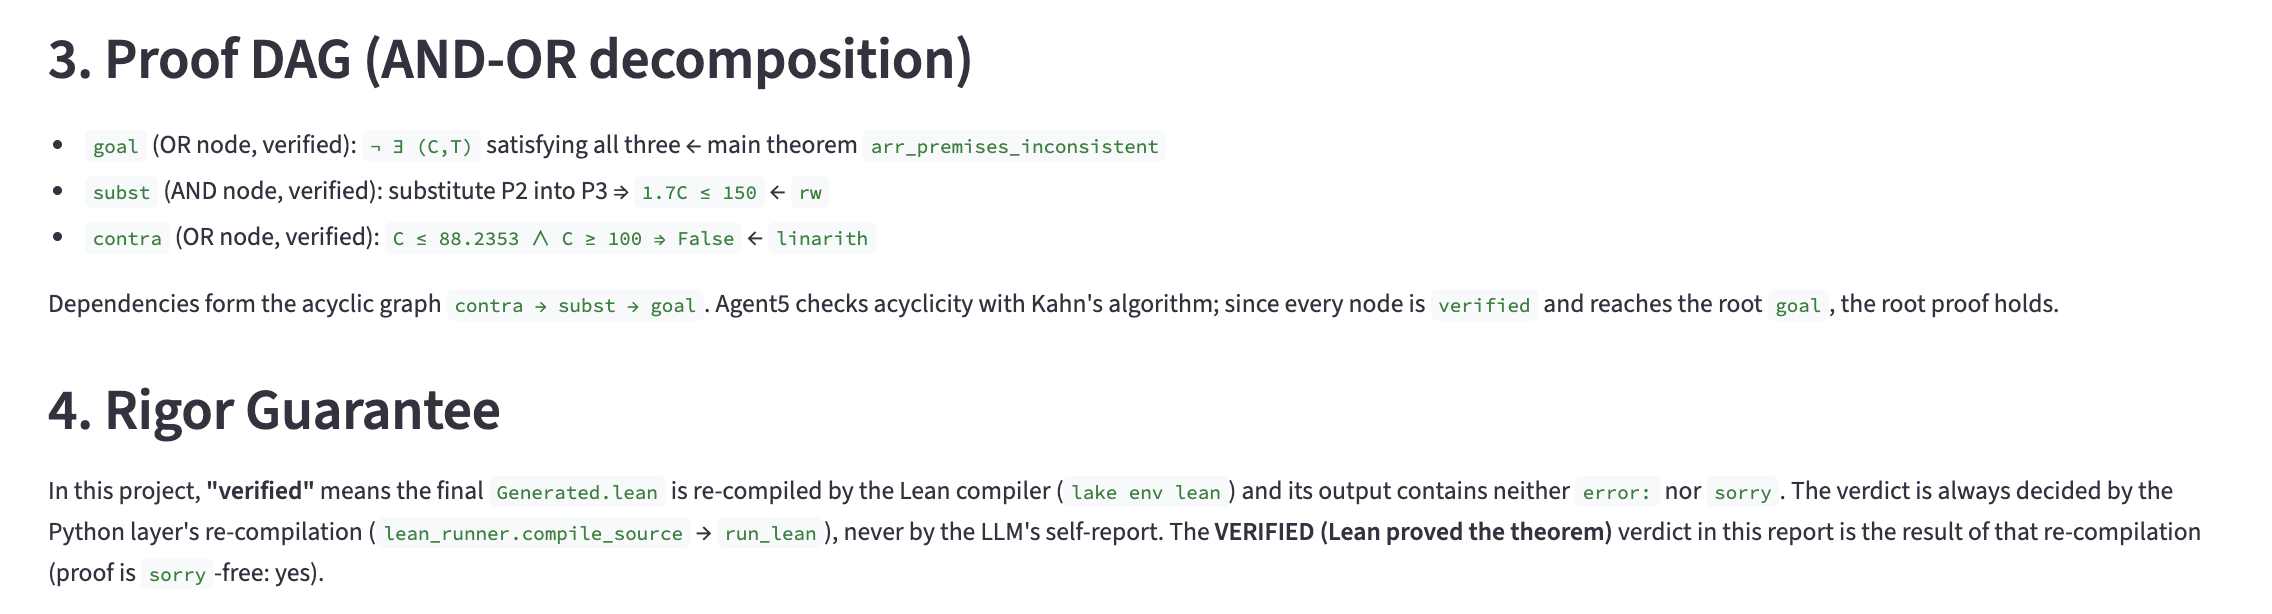
A DAG (Directed Acyclic Graph) is also used. In LEAN, once the compilation finishes, the verification is complete, meaning the proof has been established. Because it is executed strictly, the results are reliable. It is reassuring because there are no hallucinations like those seen with LLMs.


3. Implications Obtained

The implications obtained are as follows:

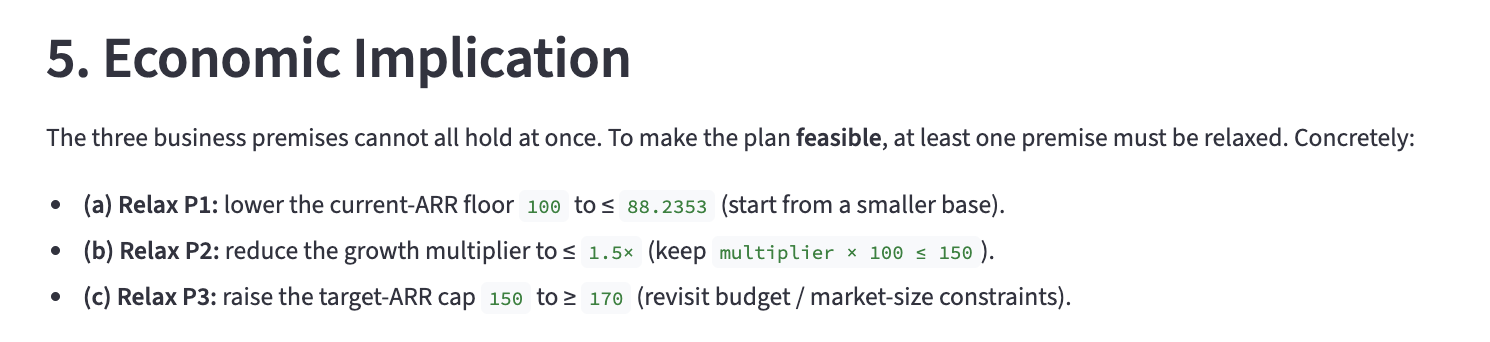
5. Economic Implication

The three business premises cannot all hold at once. To make the plan feasible, at least one premise must be relaxed. Concretely:

  • (a) Relax P1: lower the current-ARR floor 100 to ≤ 88.2353 (start from a smaller base).

  • (b) Relax P2: reduce the growth multiplier to ≤ 1.5× (keep multiplier × 100 ≤ 150).

  • (c) Relax P3: raise the target-ARR cap 150 to ≥ 170 (revisit budget / market-size constraints).

Based on these results, we must leverage them for business decision-making. This time, the results are well summarized, making them easy to understand. This is where the flexibility of LLMs comes into play. It is reassuring that if we can verify even complex management strategies with LEAN, we can automatically determine whether they can be executed without contradictions. In the future, this is expected to become an excellent advisor in boardroom meetings.


What did you think? It was a simple hypothesis verification, but I believe it is entirely possible to apply LEAN to economics. I felt that combining the flexibility of LLMs with the strictness of LEAN creates a wonderful system where they beautifully complement each other. I am looking forward to future developments. At Toshi Stats, we plan to continue tackling tasks in the field of economics using LLM + LEAN. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Stanford Economists Paul Milgrom and Robert Wilson Win the Nobel in Economic Sciences, Stanford Graduate School of Business, Oct 12, 2020
2) LEAN


Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Logic-Powered Agents: How LLMs Evolution in Math is Shaping the Future of AGI

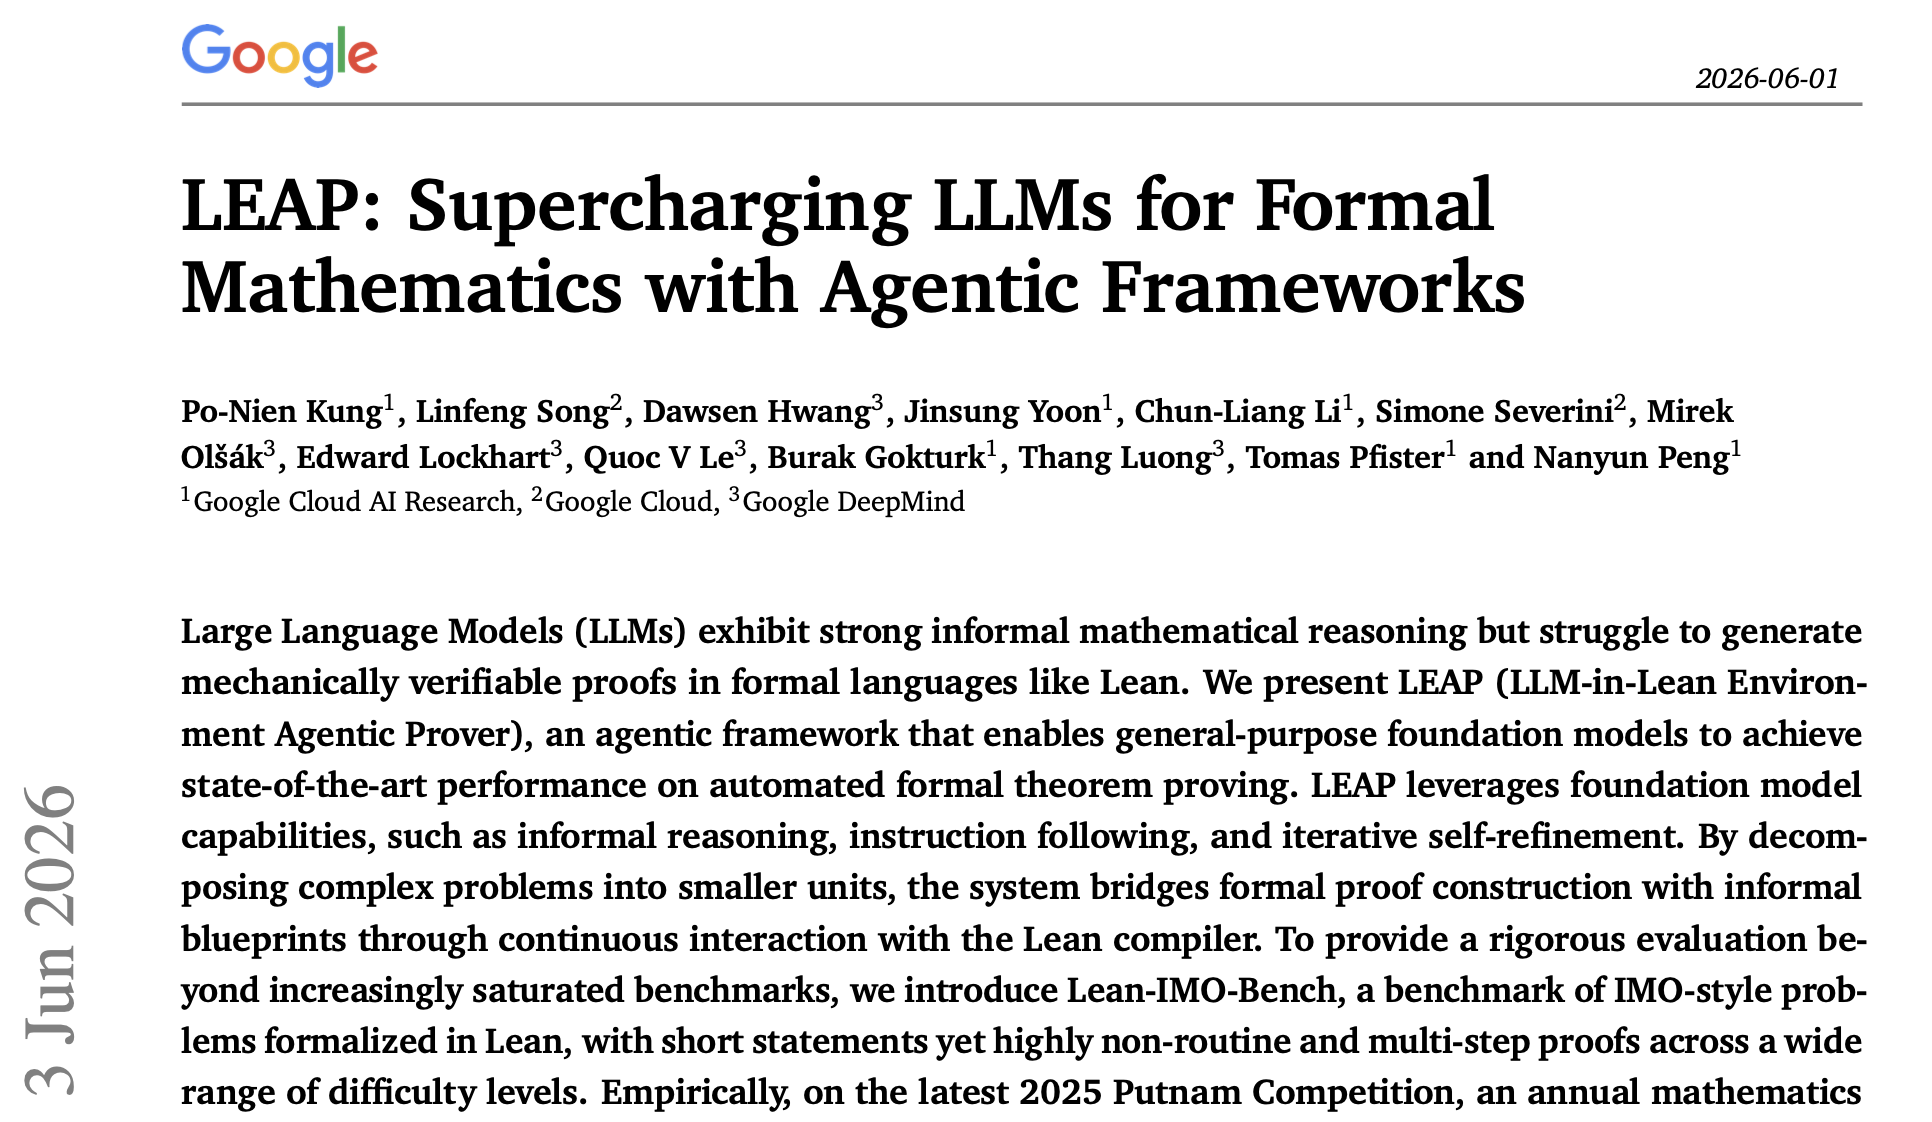
On June 3rd, a new research paper (1) was released by Google. It states that difficult mathematical proofs were solved by combining the LLM Gemini 3.1-pro with a mathematical proof language called LEAN (2). This time, I would like to delve into this paper and consider what kind of developments we can expect from this new AI agent in the future, beyond the framework of mathematics.


1. The Synergistic Effect of the LLM's Flexibility and LEAN's Strictness

Here is the paper, featuring an active AI agent called LEAP. It only uses Gemini 3.1-pro as the LLM, and no specific fine-tuning has been performed. It is being used straight out of the box. Even so, it is reported to demonstrate outstanding exploration capabilities in mathematical proofs. Since it doesn't require any particular additional training, it can be used immediately without doing anything, which is very convenient for practical use. Furthermore, by using LEAN in conjunction, if a proof with contradictory logic due to hallucinations is produced, an error occurs during compilation, creating a mechanism where it is automatically rejected.

         LEAP (LLM-in-Lean Environment Agentic Prover)

Since LLM responses can fluctuate probabilistically, humans need to verify them in detail when conducting rigorous arguments. However, by introducing LEAN, this process has been automated. This is very reassuring. It seems that this fantastic result was achieved by combining the flexibility of the LLM and the strictness of LEAN in this way. Let's look closer.


2. The Structure and Accuracy of LEAP

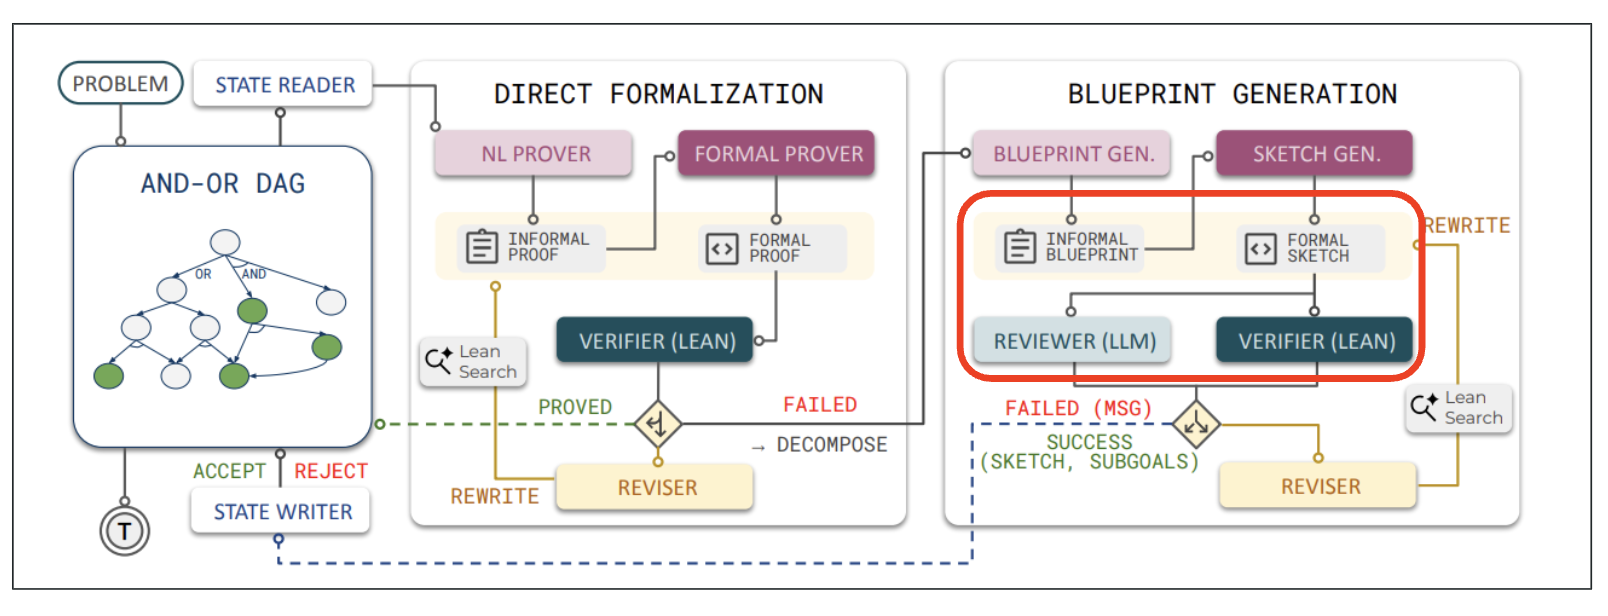
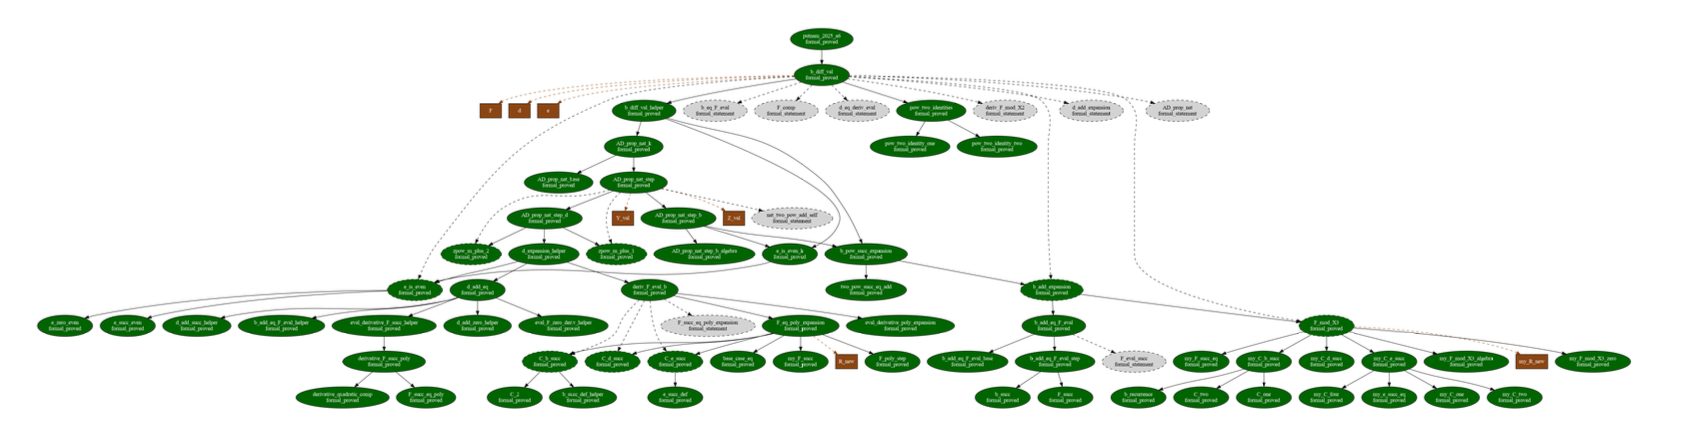
Here is the structure of LEAP. The figure on the left is the roadmap for the theorem to be proved using LEAN. Technically, it forms a structure called a DAG (Directed Acyclic Graph). Complex mathematical proofs are not completed in a single attempt; the proof progresses by going back and forth between the LLM and LEAN several times. The key here is the section in the red frame, where the LLM describes an INFORMAL BLUEPRINT in natural language and converts it into a FORMAL SKETCH in LEAN. Furthermore, a two-tier review by LEAN and the LLM awaits. LEAN verifies whether the new proof method has any contradictions, and the LLM's review verifies whether that method is genuinely effective. In other words, the LLM acts as a pilot in the search for proof methods. Even though it's just using Gemini 3.1-pro as is, its potential is truly surprising.

                LEAP workflow

Now, let's look at the results of applying LEAP to an actual task. It tackled the notoriously difficult Putnam 2025. Putnam 2025 contains twelve undergraduate-level problems from the 86th William Lowell Putnam Mathematical Competition, a highly challenging North American mathematics competition.

Looking at the DAG, you can see how the proof actually progresses. In this example of Putnam 2025 Problem A6, you can see layers upon layers of connected proofs. It's certainly a difficult problem. The green indicates the parts that have already been proven.

            DAG example for Putnam 2025 Problem A6

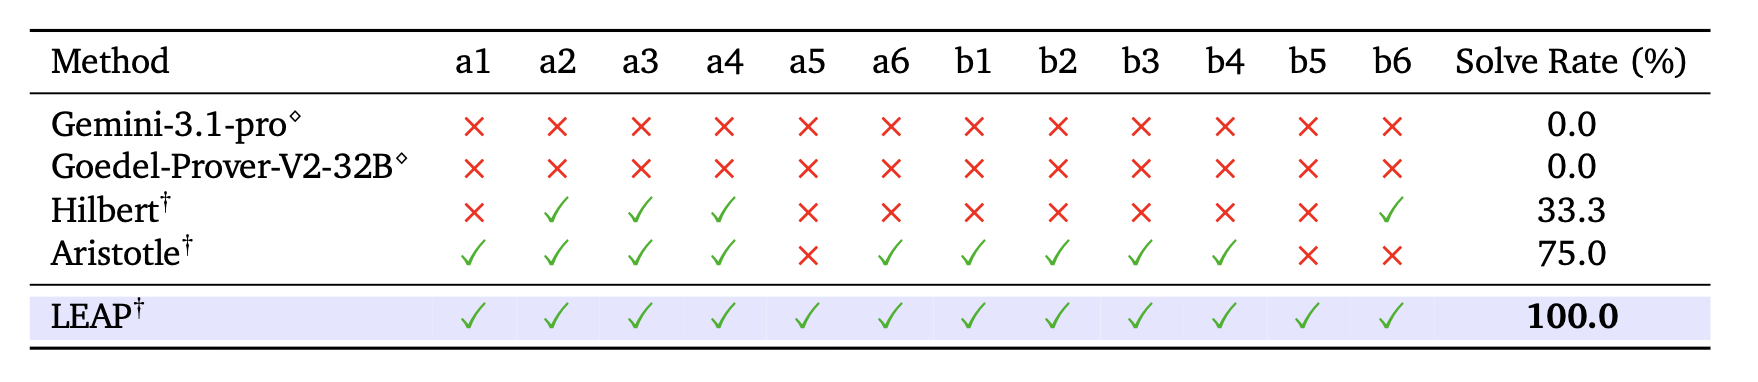
The results, as shown below, were that LEAP answered all questions correctly. An overwhelming accuracy.

                Results on Putnam 2025

You can see that while the original Gemini 3.1-pro couldn't score at all, it was able to demonstrate tremendous capabilities by combining it with LEAN. I think it is truly a breakthrough.


3. Beyond Mathematical Proofs into Various Fields

What we have seen so far were tasks related to mathematical proofs. With LEAP being able to construct such perfect logic, I felt it would be a waste to keep it confined solely to mathematics. In particular, its application to economics, which is directly linked to business practices, has immense scope and depth, and I believe it can contribute to expanding the areas where LLMs can be active. Economics is also generally described using mathematical formulas, so I think it has a high affinity with LEAP. A paper (3) on its application to economics has already been published, so if you are interested, please do give it a try.


What did you think? I believe the combination of LLMs and LEAN will be expanded and improved in various ways in the future. It might be stepping closer to AGI. It's very exciting.

At Toshi Stats, we plan to take on tasks in the field of economics moving forward. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) LEAP: Supercharging LLMs for Formal Mathematics with Agentic Frameworks, 3 Jun 2026, Google
2) LEAN
3) We Can't Agree to Disagree, Formally: Aumann's Theorem and Assumption Accounting in Lean, May 27, 2026, Ruize Chen, Ben Eltschig, Ken Ono, Jujian Zhang  Axiom Math,  Scott Duke Kominers Harvard University; a16z crypto

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

A Game-Changer for Financial Analysts: How Opus 4.8 Redefines Financial Research !

Anthropic has announced the update of its generative AI, Claude Opus 4.8. This update came less than 40 days after the previous one, which came as a bit of a surprise, but it may indicate that their internal development efficiency has increased significantly. Therefore, in this article, I would like to take on the challenge of using a combination of Claude Code and Opus 4.8 to conduct a financial analysis using US financial statements and create an investment memo.


1. Opus 4.8: The Most Powerful Model at Present

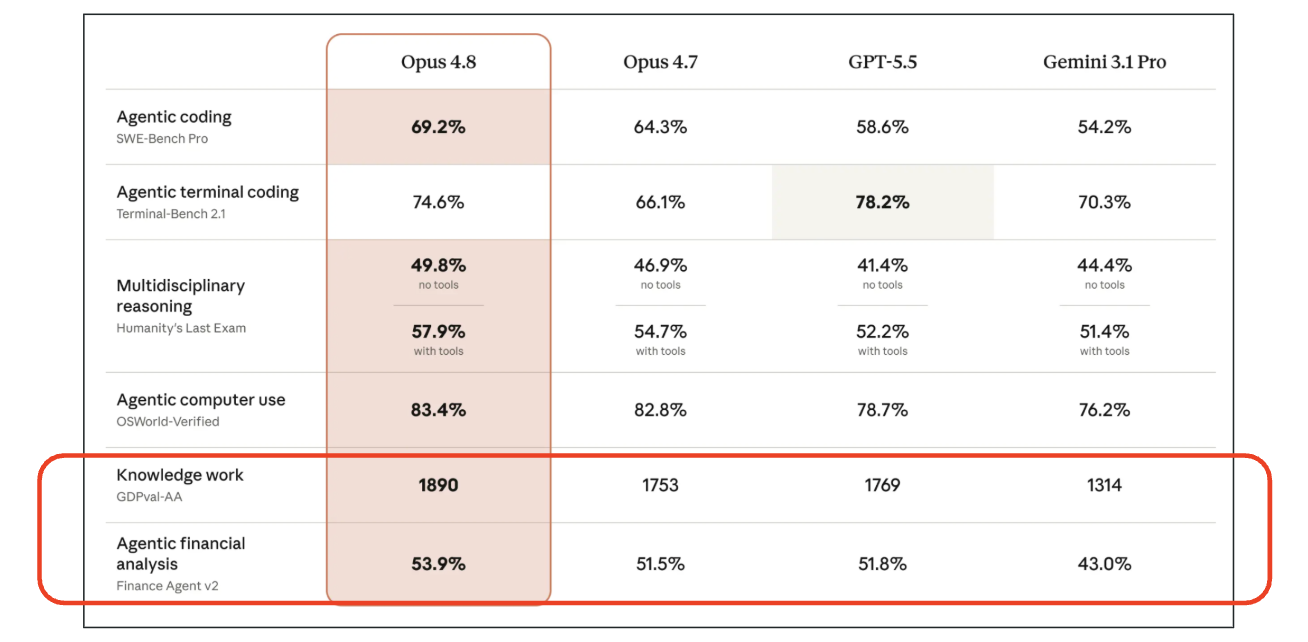
As always, when a new generative AI model is released, I compare its performance with existing models. The introduction page for Opus 4.8 (1) features the comparison table shown below. It is reported to have outperformed existing models in almost all areas. While strong coding capability is a tradition for the Opus series, what caught my attention was its exceptional strength in knowledge work. As indicated by the red box, it has achieved excellent results in two benchmarks that measure knowledge work capabilities.

‍           Opus 4.8 Performance Comparison

Therefore, in this article, I would like to verify the potential of Opus 4.8 regarding knowledge work.


2. Challenging the Creation of an Investment Memo

This time, I will attempt to create an investment memo for Google using Form 10-K, the annual performance report registered with the US SEC. An investment memo is an internal document created for investors to make a final in-house decision (approval) on whether or not to execute an investment in a specific company. Normally, financial analysts mobilize their expertise to create this based on source materials. This time, I would like to try automating that process.

First, I used the plan mode of Claude Code to formulate an implementation plan. I created a detailed plan this time as well. The following shows the initial part of it, but the actual plan continues further.

‍  ‍            Implementation Plan

After reviewing the created implementation plan and confirming there were no issues, I switched Claude Code to auto mode and actually started coding. This time, the implementation was completed all at once in about 30 minutes without stopping midway. Once I gave the green light, there was no human intervention required. It was a moment where I caught a glimpse of the true capability of Opus 4.8.

Normally, you would need a "prompt" that defines and instructs how to write each section of the investment memo, but I did not need to write it myself. Here too, Opus 4.8 automatically generated the "prompts" for me. The following is an example of this, and it is well-written without missing any key points. It is truly amazing.

‍  ‍              Generated Prompt Example


3. Reviewing the Investment Memo

In this experiment, I had the investment memo created in both English and Japanese versions and outputted as PDF files. Let's take a look at the content right away. It summarizes the overview beautifully in the opening section, as shown below. It looks very sophisticated.

investment memo by ClaudeCode with Opus4.8

It also summarizes the investment theme concisely as follows.

The investment memo this time exceeds 10 pages in total, so I cannot introduce the full text here, but I would like to look specifically at the section on competitive advantage analysis.

I think it is very well summarized. If the process can be automated to this extent, humans only need to review it, which will dramatically increase work efficiency. Furthermore, if you desire a deeper analysis leveraging domain knowledge, you can simply rewrite the "prompts." This means you can proceed based on existing work, allowing for smooth and efficient collaboration between humans and generative AI. It is wonderful. By the way, please understand that these texts were created for educational purposes and cannot be used for making investment decisions.


What did you think? I challenged the creation of an investment memo using Claude Code and Opus 4.8, and the results exceeded my expectations. I believe the performance of Opus 4.8 in knowledge work was outstanding. However, I would like to emphasize that a final review by a human is absolutely necessary. It is important to bear in mind that hallucinations can still occur. Moving forward, cooperation between generative AI and humans will continue to be essential.

At Toshi Stats, we plan to take on various tasks using Opus 4.8. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) Introducing Claude Opus 4.8,   May 28, 2026,  Anthropic PBC

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

Is Google Omni One Step Closer to AGI? Testing It in a 10-Second Video

The other day, Google held its annual developer conference, Google I/O, where they announced "Gemini Omni," a new multimodal generative AI. Google has championed AGI (Artificial General Intelligence) since its inception, viewing multimodal AI as an essential requirement to achieve it. In this article, we will use "Gemini Omni" to examine just how much closer we have come to AGI.


1. What Kind of AI is "Gemini Omni"?

First, let's look at the explanation released by Google (1).

"We’re introducing Gemini Omni, where Gemini’s ability to reason meets the ability to create. Omni is our new model that can create anything from any input — starting with video. With Omni, you can combine images, audio, video and text as input and generate high-quality videos grounded in Gemini's real-world knowledge. You can also easily edit your videos through conversation.Gemini Omni Flash is a model that can create anything from any input – starting with video."

In short, it can be described as "a generative AI that can take any form of information as input and output it in any format." It appears that "Omni" understands 3D spatial information, visual elements, and physical laws—such as objects falling downward—which are difficult to grasp through text alone. This is truly a massive leap forward toward AGI.

The Omni Flash model that debuted this time is limited to video output only. However, in line with the "any-to-any" concept, the next version is highly expected to support output across all formats. It is something to look forward to.


2. The Task: Singing to a Given Theme

So, how capable is Omni Flash in practice? Can it successfully integrate various forms of information? Can it maintain consistency in its output? To test this, we will use the image below, add a prompt, and see if it can sing emotionally based on a specific theme. She is Leia, an instructor at ToshiStats Co. She is a familiar face on YouTube, but this time she is participating in our experiment.

             Leia, Instructor at ToshiStats Co.Ltd.

For this experiment, we prepared the following prompt:

"She is singing 'Kita-wing' in English. It is 80s Japanese pop. This must be 1. An urban and bittersweet melody, 2. about emotion of an independent, mature woman for love, 3. provide courage for action, 4. A movie-like scenery born from a 'midnight flight', 5. A deep, plaintive, and vibrating long vibration. 6, This scene is needed 'An airplane gliding through the midnight sky above the glowing metropolis.'."

We entered this prompt along with the image above. We believe this makes the singing theme reasonably clear. In particular, we want to focus on how well it can express emotional nuances, such as item 1: "An urban and bittersweet melody."

While you can listen to Leia’s actual singing later on YouTube, let's walk through the analysis first. Although the original Leia had a bright smile, the singing Leia looks somewhat sorrowful.

When it transitions to a close-up, those emotions become very clear.

We specified in the prompt to incorporate a "midnight flight" scene. It has indeed been inserted effectively. In the actual video, the airplane moves slowly.

Her physical expressions and body language look natural as she conveys emotion. It is impressive.

Actually, the video ended right at the climax. Ah, what a pity. I wanted to hear more. The maximum generation time for the current Omni Flash is 10 seconds, so it cannot be helped. Let's look forward to an extended generation time in the next version update.

Please take a moment to listen to Leia's song. Both English and Japanese versions are available. The English version is nearly perfect, but the Japanese version has a few parts where the pronunciation is slightly unclear. This is an area for improvement.


3. The Roadmap to AGI

In this test, Omni Flash consistently generated quite difficult emotional expressions. It understood the meaning and context—keeping her original clothing unchanged while swapping out only the background to match the theme—to create the video. Its adherence to the prompt was also excellent. While the short generation time remains a bottleneck, the content itself deserves high praise.

It is highly probable that Google will use Omni Flash as a starting point to accelerate its development toward AGI. The AI industry is currently suffering from a shortage of GPU supplies, and Google has become one of the few actively speaking out about AGI. Ultimately, being able to develop and produce their own computing resources, such as TPUs, gives them an overwhelming advantage. Demis Hassabis, CEO of Google DeepMind, who is leading the development of Omni Flash, has stated that AGI is "just a few years away" (2).


What did you think? Through this experiment, we confirmed the latent potential of the new multimodal generative AI "Omni" and discussed its possibilities for achieving AGI. Here at ToshiStats, we will continue to explore various ideas under the theme of "Road to AGI." Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Introducing Gemini Omni,  Google
2)  A new era of discovery: AI and the frontiers of science with Demis Hassabis, May 22, 2026,  Google for Developers

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

"Agentic Commerce and Agentic Payments: The Next Game Changers for the Financial Industry?"

On May 7, 2026, Mitsubishi UFJ Financial Group, Inc. (hereinafter referred to as MUFG) and Google announced a strategic partnership in the retail sector. They stated that they will collaborate to create new financial services and customer experiences within Japan's retail finance industry. The fact that MUFG, one of Japan's largest financial conglomerates, has teamed up with Google—often regarded as the strongest among AI giants—has an extremely significant impact. In this article, out of several key points, I would like to delve deeper, focusing particularly on AI agents.


1. Agentic Commerce and Agentic Payments

First, let's take a closer look at the release from MUFG regarding the section on AI agents (1).

Content of the Partnership (1)

Next-Generation Financial Experiences Supported by AI Agents, spanning from Purchases and Payments to Financial Transaction Decision-Making: Initiatives Toward Autonomous Finance, including Agentic Commerce / Agentic Payments

  • We will collaborate with an eye toward early domestic realization in the fields of "Agentic Commerce" and "Agentic Payments," where AI agents autonomously support a continuous series of processes from product selection and purchasing to payment execution.

  • Google Cloud plans to leverage its expertise in AI and cloud infrastructure to provide MUFG with cloud and AI technologies, as well as technical advice and development support for these initiatives.

  • Through this partnership, MUFG aims to build a next-generation payment infrastructure on Google Cloud to realize Agentic Commerce / Agentic Payments, striving to establish a new standard for purchasing and payments in the AI agent era in Japan.

  • Furthermore, by having AI agents that cooperate at a high level on this same platform support decision-making processes in daily purchases, payments, and various procedures, we aim to realize a new form of finance (autonomous finance) that gently guides customers without burdening them, while respecting their intentions.

  • In addition to digital channels, we will integrate physical touchpoints such as branch offices and remote consultations. By having AI agents understand and support situations across channels, we will provide a consistent sense of security and convenience, while achieving continuous support tailored to each individual customer throughout their daily lives and life events.

As shown above, this is a highly ambitious strategy. In particular, the phrase "MUFG aims to build a next-generation payment infrastructure on Google Cloud to realize Agentic Commerce / Agentic Payments, striving to establish a new standard for purchasing and payments in the AI agent era in Japan" felt like a self-declaration that they will leave other domestic competitors far behind. The following chart is a conceptual diagram of Agentic Commerce / Agentic Payments (1). Next, let's think about why MUFG chose Google.

‍  ‍       Conceptual Diagram of Agentic Commerce / Agentic Payments


2. Google’s AI Agent Protocol Suite is One of the Strongest in the World

The primary reason for MUFG choosing Google this time is presumed to be that the suite of AI agent protocols spearheaded by Google is one of the strongest in the world, making it difficult to find alternative options. Starting with the release of the Agent Development Kit (ADK, 2) in April 2025, Google has successively released AI agent protocols (communication standards) such as A2A, AP2, and UCP, expanding its partner network and leading the industry in standardization (3). In particular, the Agent Payments Protocol (AP2) is a protocol specialized for payments, which must have been highly coveted by the financial industry. Currently, each of these is evolving as open-source software, but the fact that Google is driving them is nevertheless crucial. The following material writes well about AI agent protocols. I highly recommend giving it a read (3).

Developer’s Guide to AI Agent Protocols (3)


3. Potential for Development from the Japanese Market to the Global Market

Future developments might be easier to understand when looked at from Google’s perspective. Google knows all too well how much of a competitive advantage can be gained by securing a de facto standard in software. A prime example of this is Android, the operating system for mobile devices. Companies that want to manufacture mobile devices typically adopt Android. This is because the Android ecosystem is fully established, and even if a company were to build a proprietary system from scratch now, no partner would willingly adopt a brand-new OS. Many of you probably use mobile devices that run on Android. Through this ecosystem, Google is always able to maintain a competitive advantage in mobile devices. If they can establish a position like Android's in purchasing and payments for the AI agent era, it will bring massive benefits. Although this partnership concerns the Japanese retail market, if it succeeds in the Japanese market, expanding it as-is into the global market would be easy. This is because, inherently, there are no national borders for AI agent protocol suites. We cannot take our eyes off future developments.


What do you think? It feels like a harbinger of AI agents entering the payment market in earnest. I am very much looking forward to seeing how future financial services will change.

At ToshiStats, we will continue to think about the evolution of AI agent protocols and financial services. Look forward to it. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) Strategic Partnership between MUFG and Google in the Retail Sector, May 7, 2026, MUFG
2) Agent Development Kit (ADK)
3) Developer’s Guide to AI Agent Protocols, MARCH 18, 2026, Google


Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

"Root Cause Analysis" is All You Need !

Have you ever tried to automate any classification tasks using Generative AI? I do this quite often, but occasionally, as the number of classification classes increases, the accuracy gradually drops to a point where it is no longer viable for practical business use. So, this time, I will tackle the task of classifying bank customer complaints (1) based on their root causes. There are 20 cause classes in total, making it a difficult problem where a random guess would yield only about a 5% accuracy rate. In the example below, the "text" column contains the customer complaint, and the "Issue," which is the underlying cause, is classified by an AI agent.

              Bank Customer Complaints

We are provided with a mere 100 samples. I would like to implement Root Cause Analysis (RCA) during the classification process to see just how crucial RCA is for improving accuracy. Let's get started right away.


1. What is RCA?

RCA stands for "Root Cause Analysis". When a problem occurs, it is a method used not just to resolve the superficial events (symptoms) you see, but to pinpoint the "true cause (root cause)" in order to prevent a recurrence. This time, I have designed the following RCA approach for classification failures:

Root Cause Analysis (RCA):

  • Record the success/failure of each sample.

  • Verification: Calculate the accuracy and generate an error analysis report.

  • Failure Analysis: If a classification error occurs, scrutinize the principle and conduct a Root Cause Analysis (RCA) on why it failed (e.g., confusion with similar categories, context complexity, etc.).

  • Create a principle improvement report based on the failure analysis results. Send this feedback to the generator. Take care to ensure the generator does not overfit.

Now, as shown in the infographic below, let's actually take on the bank customer complaint classification task using an AI agent equipped with RCA capabilities.

               AI Agent with RCA Capabilities

Note that I referenced this paper (2) for this experiment. If you are interested, please definitely check it out.


2. Implementing the Bank Customer Complaint Classification AI Agent using Claude Code

Once again, I used Anthropic's Claude Code to implement and analyze the AI agent as follows. First, I set it to Plan Mode, compiled what I wanted to accomplish into a PRD (Product Requirements Document), handed it over to Claude Code, and formulated an implementation plan. This PRD incorporates the Root Cause Analysis (RCA) explained above.

              Claude Code's Plan Mode

An implementation plan like the one below is formulated in about 5 minutes. The actual document is much longer, but I will only show the first part here. The important thing is to thoroughly review this implementation plan. It is long and can be tedious, but this stage allows you to confirm whether it aligns with the task's objectives before actually diving into coding. Anthropic's generative AI, Opus 4.7, is extremely high-performing; once it enters the implementation phase, it runs non-stop until the end. Since it is difficult for humans to intervene midway, the accuracy of the implementation plan holds the key to solving the task.

               Implementation Plan via Plan Mode

Since this implementation plan was well-crafted, I will proceed directly to implementation. I switch to Auto Mode as shown below and start coding. You can see the AI agent completing the implementation process step by step.

              Implementation via Auto Mode

This time, we iterated on the analysis and improvement 9 times, which ultimately took over 10 hours, but we obtained the results below. This is the result of classifying 100 randomly sampled customer complaints into 20 classes. You can see that the accuracy gradually improves thanks to the RCA feedback.

               Accuracy at Each Iteration

However, it seems to have overfitted due to repeating the process for far too long. I validated it with newly sampled data, but saw no improvement from iteration 7 onwards.

                 Accuracy on New Data


3. Results and Challenges This Time

In this bank customer complaint classification task, the baseline accuracy using a generative AI "out of the box" without doing anything special was under 40%. By adopting a multi-agent system with a generator and an evaluator, and incorporating RCA feedback, we achieved just under 60% accuracy even on new data, so I believe the RCA was effective. However, once the accuracy on the original data exceeded 80%, overfitting occurred, so figuring out how to improve this is a future challenge.


What did you think? This time, I explicitly stated the RCA in the PRD, implemented it as a multi-agent system, and tackled the task of classifying bank customer complaints based on their causes. While the accuracy improved from 40% to about 60%, overfitting remained an issue. To aim for an accuracy of 70% or higher on new data, another breakthrough might be necessary.

At ToshiStats, we plan to further develop RCA. Please look forward to it. Stay tuned!


You can enjoy our video news ToshiStats AI Weekly Review from this link, too!

1) Consumer Complaint Database
2) CoEvoSkills: Self-Evolving Agent Skills via Co-Evolutionary Verification, Hanrong Zhang1∗ Shicheng Fan1∗ Henry Peng Zou1 Yankai Chen2,3
Zhenting Wang2
Jiayu Zhou4 Chengze Li1 Wei-Chieh Huang1 Yifei Yao5
Kening Zheng1 Xue (Steve) Liu2,3 Xiaoxiao Li6 Philip S. Yu1
1University of Illinois Chicago 2MBZUAI 3McGill University
4Columbia University 5Zhejiang University 6University of British Columbia, April 12 2026

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.

The Race for AI Supremacy: Will Google Come Out on Top?

The AI market is a battlefield where diverse players like OpenAI, Anthropic, NVIDIA, Alibaba, and Tencent are engaged in fierce competition. Today, I want to focus on Google and delve into whether they can truly seize hegemony in the AI market in the near future.


1. Google’s Secret Weapon: The 8th Generation TPU

Google recently announced its 8th generation TPU (1). The most significant feature of this generation is the separation into independent chips for training and inference. What particularly caught my attention is the remarkable improvement in inference speed. As highlighted in the red frame, the computation speed has increased approximately tenfold compared to the previous generation. While I found myself wondering, "Can it really get this much faster in just one year?", I am eager to try it out as soon as possible. It is expected to debut later this year.

                TPU Performance Comparison

With TPU inference becoming this fast, we might see the same generative AI models produce results significantly quicker when running on TPUs. Currently, among public clouds, only Google Cloud offers the TPU option, which is likely to further boost Google Cloud's competitive edge.


2. Massive Investment in Anthropic

Currently, the most popular frontier model in the AI market is Claude, developed by Anthropic. It is exceptionally strong, particularly in the B2B sector. Recently, Google reportedly committed to a massive investment in Anthropic (up to $40 billion, albeit with conditions) (2). From the perspective of frontier model development, Google and Anthropic are competitors. On the other hand, Anthropic is a major customer for Google Cloud.

Therefore, this massive investment holds significant strategic weight. If the likelihood of Claude’s training and inference being performed on TPUs increases, so does the potential for Google to generate revenue from it. This can be viewed as a form of risk diversification for Google. While it would be ideal if Google’s own frontier model, Gemini, maintained a dominant market share, rivals are constantly launching high-performance models. Practically speaking, it is a rational risk-hedging strategy to have even competing models run on TPUs—thereby collecting Google Cloud usage fees—or to aim for capital gains through equity stakes in those invested companies. In any case, we must keep a close eye on the collaboration between Google and Anthropic.


3. Google DeepMind’s Technical Prowess and Google’s Product Ecosystem

One cannot discuss Google’s AI without mentioning Gemini. Developed by Google DeepMind, this frontier model is natively multimodal and has made headlines for its high performance with every new release. The current model is Gemini 3, and there is anticipation that a next-generation model might be announced at Google I/O, the annual event starting on May 19, 2026. It’s very exciting.

However, Gemini is not the only generative AI from Google DeepMind. Boasting one of the most diverse arrays of models among all AI labs, their portfolio includes image and video generation models, as well as world models like Genie 3 (3).

Furthermore, Google possesses a vast amount of data required for model generation. Google already operates various products globally, and the data harvested from them is immense—YouTube alone is a clear example. Compared to many AI labs that must build their user bases from scratch, Google has an overwhelming advantage. The combination of "Google DeepMind’s technical prowess + data obtained from various products" is unparalleled.


What do you think? Today, we took a deep dive into Google. With powerful technology spanning not just AI model development but various other fields, Google’s strength feels overwhelming. They will likely continue to lead the AI market. Conversely, they are so strong that one might even worry about when they might run afoul of antitrust laws. What are your thoughts?

ToshiStats will continue to cover Google in the future. Stay tuned!


You can enjoy our video news ToshiStats AI Weekly Review from this link, too!

1) Our eighth generation TPUs: two chips for the agentic era, Google, Apr 23, 2026
2) Google to invest up to $40B in Anthropic in cash and compute, TechCrunch, April 24, 2026
3) Genie 3: A new frontier for world models, Google, August 5, 2025


Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.


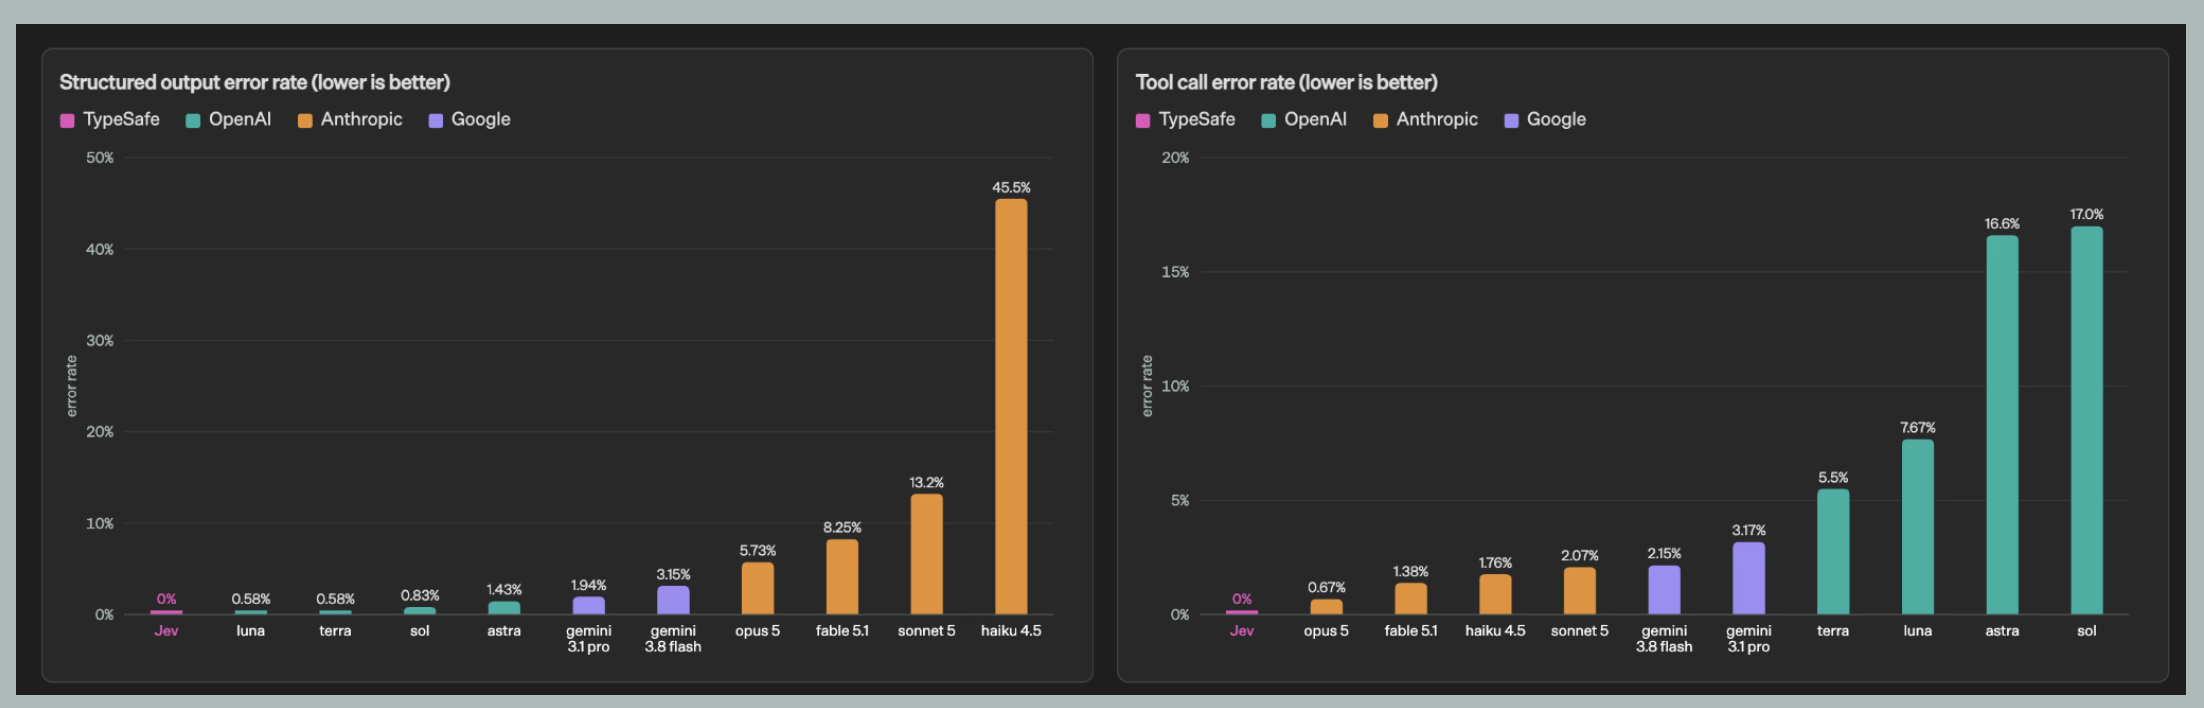
Opus 4.7’s Auto Mode: The Secret Weapon for Boosting Productivity

Anthropic has released the frontier generative AI model, Opus 4.7. This update comes just over two months after the release of Opus 4.6, highlighting the accelerating pace of technological progress. In this article, I will dive deep into the remarkable new feature added alongside Opus 4.7, "Auto Mode," by utilizing it to build a machine learning model for credit default prediction.


1. What is Auto Mode?

Boris Cherney, the developer of Claude Code—an Agentic coding development environment—commented on "Auto Mode" as follows:

Auto mode = no more permission prompts

In the past, you either had to babysit the model while it did these sorts of long tasks, our use--dangerously-skip-permissions.We recently rolled out auto mode as a safer alternative. In this mode, permission prompts are routed to a model-based classifier to decide whether the command is safe to run. If it'ssafe, it's auto-approved.

In short, this feature reduces the frequency of "Please approve" requests that appear during long agentic coding sessions, thereby boosting productivity. For someone like me, who handles dozens of these approval requests daily, this is a very welcome addition.

You can verify the "Auto Mode" status via the indicator at the bottom left of the Claude Code interface.

Auto Mode

When you first enable it, a notice will appear; I recommend giving it a thorough read.

notice of Auto Mode


2. Building a Default Prediction Model with Auto Mode

I used Claude Code’s "Auto Mode" to actually build a default prediction model. For this project, I used data from Home Credit Default Risk competition(2) at Kaggle .

First, I created an implementation plan using Plan Mode. Through dialogue with Claude Code, a structured plan was established.

                  Implementation Plan

At this stage, Claude Code asks, "Would you like to use Auto Mode?" and answering "Yes" initiates the process.

                   Approval Request

The Implementation Process: I watched to see how many approval requests would appear before completion.

                Implementation using Auto Mode

After approximately 90 minutes, the system announced, "Finished." Remarkably, not a single approval request was triggered. This makes the work significantly easier and the implementation process much more enjoyable.

                   Completion Notice

Accuracy Validation: I checked the evaluation metric on Kaggle. The result was an AUC = 0.79632. This is my personal best for a single model without using ensembles. It ranks within the top 4.2% of the competition. Achieving this score without any manual intervention after the initial planning phase is truly astonishing.

                 Evaluation Metric


3. Auto Mode and Productivity in Data Analysis

While Auto Mode makes implementation effortless, its true power lies elsewhere. Because the frequency of approval requests has decreased so dramatically, it is now feasible to work with parallel computing—building multiple models simultaneously.
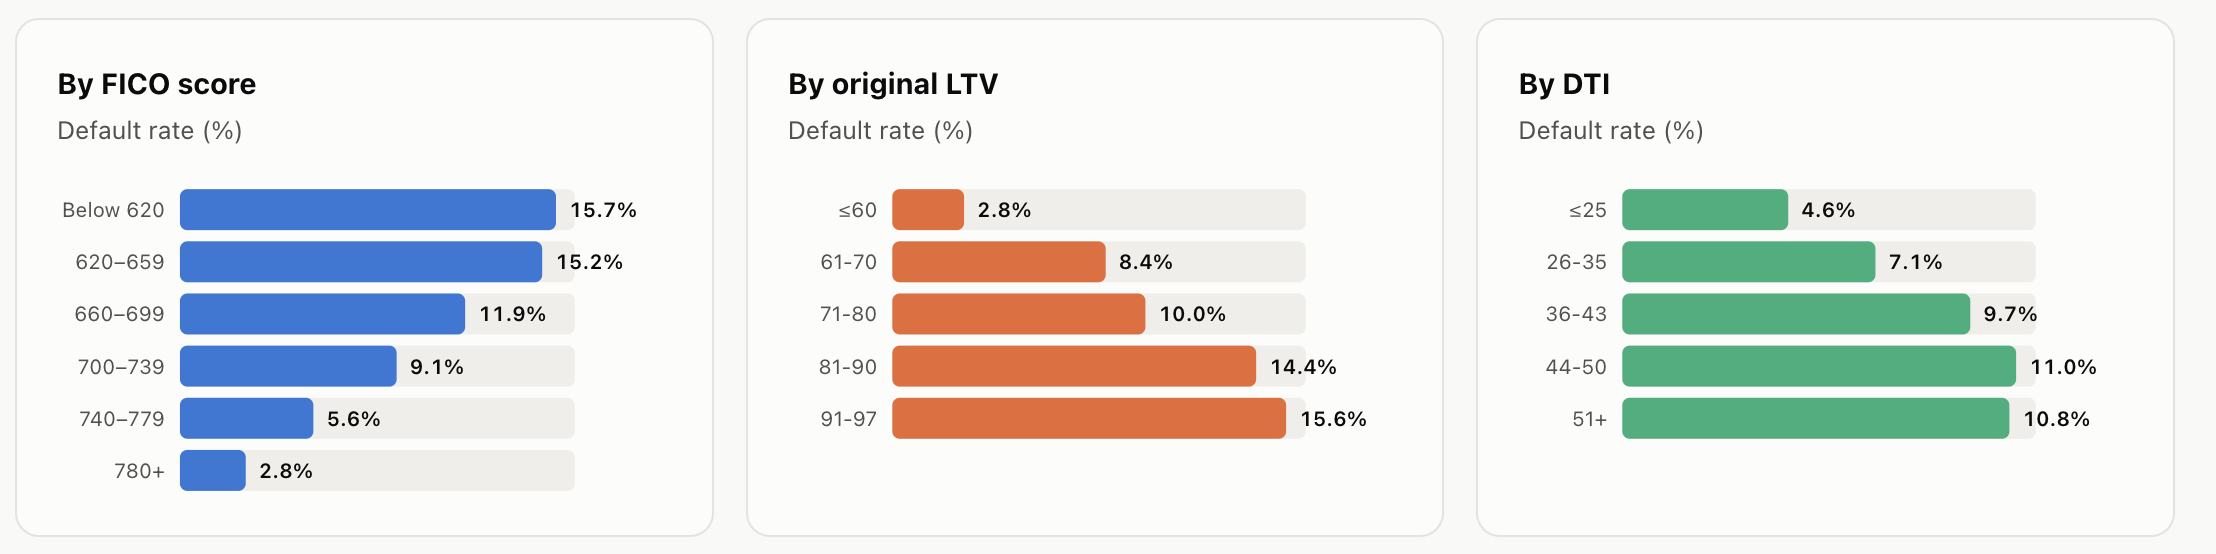
Whether in Kaggle competitions or practical business scenarios, we are often required to improve accuracy within a limited timeframe. If parallel computing becomes this easy, increasing productivity by 5x to 10x is no longer just a dream. It is a challenge well worth taking.
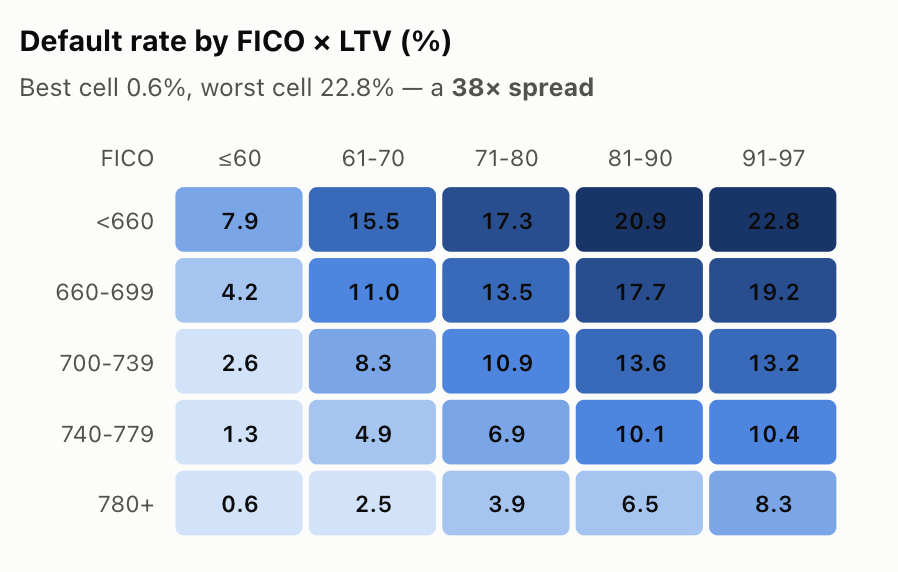
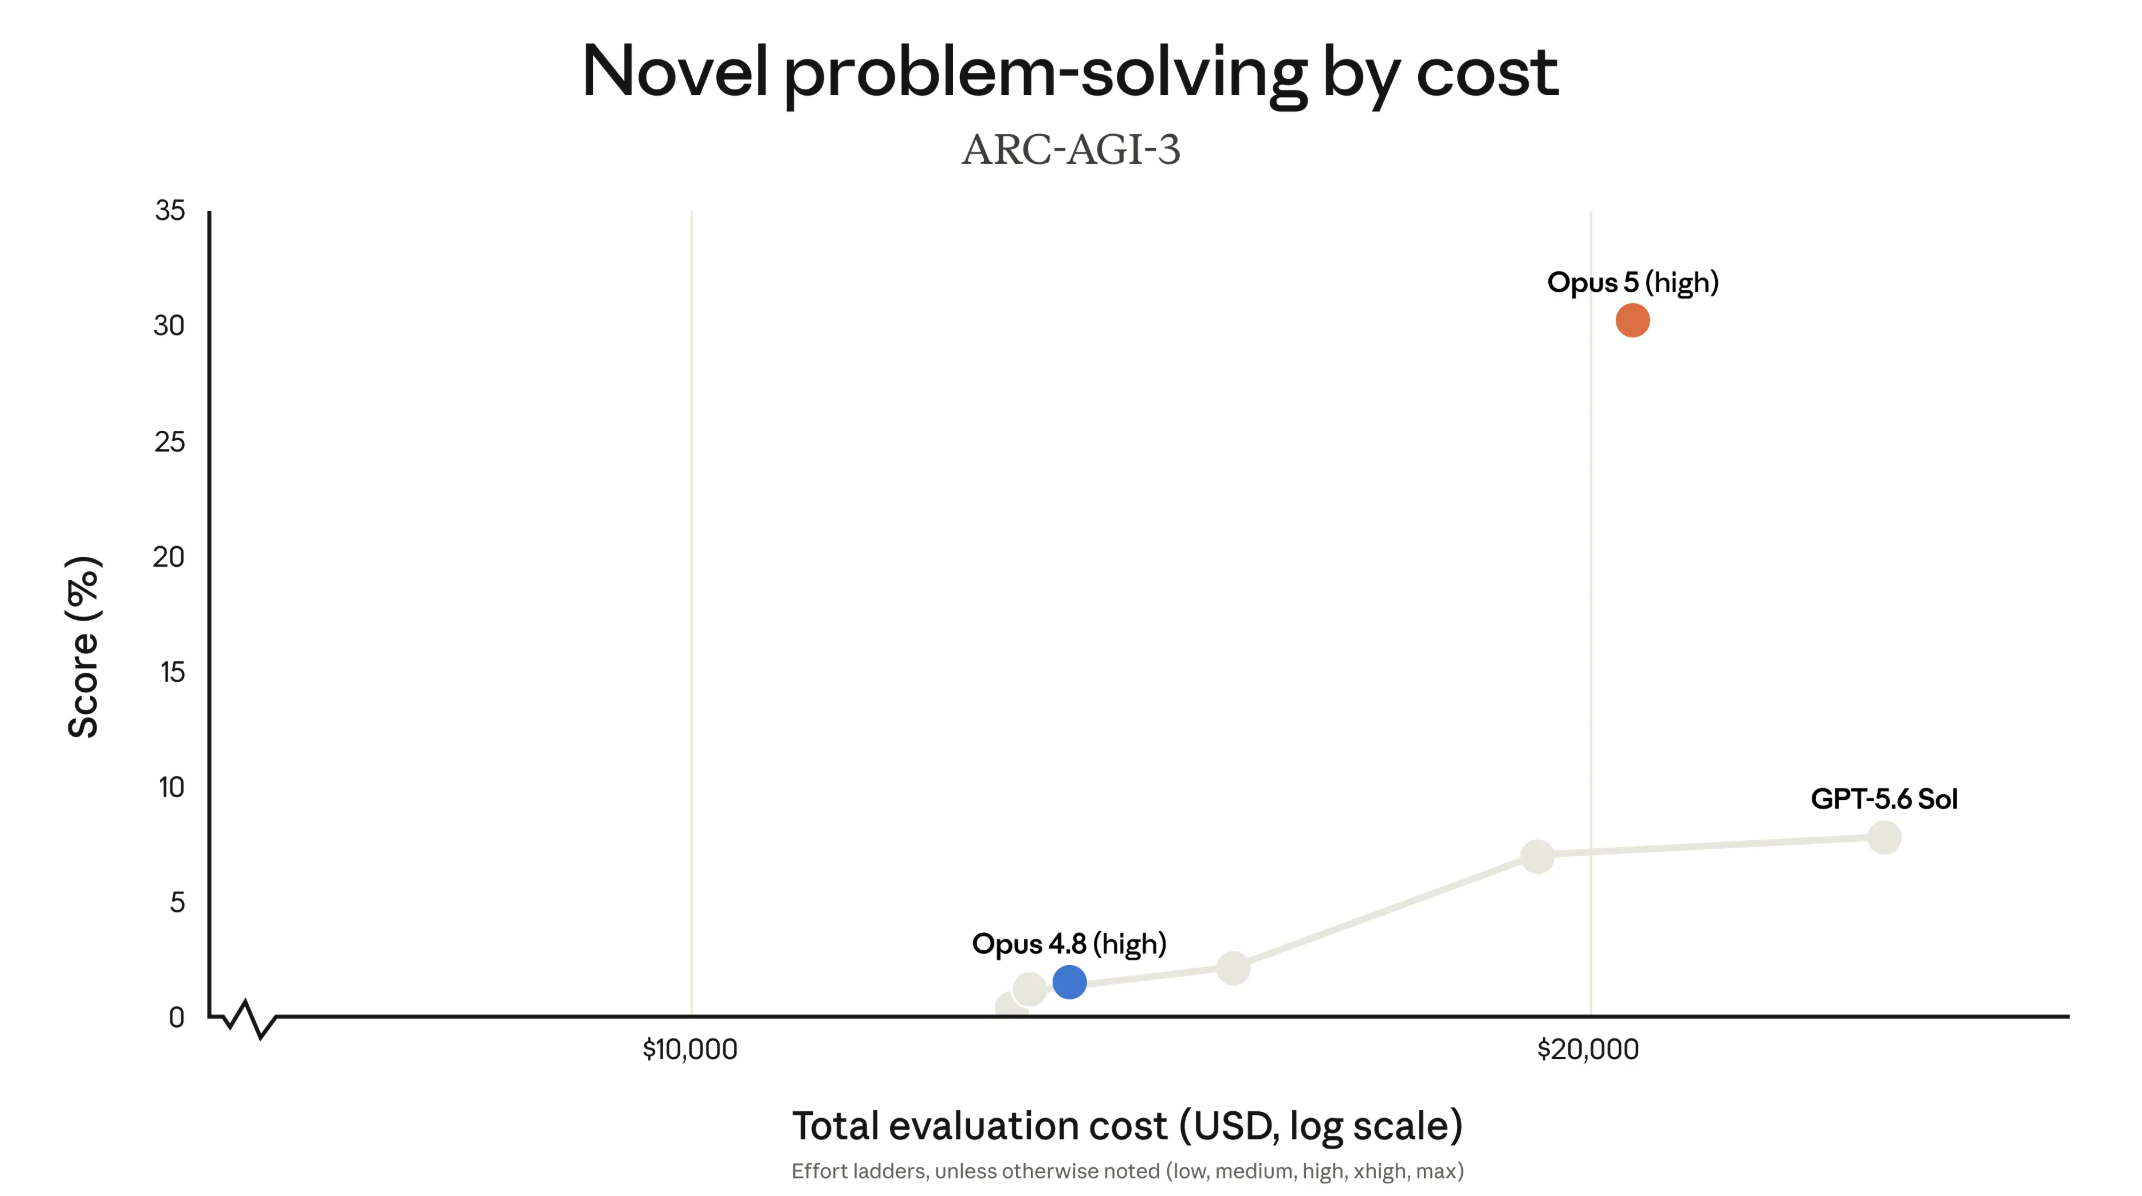
 

Conclusion

Auto Mode has simplified parallel computing and opened a new path toward enhanced productivity. At ToshiStats, we will continue to explore case studies using Auto Mode.
Stay tuned!


You can enjoy our video news ToshiStats AI Weekly Review from this link, too!

1) https://x.com/bcherny/status/2044847848035156457, Boris Cherney, Anthropic
2) Home Credit Default Risk, kaggle


Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.