AI agent

Open-Jev: A Zero-Cost Game Changer for AI-Driven Automation?

Inspired by "Jev" (1), an AI model specialized in decision-making, a number of downloadable open-weight Jev models—which I will refer to here as Open-Jev—have been emerging. Today, I will pick five Open-Jev models and compare them with the original Jev to examine their characteristics. Since open-weight models can be downloaded and run on your local PC, there is zero cost compared to using Jev via an API, and all data remains entirely on your local PC. Consequently, they can be used even in environments with strict security requirements, making them extremely convenient. Without further ado, let's get started.


1.What is Open-Jev?

AI models specialized in tasks that answer through intuitive judgment are sometimes called "System one" models. Jev, which debuted on September 15, 2026, is a prime example of such a model. Since then, several open-weight models with capabilities similar to Jev have emerged. While their architectures are not necessarily similar to Jev's, I refer to these open-weight System 1 models as Open-Jev and plan to use them going forward. For this experiment, I have lined up five Open-Jev models available on Ollama (2), as shown below.
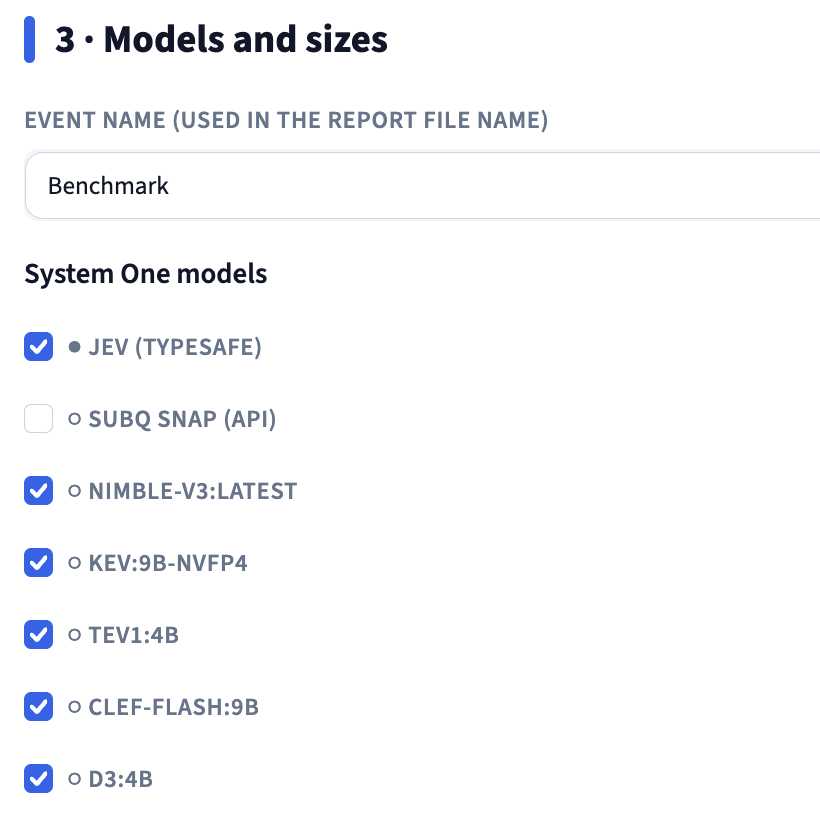
Let's immediately test how close these five Open-Jev models can get to the original Jev in terms of accuracy and computation speed.


2.Experimenting with Bank Complaint Analysis

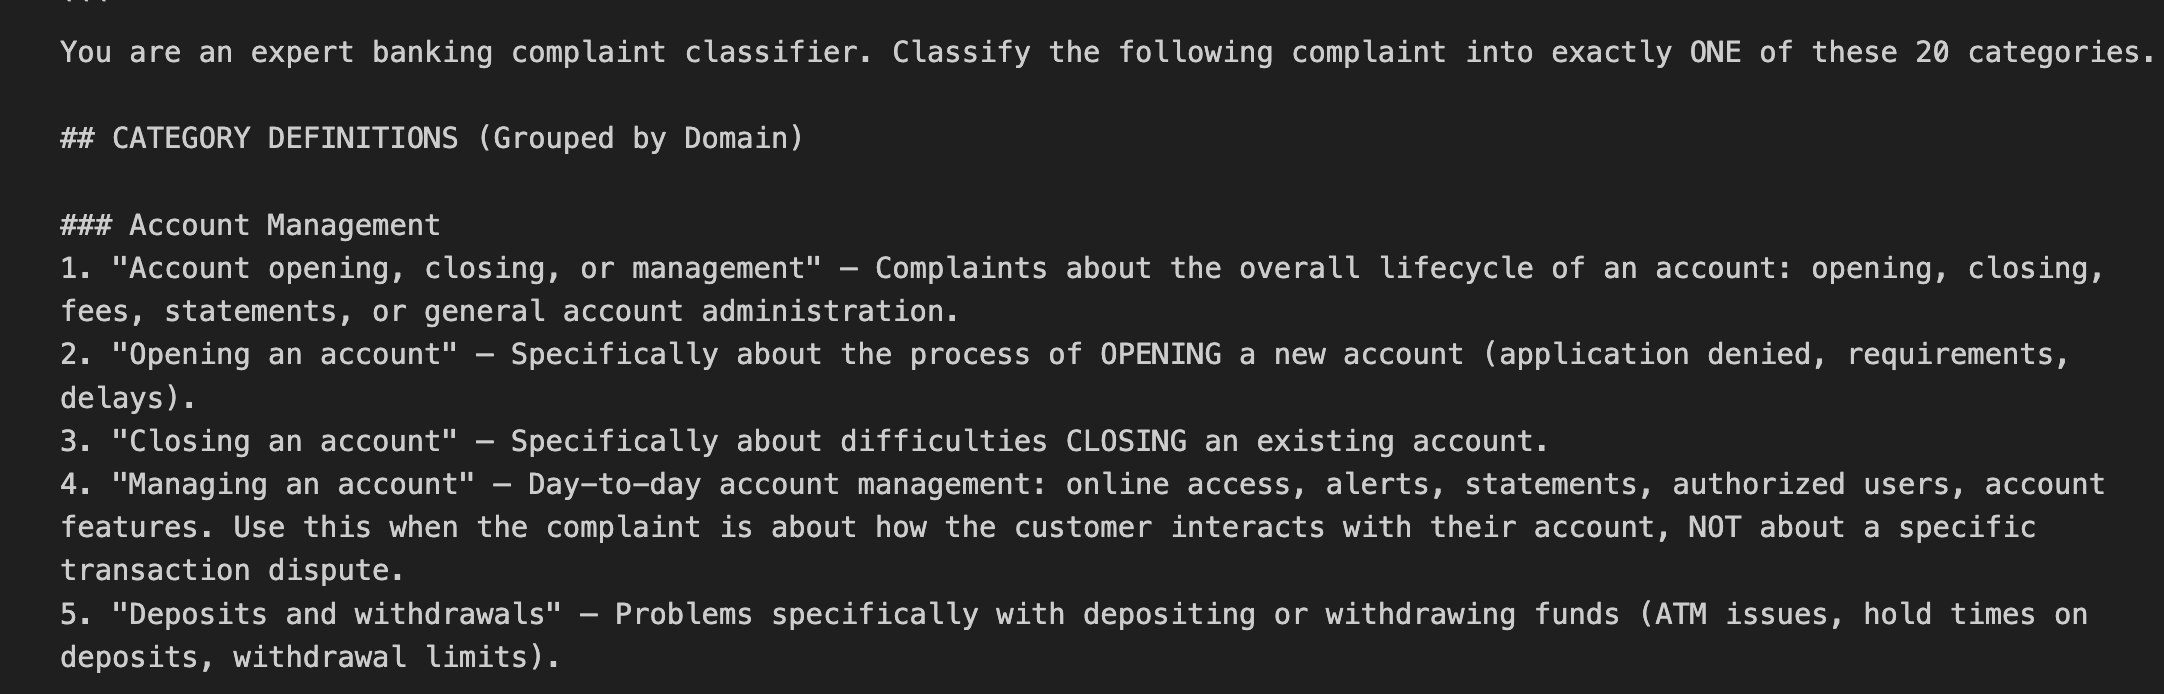
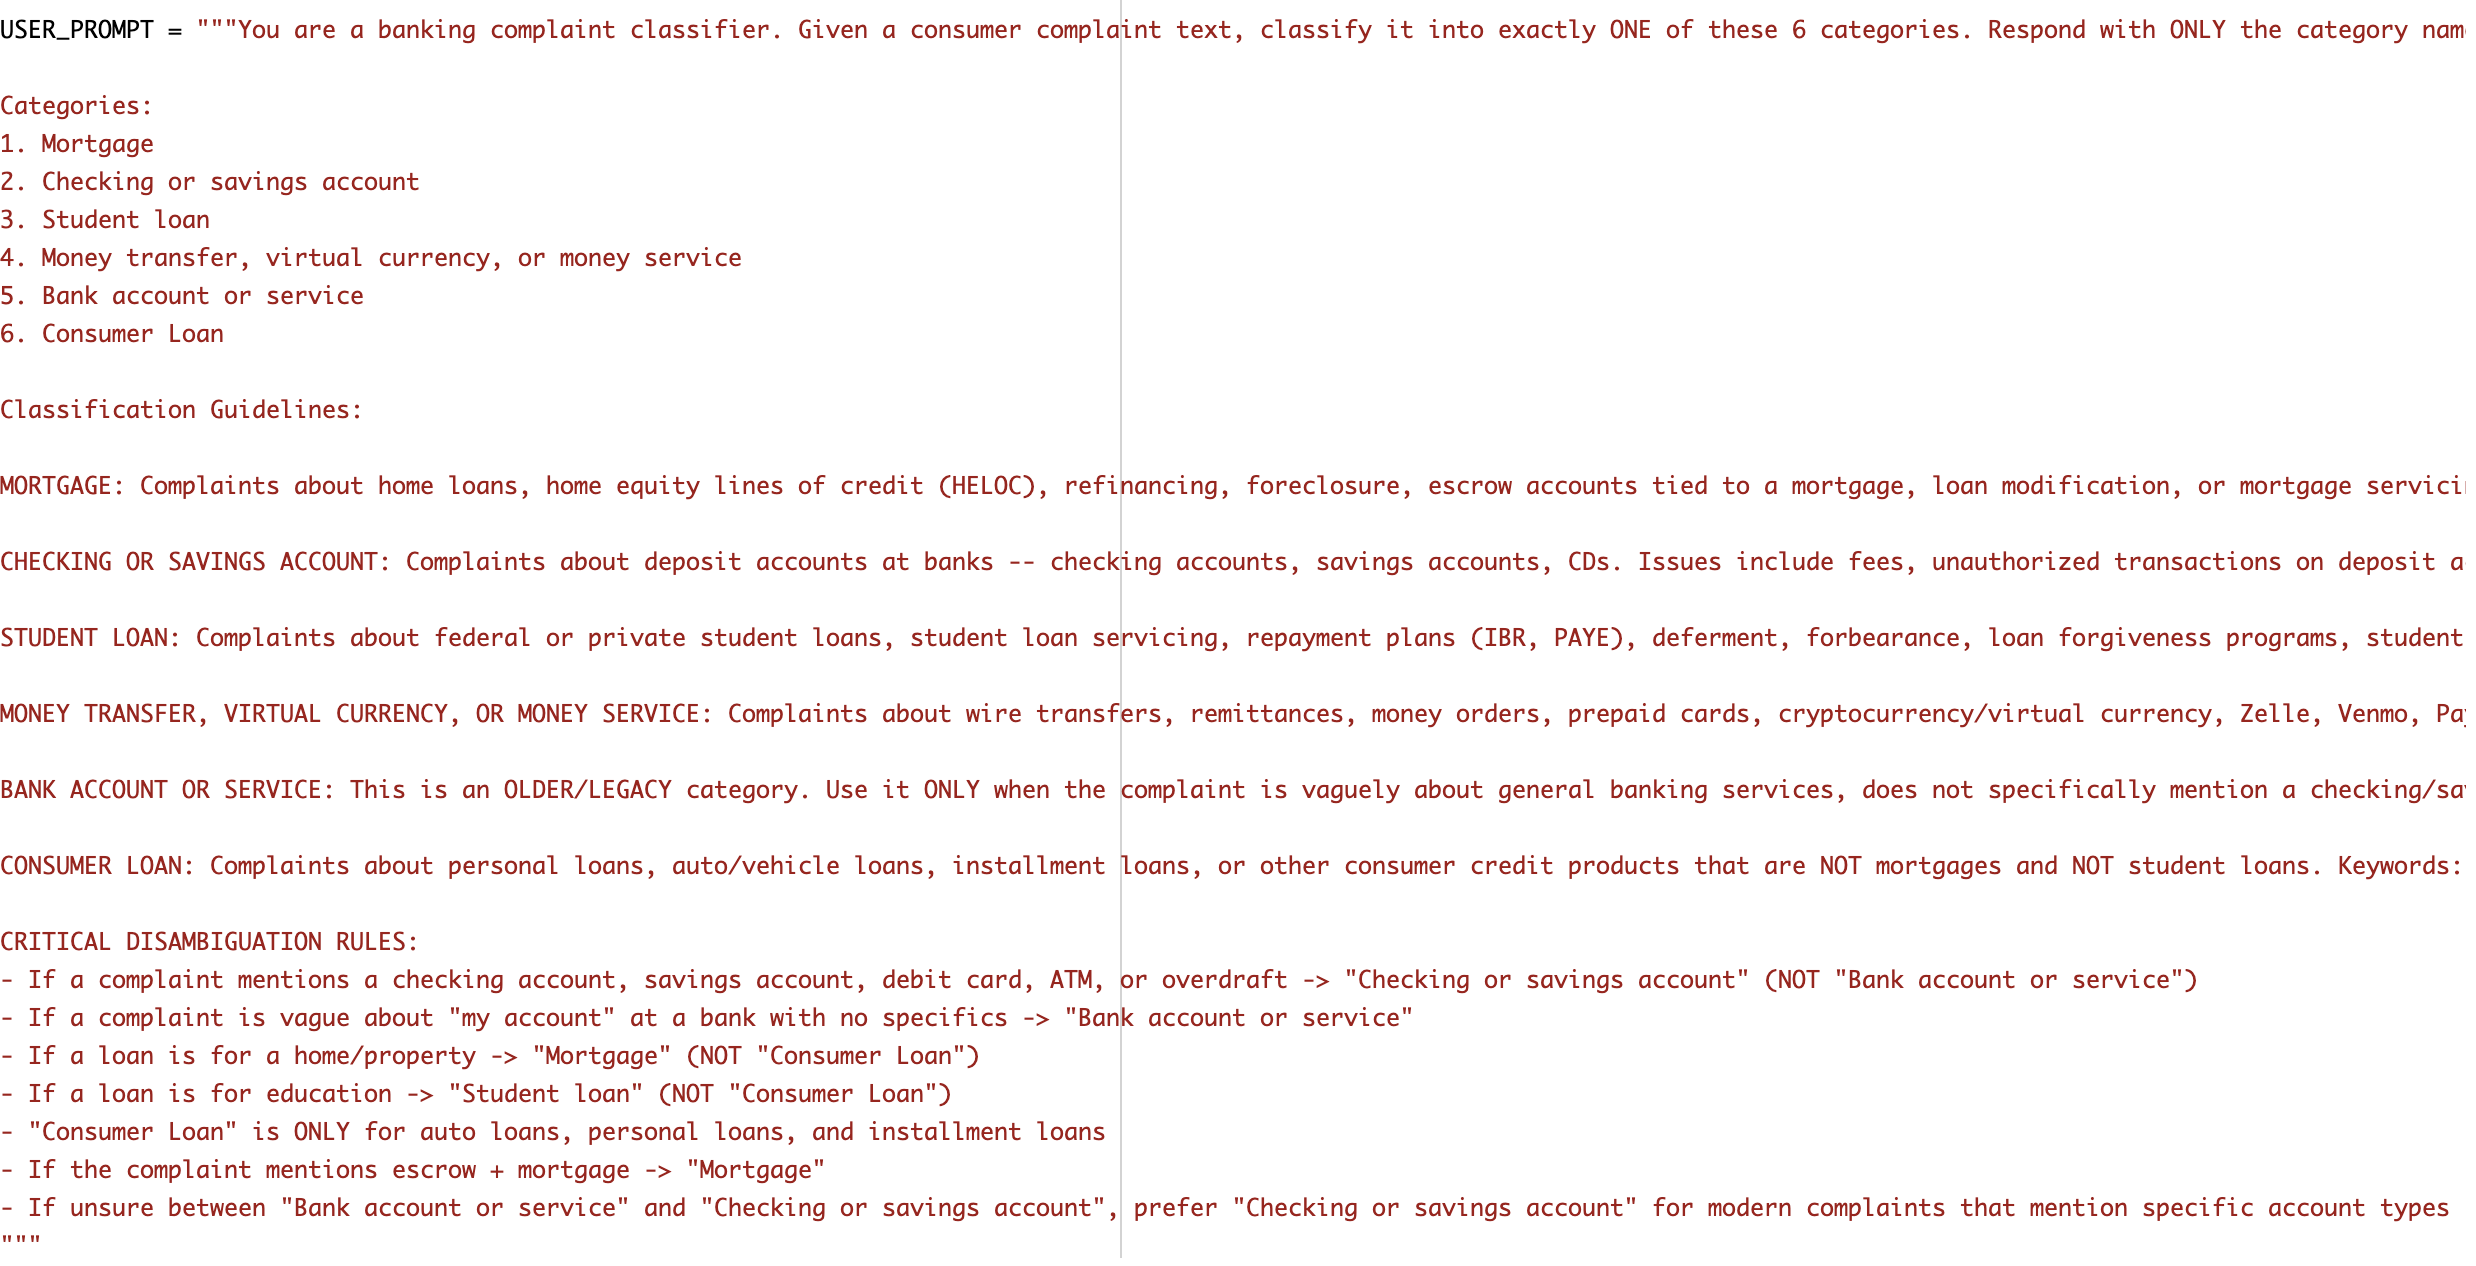
The task we are tackling this time is an experiment analyzing 100 samples of customer complaints submitted to a bank to determine which financial product each individual complaint pertains to (3). Although I have conducted this experiment before, this is my first time trying it with Open-Jev models. Because it is a task that can be answered intuitively, I believe it is well-suited for Open-Jev, which are System one models. The actual prompt used is shown below. Since the complaints are written in English, the prompt is also in English. This prompt was automatically generated by a Large Language Model (LLM) after reading the sample data to match its content.
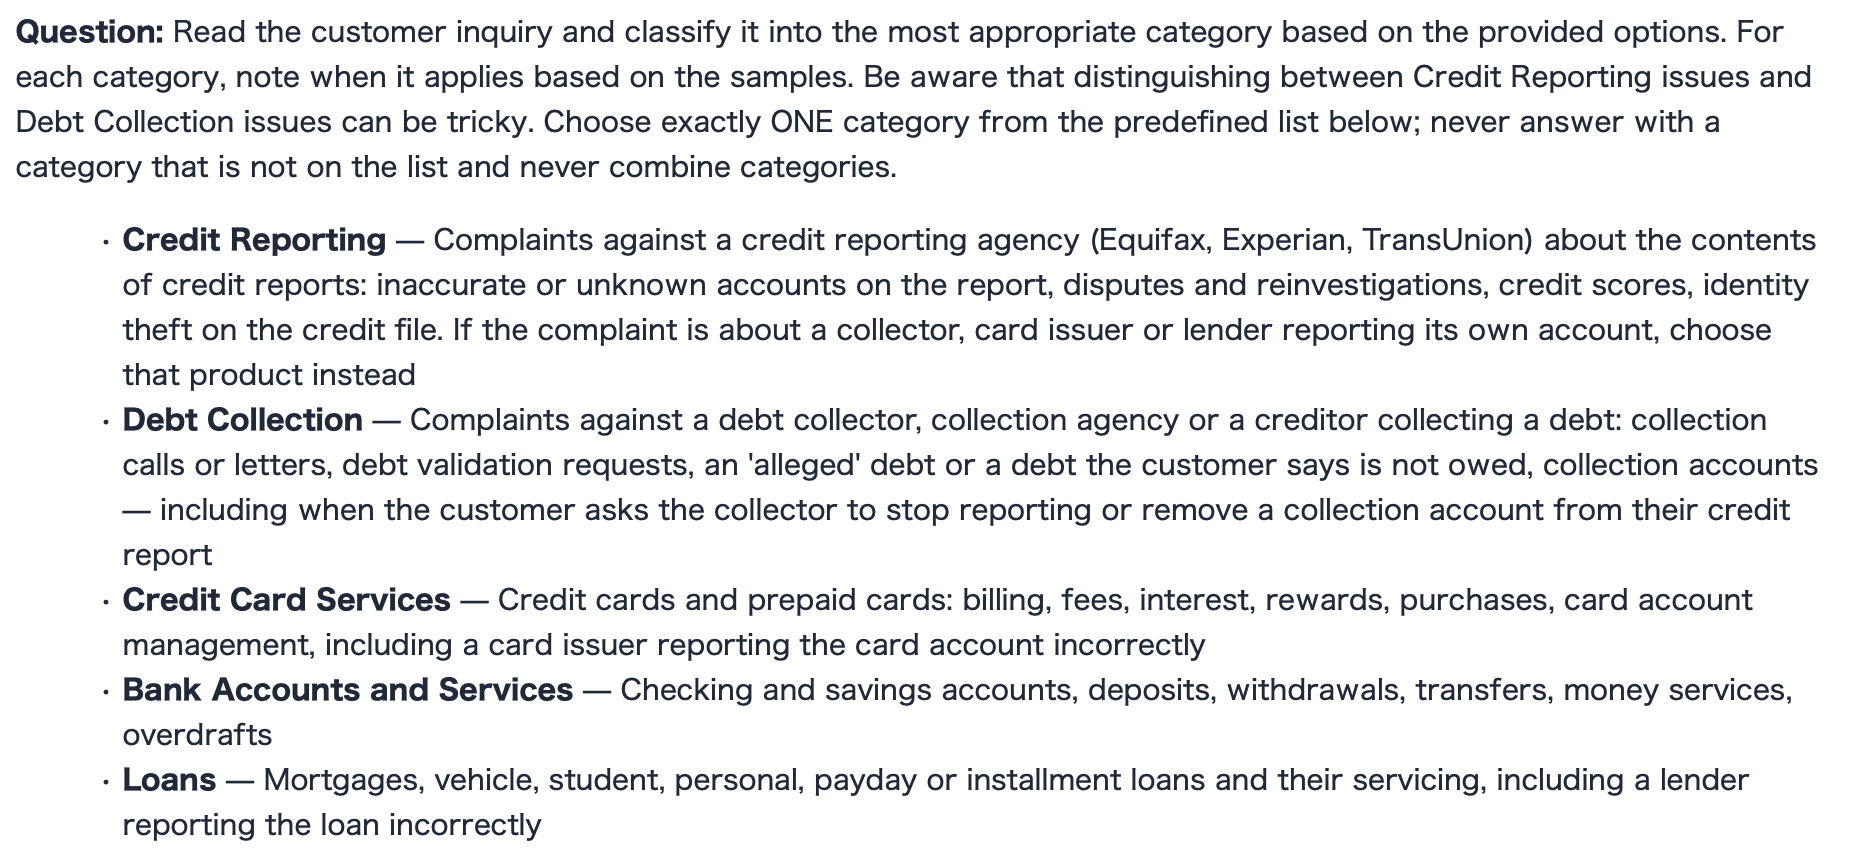
Prompt

The 100 customer complaint samples used this time contain an equal distribution of the five financial products mentioned above. Let's see how well Open-Jev can identify which of the five financial products each customer complaint is directed at.


3.Accuracy, Computation Speed, and Confidence Score

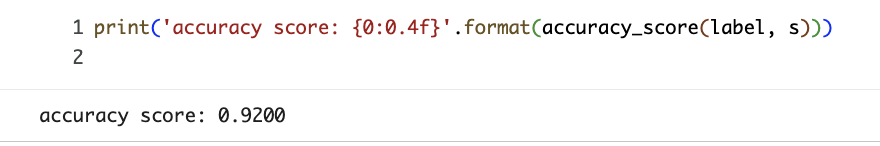
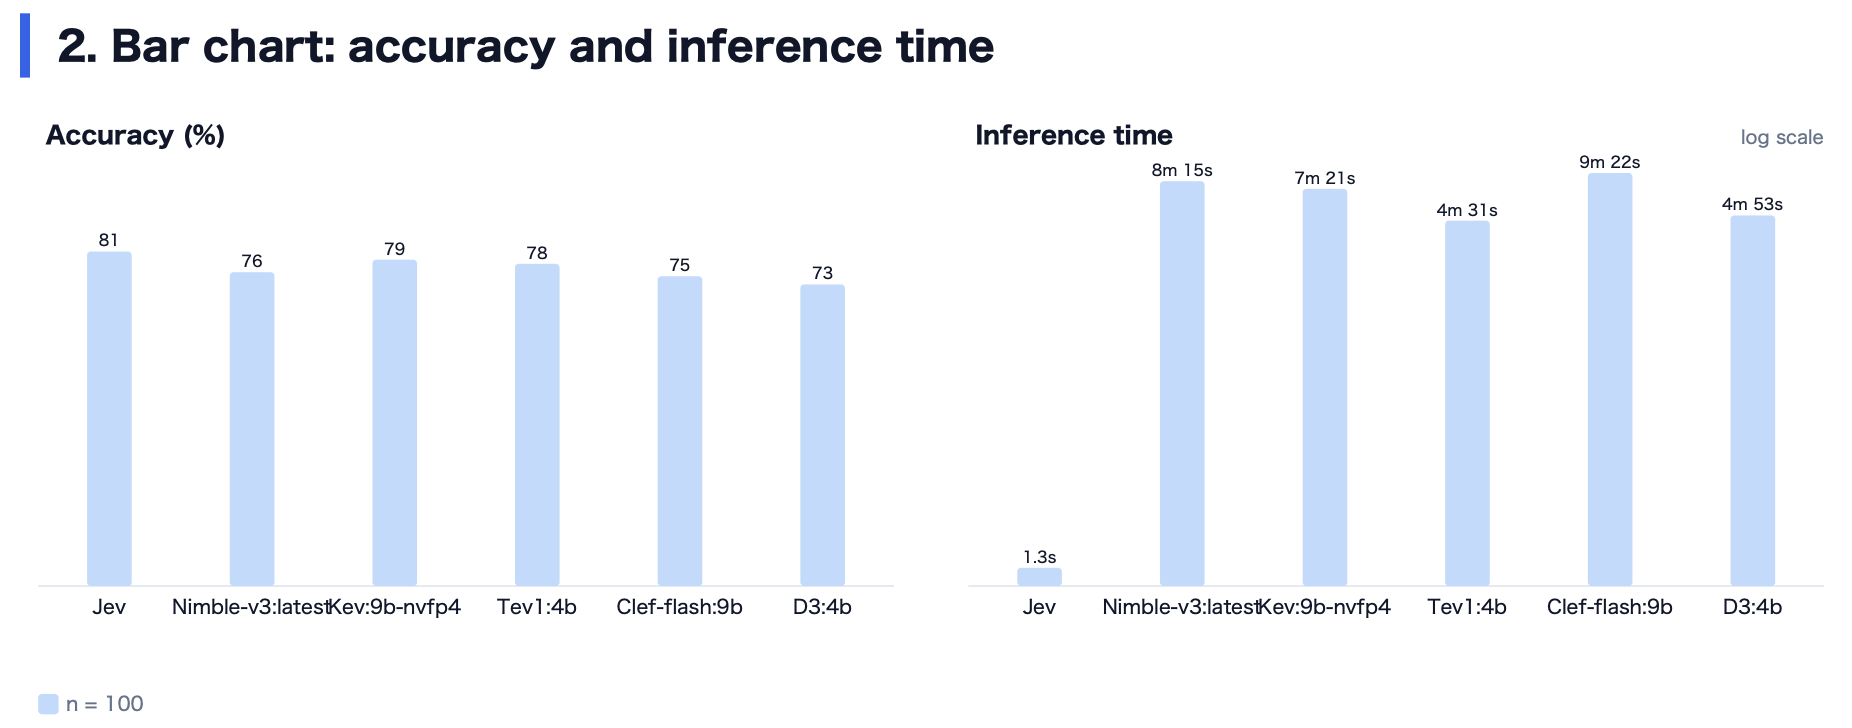
Now let's look at the experimental results. First, regarding accuracy, Jev took the top spot with 81% accuracy. That is to be expected from the original model. Most of the other Open-Jev models achieved accuracy in the high 70% range. I think they put up a very good fight. However, in terms of computation speed, while Jev took about one-hundredth of a second per sample, even the fastest Open-Jev model, Tev1:4B, took 2.7 seconds, requiring significantly more time. Here, the original Jev won by a landslide. That said, Open-Jev runs on a local PC, and this computation speed depends on the hardware used for this experiment—a MacBook Air M4 with 24GB of RAM. Naturally, as hardware performance improves, the speed will also increase, so that point needs to be taken into account.
For System one models, accuracy is not the only thing that matters. How confidently a decision is output—referred to as the "confidence score" or "reliability"—is crucial when advancing AI-driven workflow automation. Here, I will benchmark against Jev to see what characteristics each Open-Jev model possesses.
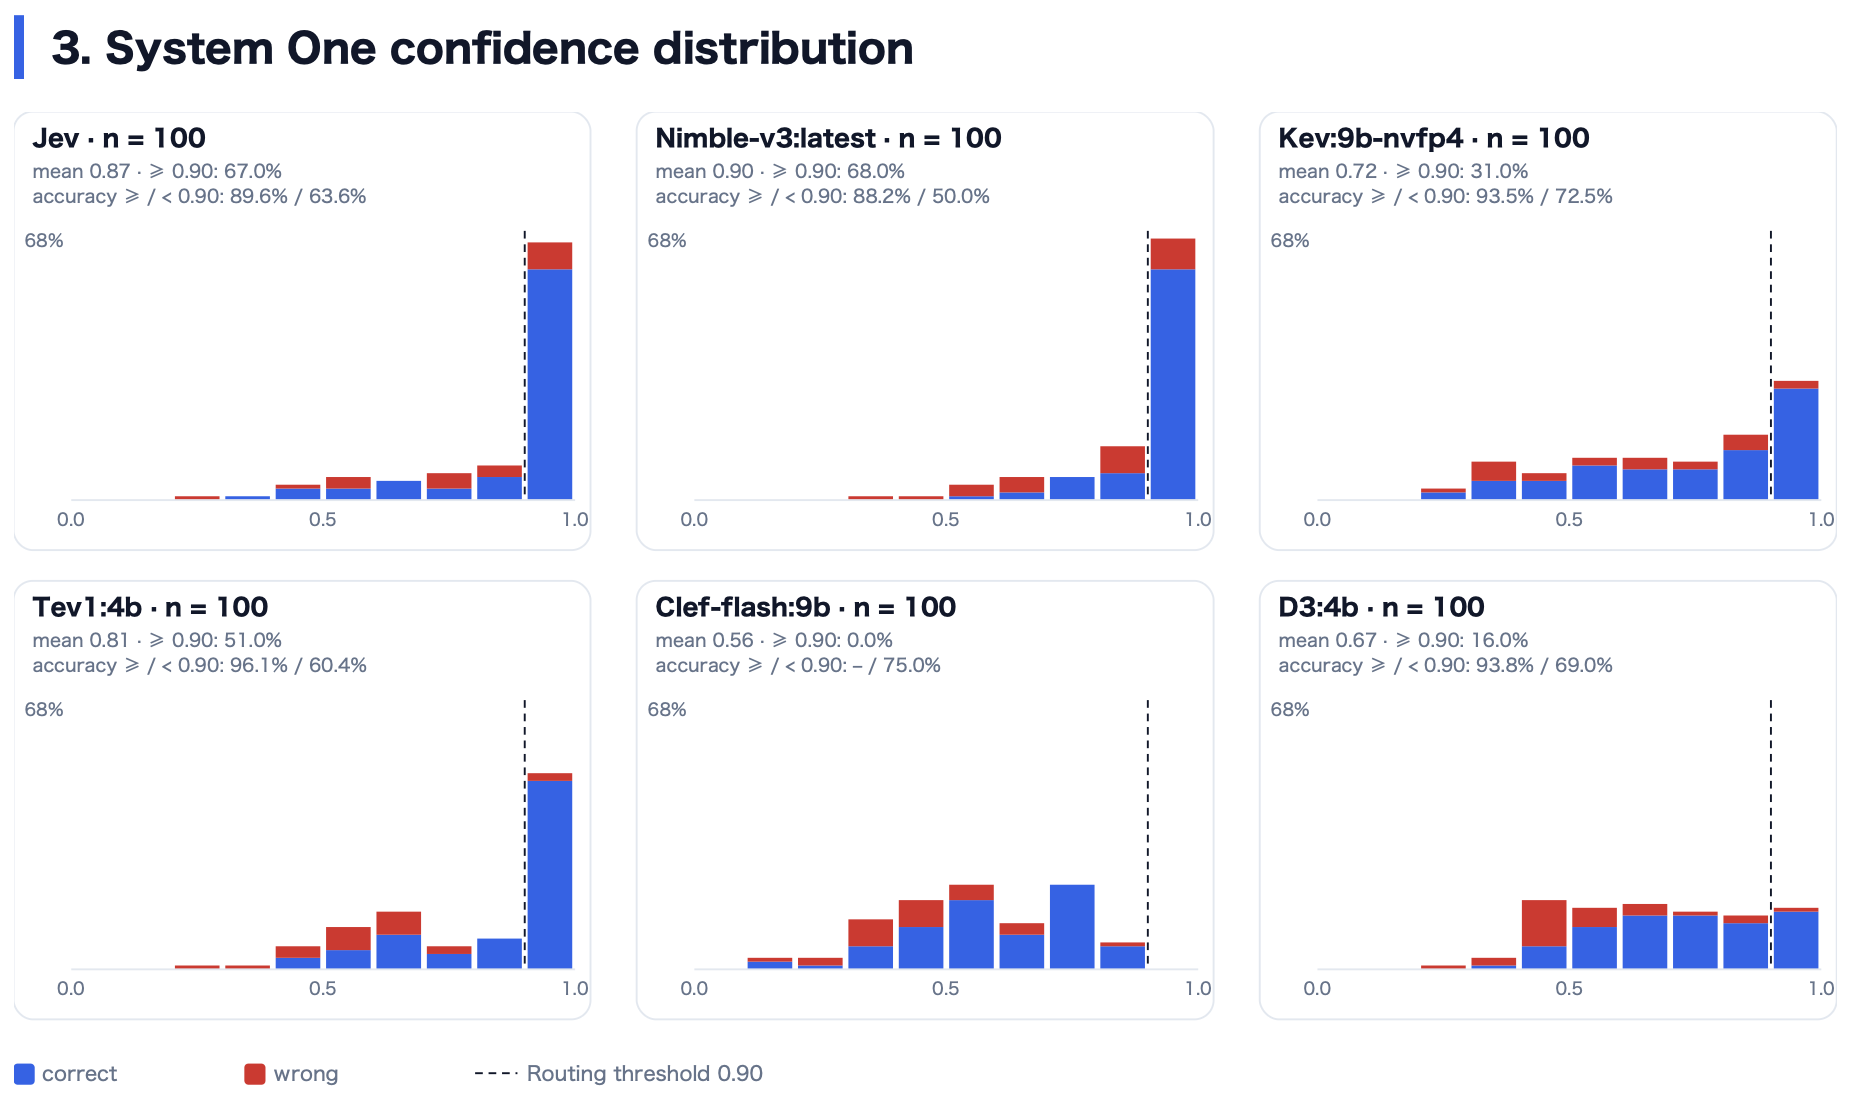
First, let's look at the confidence distribution of Jev in the upper left. The horizontal axis of the graph represents the confidence score, with each sample assigned a value between 0.0 and 1.0. There is a tall bar on the right side of the graph, which represents the distribution of samples with a confidence score of 0.9 or higher. This bar contains 67% of the total samples, meaning that if a threshold is set at a confidence score of 0.9, more than two-thirds of the samples will fall into this category. Blue indicates correct answers, while red indicates errors. Since the rightmost bar is not entirely blue, the accuracy is not 100%, but there is no doubt that it boasts high accuracy. It can be inferred that at a confidence threshold of 0.9, Jev clearly distinguishes between confident decisions and uncertain ones.

The models with confidence distributions similar to Jev are Nimble-v3:latest and Tev1:4b. Both include over 50% of the samples at the 0.9 confidence threshold, and the accuracy of those samples is also high. The other Open-Jev models have flatter confidence distributions, suggesting they are unable to effectively separate confident decisions at a confidence level of 0.9 or above. Therefore, to advance AI-driven automation, choosing either Nimble-v3:latest or Tev1:4b would be ideal. Please see here for more detailed experimental results.
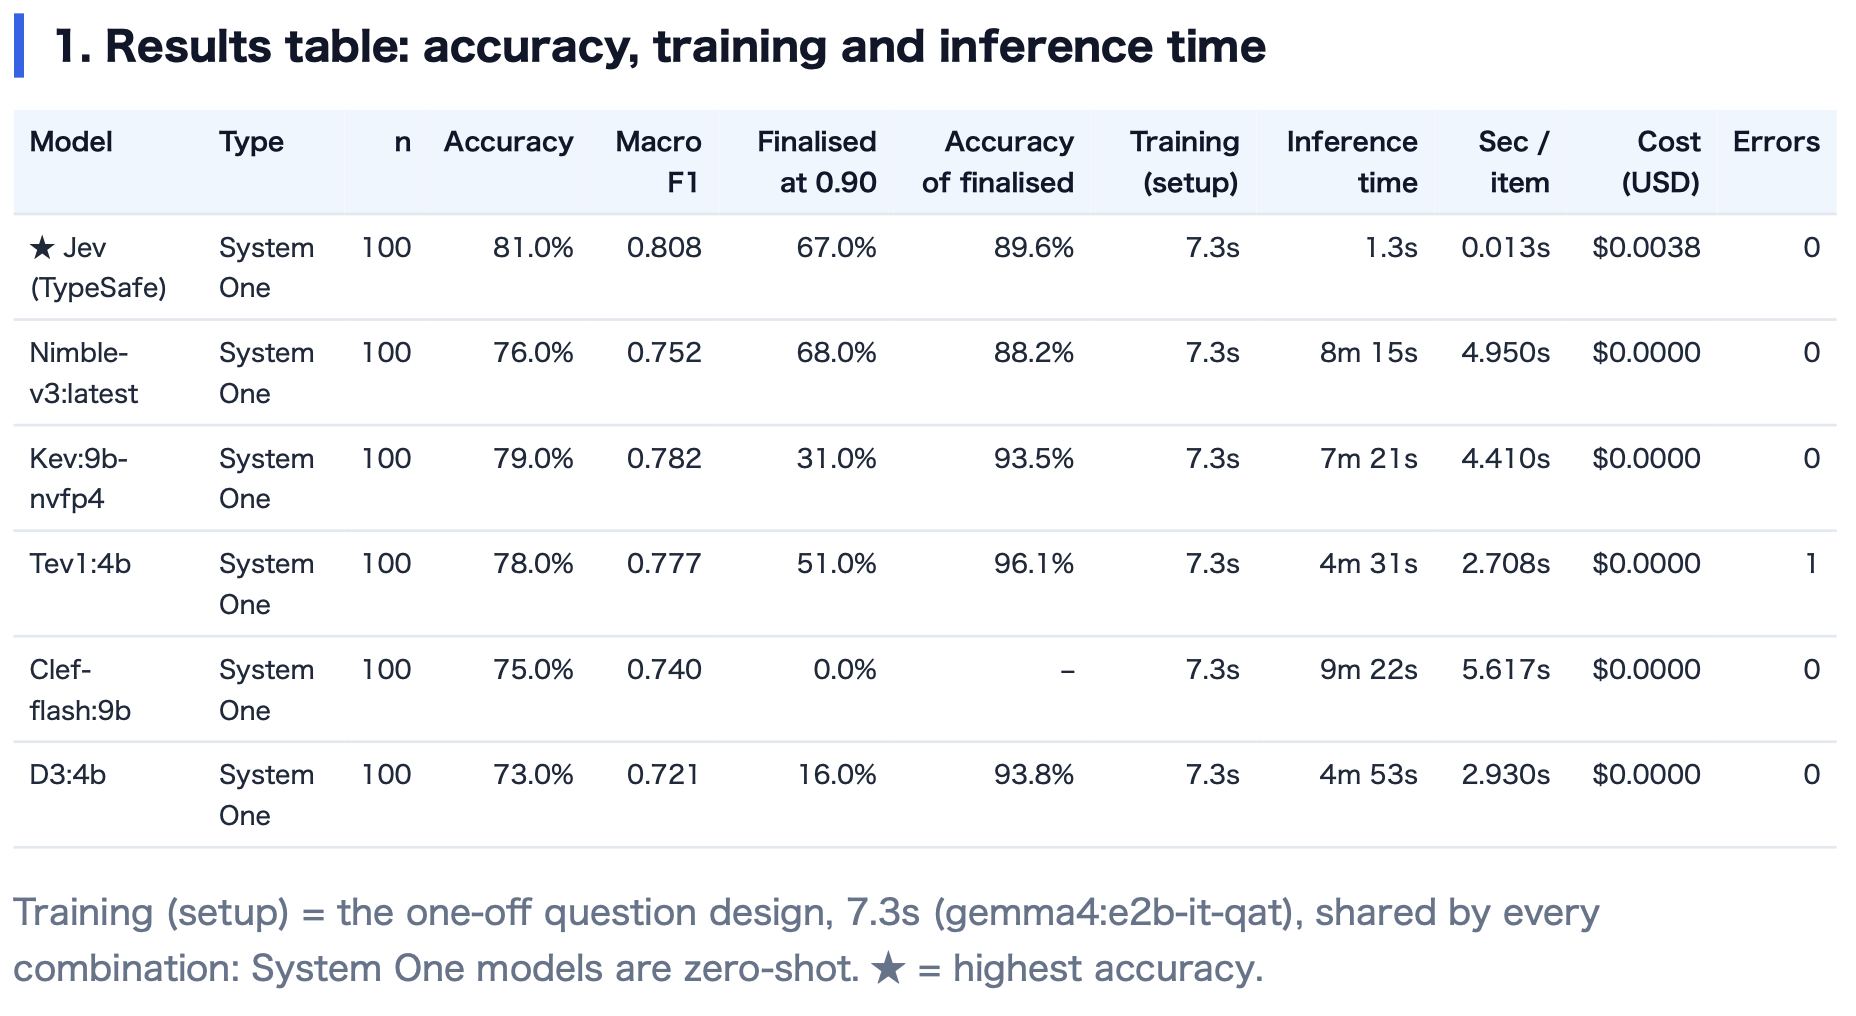
 

What did you think? I believe Open-Jev demonstrated performance comparable to the original Jev. Currently, since Jev can only be used via an API, there are likely many cases where it cannot be used in environments with strict security requirements. In such situations, considering Open-Jev is well worth it. The fact that it incurs no cost is another advantage. To increase computation speed, however, it will likely be necessary to prepare a high-powered GPU.


The development of Open-Jev has only just begun. As high-performance models are expected to emerge one after another in the future, we at Toshi Stats intend to actively adopt Open-Jev as well. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link.


1) Introducing System One Models & Jev, Sep 15 2026, Diogo Almeida, founder, TypeSafe
2) Ollama now supports Jev-style decision models, Sep 29, 2026
3) Consumer Financial Protection Bureau

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Building Resilient Automation: How to Combine LLMs and Jev for Production-Grade Workflows   

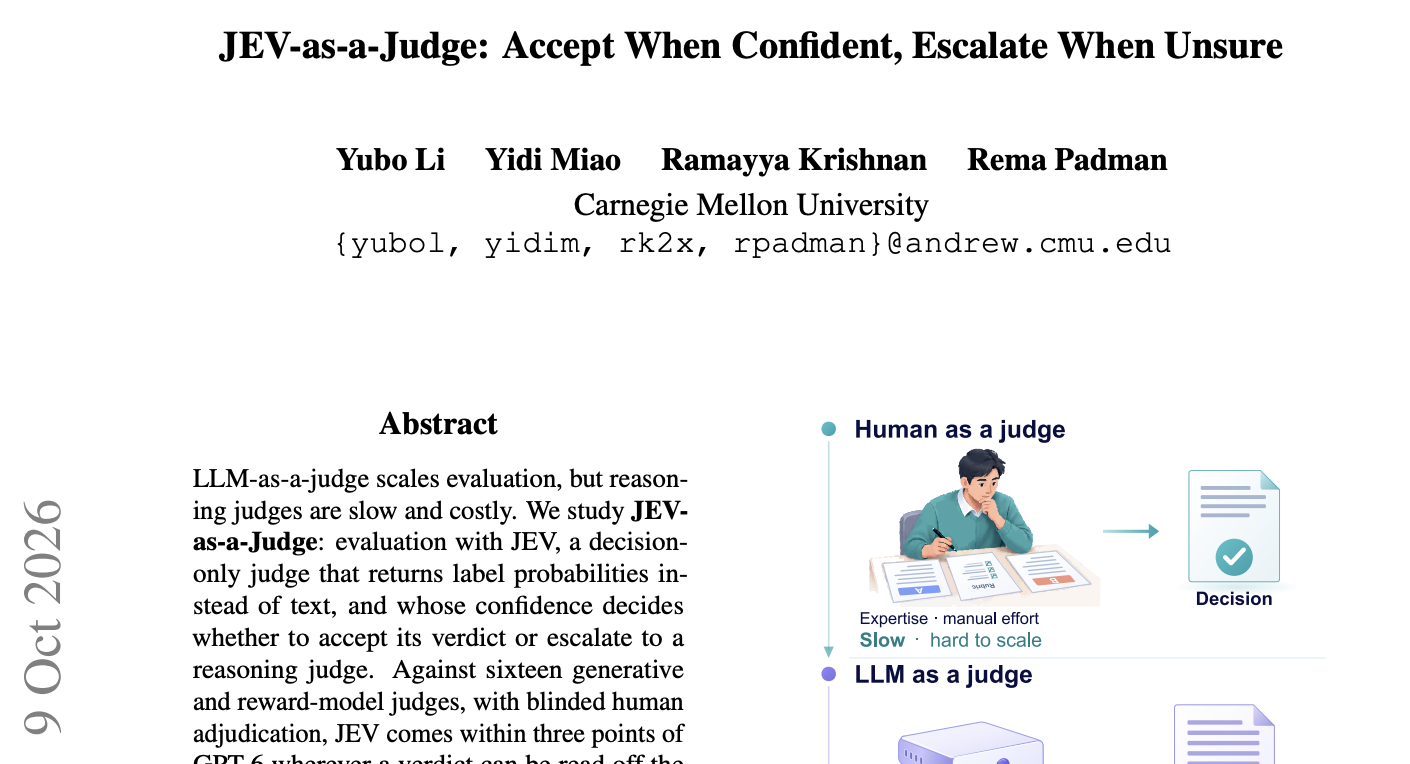
Nearly a month has passed since the new type of AI, "Jev," was announced on September 15, 2026 (1). Since then, various companies have introduced similar AIs, and momentum around this Jev-like-AI category has been growing rapidly. Therefore, in this article, we would like to unpack the wonderful research paper below (2) and explore ways to achieve automation by mastering this AI called Jev.


1. Humans, LLMs, and Jev

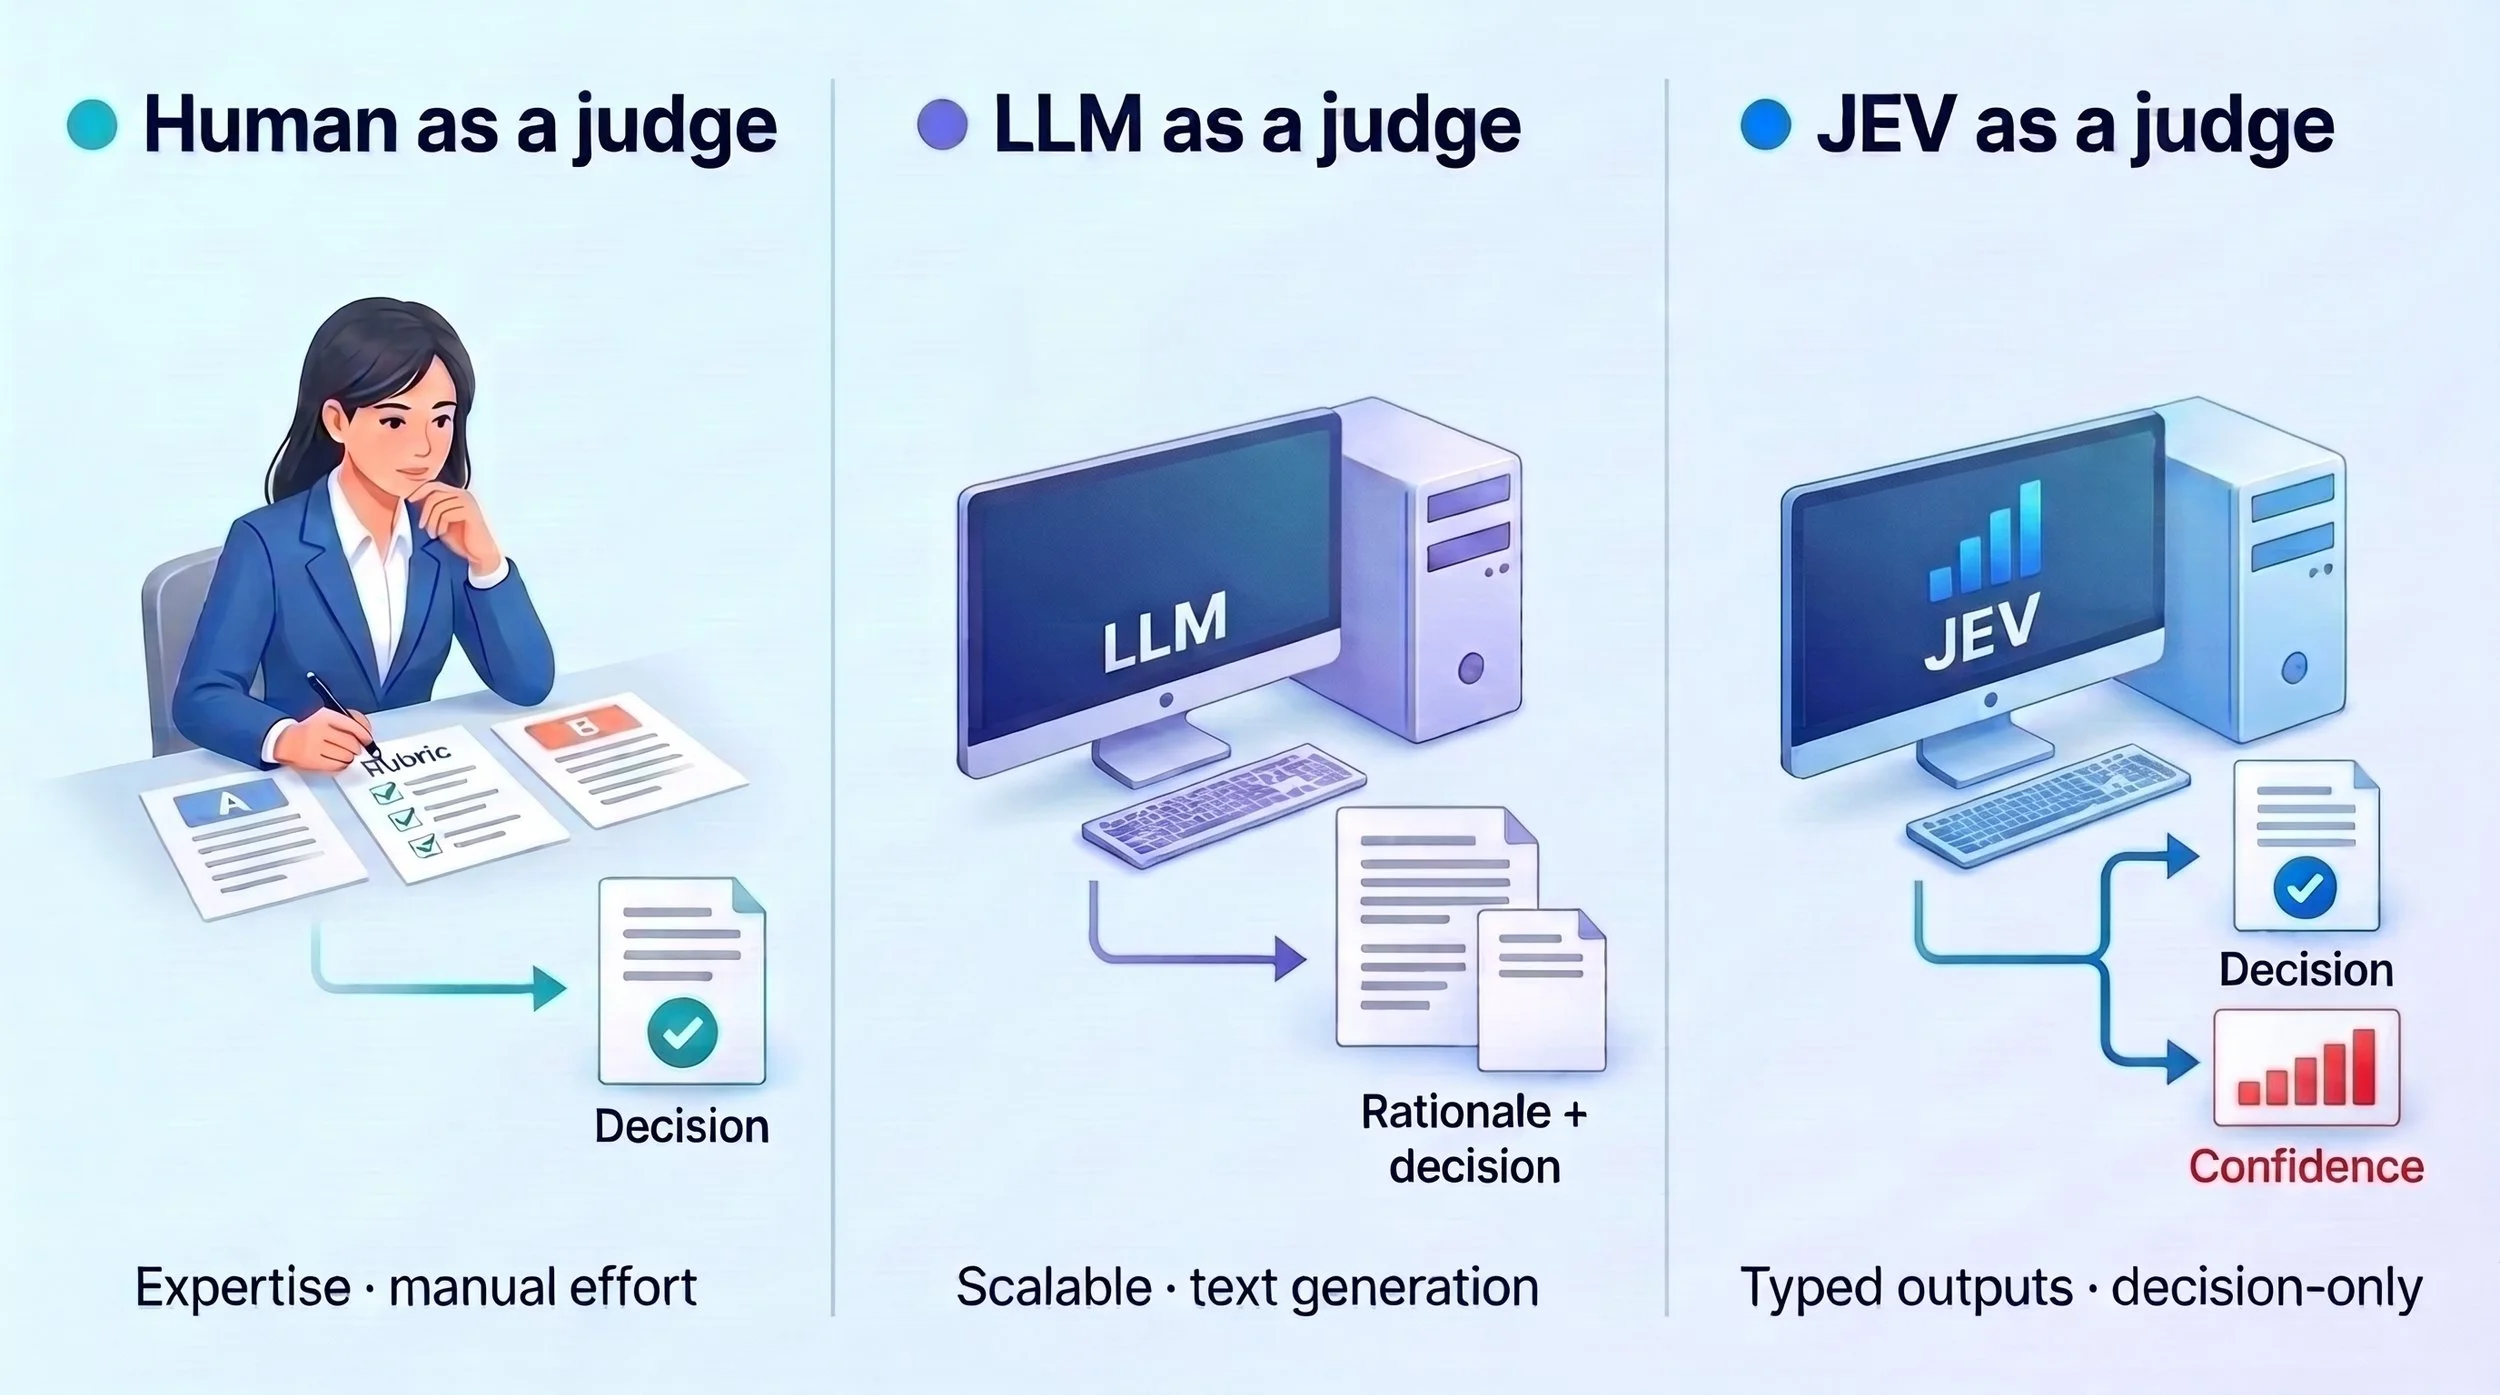
First, let us compare judgments made by humans, LLMs (Large Language Models), and Jev to examine their respective characteristics. The research report also summarizes them as shown in the chart below.

Here, let’s consider a task where you read an internal approval request and decide whether you can sign off on it. With the expertise you have cultivated fully on display, the accuracy of your discernment would undoubtedly be outstanding. Unfortunately, however, your resource is limited to single-person manpower, making it impossible to scale up all at once. For this reason, it has recently become common practice to delegate your tasks to AI agents powered by LLMs. The capabilities of cutting-edge LLMs are remarkable, with cases emerging where their accuracy surpasses that of humans. Yet, LLMs also have shortcomings that make them ill-suited for automation.

‍              ‍Distinction between Humans and AI

It is true that more and more LLMs can achieve high accuracy; however, they inevitably suffer from two persistent drawbacks:

  1. Slow computation speed

  2. High computation cost

Because they perform inference using a massive number of tokens—a process known as Chain of Thought—to achieve high accuracy, they are structurally disadvantaged in terms of both computation speed and cost.

That is where Jev comes in. Jev overcomes these shortcomings of LLMs. We will explain this in detail in the next section.


2. The Capabilities of Jev

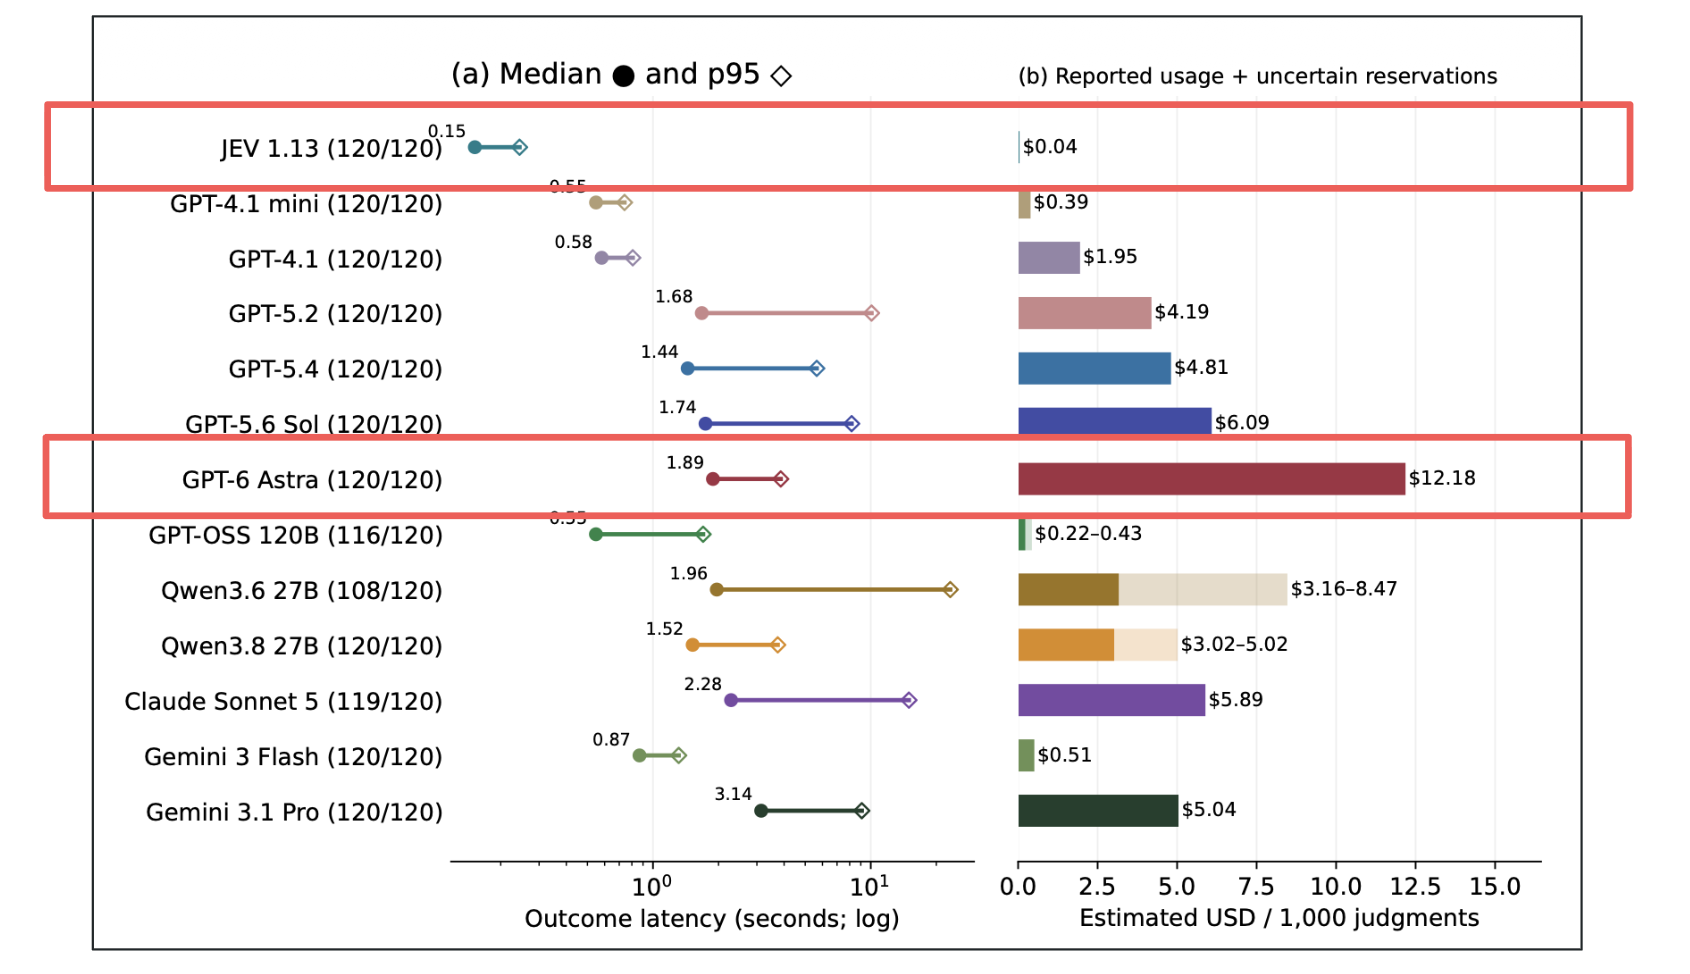
Here, let us directly compare Jev with GPT6 Astra, one of the pinnacle LLMs. The parts enclosed in red frames are Jev and GPT6 Astra.

First, looking at latency (computation time), handling the exact same task took 0.15 seconds for Jev, whereas GPT6 Astra took 1.89 seconds—more than 10 times longer. Next, regarding cost, when performing 1,000 classifications, Jev cost 0.04 USD, whereas GPT6 Astra cost 12.18 USD—over 200 times more expensive. While this is just one example, it is more than sufficient to understand Jev's strengths.

‍  ‍              Latency and Cost Comparison

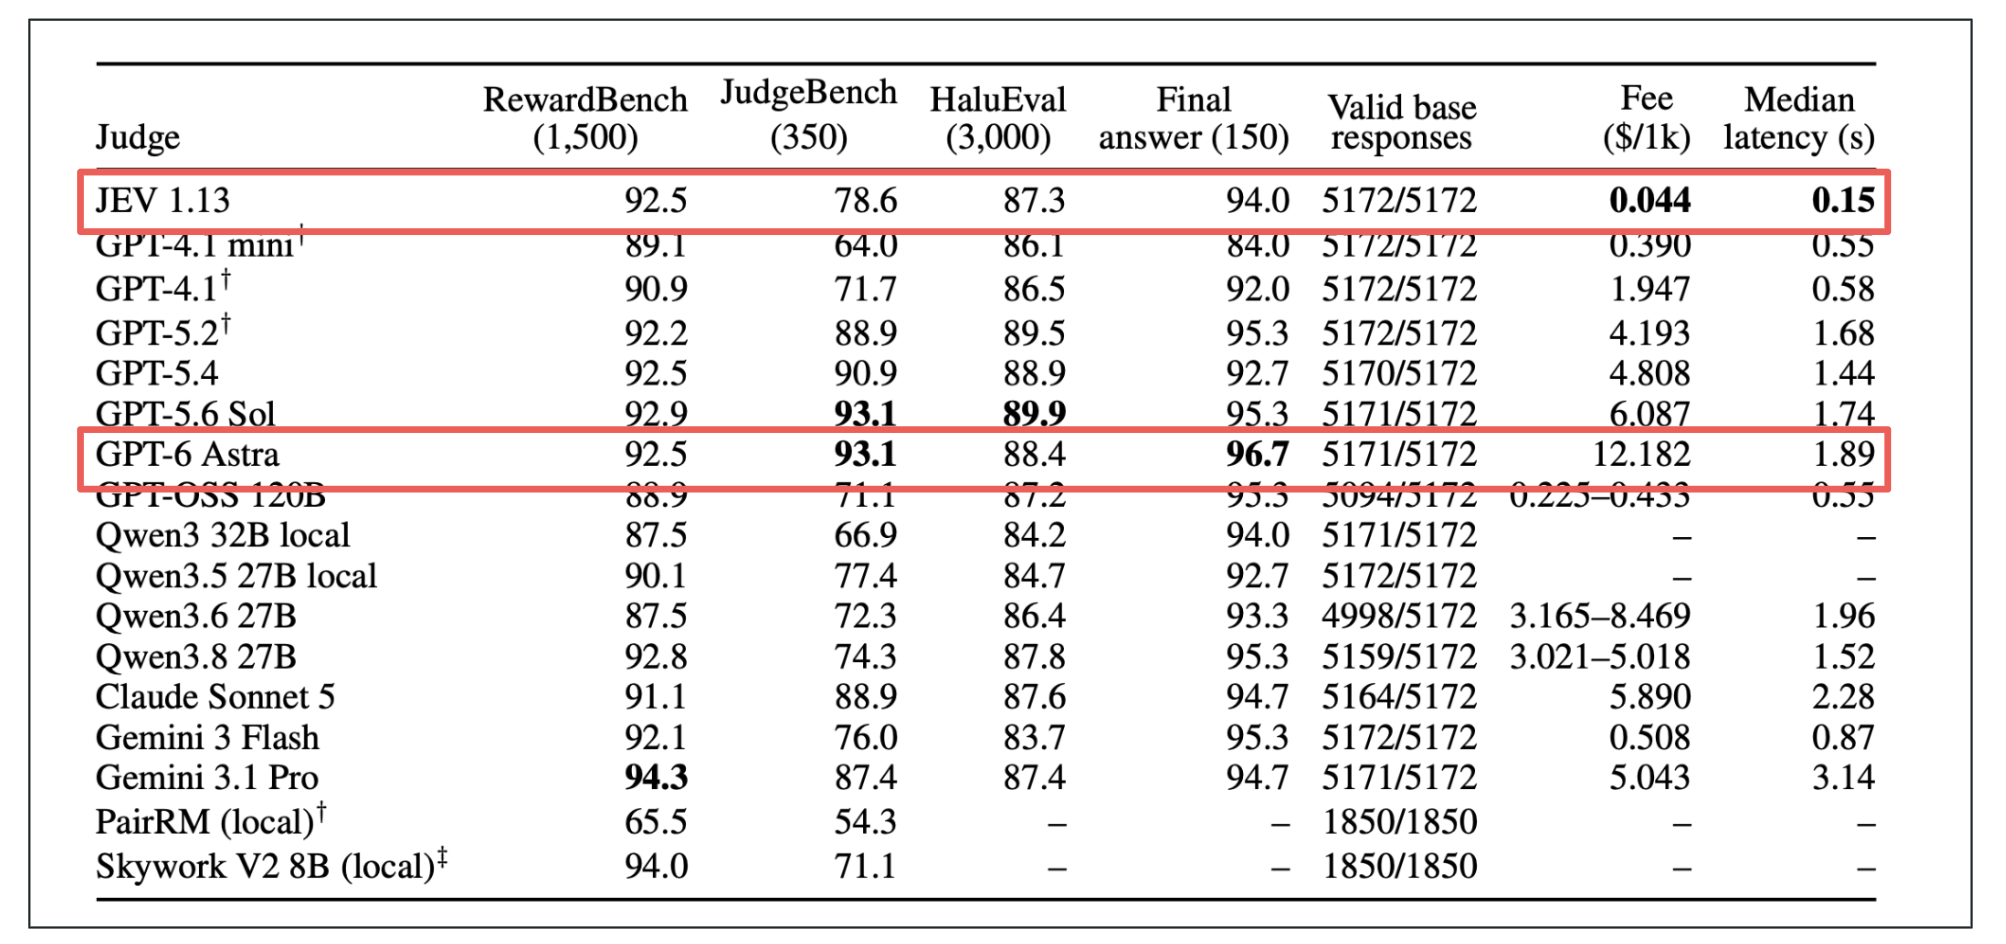
Although Jev may seem flawless, it naturally has weaknesses. As shown below, Jev is clearly inferior to GPT6 Astra on JudgeBench.

‍  ‍               AI Performance Comparison

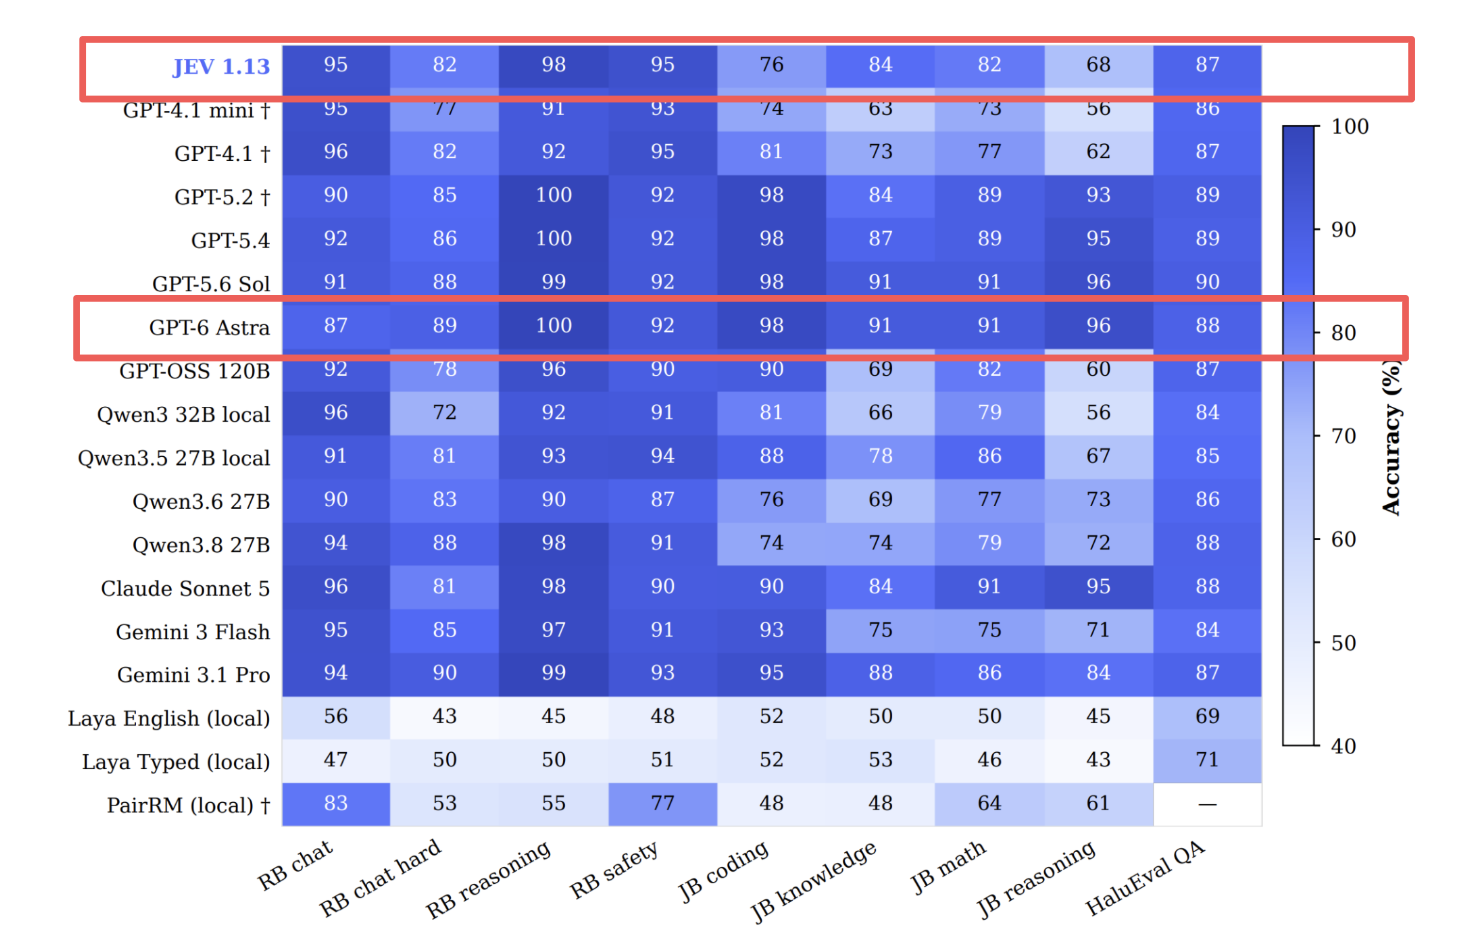
Let’s look into this in more detail. Jev is visibly inferior to GPT6 Astra across the domains of coding, knowledge, math, and reasoning. These are considered "System 2" thinking tasks that require deep reasoning capabilities. Jev was originally referred to as a "System 1 model"—a model adept at tasks that a human could answer intuitively. Therefore, based on these results, it is safe to say that the domains where Jev can be applied are limited to "System 1" thinking tasks. There is still no all-powerful AI that can cover everything. As expected, using Jev and LLMs selectively according to the use case is essential.

             AI Performance Comparison Across Domains


3. Automation with LLMs and Jev

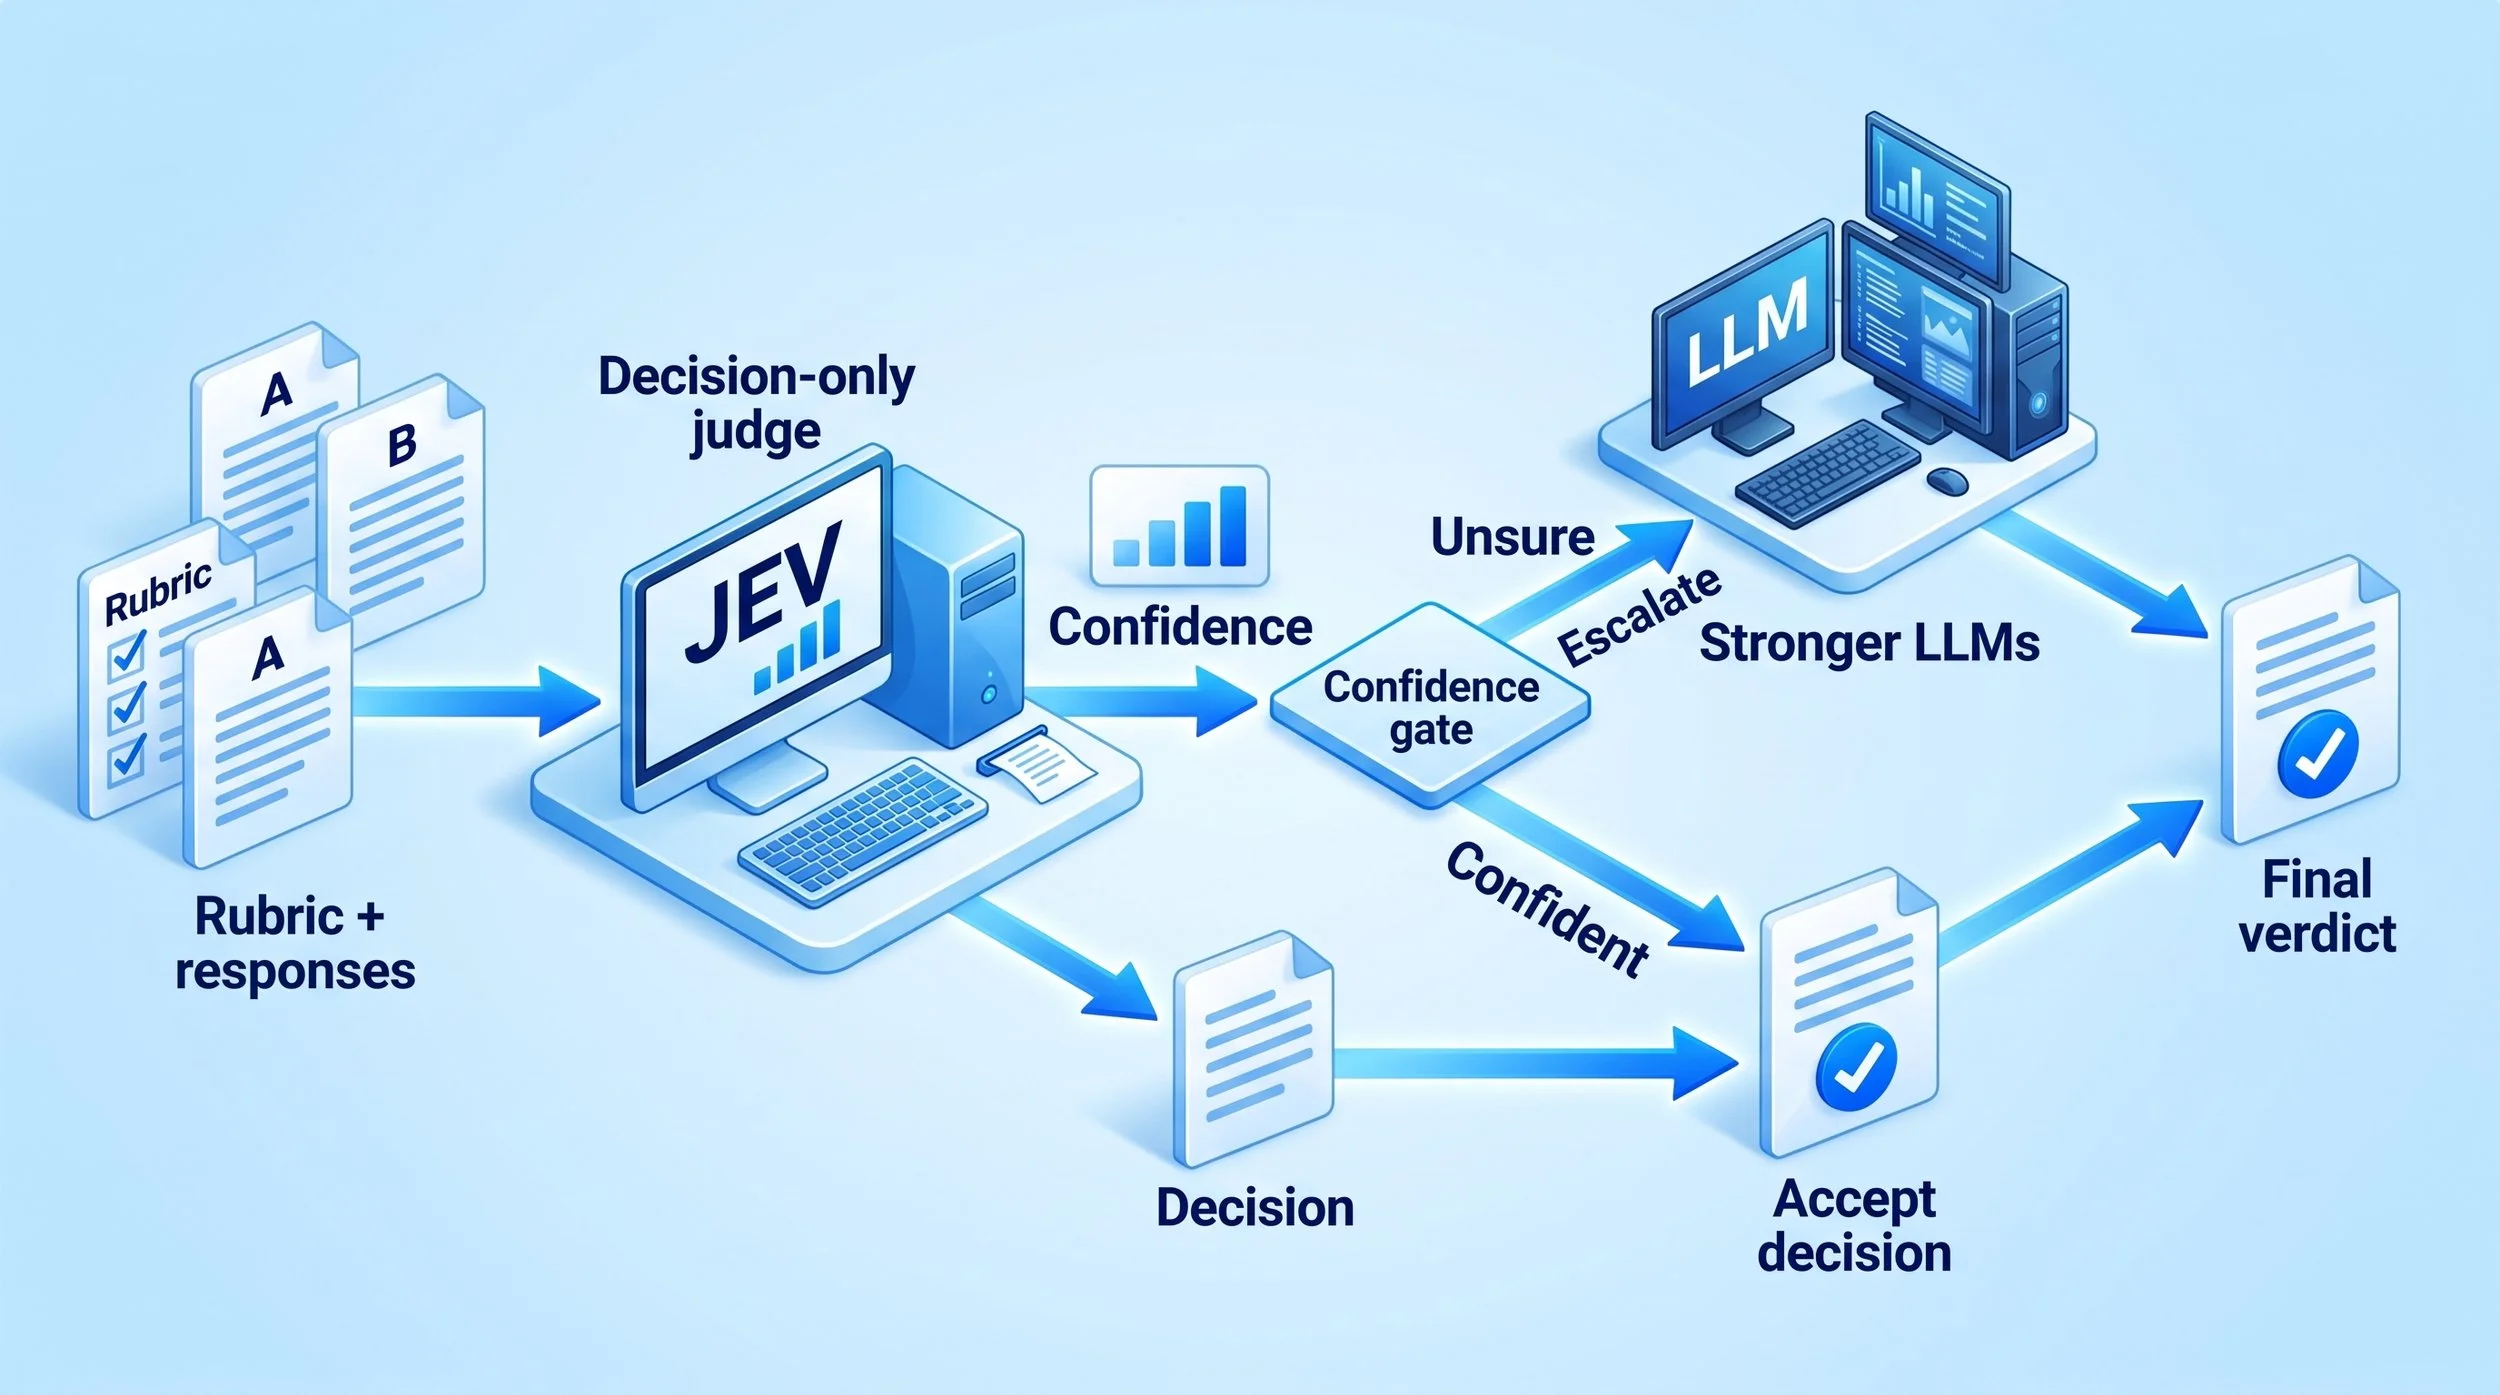
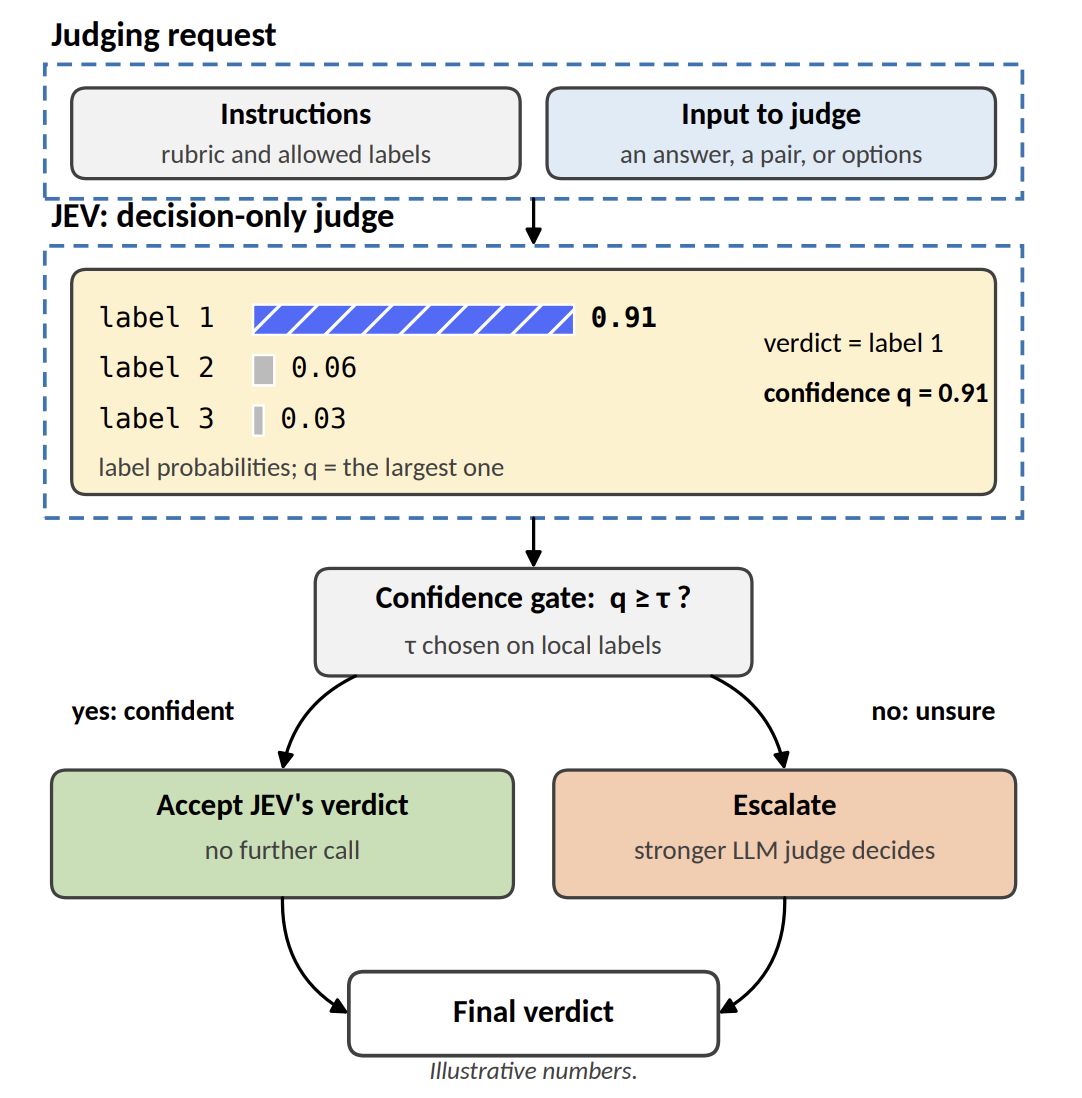
Now that we understand the pros and cons of Jev, let us finally consider a mechanism for automation. As highlighted in the research paper, the fundamental concept is: "Use Jev to triage samples to be evaluated, identify samples where Jev's judgment lacks high confidence, and forward them to a high-performance LLM." This triaging is performed based on the confidence score generated by Jev.

‍  ‍              Automation Process Using Jev

Specifically, it works as follows: Jev outputs the classification result along with confidence scores for each label. In this example, the confidence score is 0.91. With this level of certainty, Jev's output "Classification Label 1" can be accepted. However, if the confidence score is low, such as 0.6, it is better to route it to a powerful LLM and adopt the judgment from there. Furthermore, that threshold is configured based on the target labeled dataset. Through this approach, automation that eliminates the "Human in the loop" is achieved. It is truly remarkable.

‍  ‍              Automation Combining LLMs and Jev


What did you think? By combining LLMs with Jev, we can see a clear path to breaking through the barriers of computation speed and cost—the traditional drawbacks of LLMs—while maintaining accuracy.


Here at Toshi Stats, we intend to continue taking on the challenge of business automation through AI. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link.


1) Introducing System One Models & Jev,  Sep 15 2026, Diogo Almeida, founder, TypeSafe
2) JEV-as-a-Judge: Accept When Confident, Escalate When Unsure
Yubo Li, Yidi Miao. Ramayya Krishnan, Rema Padman
Carnegie Mellon University, Oct 9 2026

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Is "Gemini 4 Argon" Really the Ultimate AI for Financial Analysts? A Look at Finance Agent v2

Google has released a new frontier AI model, "Gemini 4 Argon," marking its first major release in quite a while. It appears to boast performance rivaling that of the leading Opus 5.5 and GPT-6 Astra. Google's website (1) introduces it as follows:

"Gemini 4 Argon delivers frontier performance in complex workflows across real-world software engineering, enterprise knowledge work like legal and finance, and cybersecurity defense."

Therefore, based on available materials, I would like to delve into how well "Gemini 4 Argon" performs, focusing specifically on the financial and accounting analysis that I conduct daily.


1. Gemini 4 Argon Is a First-Class AI

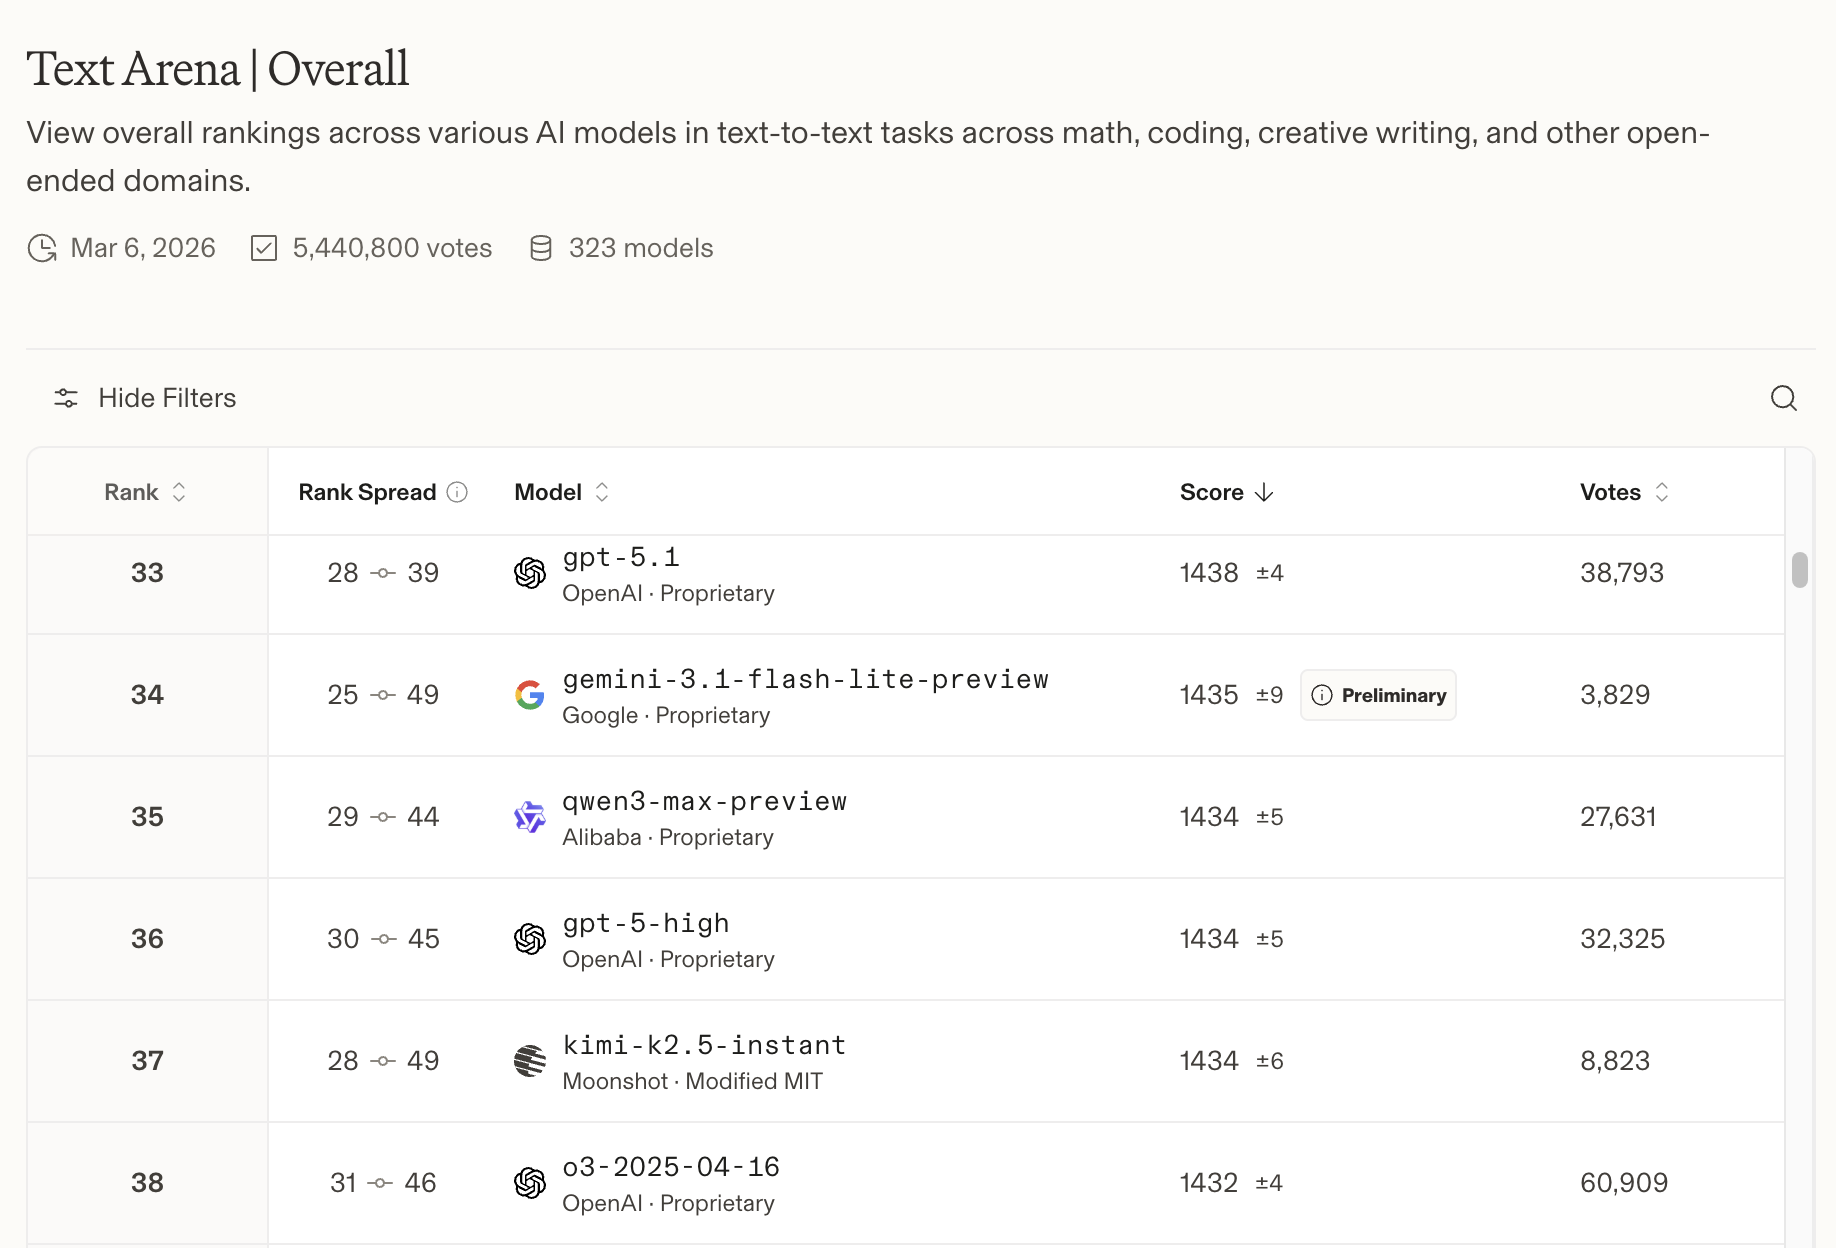
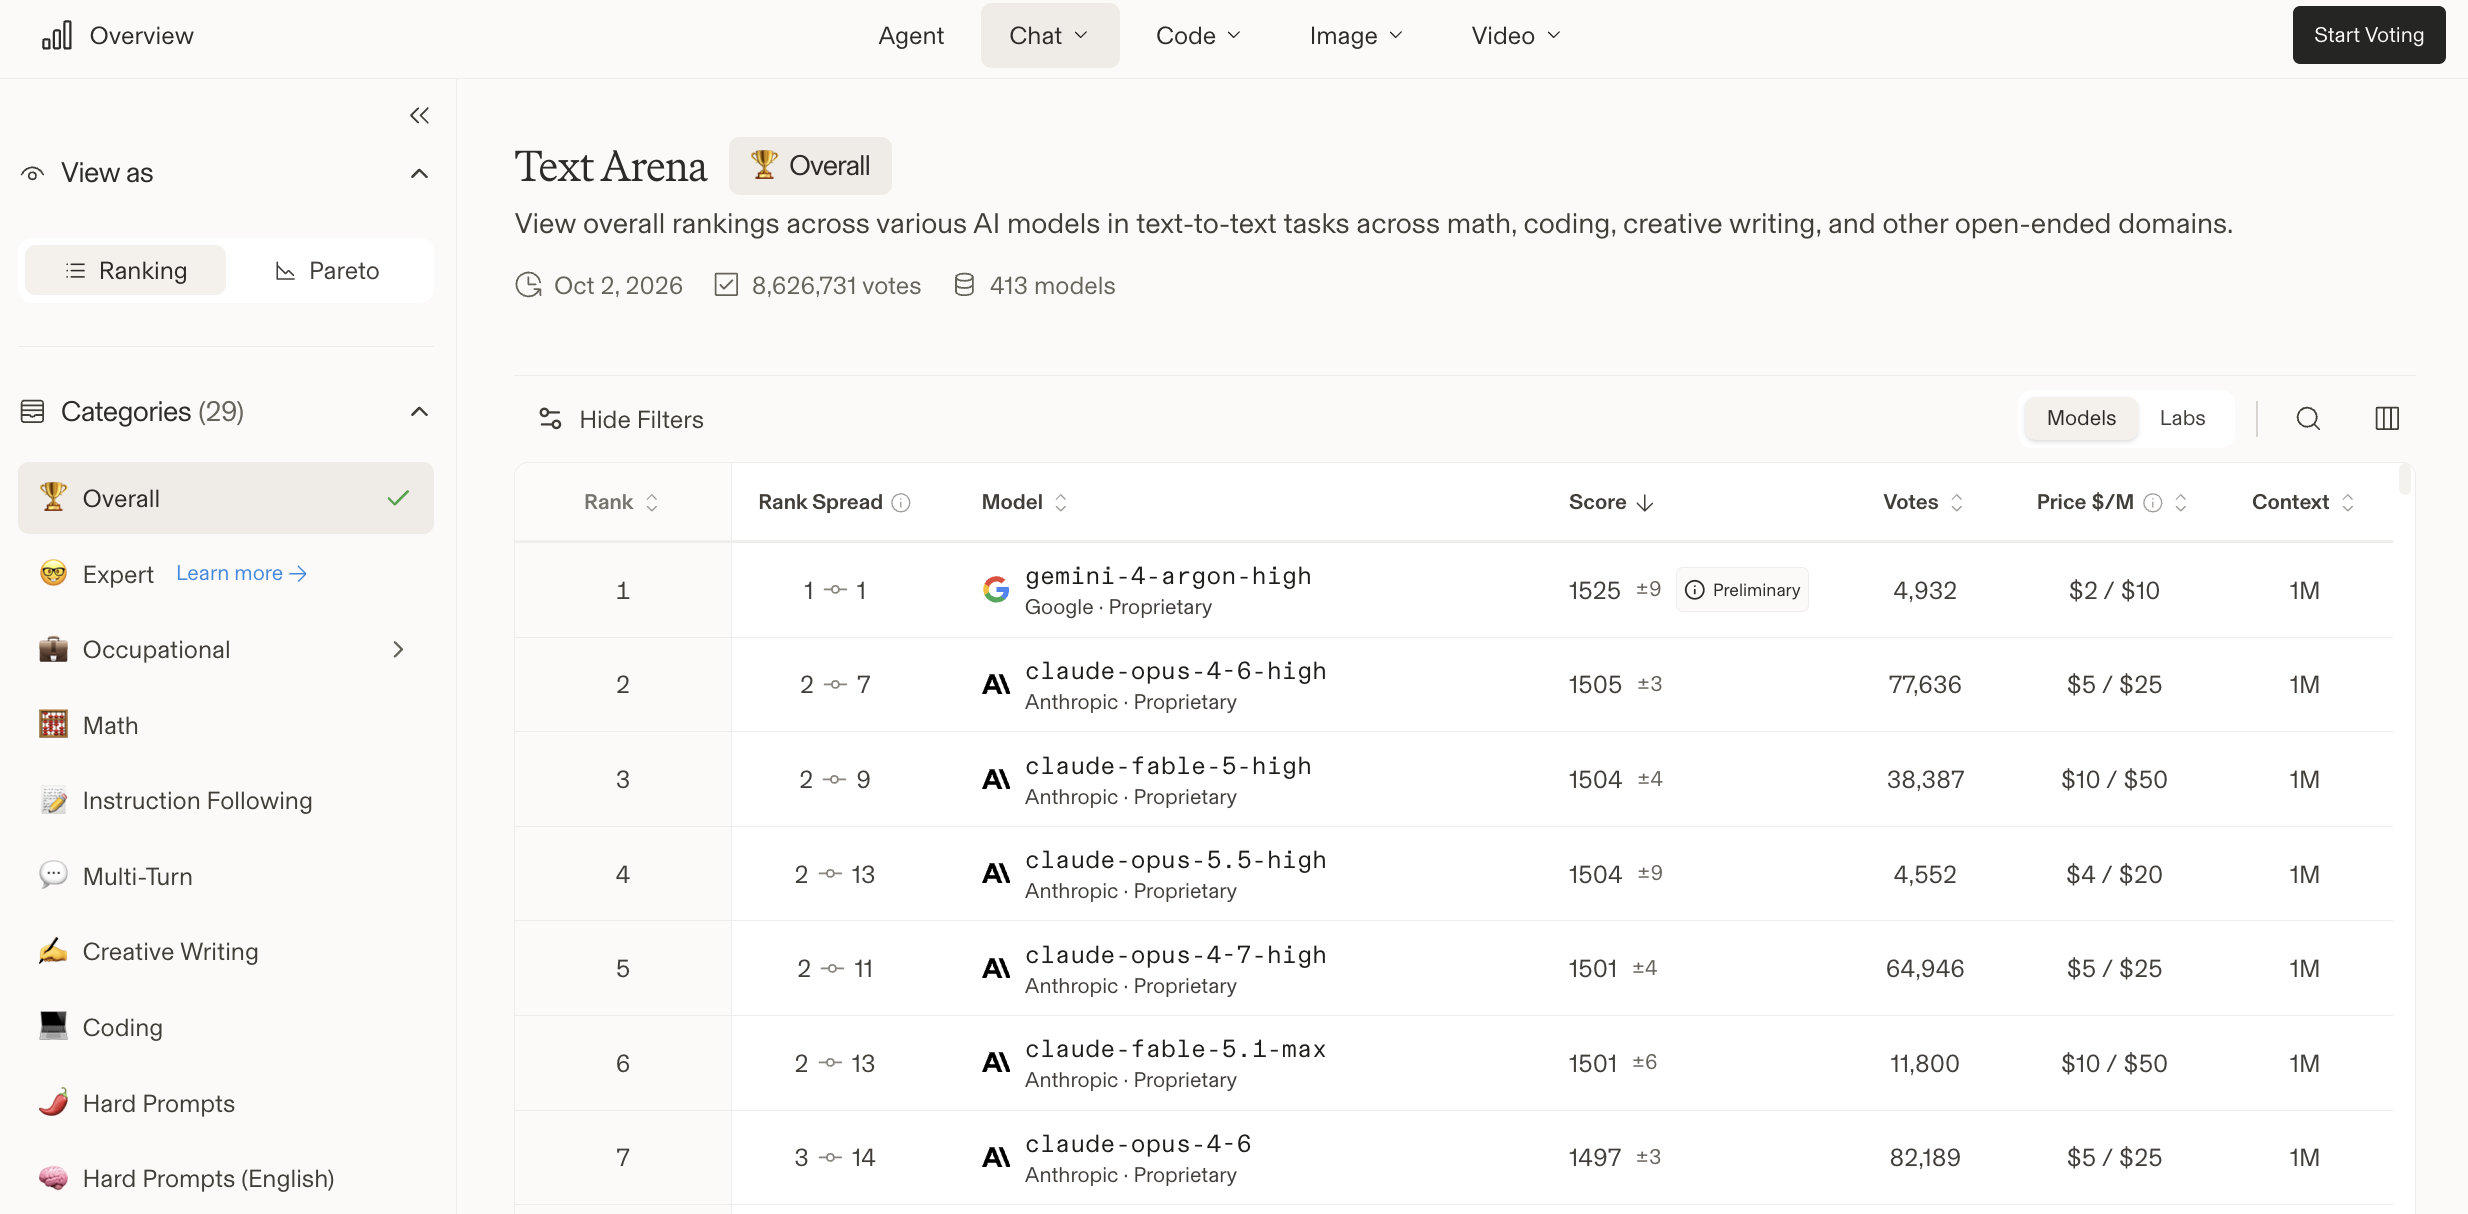
Gemini 4 Argon demonstrates high overall capability, but its text-related performance is particularly noteworthy. As seen in the leaderboard below (2), it surpasses existing leading AI models. Given that strong text processing is an absolute necessity for banking and financial operations, expectations for Gemini 4 Argon are high. A deep analysis is not possible since the technical specifications have not been publicly disclosed; however, the newly introduced 1-million-token output capability may be a contributing factor. Output limits for existing AI models mostly peaked at 128,000 tokens. Gemini 4 Argon is the first to achieve a 1-million-token output, which likely allows techniques such as Chain-of-Thought reasoning to be applied over much longer sequences, thereby driving its performance gains.

              Text Leaderboard

For reference, the leaderboard is defined as follows:

“View overall rankings across various AI models in text-to-text tasks across math, coding, creative writing, and other open-ended domains.”


2. A Look at Financial and Accounting Analysis Benchmarks

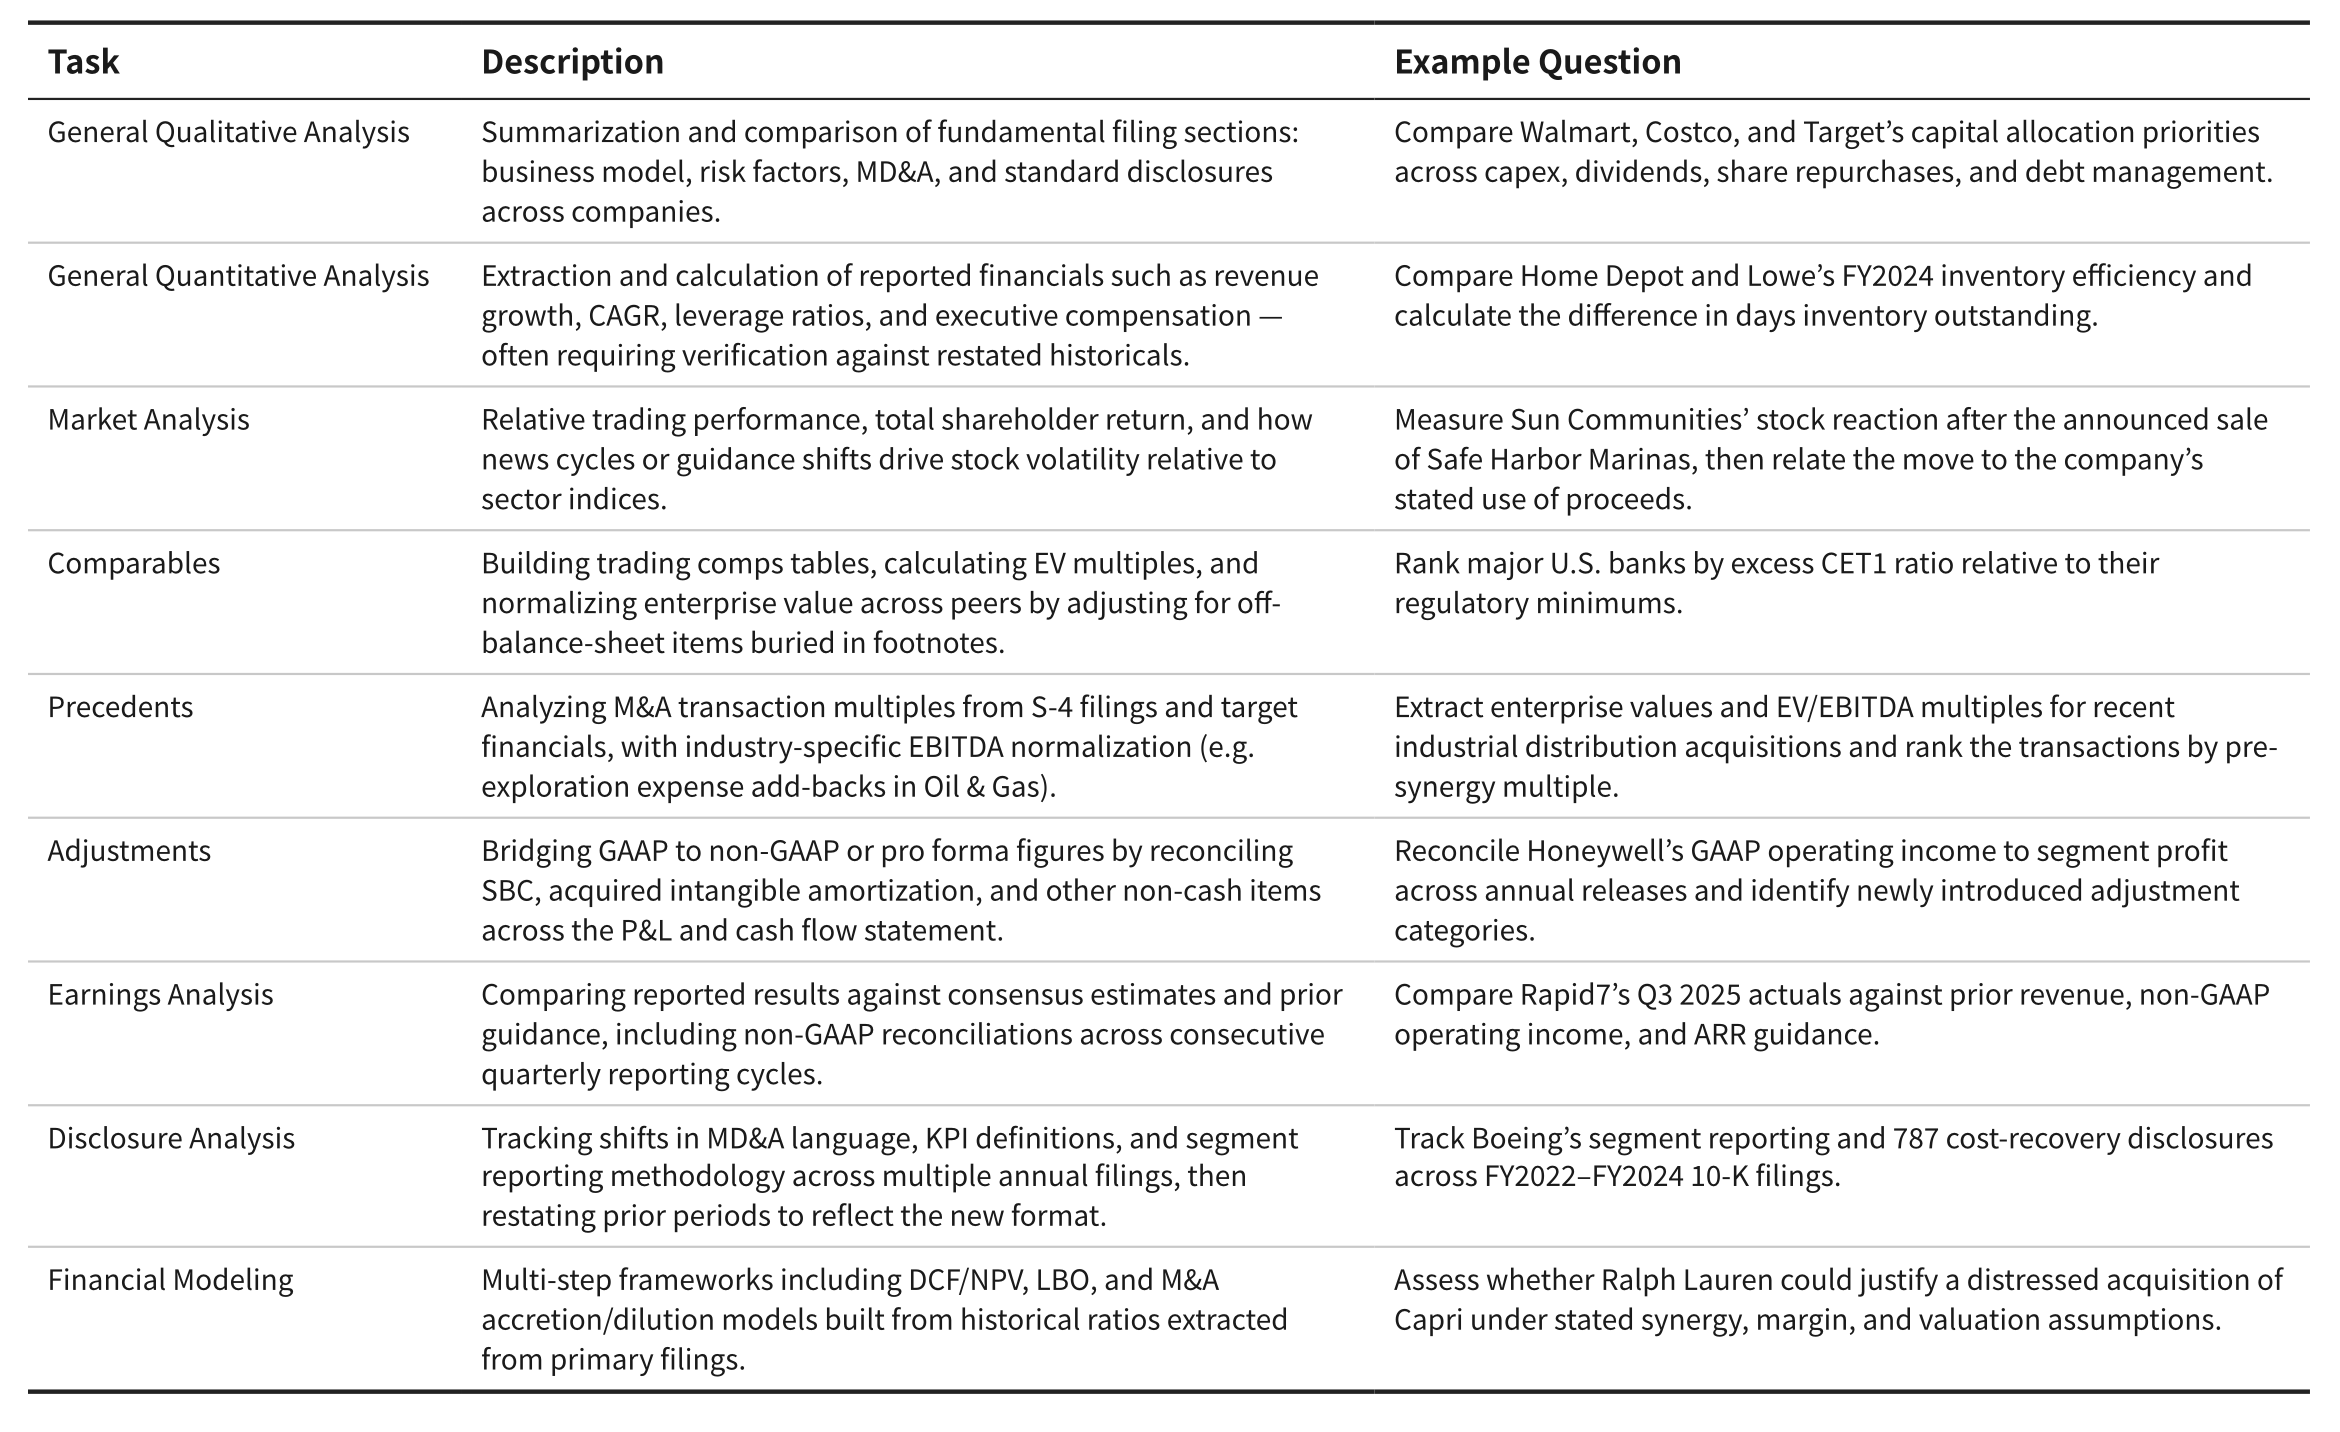
Let us examine specific domains in greater detail. Since my area of expertise is finance, I would like to look at a finance-specific benchmark. The Finance Agent v2 benchmark (3) analyzes the daily tasks of financial industry analysts, categorizing them into nine distinct tasks to evaluate AI performance. Specifically, the benchmark assesses an AI's ability to access and analyze publicly disclosed financial statements using external tools, spanning tasks from simple data extraction of specified metrics to advanced operations such as Discounted Cash Flow (DCF) analysis. Refer to the table below for task details.

Nine Task Categories for Analysts

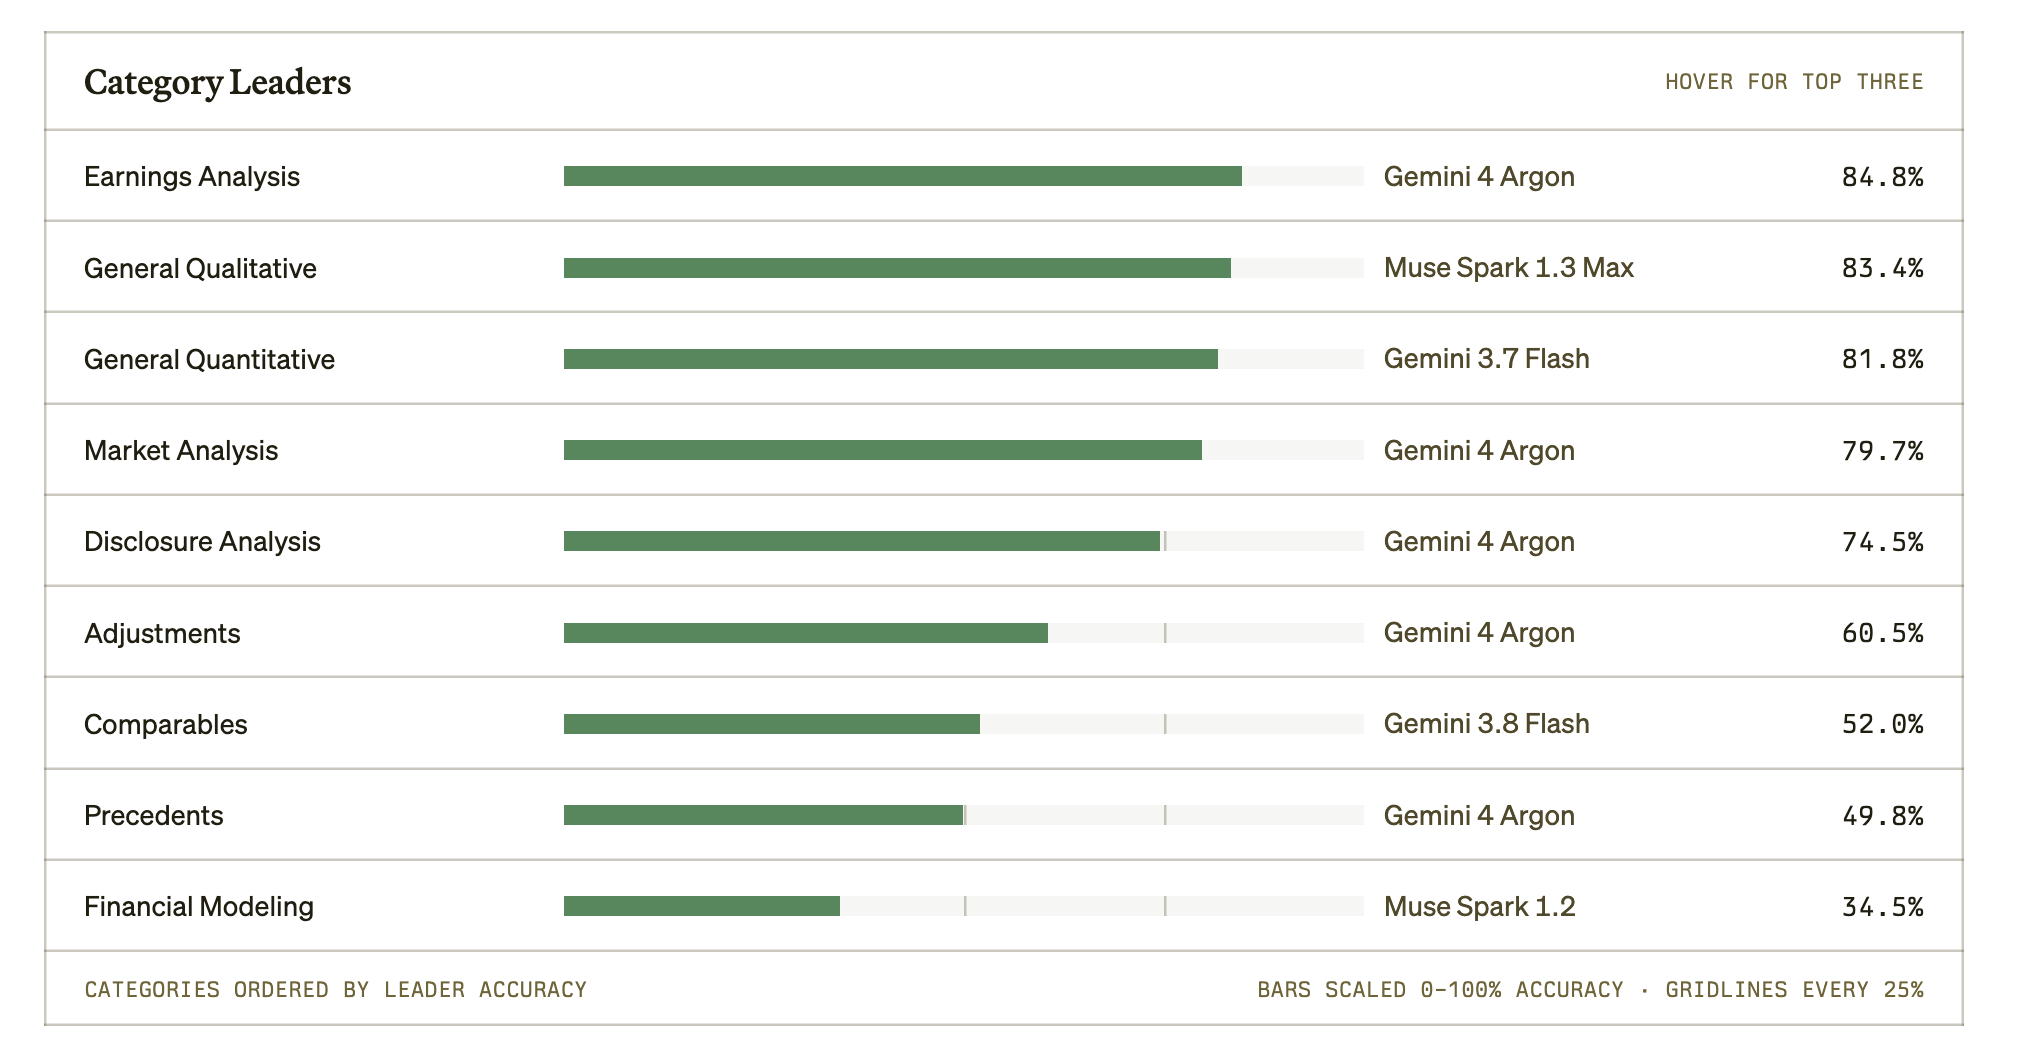
The top-performing AI model in each task category is listed below. Gemini 4 Argon ranked first in 5 out of the 9 task categories, showcasing its strength in this area. However, there are 4 categories—even when accounting for all other AI models—where absolute scores remain below 70%, suggesting that substantial room for improvement remains.

Task Categories and Top-Performing AI Models


3. Can It Be Used in Practical Operations?

Judging from the scores across each task category, it is likely to serve as an outstanding assistant—provided its scope is limited to relatively simple tasks. Ideally, we would entrust it with complex assignments, but tasks like Discounted Cash Flow analysis are still executed far more reliably by human analysts. Even with the cutting-edge Gemini 4 Argon, accuracy remains insufficient across several tasks. Determining what can be delegated to AI and where human intervention is required will be the key to successfully utilizing AI in finance and accounting. Trial and error will inevitably continue for the foreseeable future.


What are your thoughts? There is little doubt that Gemini 4 Argon currently stands as a pinnacle AI model. Hopefully, it will soon become accessible worldwide. Nevertheless, as the Finance Agent v2 scores indicate, successfully implementing AI in finance and accounting relies on establishing effective collaboration between humans and machines.

At Toshi Stats, we intend to continue exploring AI applications in finance and accounting. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link.

1) Gemini 4 Argon: our next era of frontier intelligence, Sep 30, 2026, Google
2) Text Arena, Oct 2, 2026, Arena
3) Finance Agent, Oct 1, 2026, VALS

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Why "Jev-as-a-Judge" is a Game Changer for AI-Driven Automation

A "System One Model" known as "Jev" (1) is currently drawing significant attention, leading many to suggest that full-scale AI-driven automation is about to begin. In this article, taking the classification of bank customer complaints as our theme, we explore how applying "Jev" can make automation successful.


1.Measuring Prediction Accuracy

The dataset prepared for this evaluation consists of US bank customer complaints (2). Using "Jev," we tackled a classification task to predict which financial product each individual complaint pertains to. We built a prediction application as shown below and compared the accuracy across five AI models, including "Jev."

The task requires selecting one out of the following six financial products. A total of 50 samples were classified.

List of financial products to choose from

As shown below, "Jev" achieved an accuracy of 90%, standing toe-to-toe with the other models, while completely outperforming them in computational speed. The architecture—which returns only the prediction result without generating natural language text—is clearly proving effective here. Truly impressive.

Comparison with other AI models


2. Identifying Target Samples for Automation Using Prediction Confidence

A major feature of "Jev" is its ability to simultaneously calculate a prediction confidence score. For predictions made with high certainty, the confidence score approaches 1. Therefore, we use this confidence metric to select only the samples about which "Jev" is genuinely confident as targets for automation. In this test, 1,000 samples were evaluated. We set only the samples with a confidence score of 1 as candidates for automation. The qualifying sample count was 788, yielding an accuracy of 95.1%. While this accuracy is already solid, mapping legacy category names that "Jev" did not select to their updated counterparts (as product names were updated over the course of the long-term data collection period) brings the accuracy up to 98.2%. In other words, the error rate for samples targeted for automation drops below 2%, making them ideal candidates for automated processing. A summary of the results is shown below

Analysis results for samples with confidence = 1


3.Implementation Workflow for AI-Driven Automation

We found that "Jev" can effectively identify which samples to automate. In this experiment, samples with a confidence score of 1 accounted for roughly 80% of the total, with an error rate of about 2%. By designing an operation that routes the remaining 20% to human review (Human-in-the-loop), an operational productivity boost of approximately 5x compared to pre-automation levels can be expected. Naturally, results depend on the incoming data, and several points require evaluation—such as whether a 2% error rate is acceptable. Nevertheless, as the precision of confidence scoring is expected to improve in the future, right now is the best time to consider automation powered by "Jev." The automation workflow is as follows

Automation workflow using "Jev"


What did you think? Entrusting decision-making tasks to Jev in place of humans is referred to as "Jev-as-a-Judge." As the accuracy of "Jev-as-a-Judge" continues to advance, business process automation driven by AI may take substantial leaps forward. There is plenty of reason for optimism.


Here at Toshi Stats, we plan to continue exploring various applications of "Jev-as-a-Judge." Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link.

1) Introducing System One Models & Jev, August 15 2026, Diogo Almeida, founder, TypeSafe
2) Consumer Financial Protection Bureau

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Qwen3.8-Flash-Next: The Prelude to China's Next AI Leap!

Chinese AI models have been making remarkable leaps forward, and on August 26, 2026, a new AI was announced by Alibaba Cloud (1). It is called "Qwen3.8-Flash-Next," and it's touted to surpass the frontier model Opus4.6. Furthermore, its outstanding technology will reportedly be directly carried over to the next-generation Qwen4. Let's take a look right away!


1. Features of "Qwen3.8-Flash-Next"

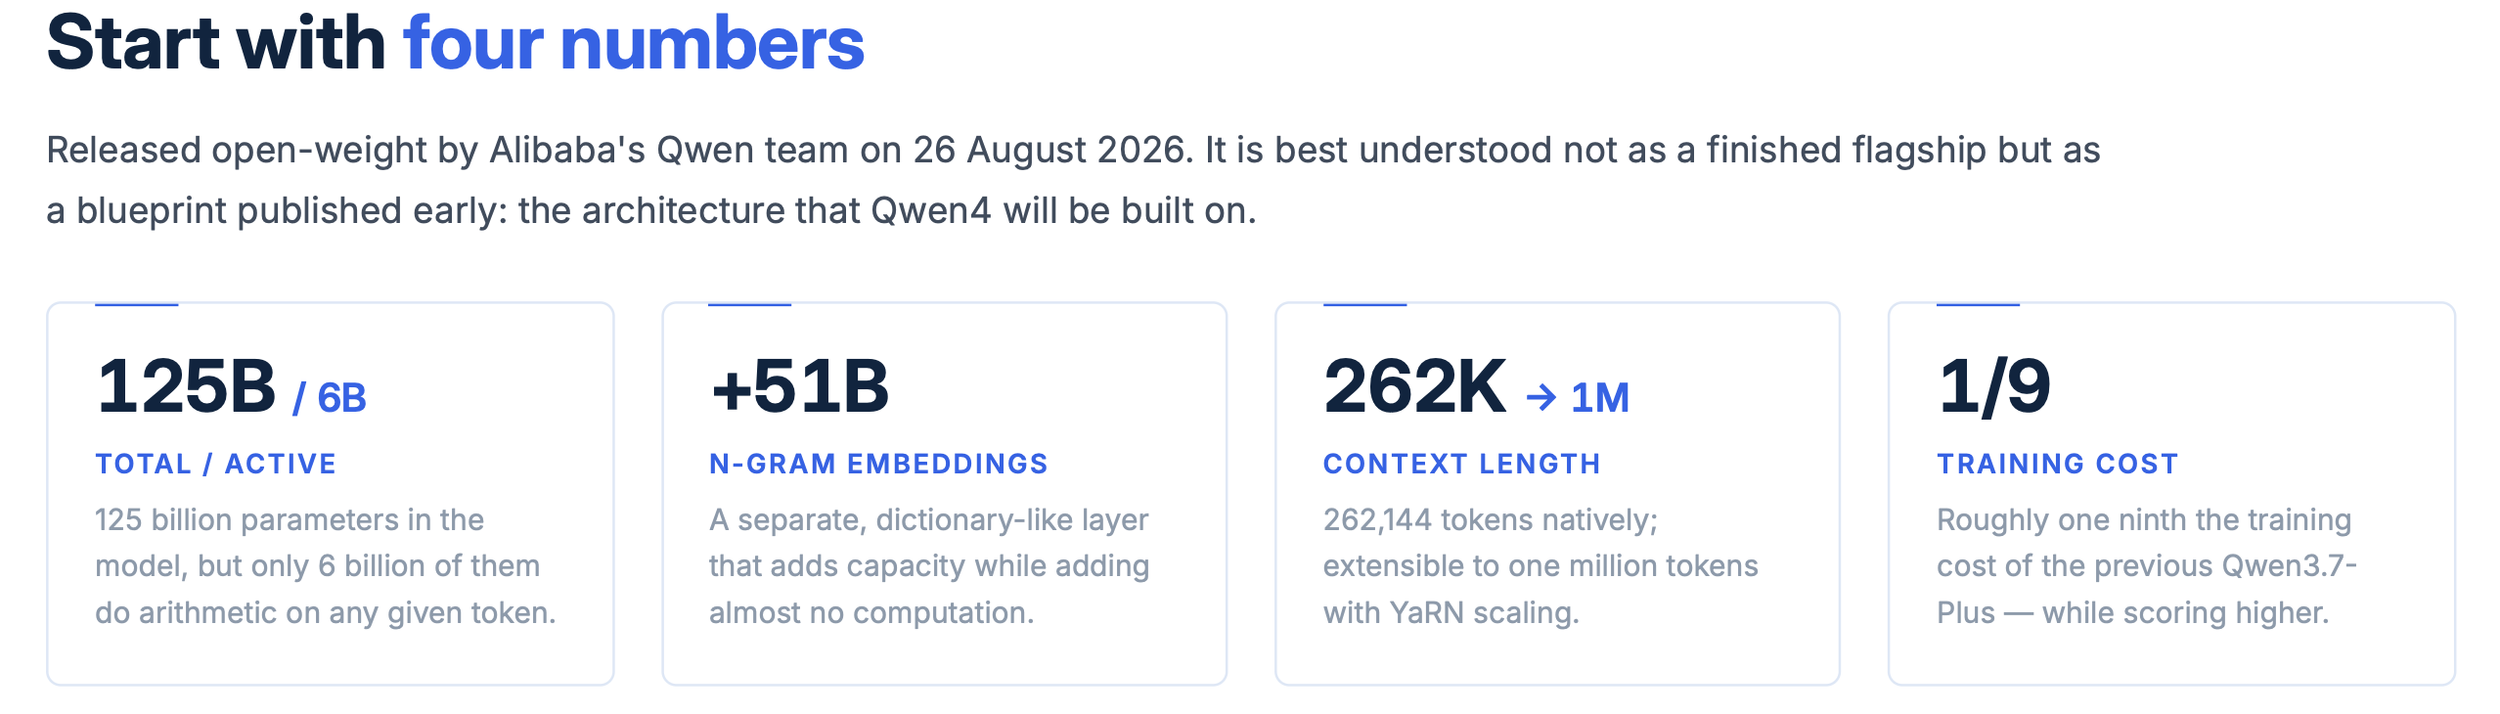
This model is a medium-scale AI model with 125 billion parameters. It adopts MoE (Mixture of Experts), and the actual active parameters are extremely small at 6 billion. Therefore, the calculation speed is presumed to be very fast. The context window is also large at 262,000 tokens, and it seems it can even be expanded to 1 million tokens. Compared to the previous generation model, the training cost is supposedly only 1/9th, making it a highly super-efficient model. However, it's a wonder how it manages to surpass Opus4.6 with a parameter count that is by no means massive. Let's explore the secret behind this.


2. Core Technology of "Qwen3.8-Flash-Next"

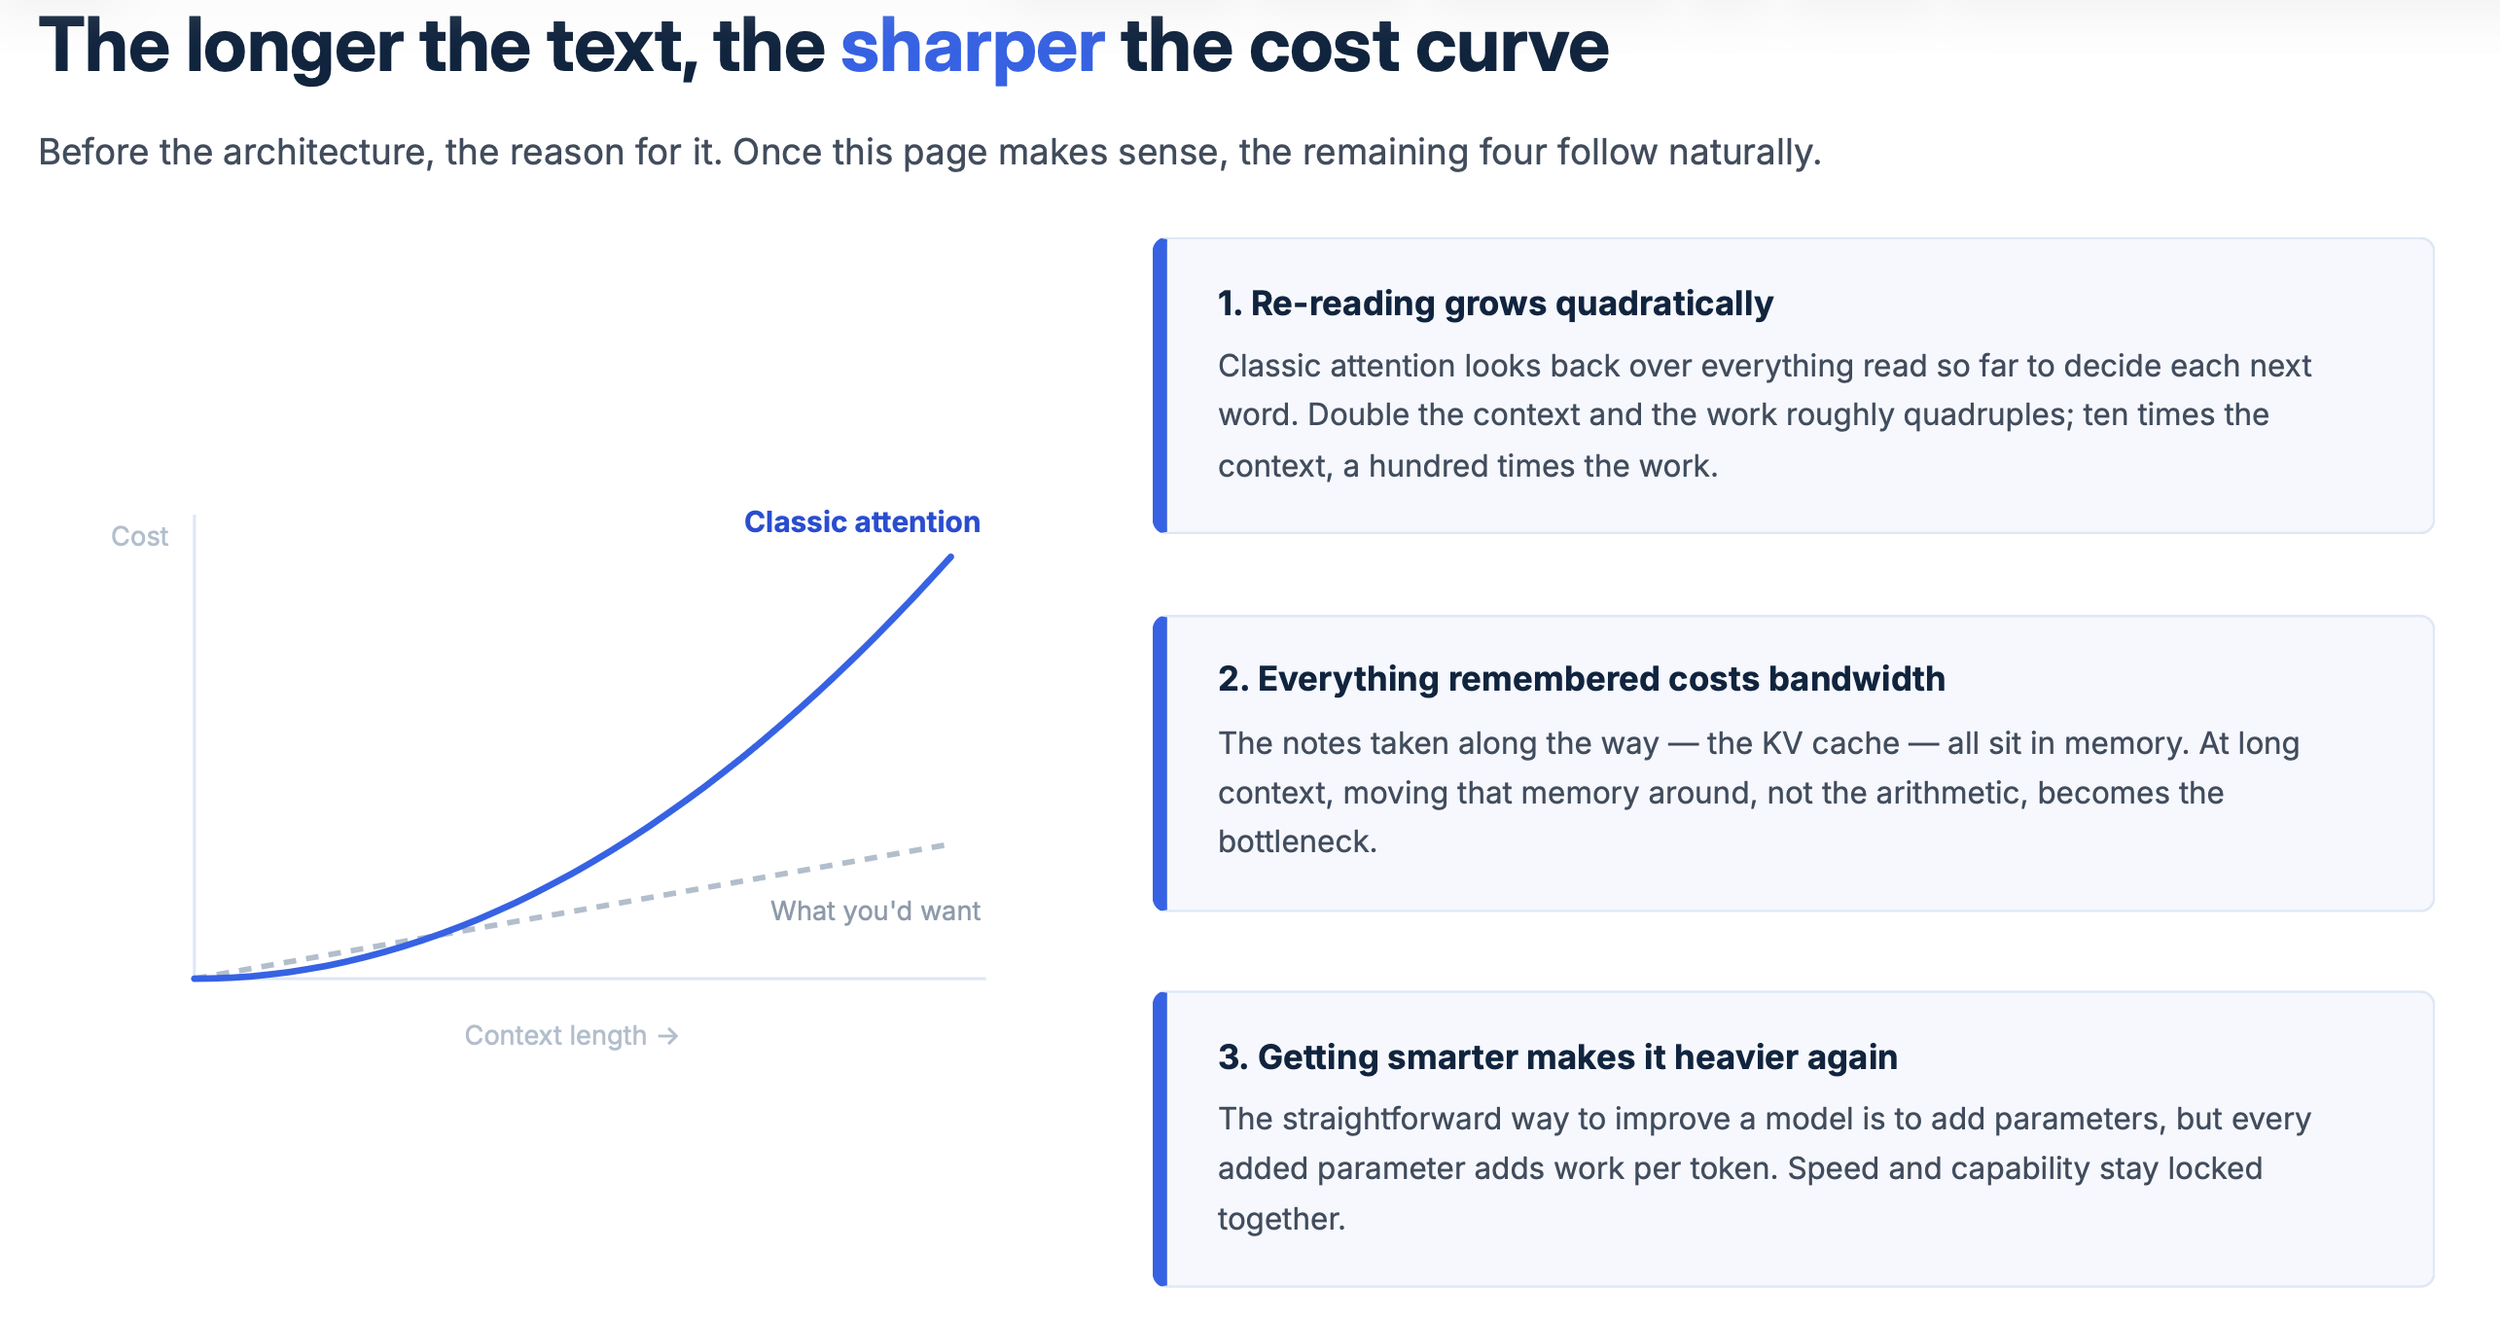
First, it is often said that to improve AI accuracy, the size must be increased. The wall developers hit there is that as the information to process increases, the AI suddenly becomes heavy. The main issue lies in the "attention mechanism" used by most AIs. This is a mechanism that calculates "how much attention should be paid to which information" while the data advances through each layer, but the sheer volume of calculation is massive. Wishing to "do something about this," Alibaba researchers seem to have applied great ingenuity to the "attention mechanism."

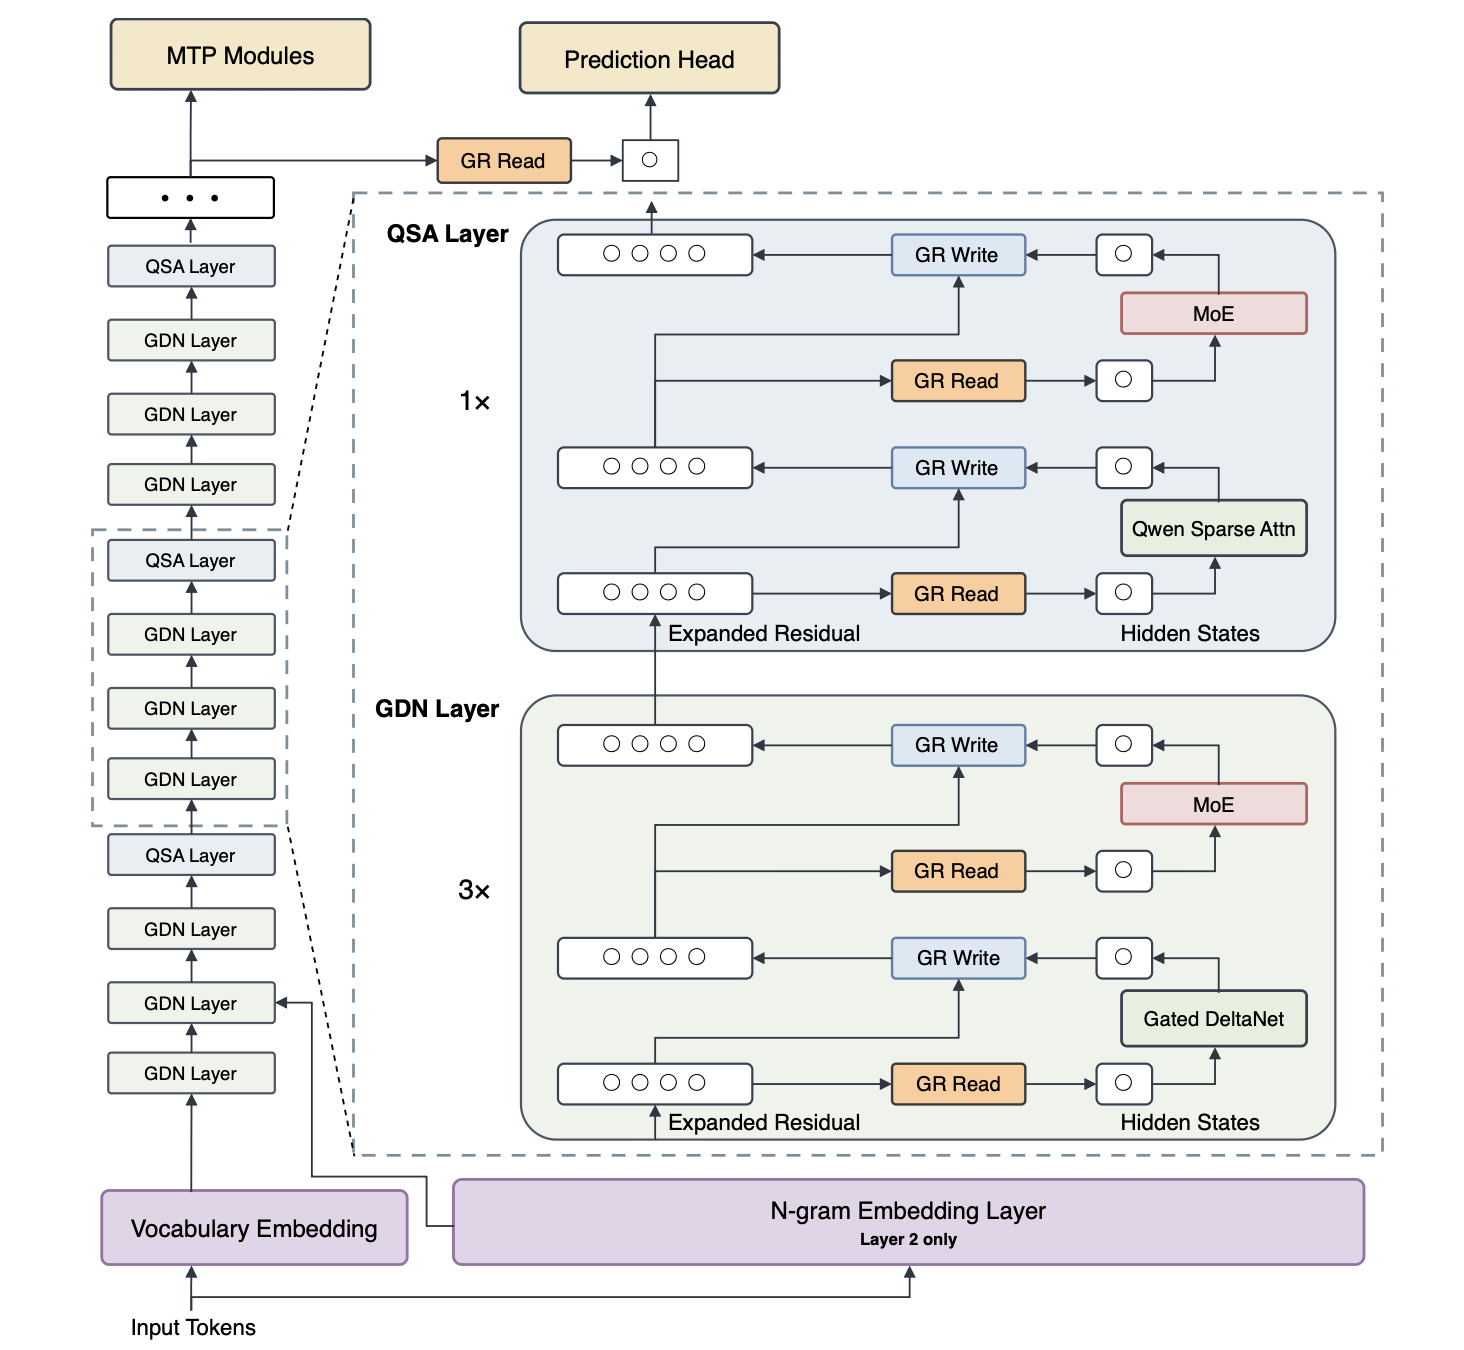
Here is the overall structural diagram of Qwen3.8-Flash-Next.

            Qwen3.8-Flash-Next

First, let's look at the attention mechanism. It has a structure of 48 layers in total, consisting of 12 sets of GDN (Gated DeltaNet) and QSA (Qwen Sparse Attention) in a 3:1 ratio. I think this exquisite combination is absolutely brilliant.

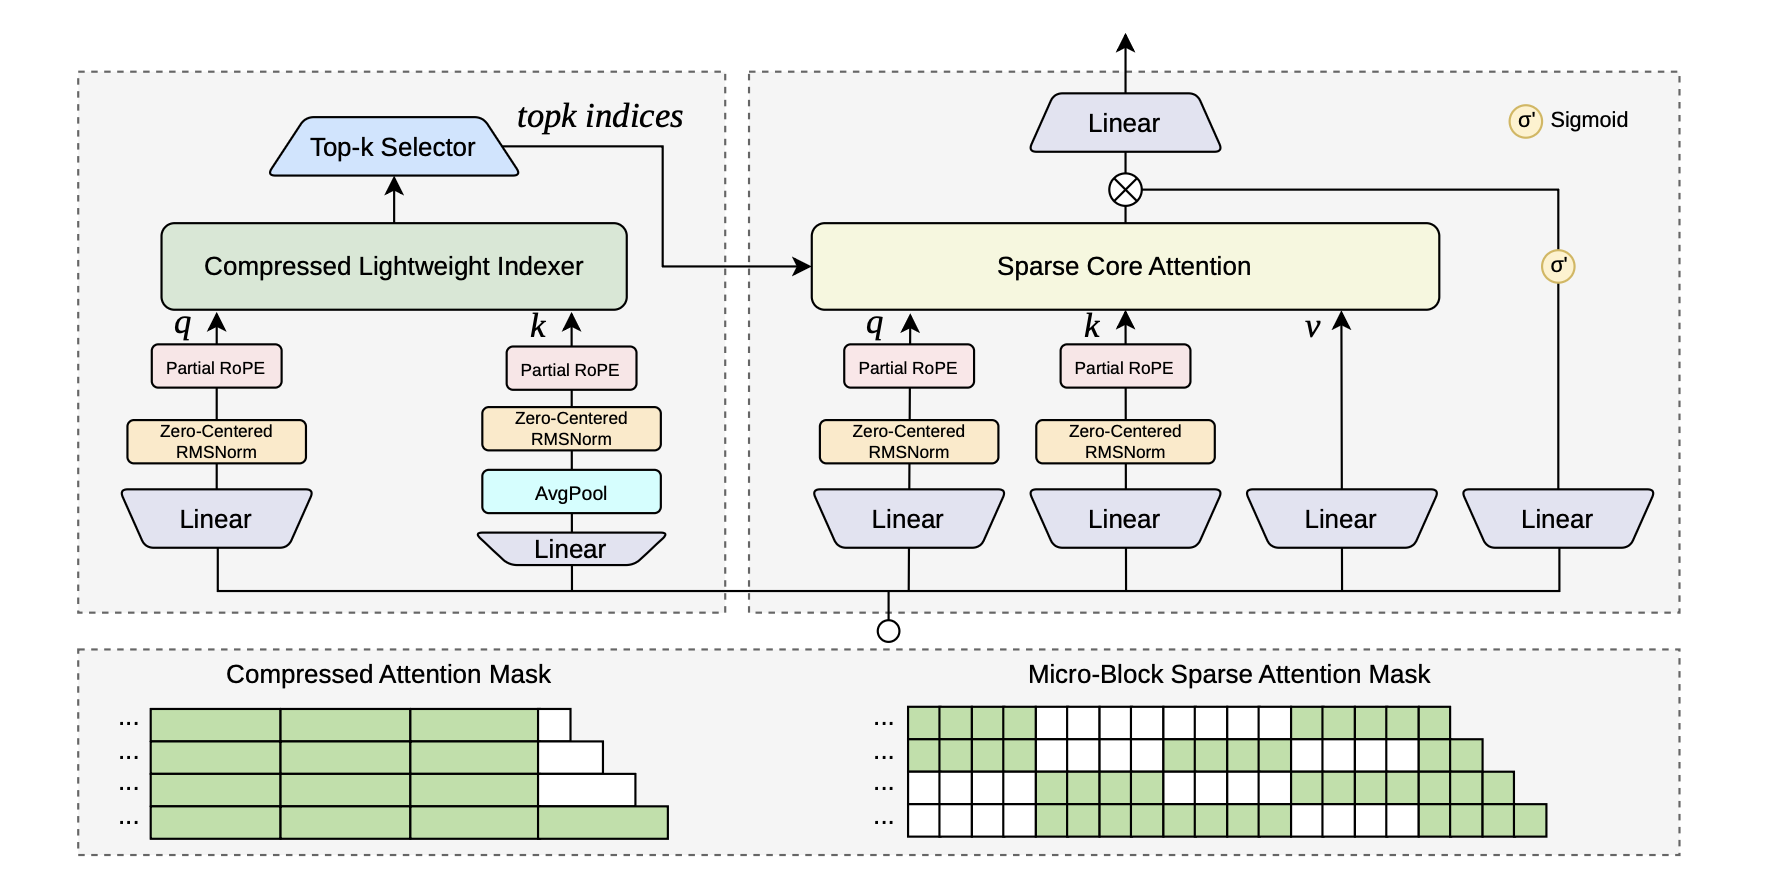
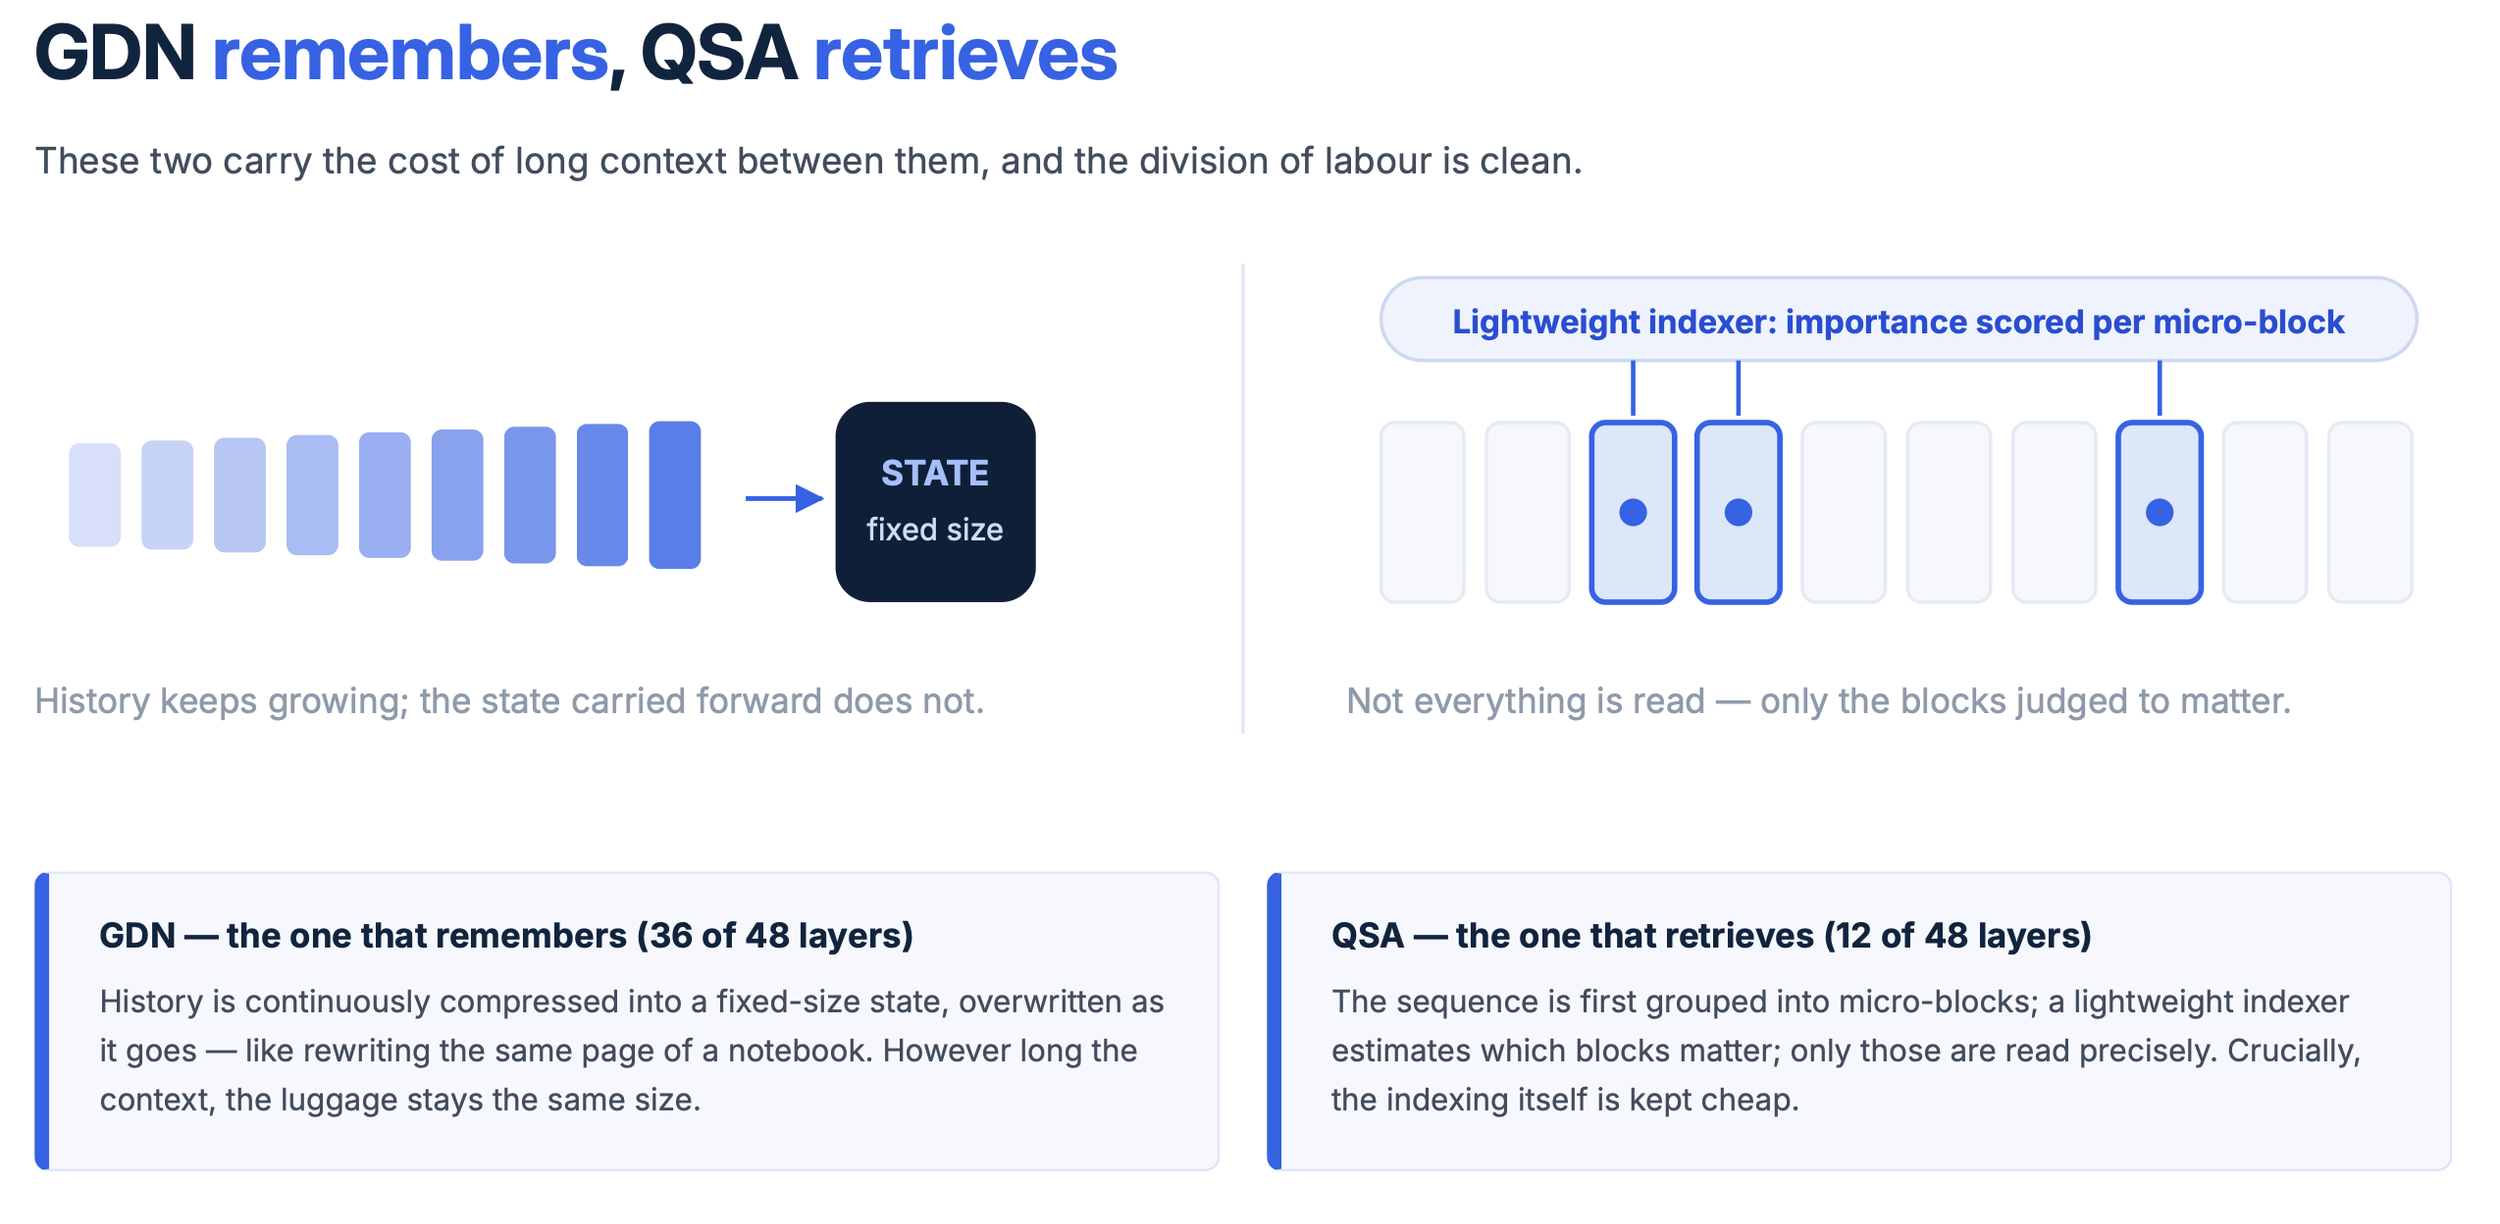
Now, I will explain GDN and QSA. To prevent calculations from becoming too heavy while maintaining accuracy, GDN features a mechanism where the computational volume doesn't increase significantly even if the length of the input tokens increases. That is wonderful, but as a trade-off, there are inevitably cases where accuracy drops. Thus, QSA is used to prevent this decline in accuracy. Normally, a method called "full attention," which looks at every single token, is used, but it has the drawback of bloated computational costs. Therefore, QSA keeps computational costs down by using a method of briefly skimming once, and then reading closely on the second pass.

                Qwen Sparse Attention (QSA)

The diagram above is the structural diagram of QSA. On the left side, the original token sequence is divided into chunks of, say, 16 or 64 tokens, and 'k' particularly important parts are selected. By expanding those specific parts back into the original token sequence, it becomes possible to increase computational efficiency without dropping accuracy. In the diagram on the bottom right showing the state of the tokens, the white sections are the sparse parts where no calculations are performed.

Summarizing GDN and QSA, it looks like the following. This attention mechanism might become a textbook example for AI development in the future.

                GDN and QSA

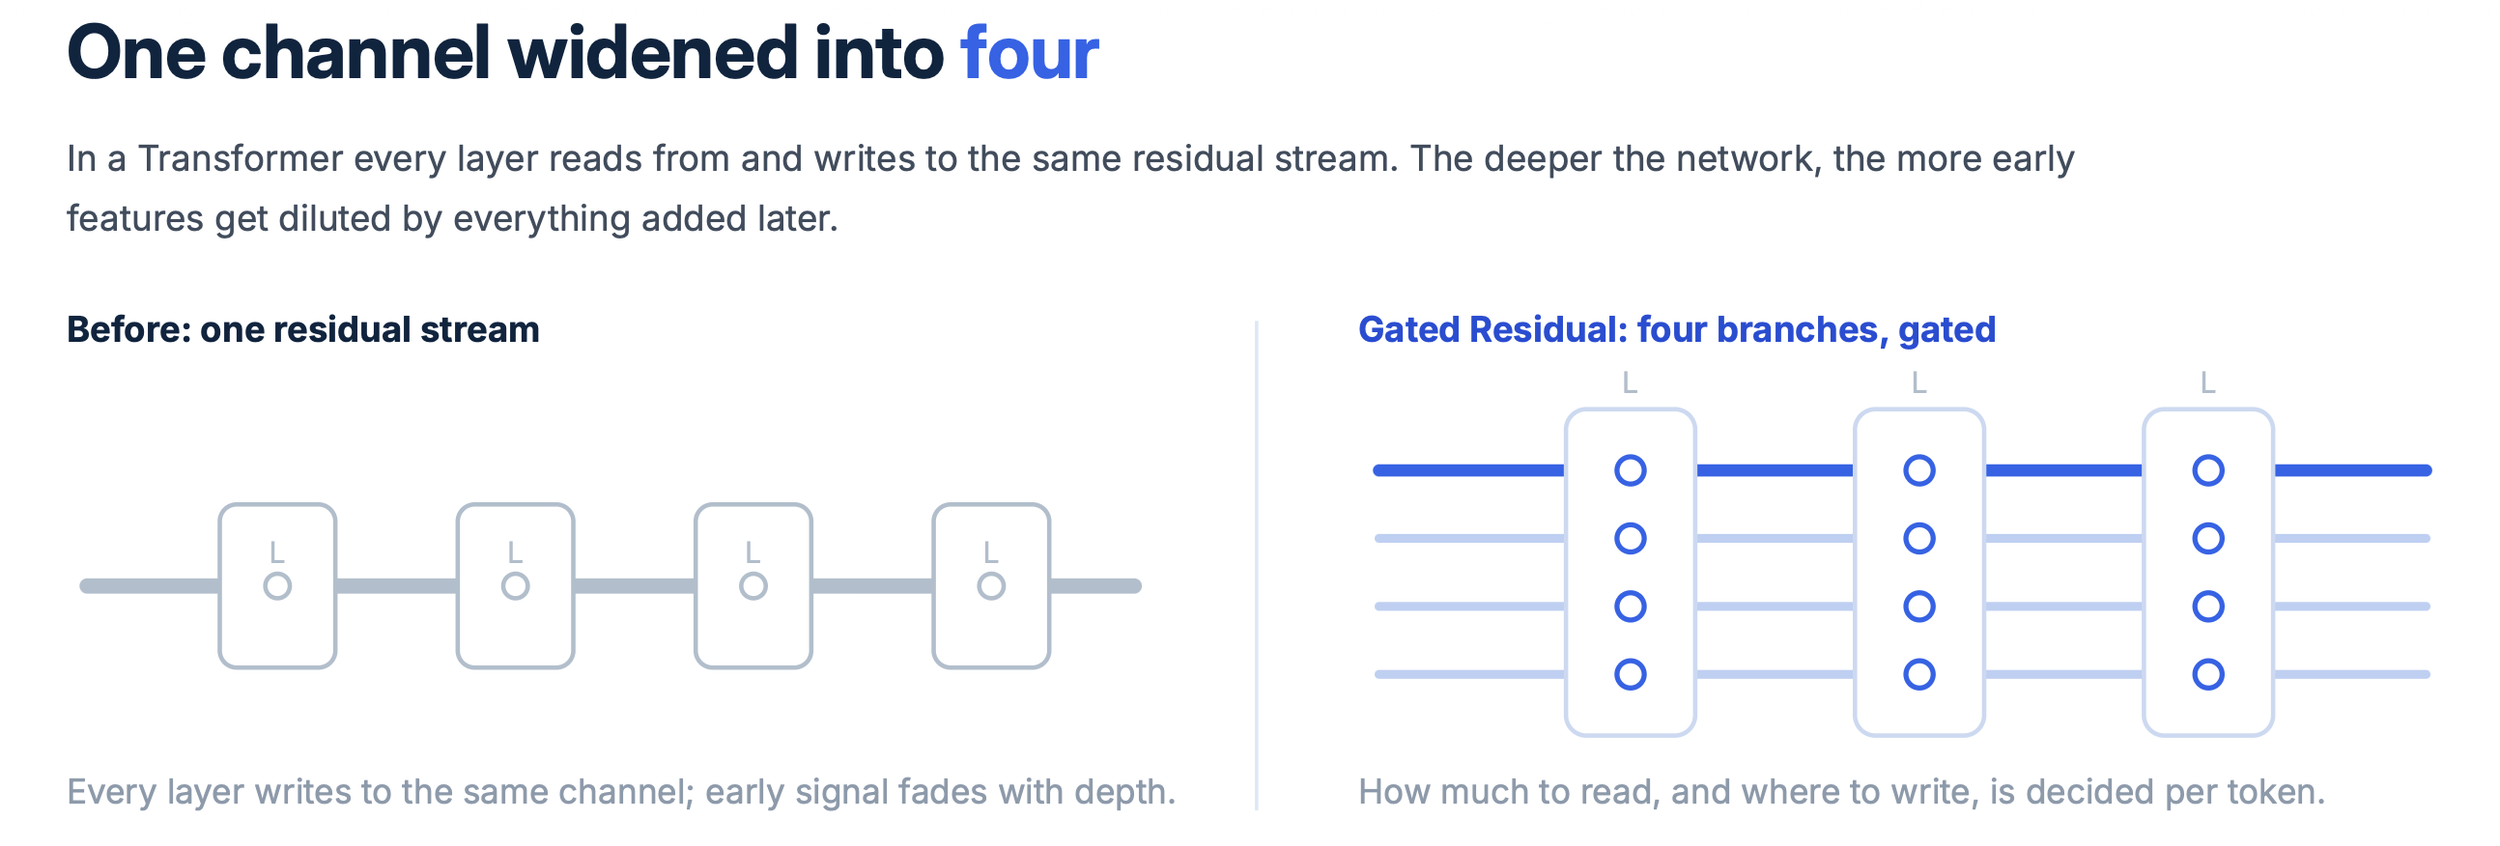
Additionally, the residual stream was expanded into a highly flexible one called "Gated Residual (GR)." Simply put, it means expanding the standard single flow of information into four, and further incorporating a mechanism that decides what information to read and where to write it. There is a mention of "GR Read/GR Write" in the overall structural diagram of Qwen3.8-Flash-Next above, and the read/write functions play an active role here. The residual stream became a de facto standard in the field of image recognition with a very famous 2015 paper called ResNet (2), but at the time, it was still a basic concept that simply added the original information to the information generated in each layer. This Gated Residual enables far more flexible information processing, and I was deeply moved to catch a glimpse of the technological progress made over this past decade.

               Gated Residual (GR)

Moreover, Qwen3.8-Flash-Next incorporates numerous other technologies, such as N-gram Embedding and the Muon optimization method. It seems that these ingenuities organically connect to give birth to a high-performance AI. I would like to share a sentence from the conclusion of their technical report:

The design reflects a conviction that architecture, efficiency, and optimization form one coupled system.


3. Performance of "Qwen3.8-Flash-Next"

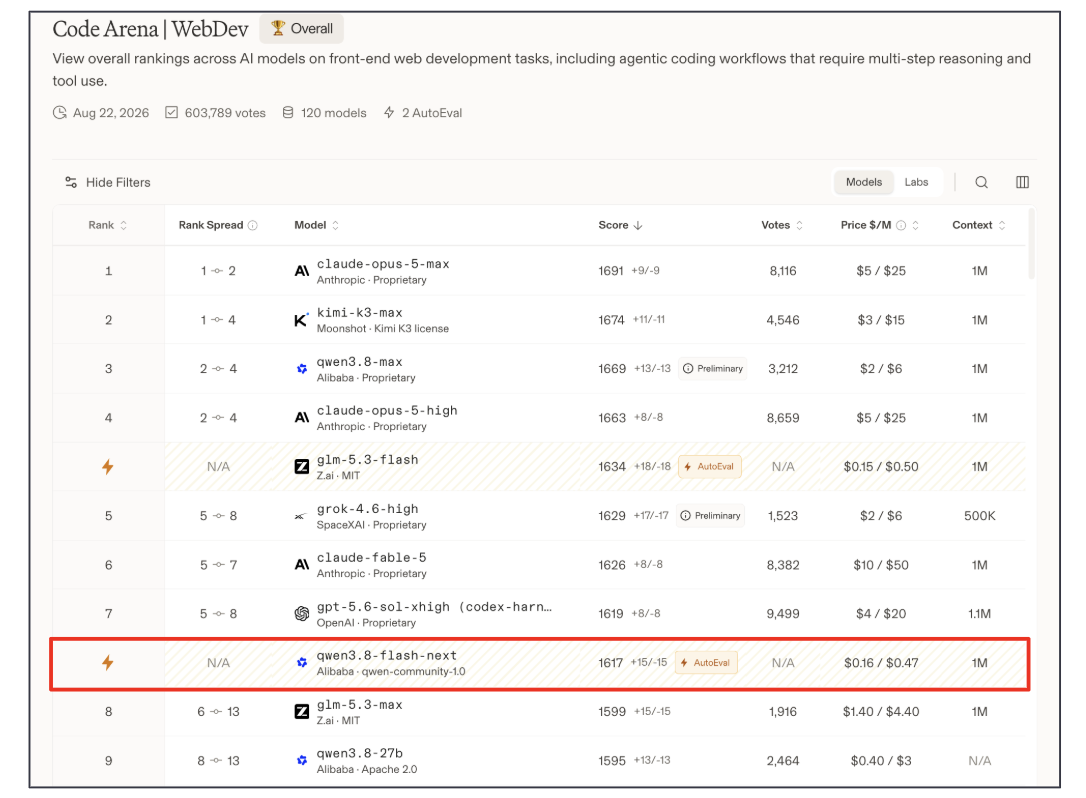
Now, what about the actual performance of "Qwen3.8-Flash-Next", which has pursued efficiency to such an extent? A third-party evaluation is necessary, so let's look at the leaderboard below (3).

                 Arena

"Qwen3.8-Flash-Next" is positioned around 8th place, and naturally, it sits above Opus4.6. As expected, the performance of this model is incredible. The models ranked higher than it are all super-large frontier models, with parameter counts exceeding 1 trillion. "Qwen3.8-Flash-Next", which achieved the ability to break into the top ranks with only 125 billion parameters, can truly be called a magnificent AI. Also, since this AI is a preview version for evaluating "Qwen4," I am already incredibly excited to see what kind of performance the next-generation "Qwen4" will achieve.


What did you think? This was the first time I fully covered a Chinese-made AI. I felt it was fantastic because a detailed technical report was published, allowing for more concrete technological discussions. Classic technologies like attention mechanisms and residual connections are very meticulously combined, highlighting the high technical prowess of the development team. I believe researchers around the world engaging in AI development moving forward will undoubtedly reference this report, and it will likely further accelerate the development of AI worldwide. We really can't take our eyes off AI right now.


At Toshi Stats, we plan to continue challenging ourselves to explore the mechanisms of AI. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) Qwen3.8-Flash-Next: A New Architecture, Towards Ultimate Cost-Efficiency, 26 Aug 2026, Alibaba Cloud
2) Deep Residual Learning for Image Recognition, 10 Dec 2015, Kaiming He, Xiangyu Zhang, Shaoqing Ren, Jian Sun, Microsoft Research
3) Arena

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Exploring Tabular ICL: High-Precision Prediction Models for Small Datasets

Recently, I've been hearing a lot about models that perform tabular prediction using ICL (In-Context Learning). In addition to Google TabFM, which I introduced last time, several startups have also released ICL models. Therefore, I would like to compare them with LightGBM, a machine learning model I frequently use, to see where their strengths lie. Let's dive right into the details.


1. Applying ICL (In-Context Learning) to Tabular Data

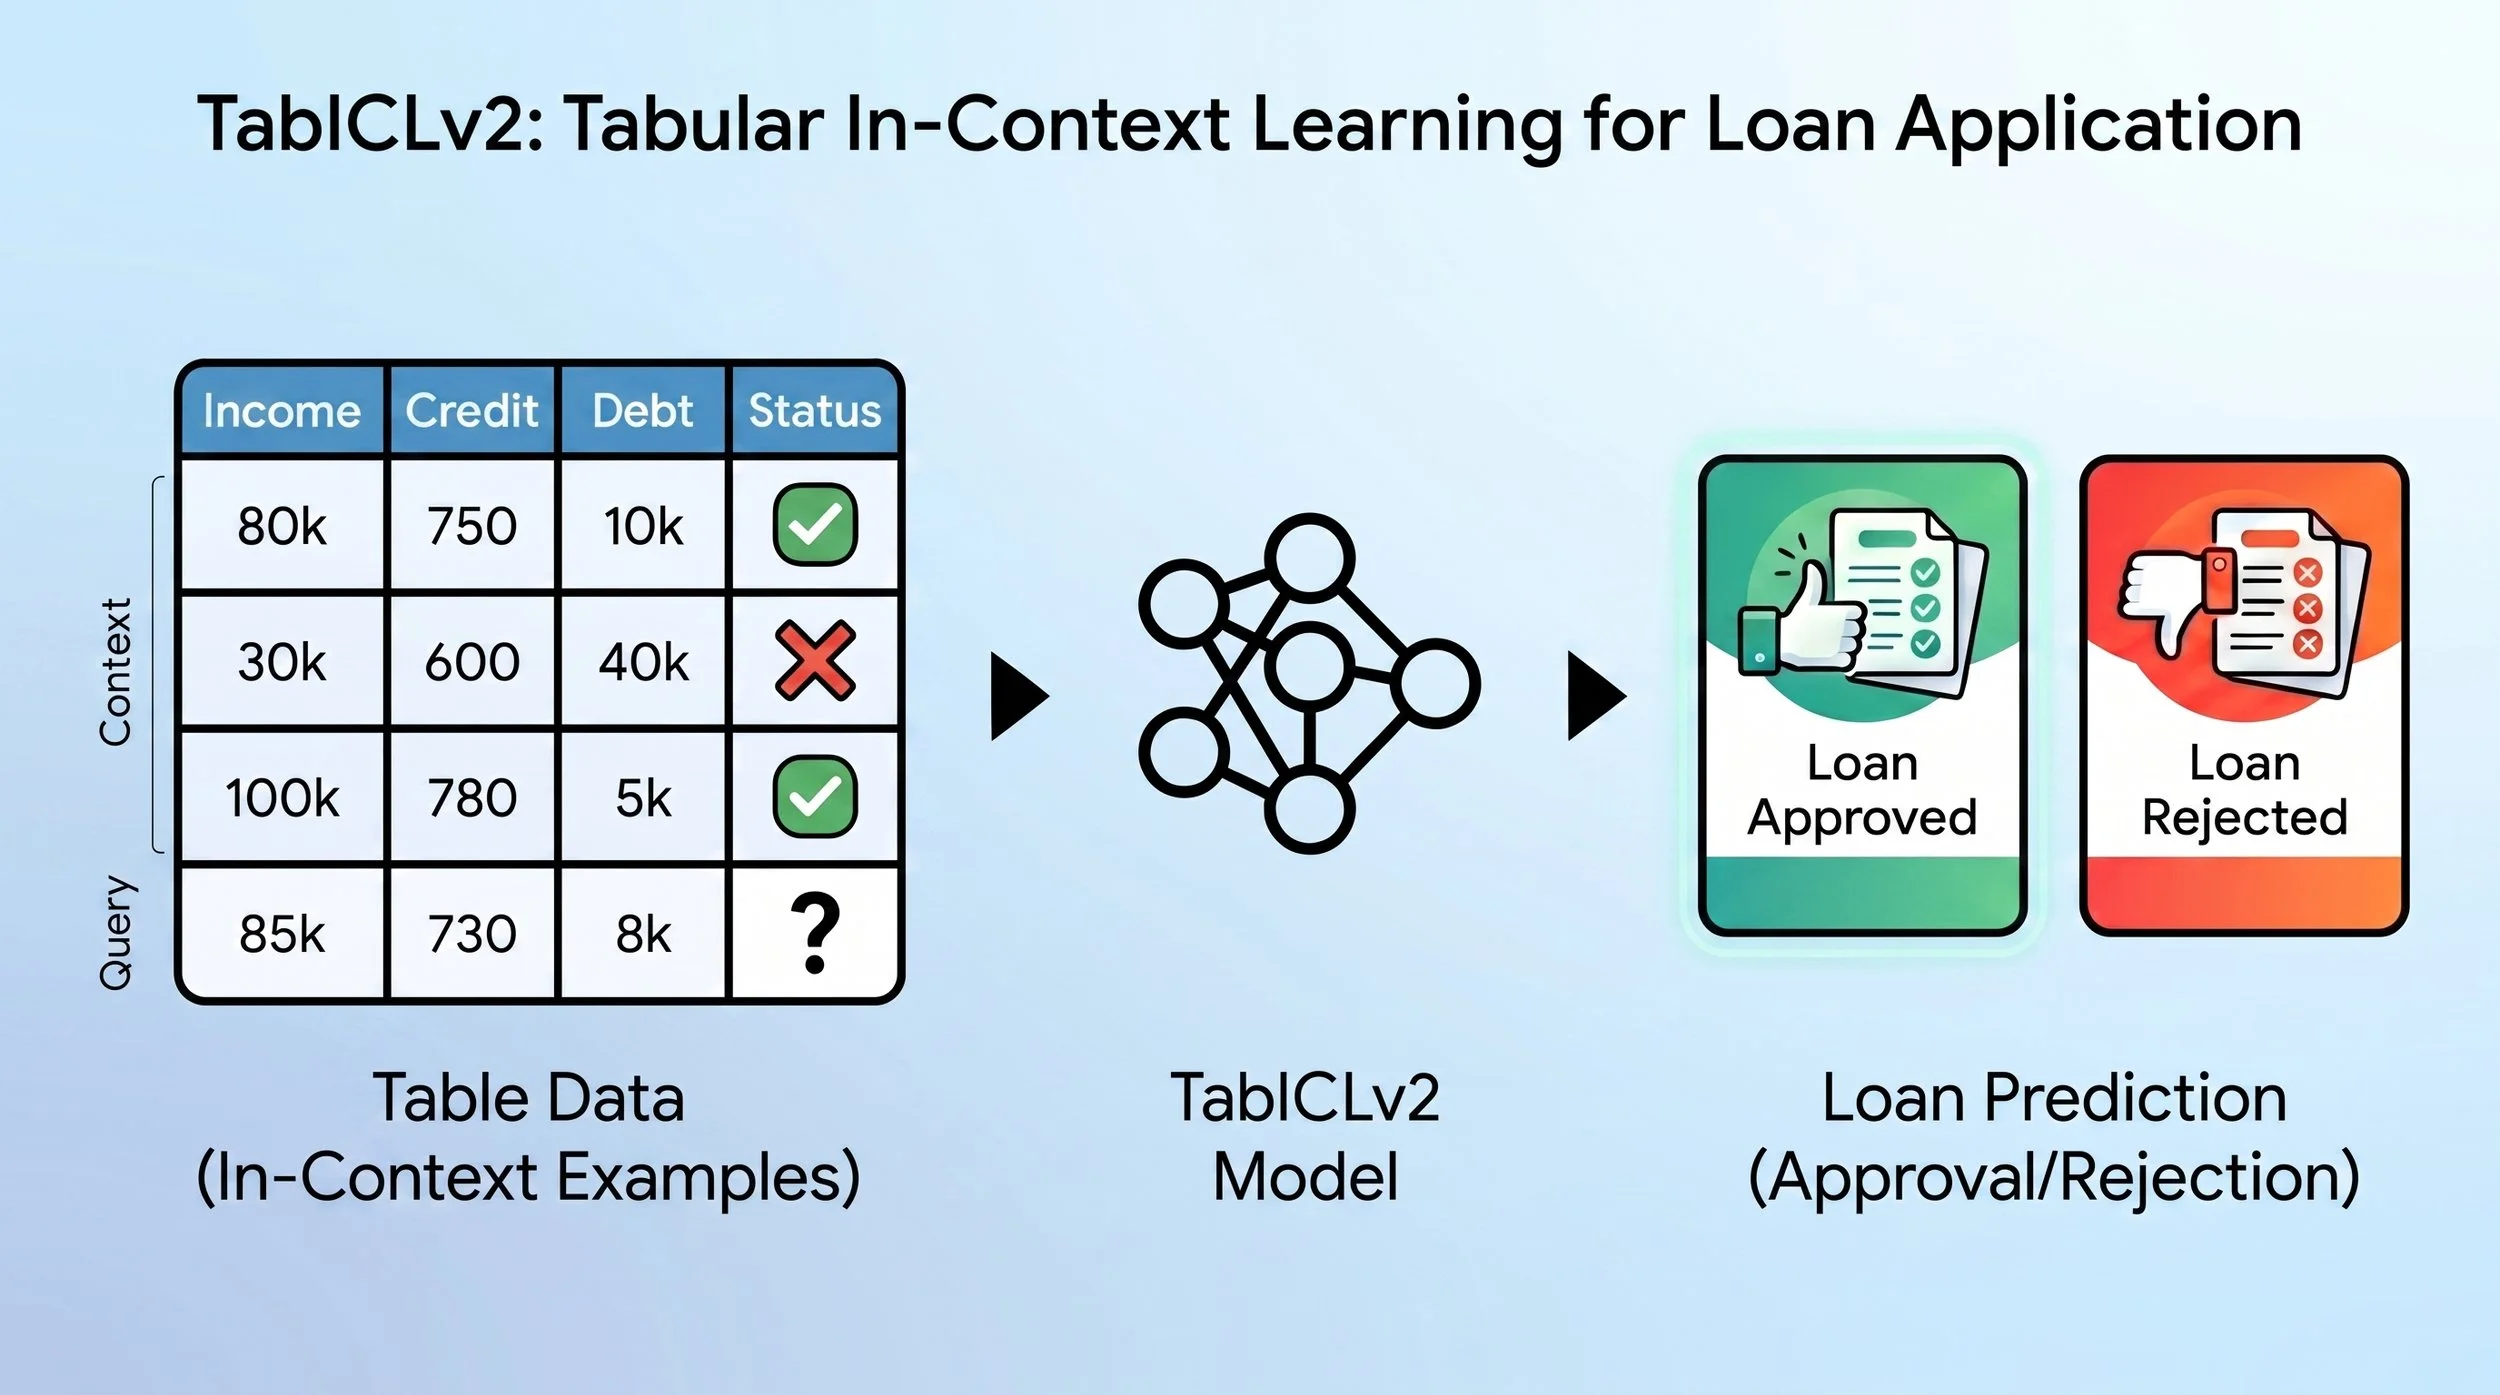
The selling point of ICL models is that they can be used straight out of the box without training. The chart below should make this specifically easier to understand.

‍  ‍      Applying ICL (In-Context Learning) to Tabular Data

First, regarding the input data, the context is key. This involves gathering data with already known outcomes and showing it to the model beforehand to prepare it for prediction. Next, the samples (queries) for the actual prediction are input, and the prediction is executed. In reality, as shown in the diagram, the context and the samples (queries) are combined and input into the ICL model as one large prompt. Since we will be predicting approval or rejection based on loan application data this time (3), it will be a binary classification prediction task. Now, let's actually experiment with some data.


2. Comparison between ICL Models and LightGBM

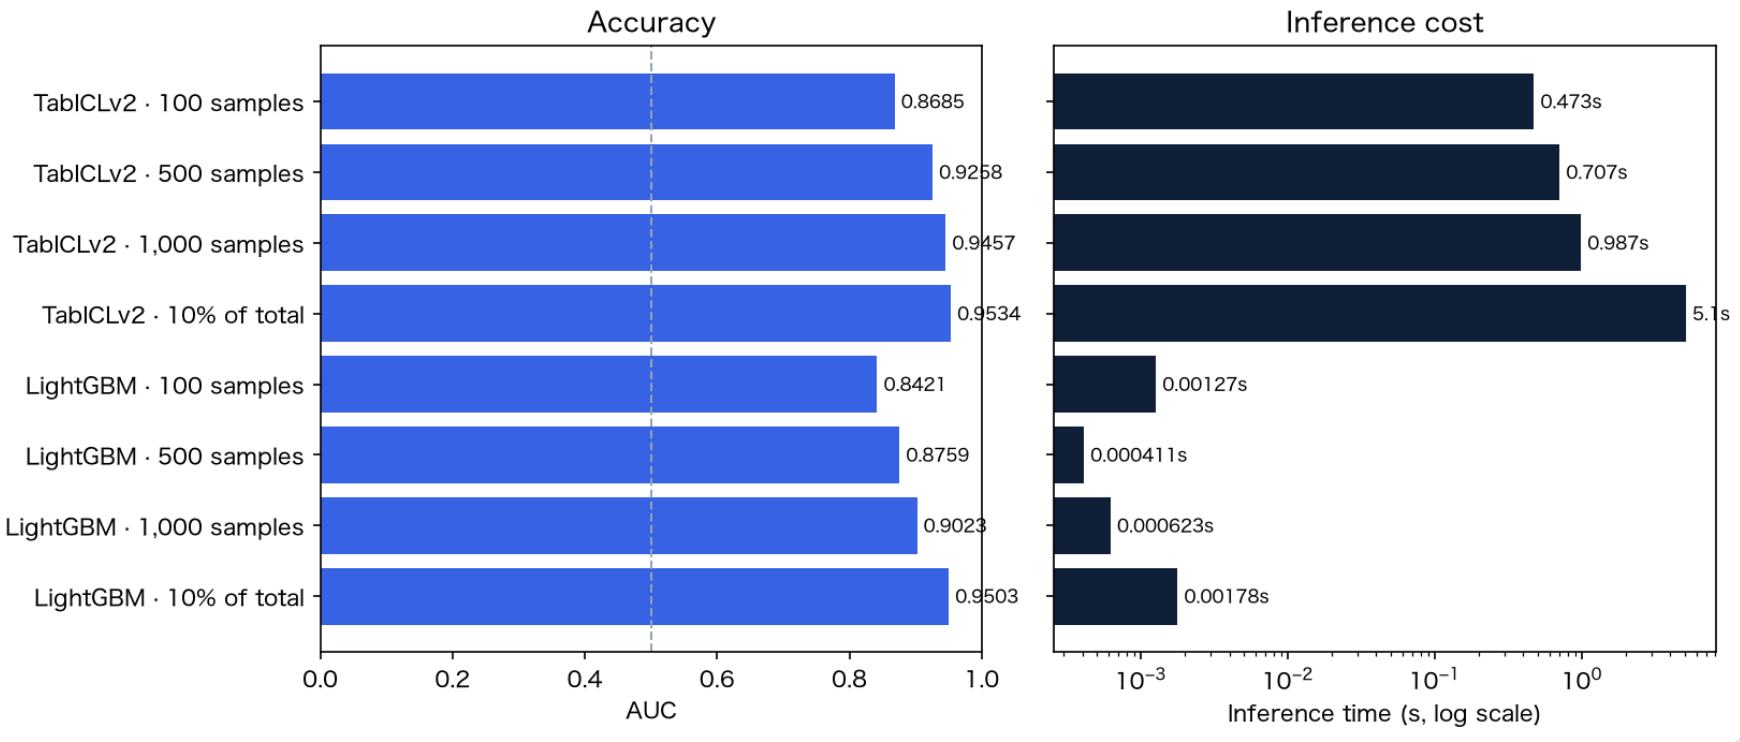
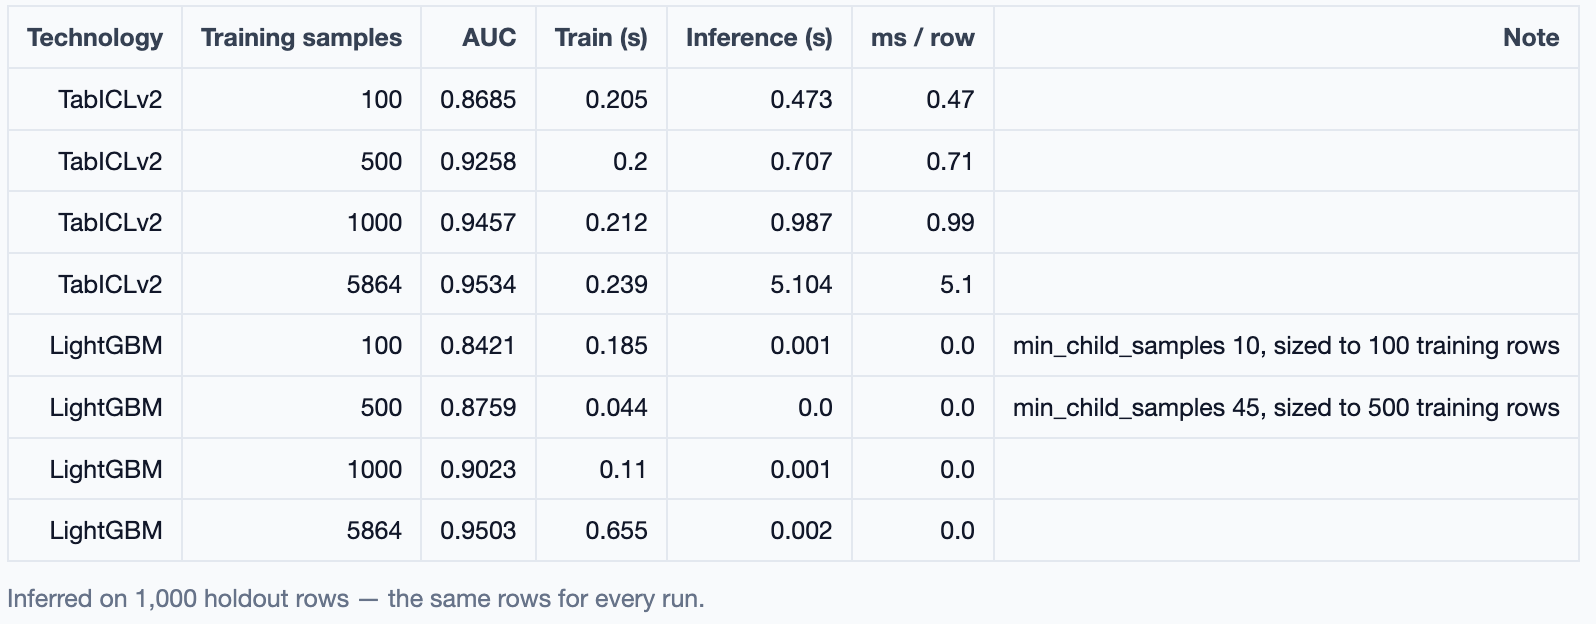
For this experiment, I used a model called TabICLv2 (1). It is lightweight, easy to use, and its availability under the BSD 3-Clause License is also appealing. I compared it with LightGBM (2), a gradient boosting machine learning model. I have been using LightGBM as my first-choice model for over five years. I'm excited to see how close TabICLv2 can get to this LightGBM. By the way, the hardware used this time is a MacBook Air M4 with 24GB of RAM. The results are as follows:

‍  ‍             TabICLv2 vs LightGBM

The most noticeable thing is the high accuracy of TabICLv2 with a training dataset of only 100 samples. While LightGBM requires model training before prediction, with 1,000 samples or fewer, the training data was simply too small, causing it to fall behind TabICLv2. The high accuracy with a small number of samples is due to the fact that TabICLv2 is a foundation model and has been thoroughly pre-trained. Because it possesses the necessary information for prediction from the start, it can predict without any issues even with a small number of samples. It's amazing!

‍  ‍               TabICLv2 vs LightGBM

However, in terms of cost (computation time), LightGBM has the advantage. When performing ICL (In-Context Learning) with TabICLv2, you end up inputting a large amount of context every time you make a prediction. If the context is around 1,000 samples, there is no particular problem in practice, but at 5,000 samples, the computation time becomes noticeable. Also, this time, the number of prediction samples is fixed at 1,000. In actual business operations, it often exceeds 10,000, so it is presumed that TabICLv2 would be difficult to use in cases requiring real-time processing.


3. When Should You Use an ICL Model?

Based on the above experimental results, I recommend trying out ICL models in the following cases:

  • When you want to execute predictions with a small amount of data on hand      The situation of "not being able to do anything until data accumulates" is often called the cold start problem. Immediately after launching a new product in finance, naturally, there is no data. In such cases, managing credit risk used to be difficult, but it seems ICL models can resolve this issue.

  • When there are no data analysis experts                     Training models like LightGBM still requires specialized knowledge. If you do not have such talent in-house, an ICL model, which completely eliminates the training process, becomes a reliable asset.

Conversely, if you have abundant data and data scientists in-house, LightGBM seems to have the upper hand. After all, having the right tool for the right job is important.


What did you think? Various new ICL-type models are being released, and I'm looking forward to future developments. At Toshi Stats, we plan to continue exploring the application of In-Context Learning (ICL) to tabular data. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) TabICLv2: A better, faster, scalable, and open tabular foundation model, Jingang Qu, David Holzmüller, Gaël Varoquaux, Marine Le Morvan, Feb 11, 2026
2) LightGBM, Microsoft Corporation
3) Loan Approval Prediction,  kaggle, Oct 1, 2024

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
The AI Strategy for Churn Prediction: When to Use Open vs. Proprietary Models

Many of you might be struggling to decide which generative AI to choose, caught between high-performance but costly proprietary models (like the famous GPT and Opus) and cost-free open-weights models where it's uncertain just how many tasks they can handle. With Jensen Huang (Founder and CEO of NVIDIA) publishing a report on X titled "Open Weights and American AI Leadership" (1), the momentum supporting open-weights models has grown. Therefore, this time, I would like to actually run both models on a customer churn prediction task and compare which one is better.


1. Gemini 3.6 Flash and Gemma 4

Both models are from Google. Gemini 3.6 Flash (2) is a proprietary model that strikes a great balance between accuracy, speed, and cost, making it the perfect baseline for comparison. Gemma 4 (3) is an open-weights model, divided into five types based on its size. This time, keeping in mind running it on a PC without a GPU like a standard Windows PC, I would like to focus the comparison on the smallest Gemma 4 E2B QAT. This generative AI can even be deployed on small devices like mobile phones, and I am excited to see how well this model can hold its own against a large proprietary model. By the way, the PC I used is a MacBook Air M4-24GB. Let's get started!


2. Generating Special Offer Proposal Texts for Customers

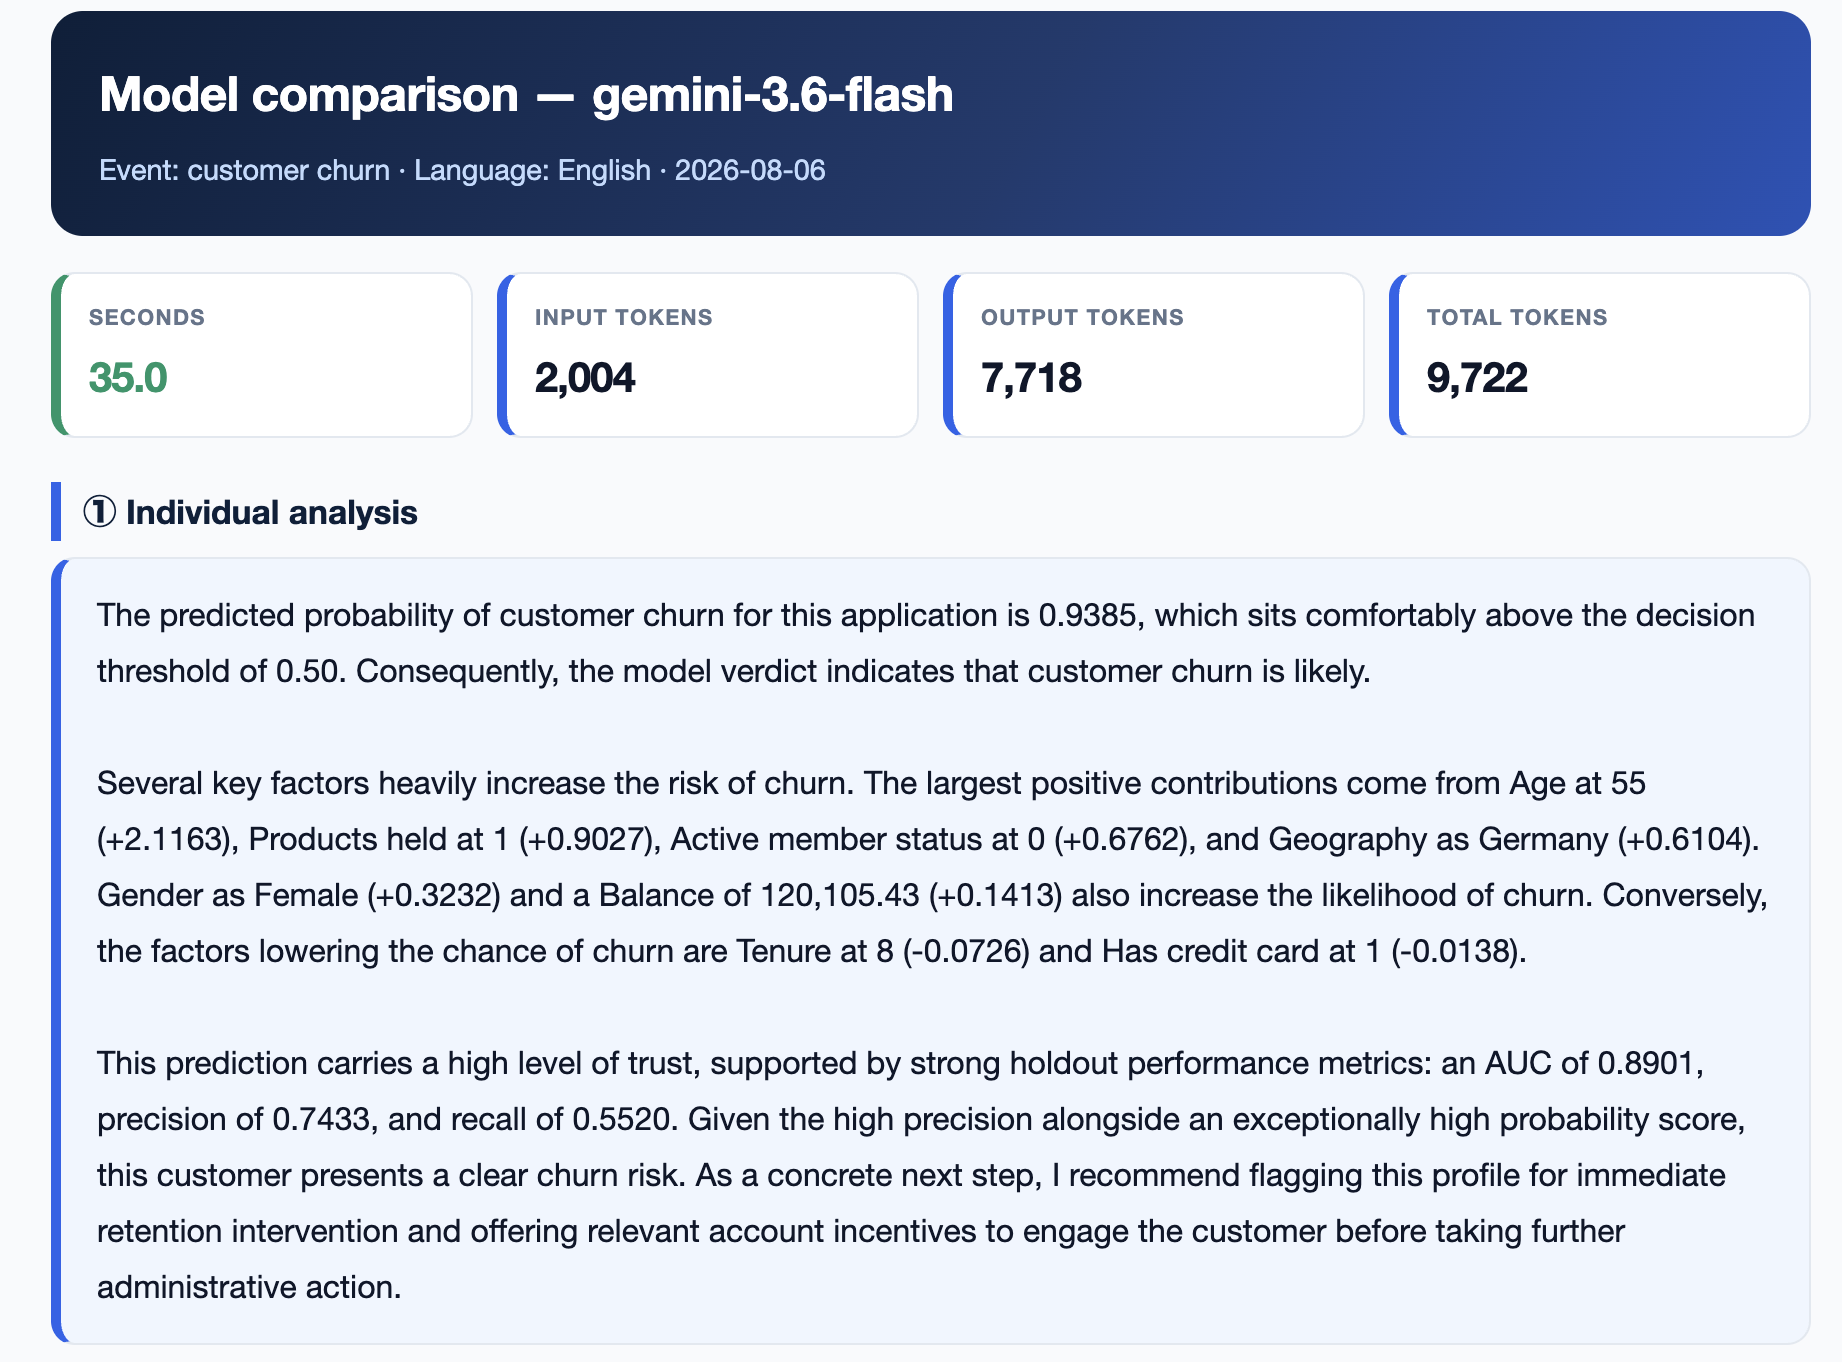
For the first experiment, I would like to actually try proposing preferential treatment to customers with a high probability of churning before they leave. The keys are: 1. Identifying customers who are likely to churn, and 2. Whether we can execute the notification of the preferential treatment offer in a timely manner. Here, we will leave 1 to a powerful machine learning library called LightGBM, and for 2, we will use generative AI to generate both the explanation of the analysis results and the notification letter to compare them. First, let's generate the analysis explanation text using Gemini 3.6 Flash as a baseline. The result is below. It is carefully explained in natural English.

‍ ‍ Analysis Explanation by Gemini 3.6 Flash

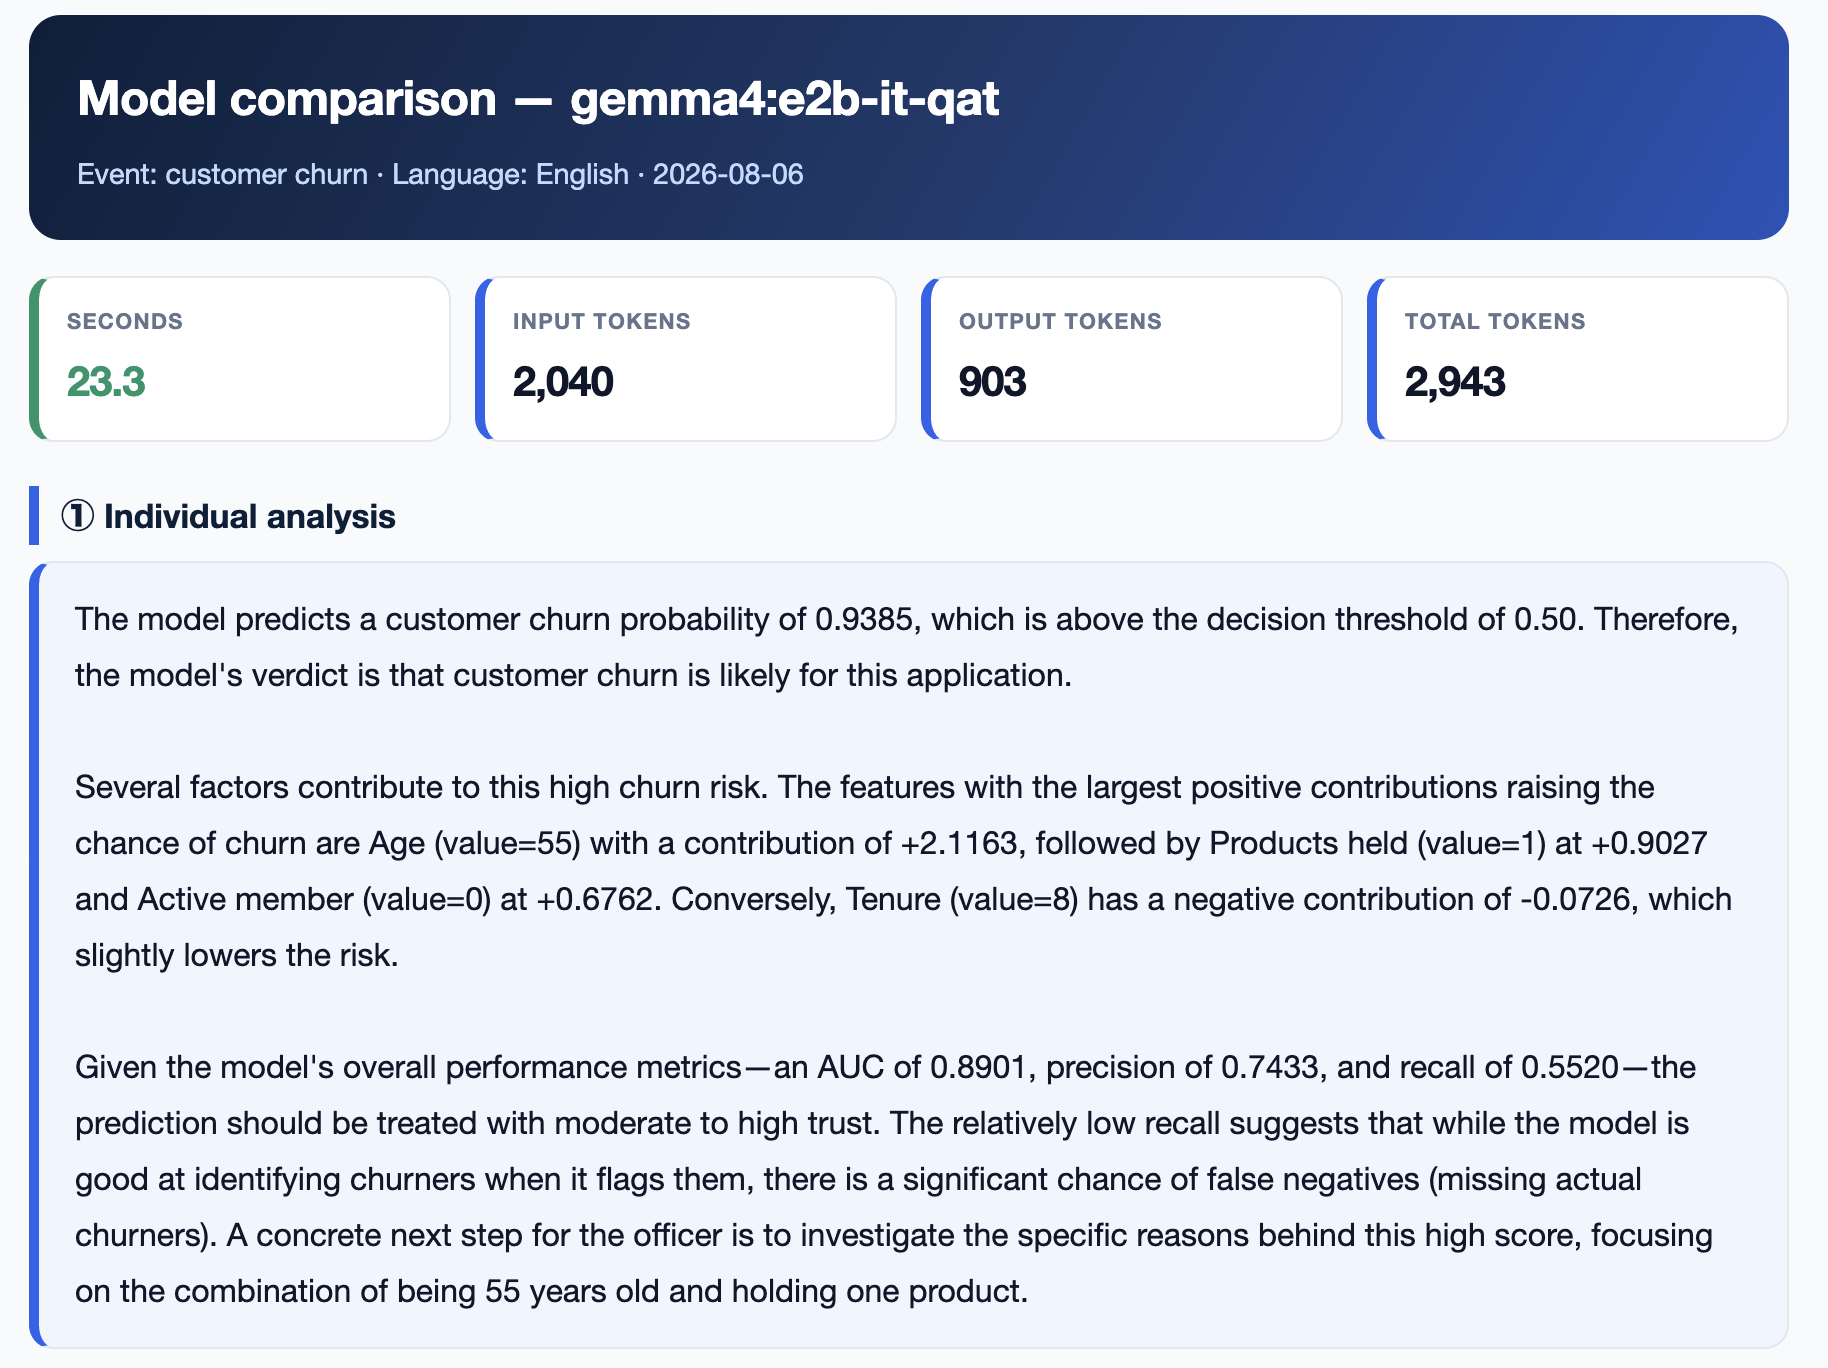
Next, let's try it with Gemma 4 E2B QAT. The results are as follows. This is also written in natural English. It's wonderful. Although it is the smallest model, it functions perfectly well. It looks like it could be immediately used in actual business operations. It is incredibly appreciated that a generative AI of this level can be used for free.

‍ ‍ Analysis Explanation by Gemma 4 E2B QAT

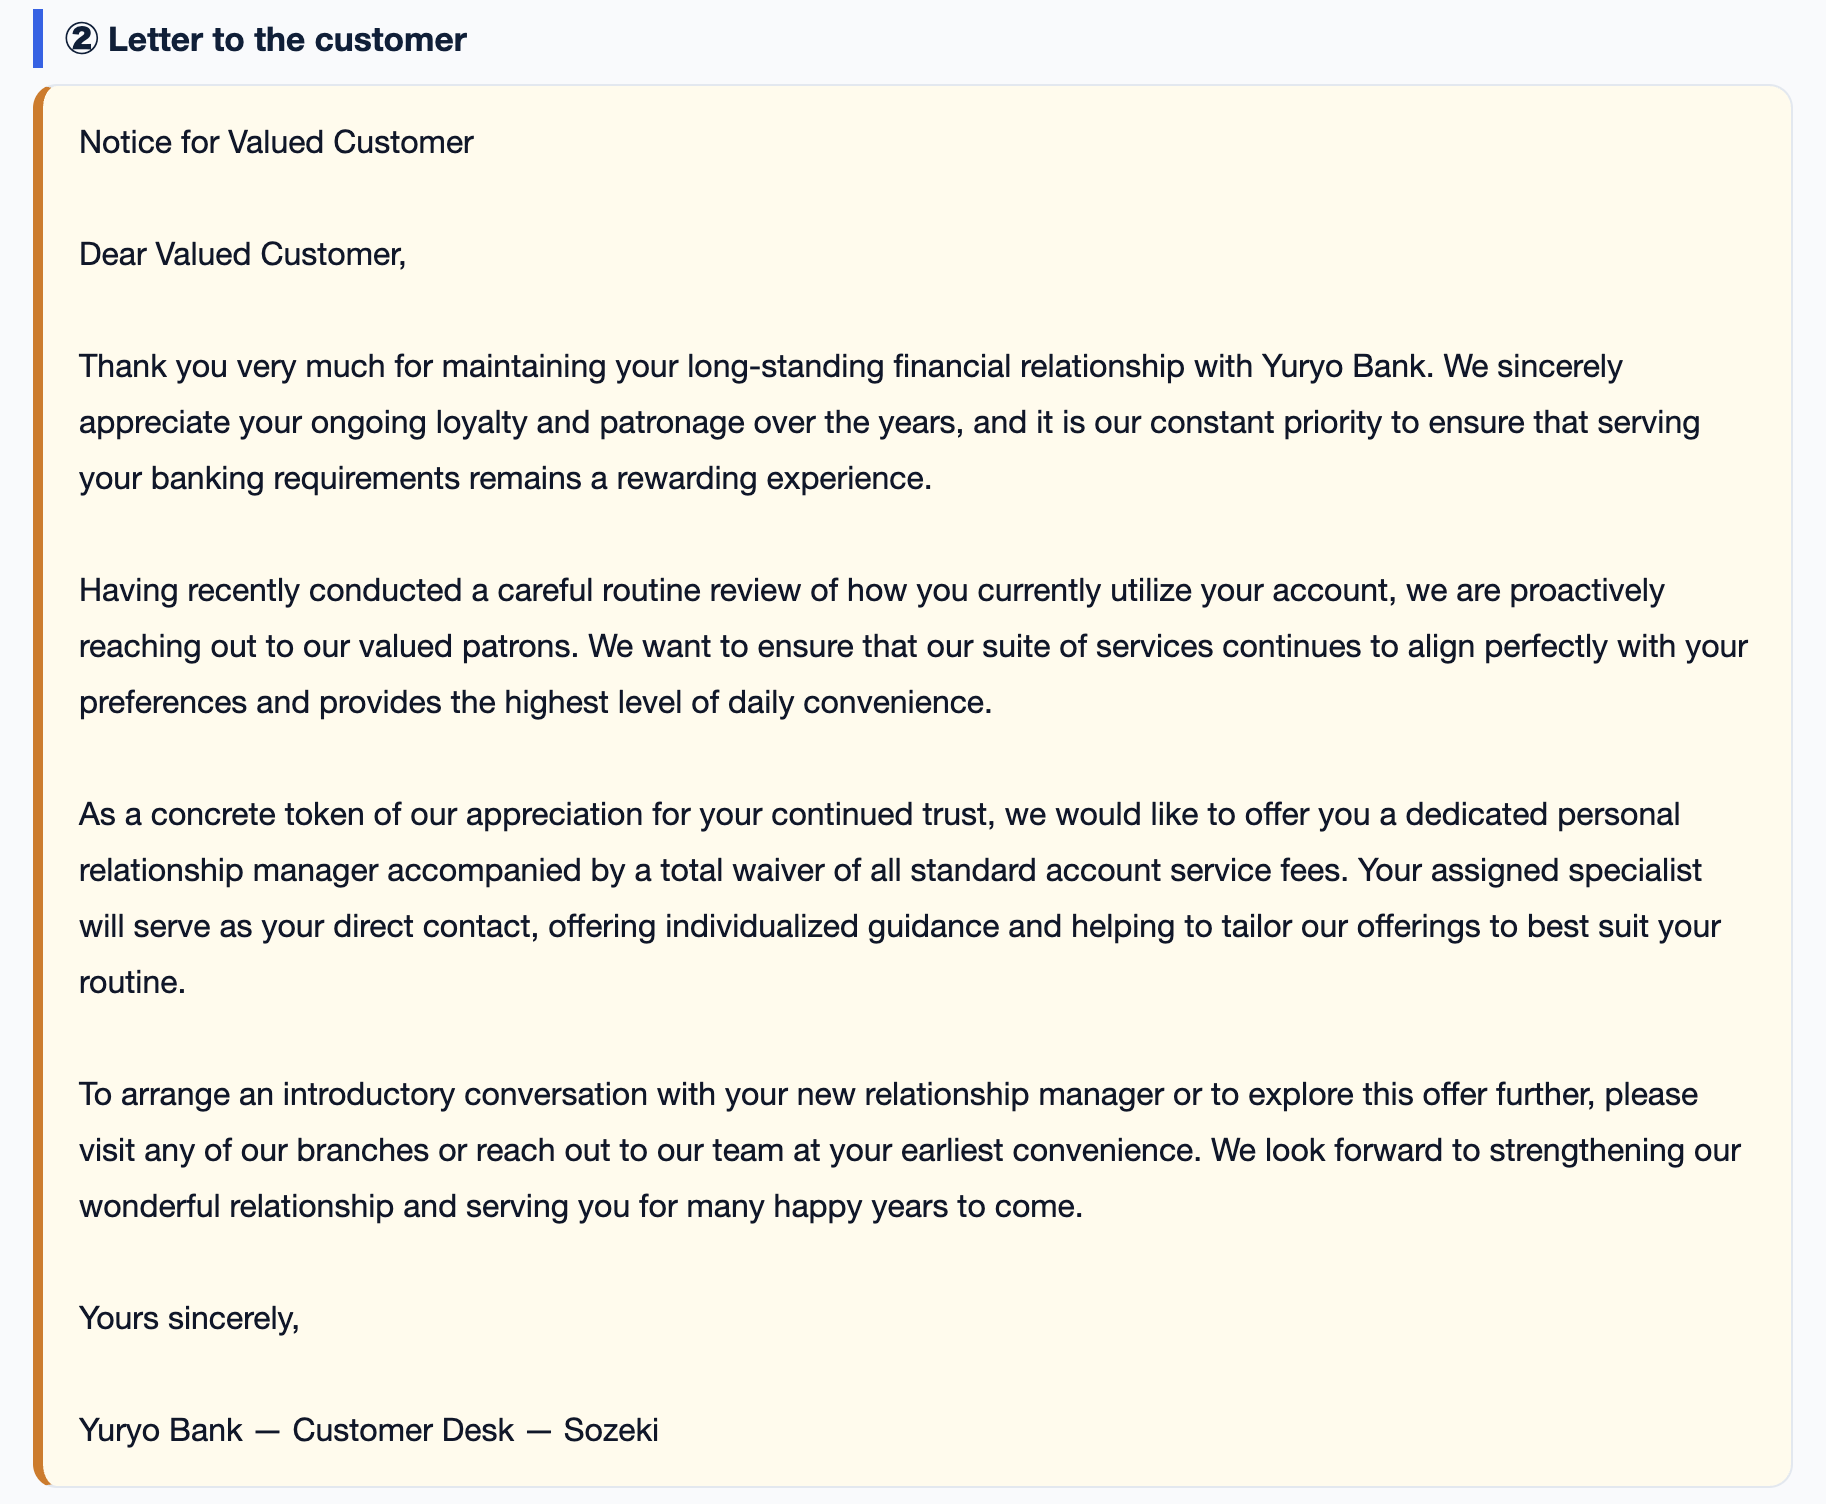
Now, I would like to create a notification letter for preferential treatment to prevent customers from churning. First up is Gemini 3.6 Flash, and as expected, it's perfect.

‍ ‍ Preferential Treatment Notification Letter by Gemini 3.6 Flash

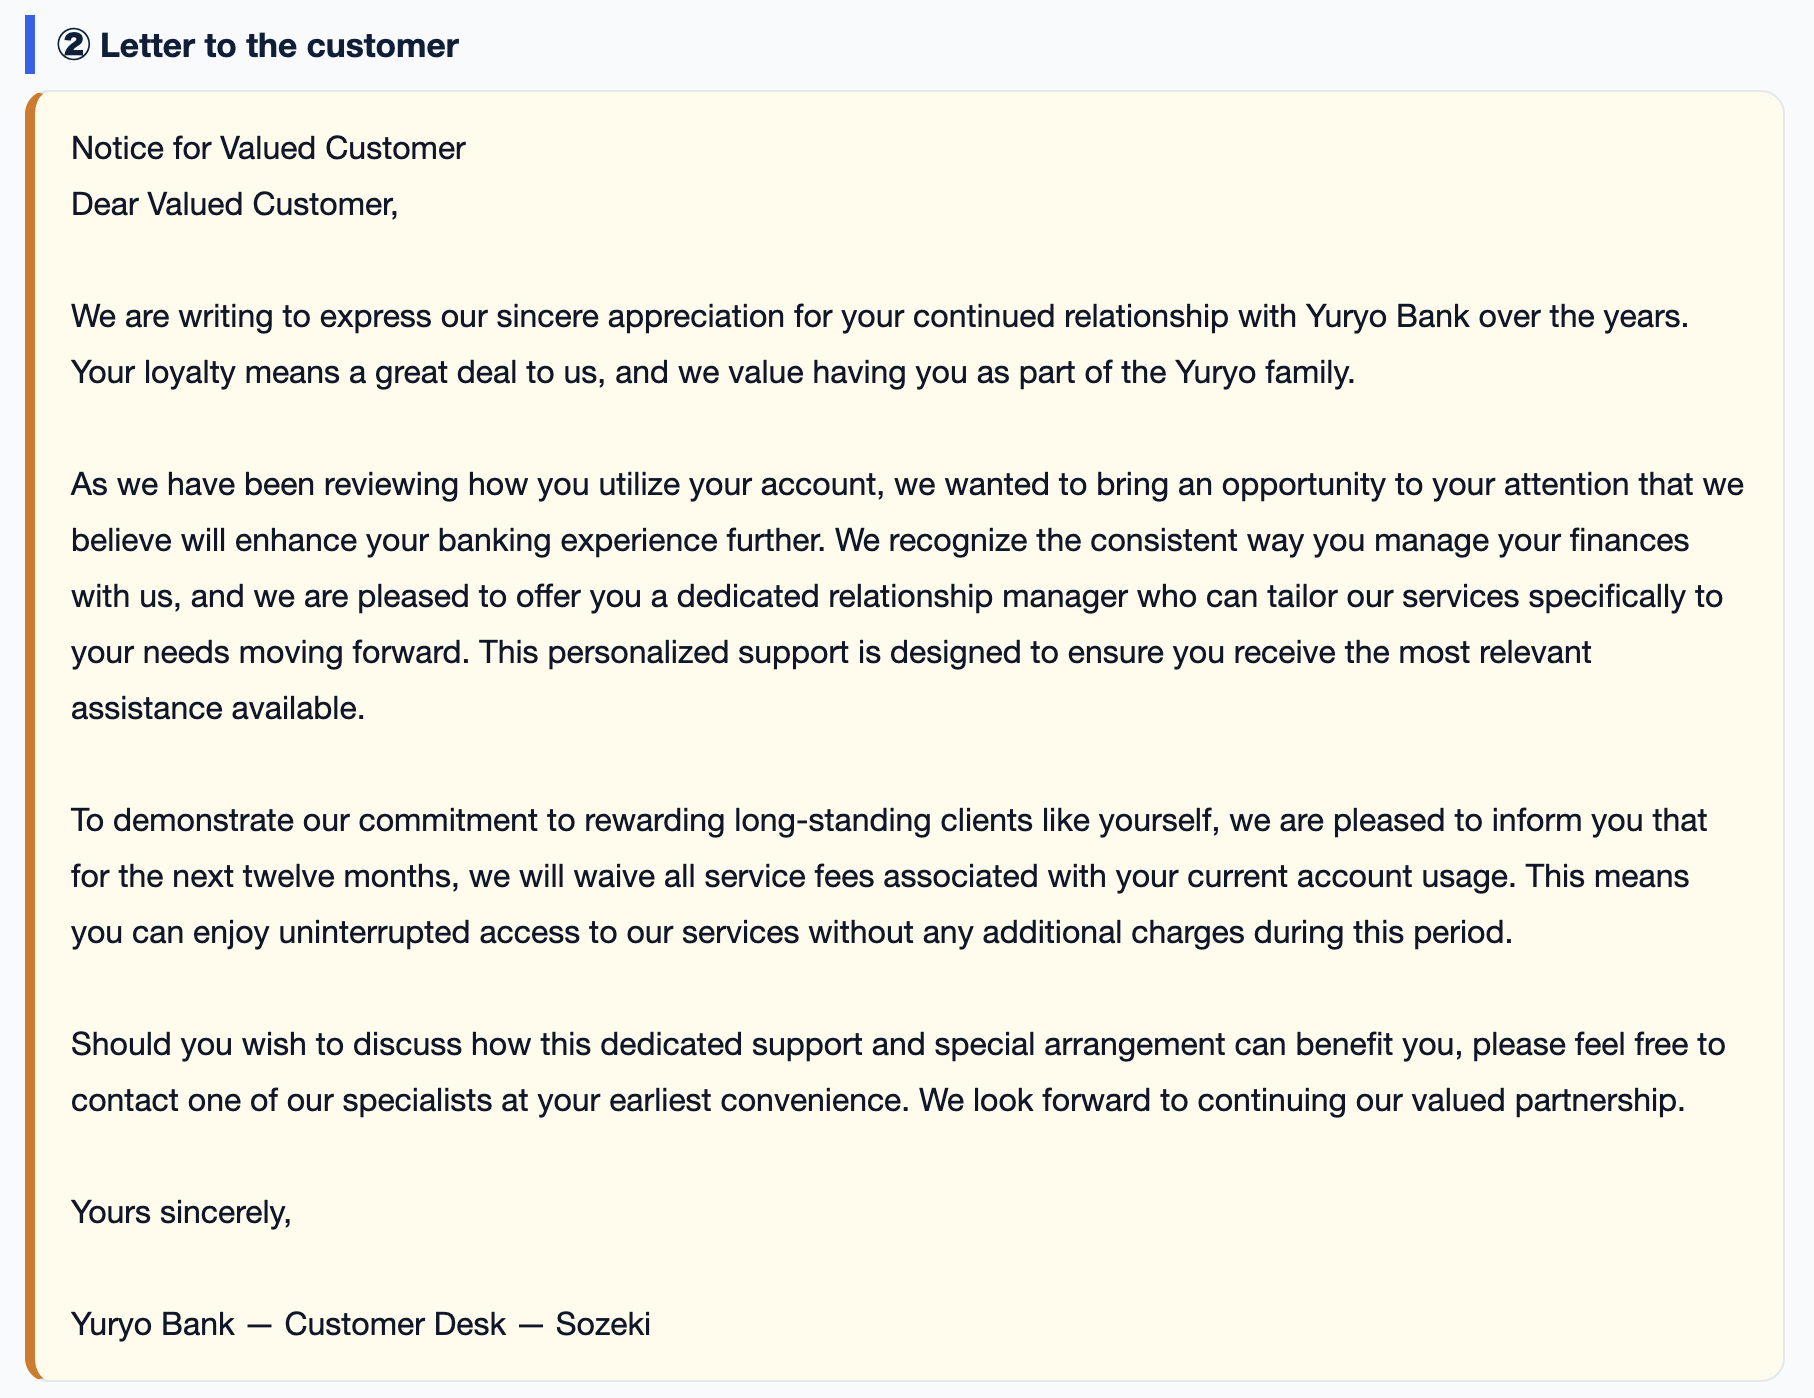
Gemma 4 E2B QAT doesn't fall behind either. This is also written in natural Japanese and has sufficient content. With this, I think it has reached a quality that can be sent to customers. I am a bit moved that even an open-weights model can do this much.

‍ ‍ Preferential Treatment Notification Letter by Gemma 4 E2B QAT

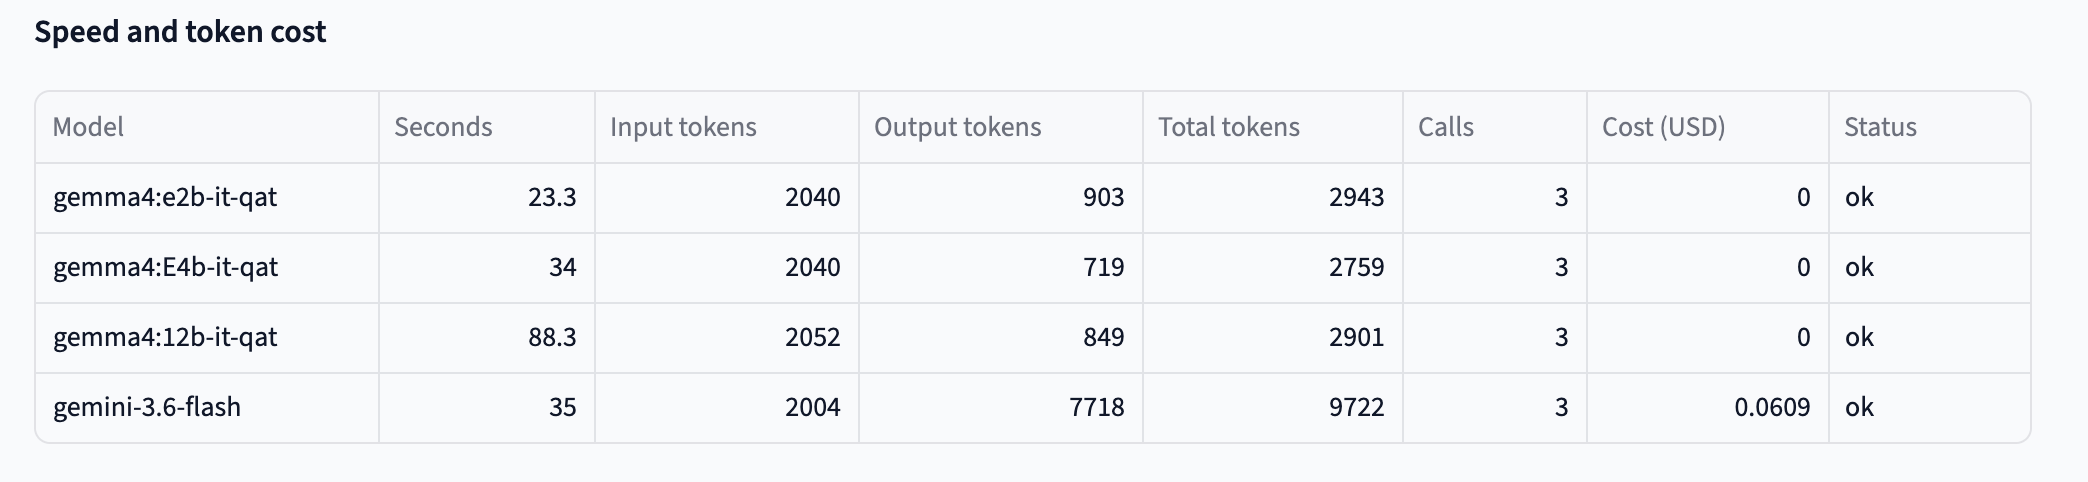
I have summarized the results here. I have added two open-weights models with slightly larger parameters here. The time taken for computation inevitably gets longer as the parameters increase. By the way, even if you use these models, naturally, there are no usage fees. That is the wonderful thing about open-weights models. Gemini 3.6 Flash is the only proprietary model, and it boasts extremely fast speeds. It fully demonstrated its performance here as well, recording the second-fastest speed. This is a point worth noting. However, it does incur a cost, so budget management is essential when a large amount of processing is required. This cost is calculated based on generating the three types of texts.

‍ ‍ Summary of the Text Generation Task


3. On-Demand Data Analysis

This time, I would like to provide data to the generative AI and execute data analysis. I will visualize what percentage of the total customers are likely to churn. This is information that marketing personnel would definitely want. Normally, this is a task performed by data scientists who can write Python, but this time I want to challenge how far we can take data analysis by giving instructions via prompts and having the generative AI generate the Python code. First, let's try it with Gemini 3.6 Flash. As expected, it turned out perfectly.

‍  ‍     Visualization of Customer Distribution by Gemini 3.6 Flash

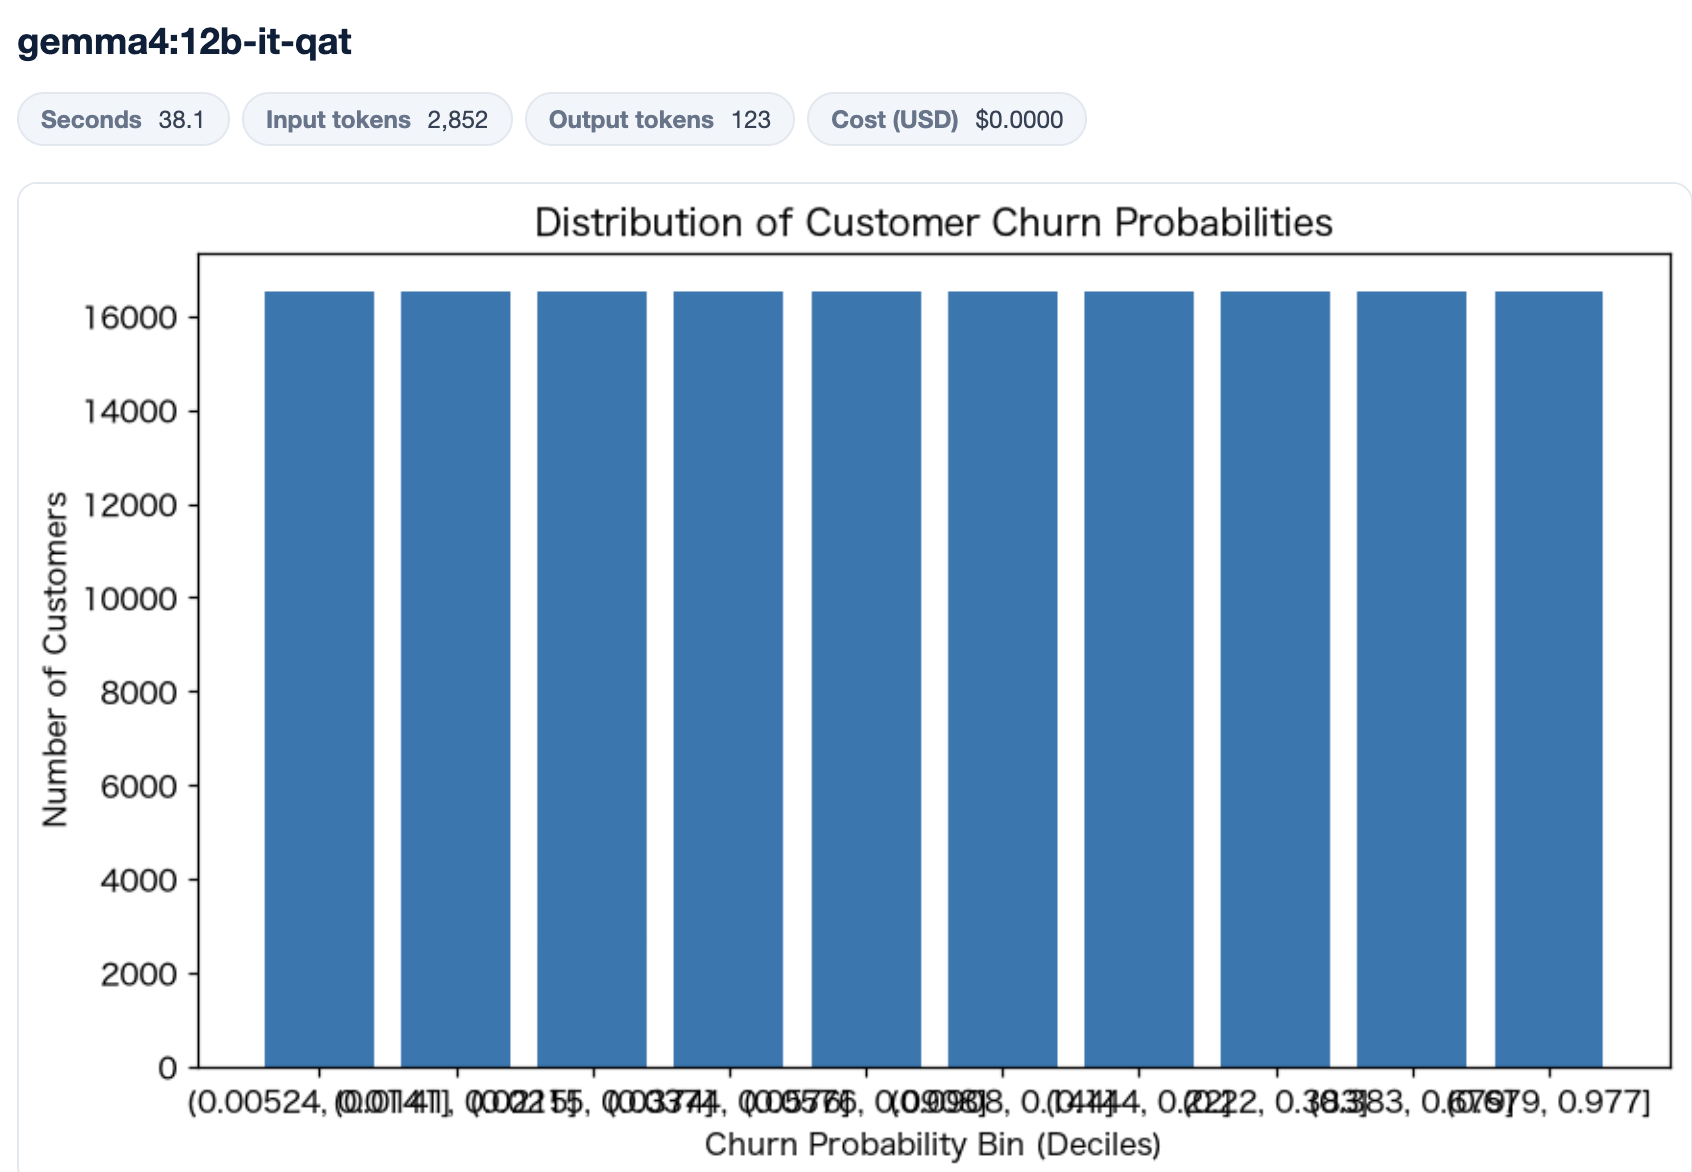
Next, I wanted to show the results for gemma4:E2b-it-qat, but unfortunately, it did not succeed after 3 attempts. It seems to have been a somewhat difficult task for a small generative AI. This time, all the prompt instructions were fixed and unchanged, but I think there is a possibility that even a small generative AI could succeed with some adjustments. The larger gemma4:E4b-it-qat worked out well, but gemma4:12b-it-qat failed as shown below. Code generation tasks might be quite a heavy burden for gemma4.

‍  ‍       Visualization of Customer Distribution by gemma4:E4b-it-qat

‍  ‍         Visualization of Customer Distribution by gemma4:12b-it-qat


What did you think? As we found out from this experiment, the cases where you would want to prioritize using an open-weights model are:

  • When handling confidential information and you want to complete the processing entirely on a local PC.

  • When budget management is strict and you cannot bear the costs.

  • When the task is centered around text generation.

Code generation tasks might reach a practical level if the prompts are adjusted. We at Toshi Stats will continue to take on these challenges. Stay tuned!

You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Open Weights and American AI Leadership, Jensen Huang (Founder and CEO of NVIDIA), July 24, 2026
2) Gemini 3.6 Flash Best for token efficiency in coding, knowledge work, and multimodal tasks, Google DeepMind
3) Gemma 4 QAT models: Optimizing model compression for mobile and laptop efficiency, Google, Jun 05, 2026

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Opus 5 is Here: The Ultimate Game Changer for Product Development

On July 24, 2026, Anthropic released its new generative AI, Opus5 (1). Shortly after that, a discussion about Opus5 by Boris Cherny, the developer of Claude Code, was published on YouTube (2). Because the content was highly informative, I would like to briefly summarize the main points and consider the implications for future product development.


1.Boris's Recommendations

First of all, Boris stated, "Opus5 can run continuously for weeks if you use the auto mode, which allows for continuous operation." In fact, in his own project, Opus5 has already been running for over two weeks and is still ongoing. If it can operate for such a long time, it seems capable of handling quite complex tasks. Since the continuous operation time of generative AI models half a year ago was said to be about 12 hours, this is a dramatic increase. Furthermore, to unlock the potential of Opus5, Boris emphasized two points: "give Opus5 tasks that seem a bit difficult" and "think about how to verify the results and outcomes." It seems better to just try it out and figure things out after observing Opus5's behavior. I felt he was emphasizing that things are quite different from half a year ago, noting things like, "It is not recommended for humans to predict specific instructions in advance because they are not always correct," and "Writing instructions too detailed gets in the way of bringing out Opus5's capabilities."


2.Opus5 is also good at understanding complex data

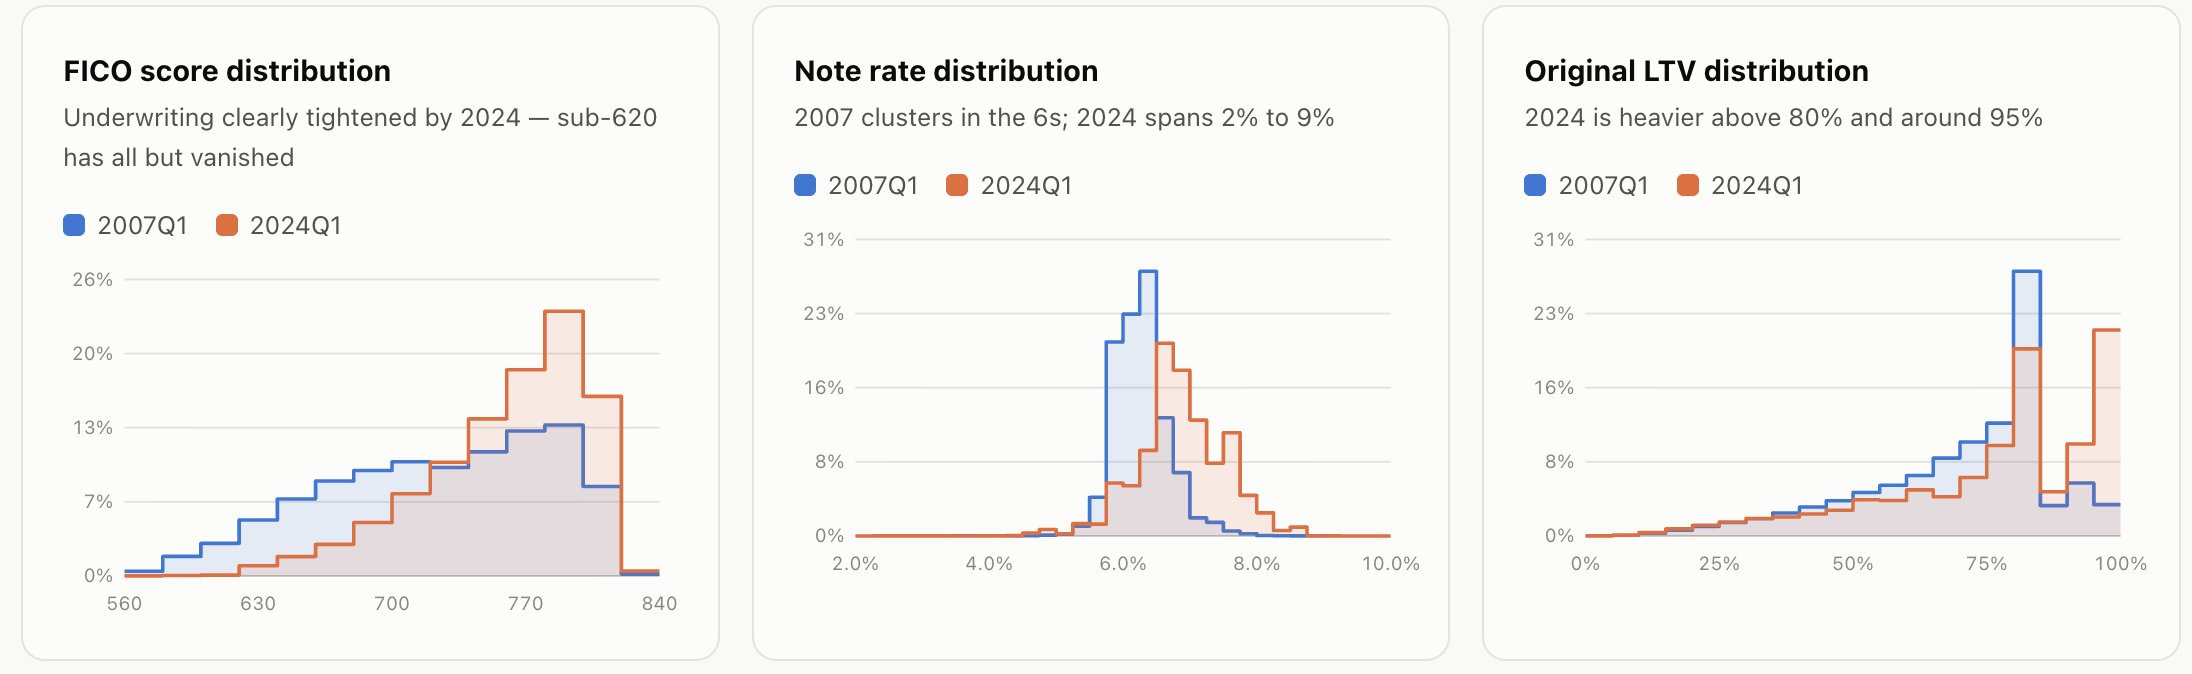
To test the method of "not writing detailed instructions" suggested by Boris, I obtained complex mortgage data, "Fannie Mae Single-Family Loan Performance" (3), and tried analyzing it using Opus5 on Claude Cowork. However, the prompt I provided was minimal, exactly as Boris suggested: "What is in the FannieMaeSingleFamilyLoan? Please explain it using graphs." Nevertheless, the analysis and graphs produced by Opus5 were excellent, as shown below. For example, it output the distribution of FICO and LTV. This makes it easy to compare with 17 years ago.

‍ ‍ FICO and LTV distribution status

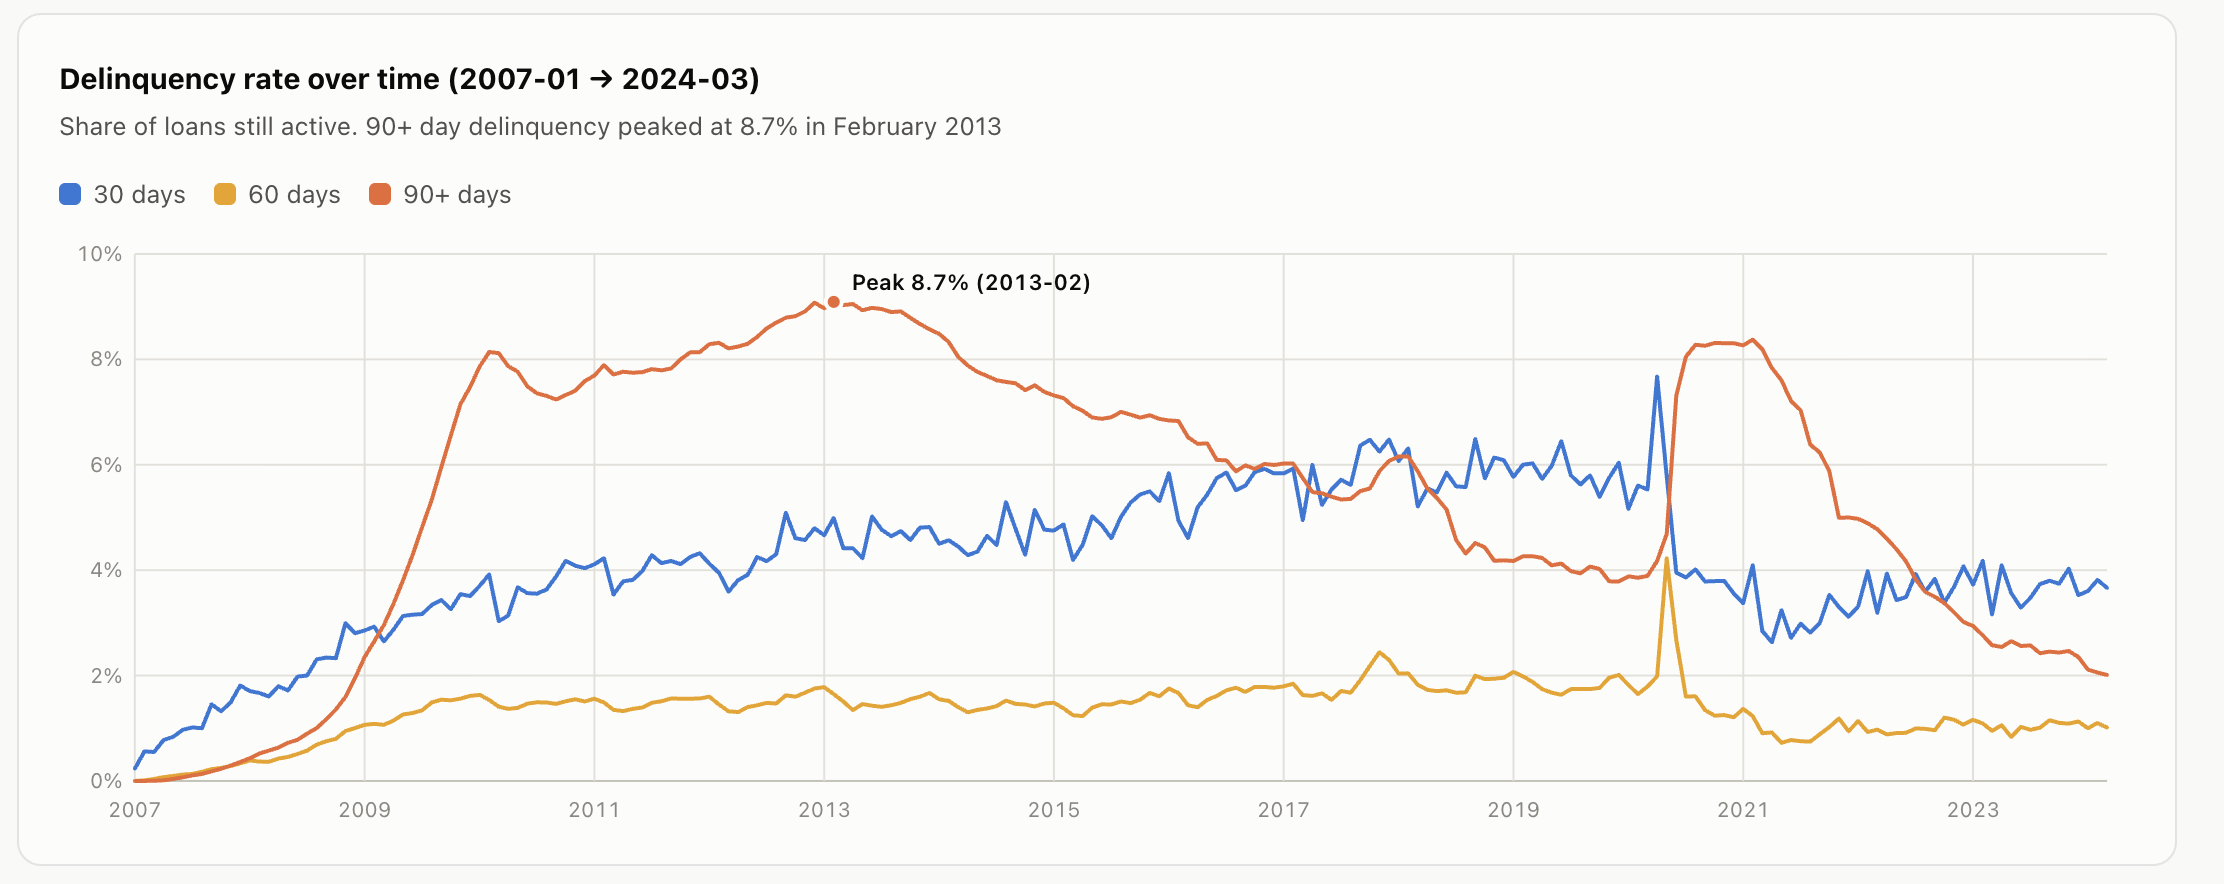
There is also a trend graph for the occurrence of past delinquent loans. Looking at this, you can immediately tell around when delinquencies peaked.

‍ ‍ Transition of delinquency rates

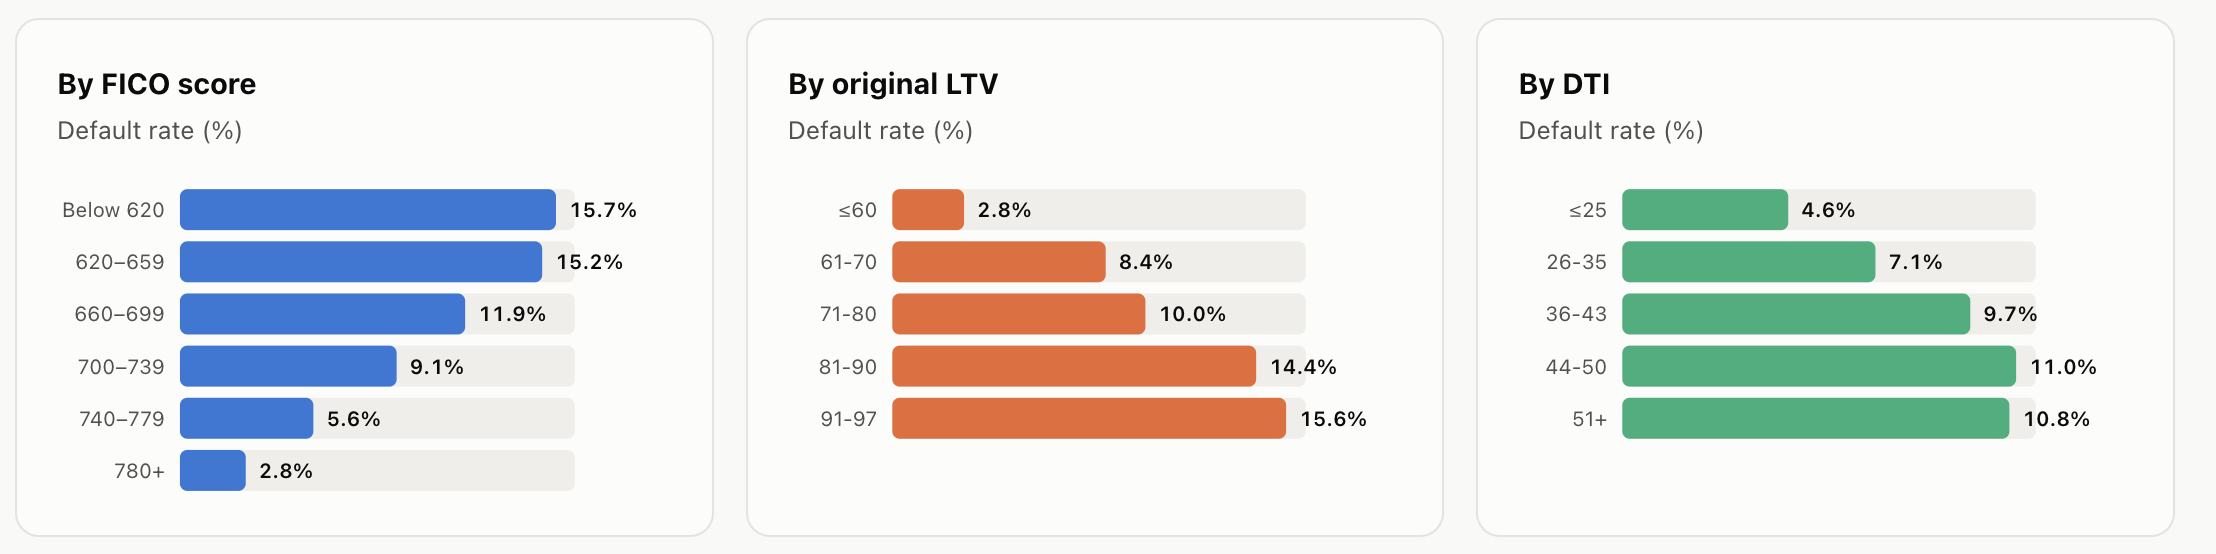
It also beautifully visualizes the relationship between each explanatory variable/feature and the default rate.

‍ ‍ Each explanatory variable/feature and default rate

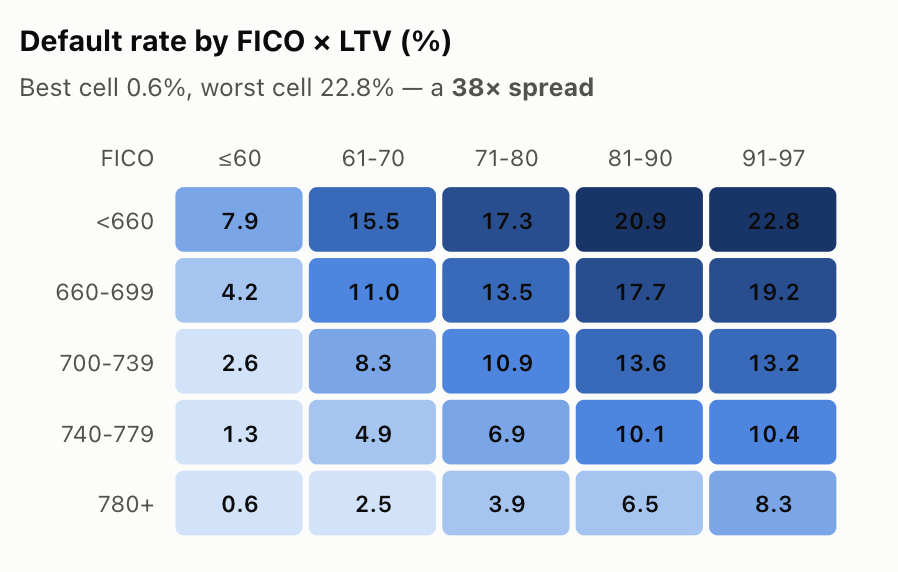
Finally, it visualized defaults using a matrix of the two features most likely related to default: FICO and LTV. It's surprising that Opus5 can do this autonomously to this extent, even though I didn't give any specific instructions for it.

‍ ‍ FICO/LTV and default rate


3.Operating over 1,000 agents

Boris commented that he is "running over 1,000 agents." He mentioned he uses a feature in Claude Code called "Dynamic Workflows." He expressed the view that, theoretically speaking, this means performing test-time computing while automatically optimizing it. Indeed, coupled with the ability to run for long periods, this seems to be the key to improving accuracy. Unfortunately, I have not yet used "Dynamic Workflows," so I would like to give it a try next time. I am really looking forward to it, as it seems it will be highly effective, especially for complex data analysis tasks.


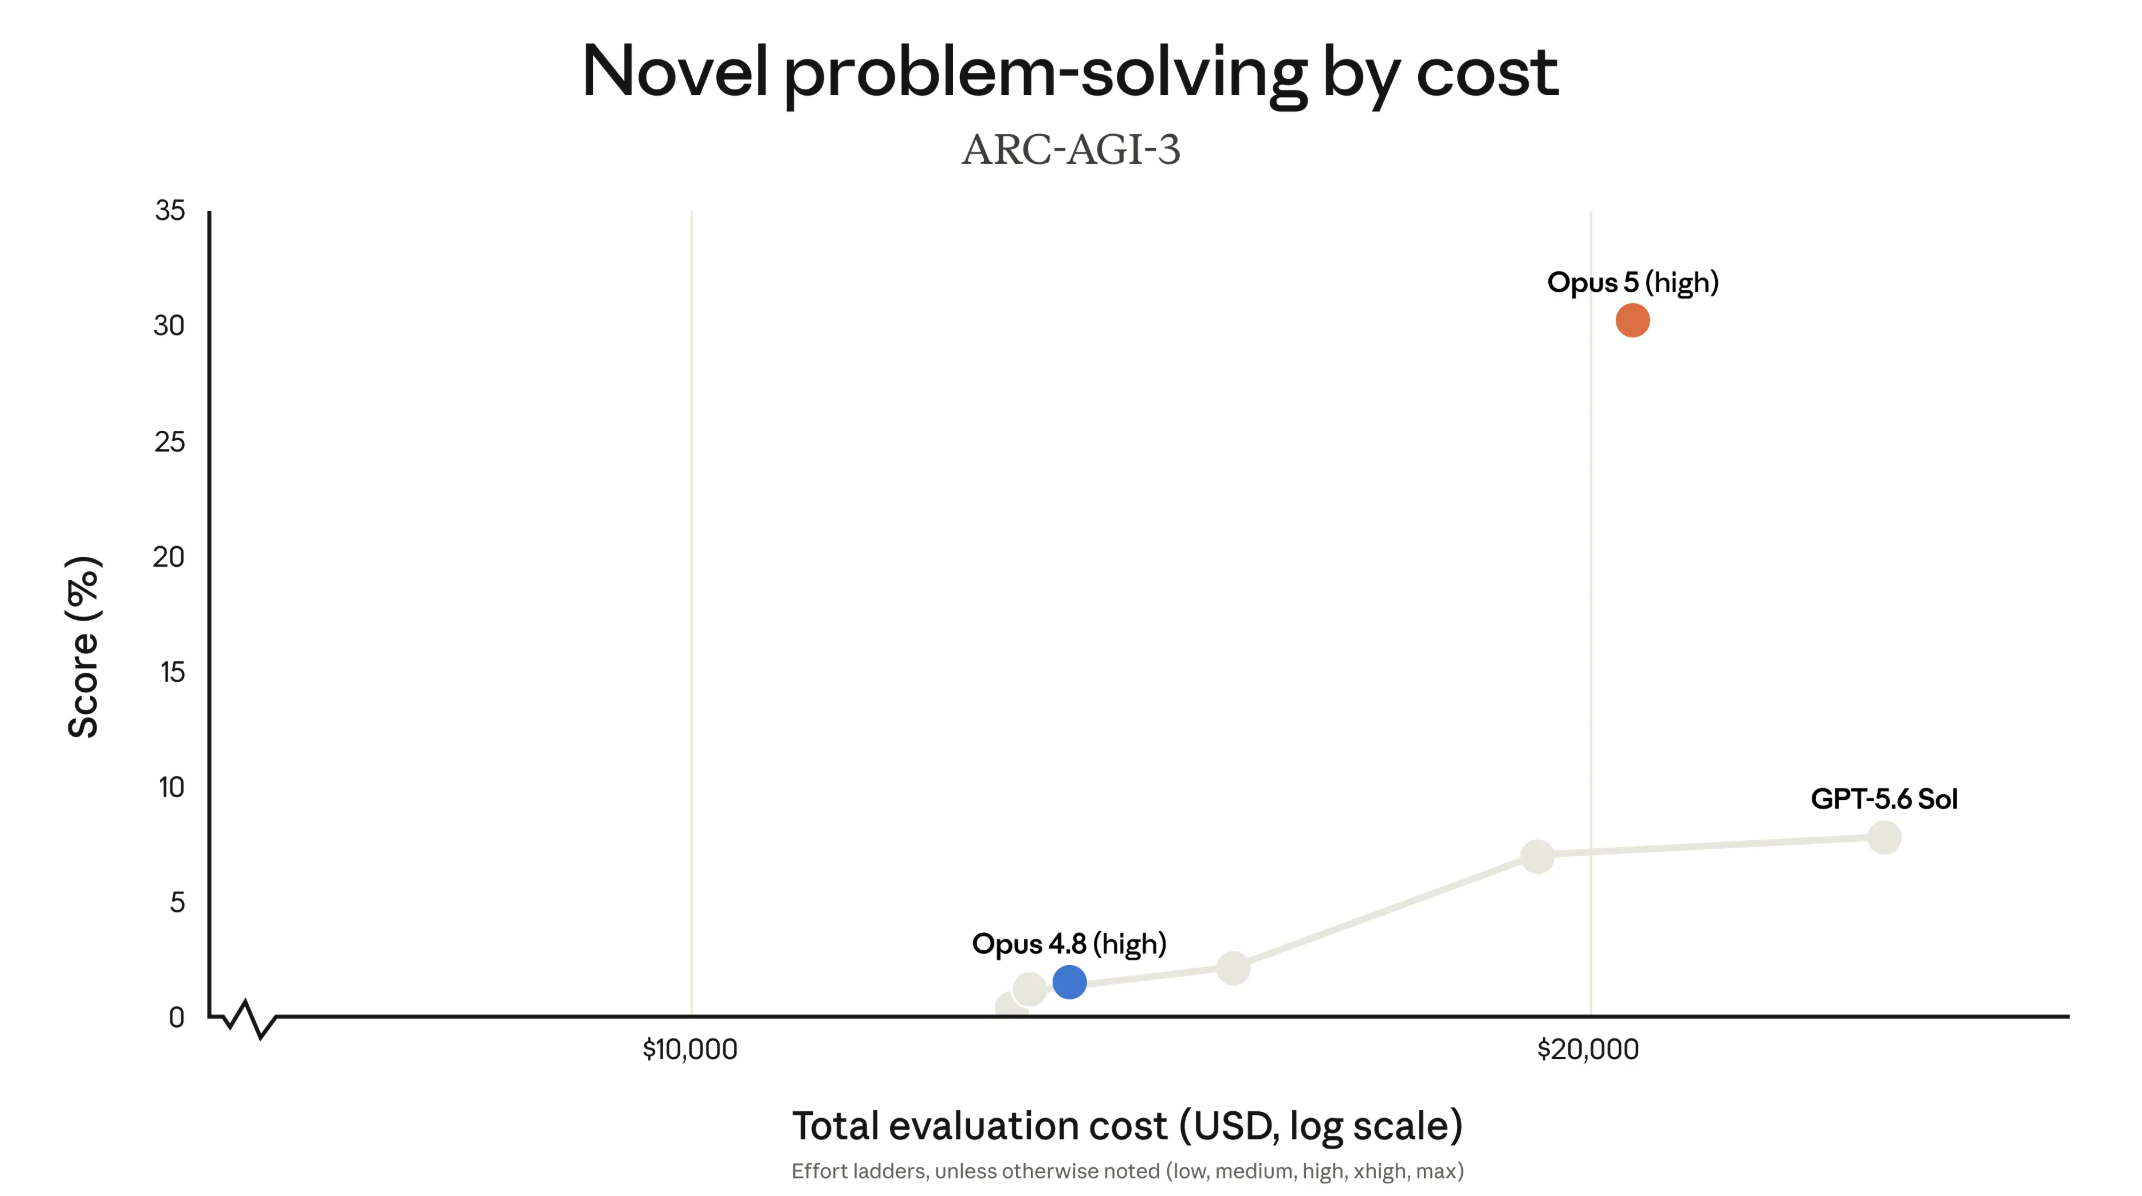
What do you think? Opus5 might indeed possess potential on a completely different dimension from conventional models. What caught my attention is that in "ARC-AGI 3," an evaluation test where the model has to solve unknown problems, Opus5's score has skyrocketed (1). I have high expectations that Opus5 will be able to distinguish and recognize even unprecedented patterns.

At Toshi Stats, we plan to continue tackling various tasks using Opus5. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Introducing Claude Opus 5,  Anthropic, July 24, 2026 
2) Boris Cherny: We Cut 80% of Claude Code’s Prompt, Y Combinator,  Jul 28, 2026
3) Fannie Mae Single-Family Loan Performance, kaggle

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Google's Gemma 4 E2B: The Ultimate Game Changer in On-Device AI

Have you ever worried about the next billing amount when running a generative AI for long hours? This is especially true since high-performance frontier models can easily run continuously for half a day or more. While we understand the incredible performance they offer, I'm sure many of you are wondering, "Isn't there a way to operate generative AI at a lower cost?" So, today, I would like to introduce "Gemma 4 E2B", an open-weight generative AI that you can download and use right on your local PC.


1. The Highly Anticipated Open-Weight Generative AI from Google: "Gemma 4 E2B"

Various AI companies have released open-weight generative AI models. My personal focus is on the Gemma series from Google, which is now in its 4th generation. It has steadily powered up with each generation, and among them, the performance of the smallest latest version, "Gemma 4 E2B QAT" (1), is particularly outstanding. This time, I built an application that predicts customer churn by combining machine learning with "Gemma 4 E2B QAT."

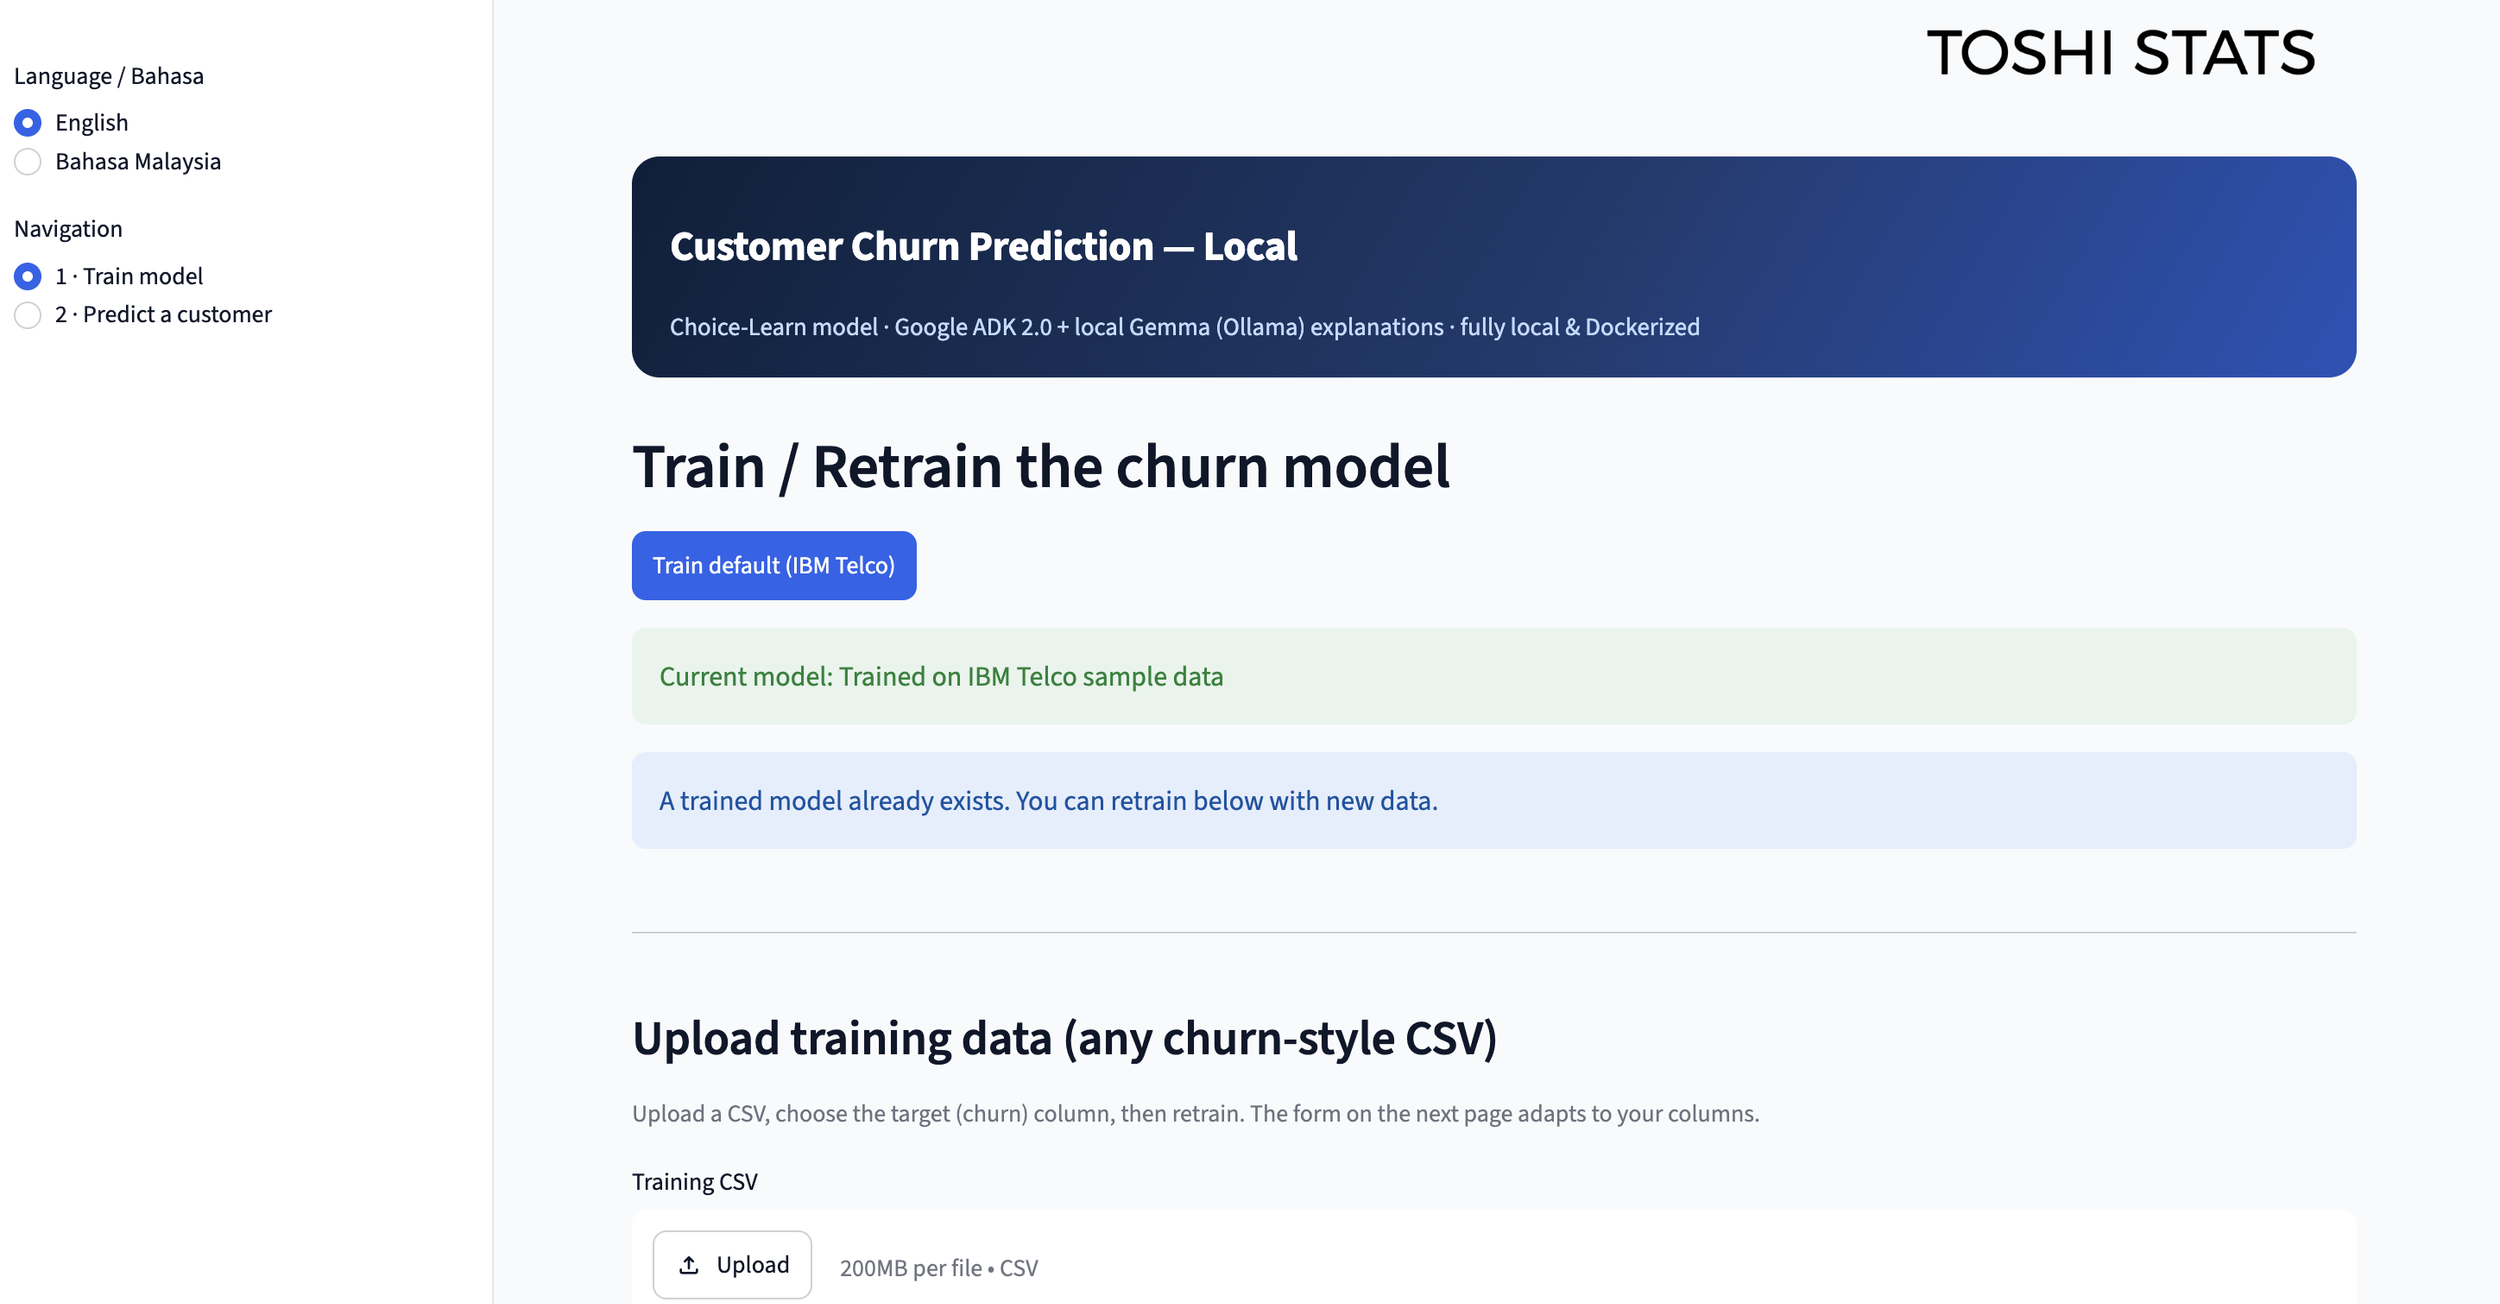
Here is its GUI. For this version, it features bilingual specifications supporting both English and Malay. This is the screen for training the machine learning model.

              Model Training Screen (English)]

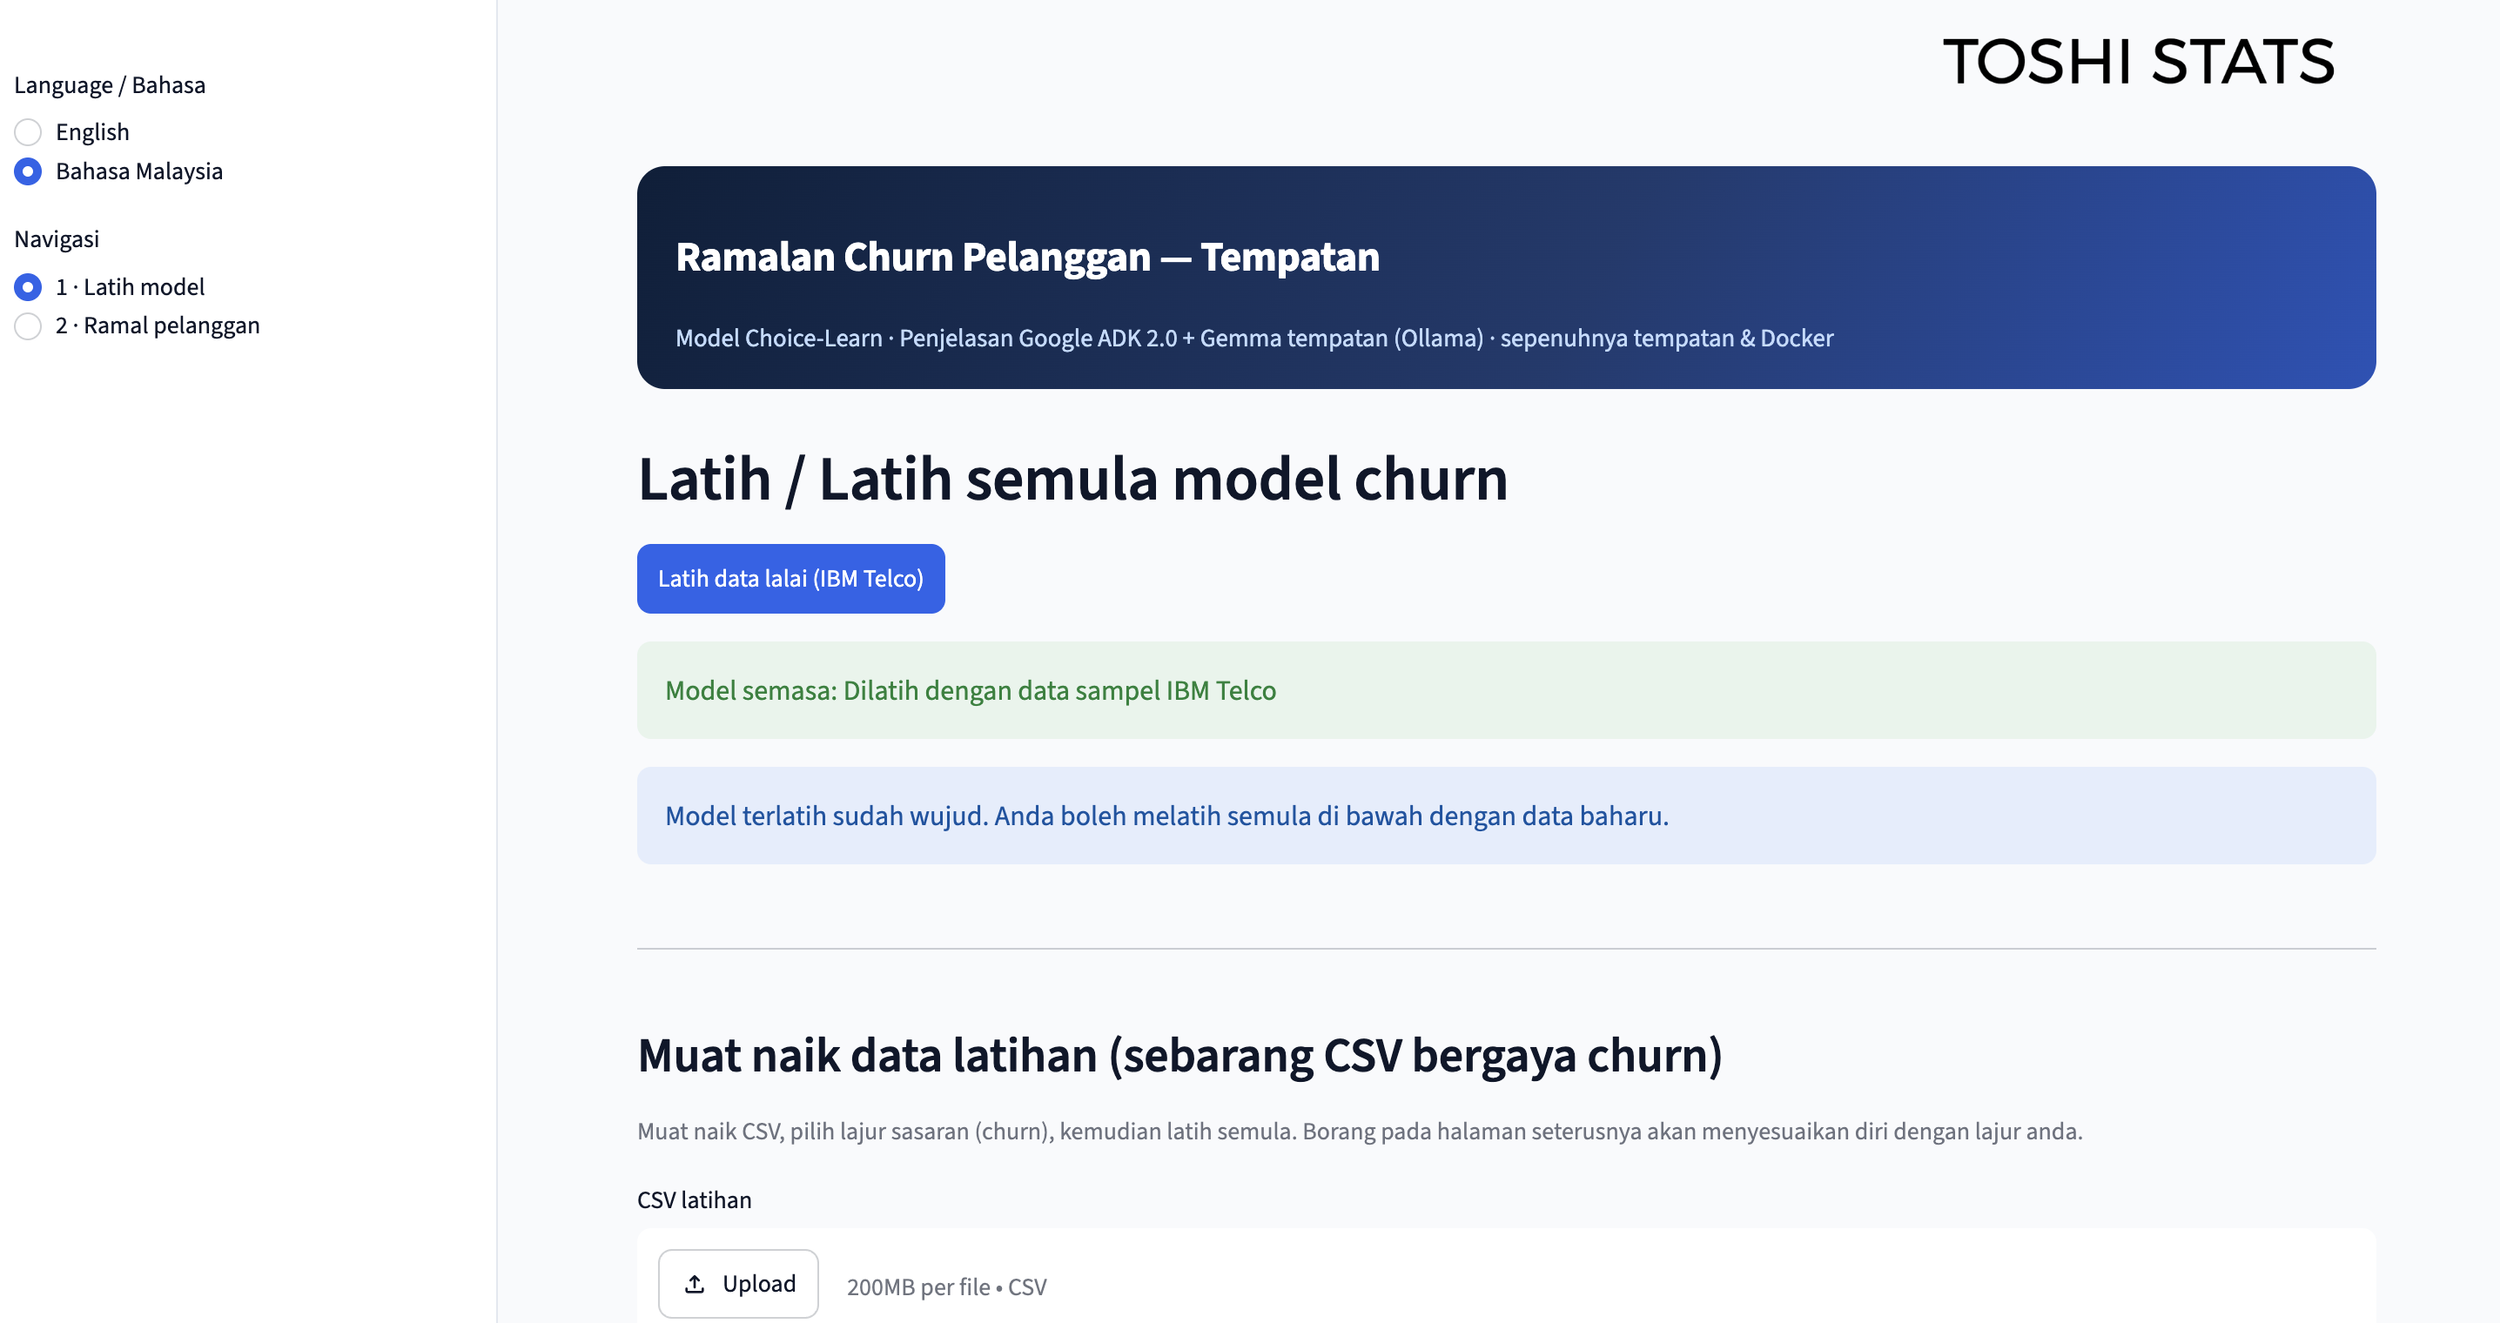
You can switch it to Malay as shown below. It makes it easy to use even in Kuala Lumpur, the capital of Malaysia!

                Model Training Screen (Malay)


2. Exploring the Probability of Individual Customer Churn

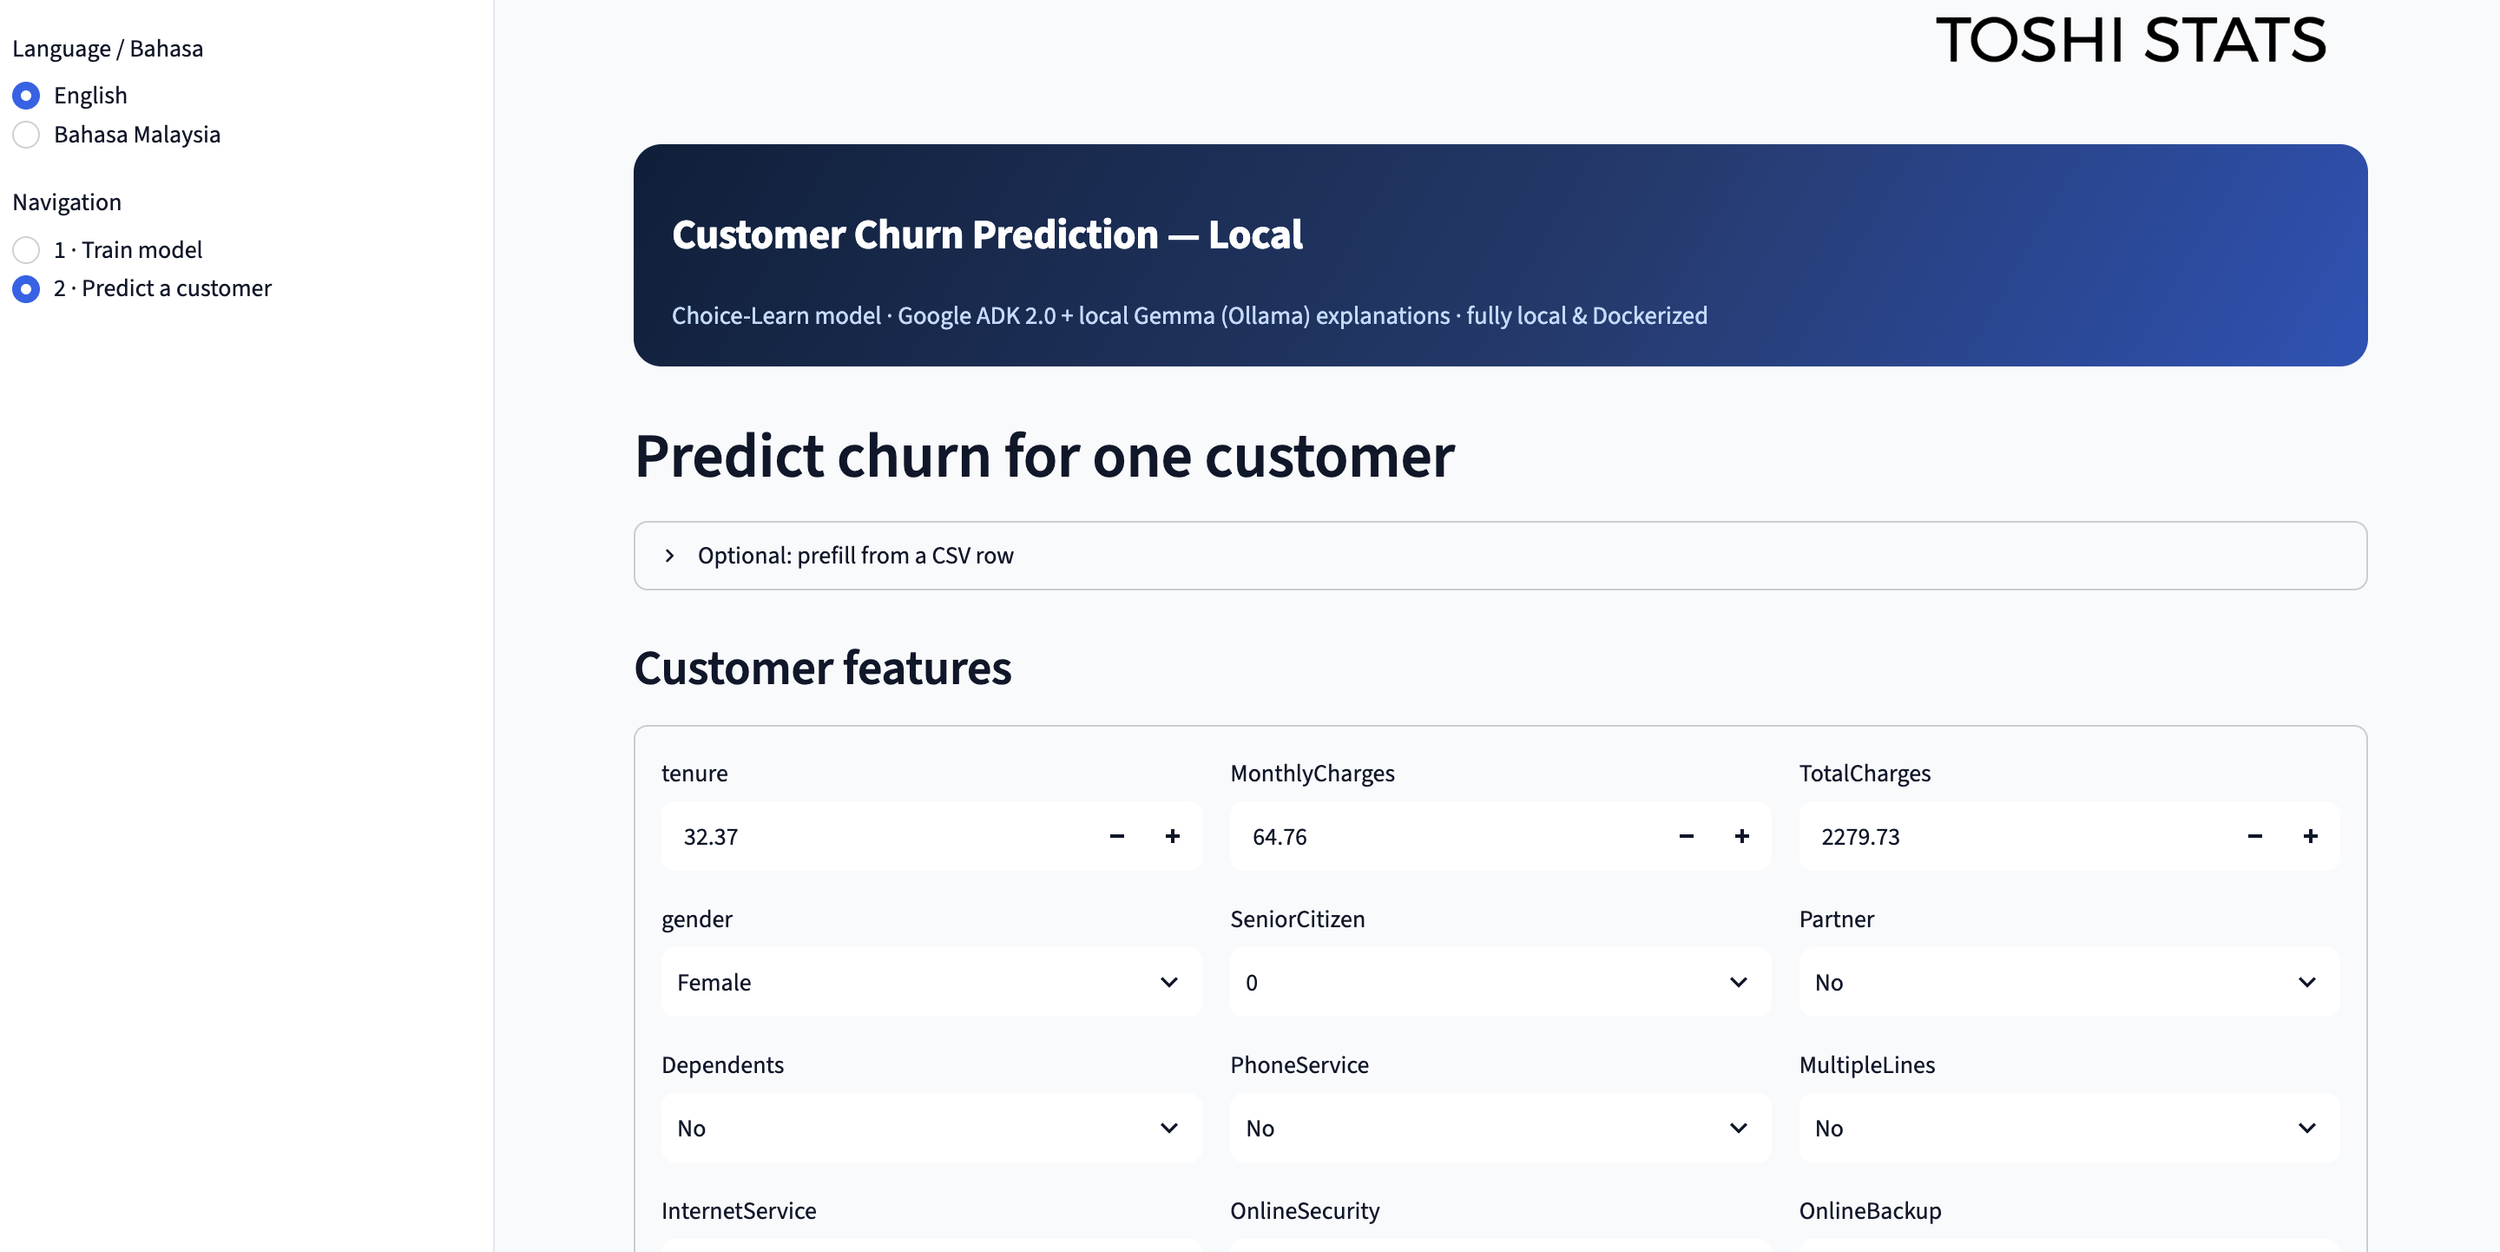
Now, let's get down to business. By inputting individual customer data into the machine learning model, you can calculate the probability of that customer churning. Here, the system is set so that if the probability is 50% or higher, the customer is predicted to churn. The churn probability for the customer shown on this screen is 15.01%, so they were judged as "will not churn."

                   Customer Data

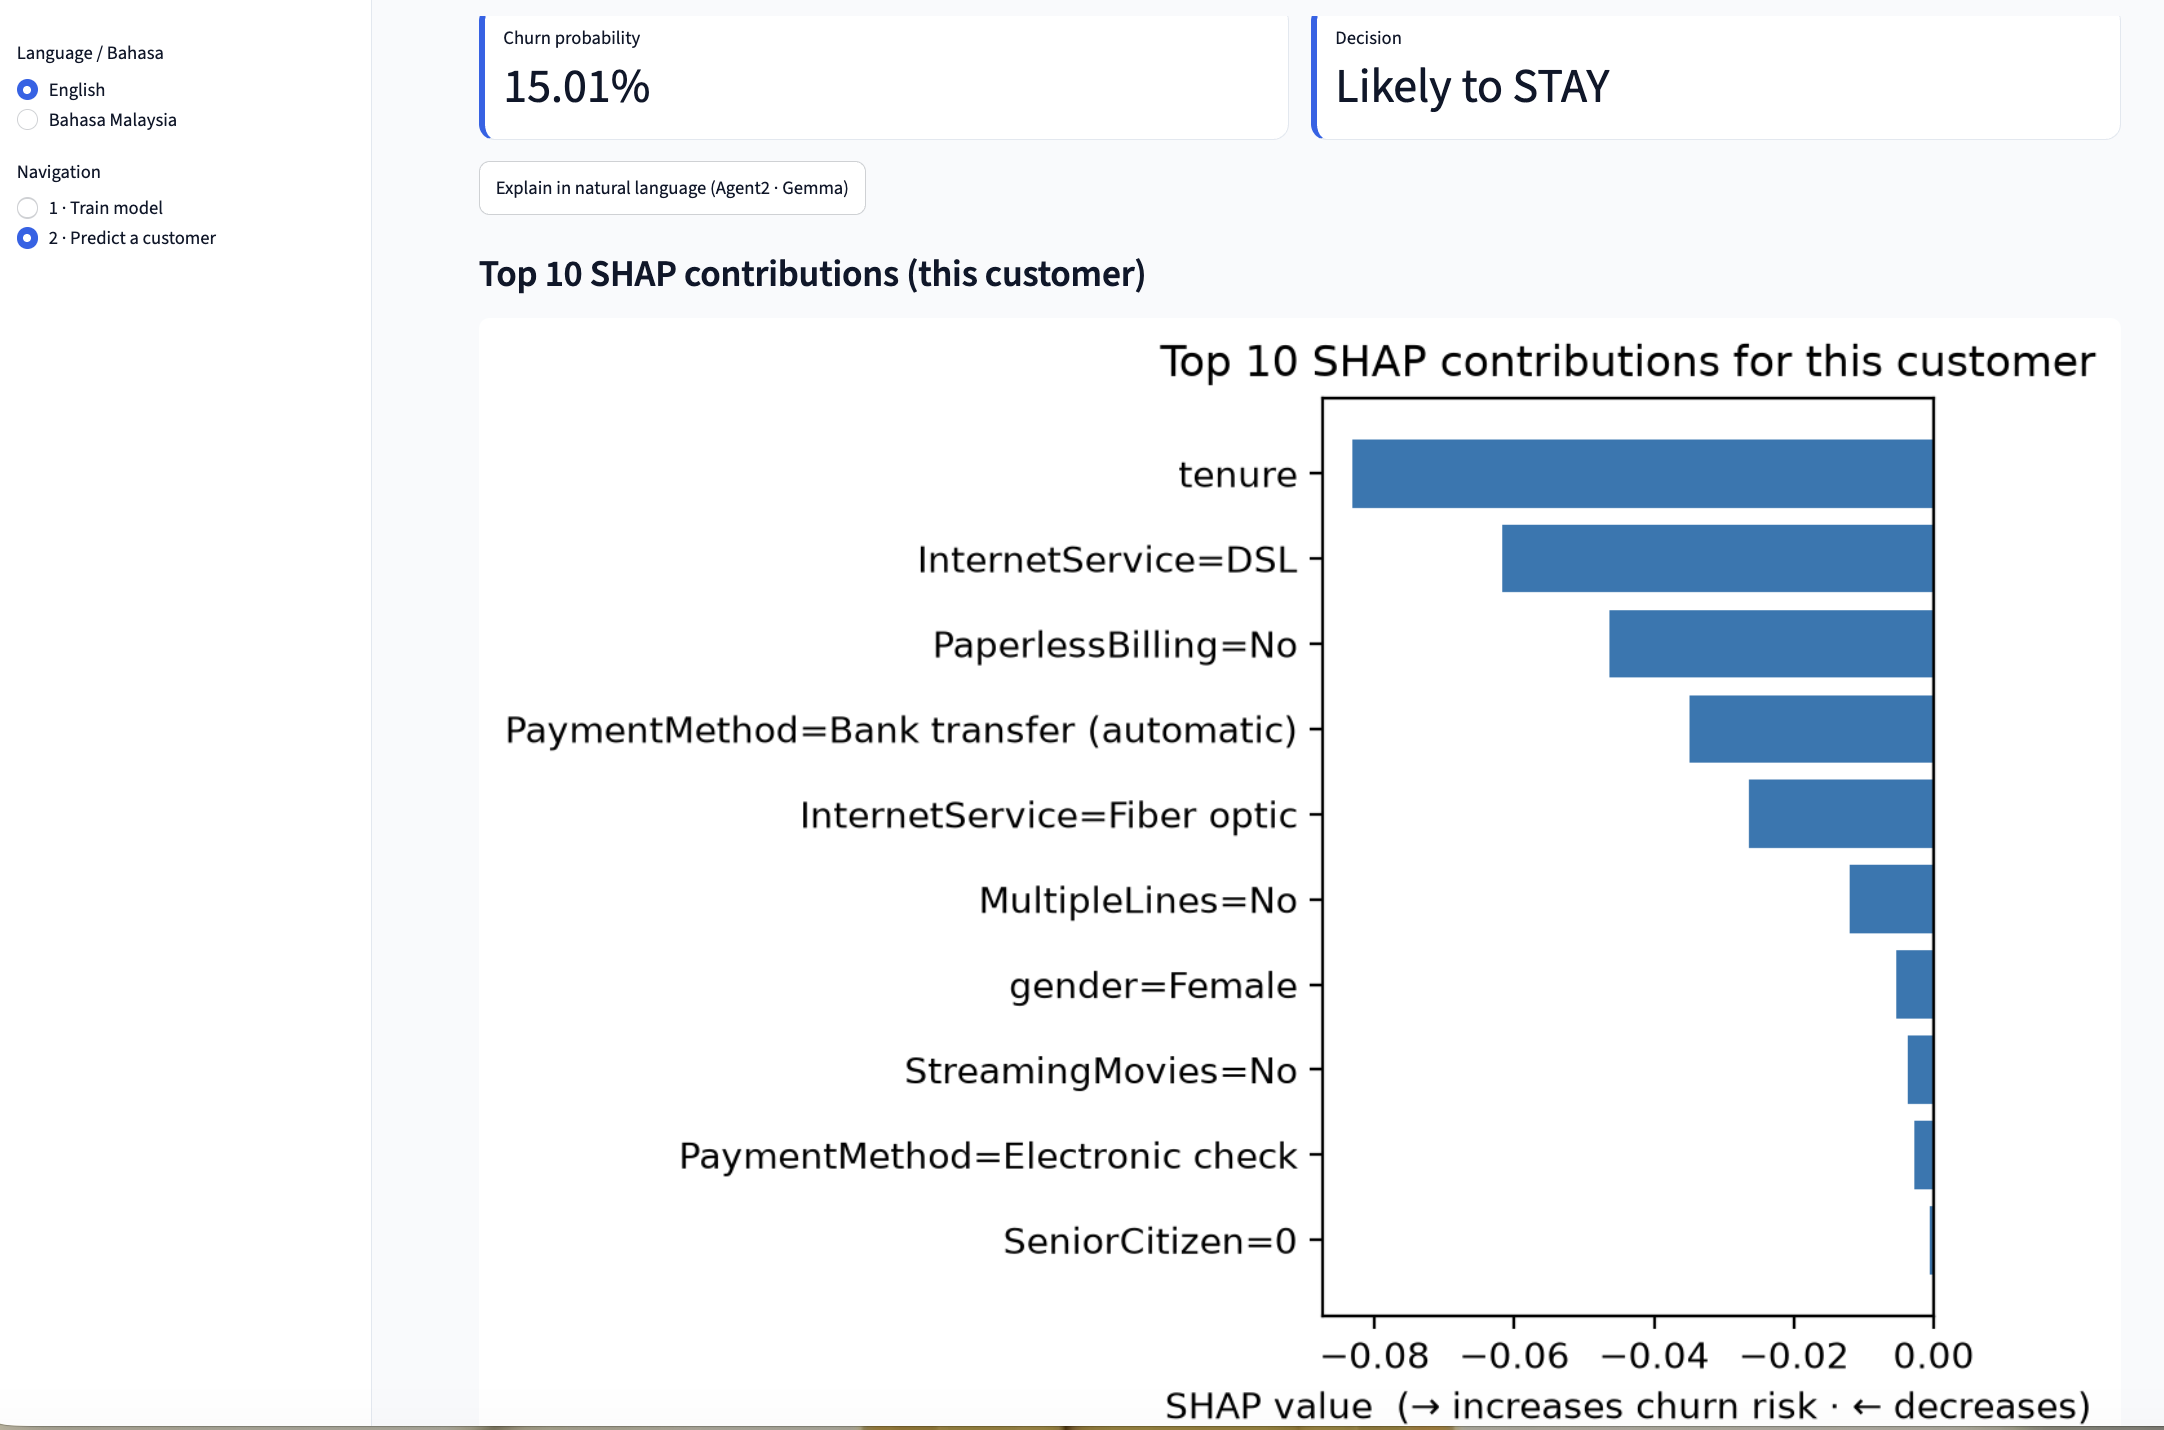
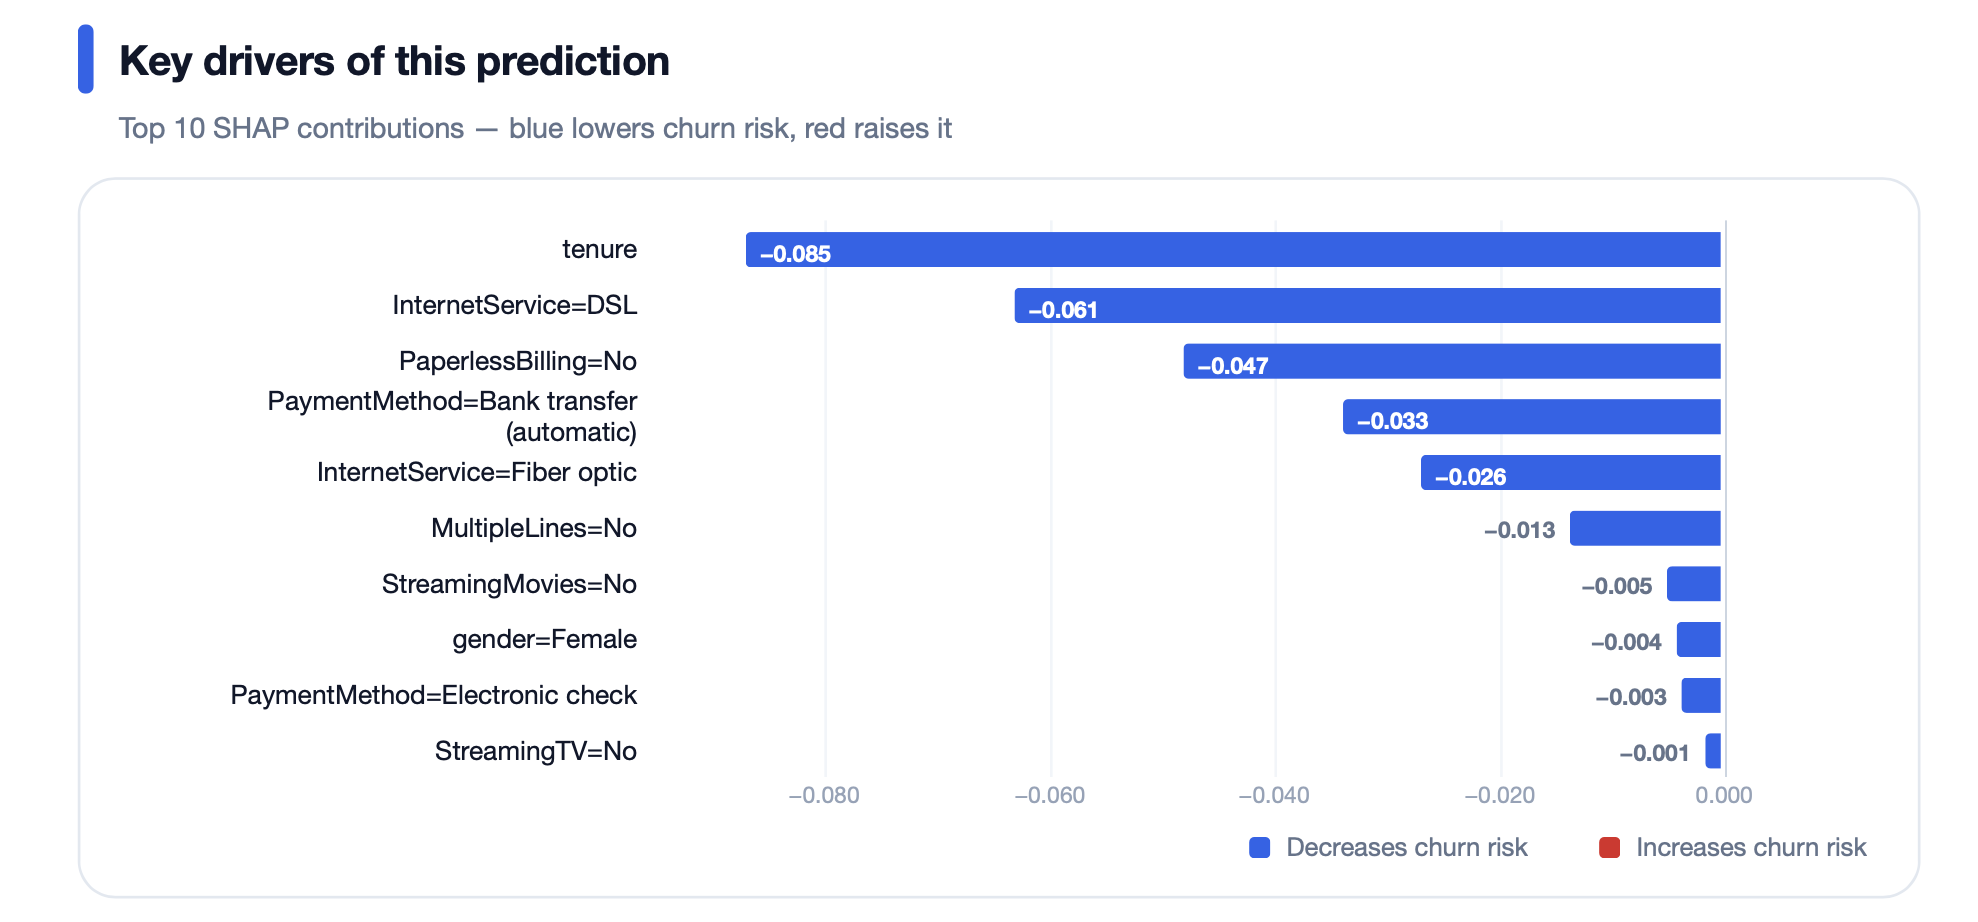
What's really important here is the reasoning behind why it decided they wouldn't churn. For this, a metric called SHAP (2) is employed. The graph below shows numerically and visually how much each feature contributed to the decision.

                Churn Probability and SHAP

However, the problem here is that SHAP is mostly well-known only to data scientists, and there's a high chance that ordinary business professionals aren't familiar with it at all. Therefore, simply saying "Please look at this graph" isn't very user-friendly.

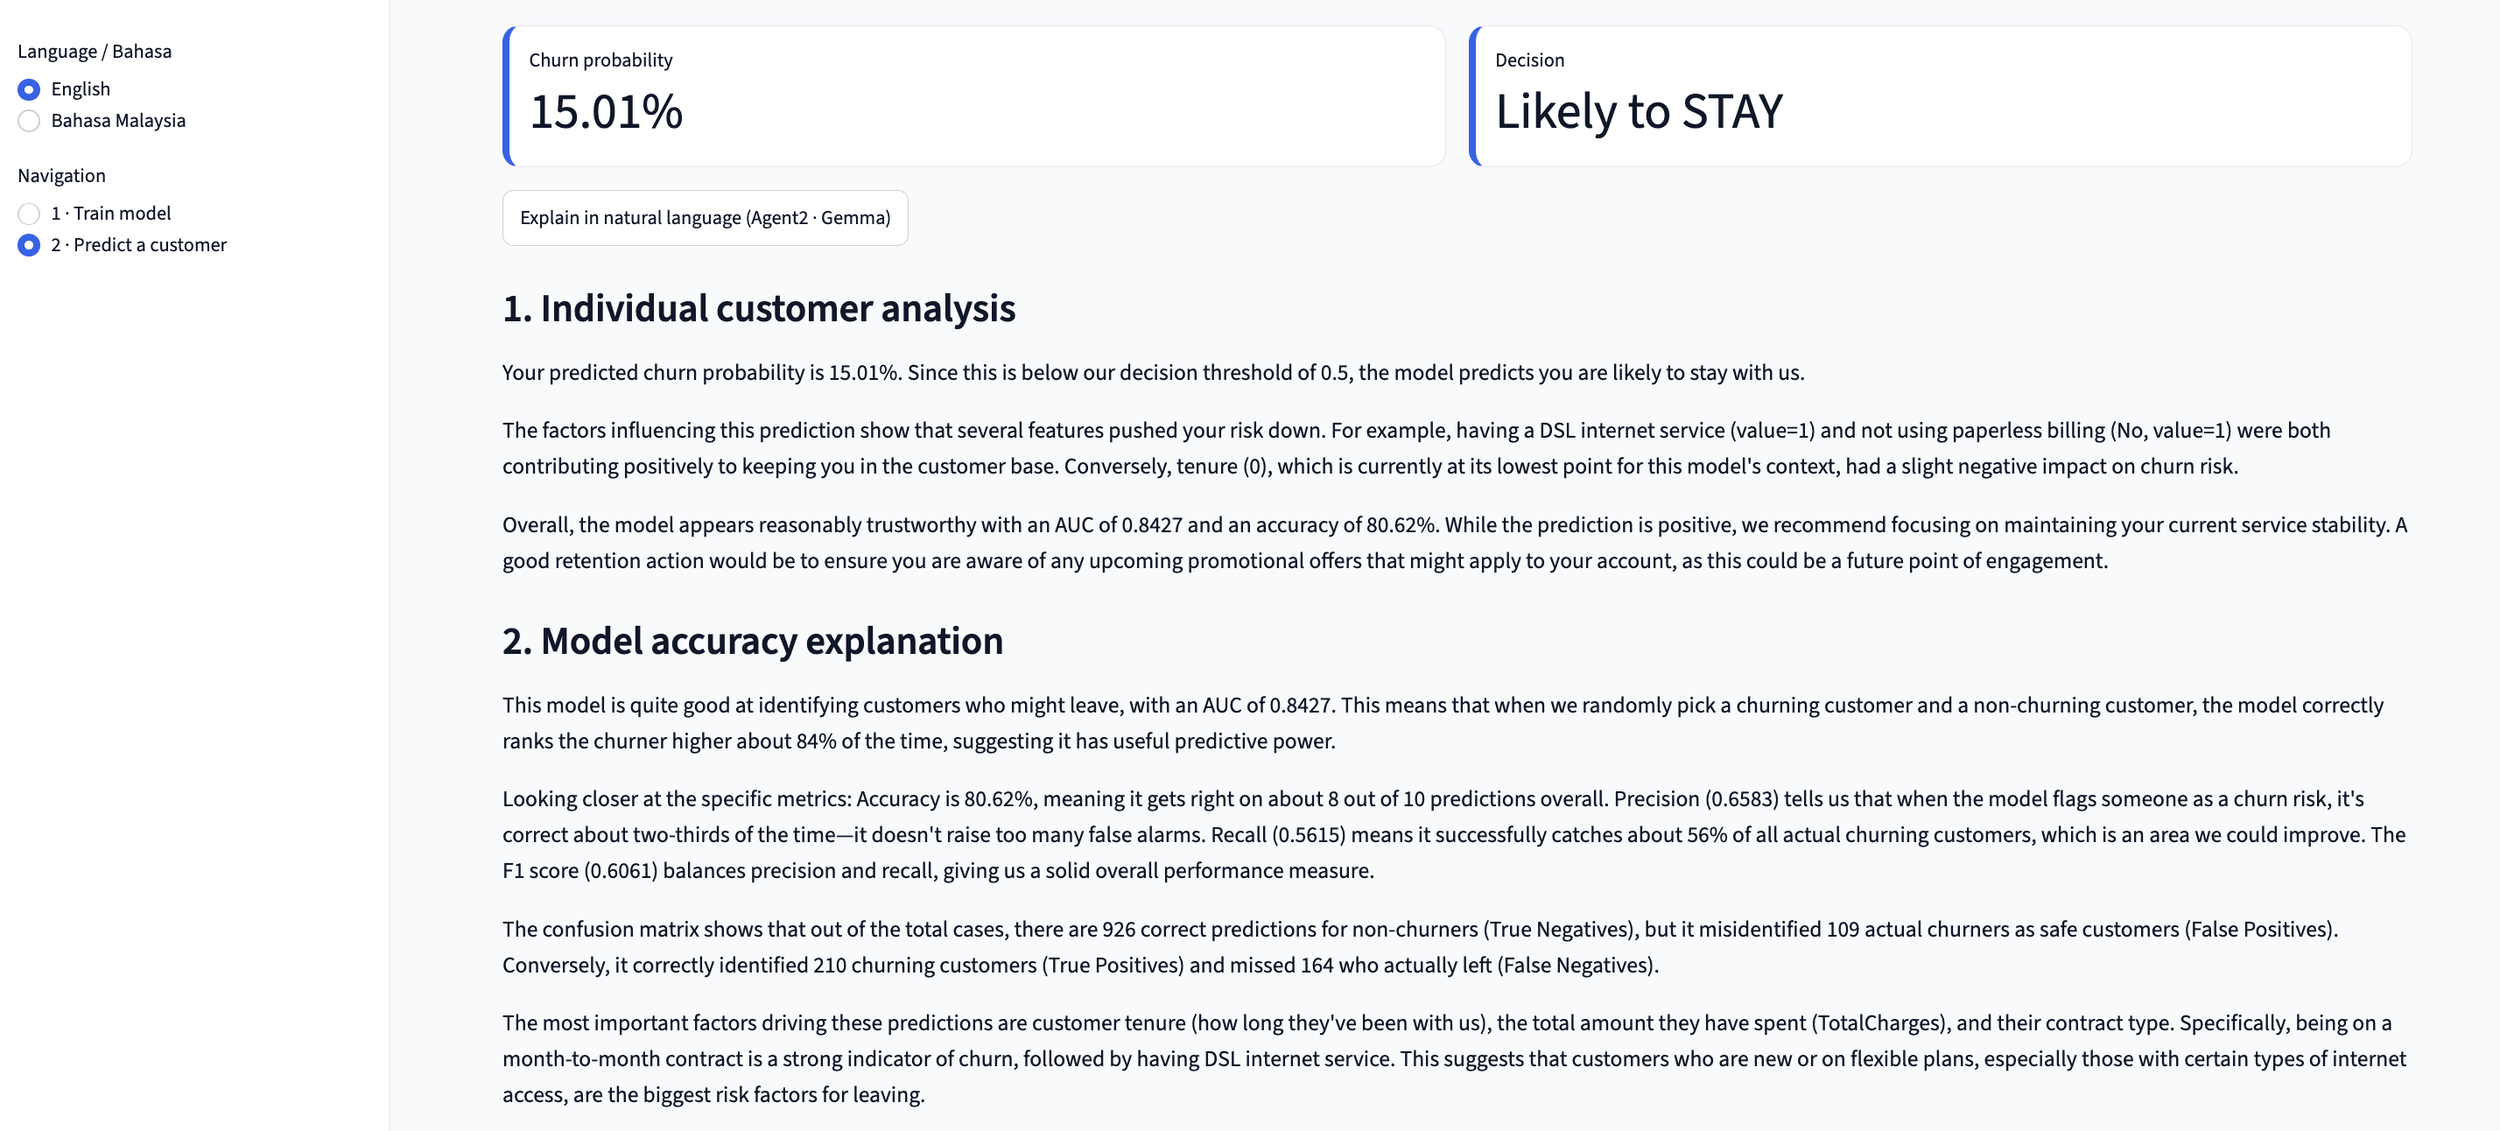
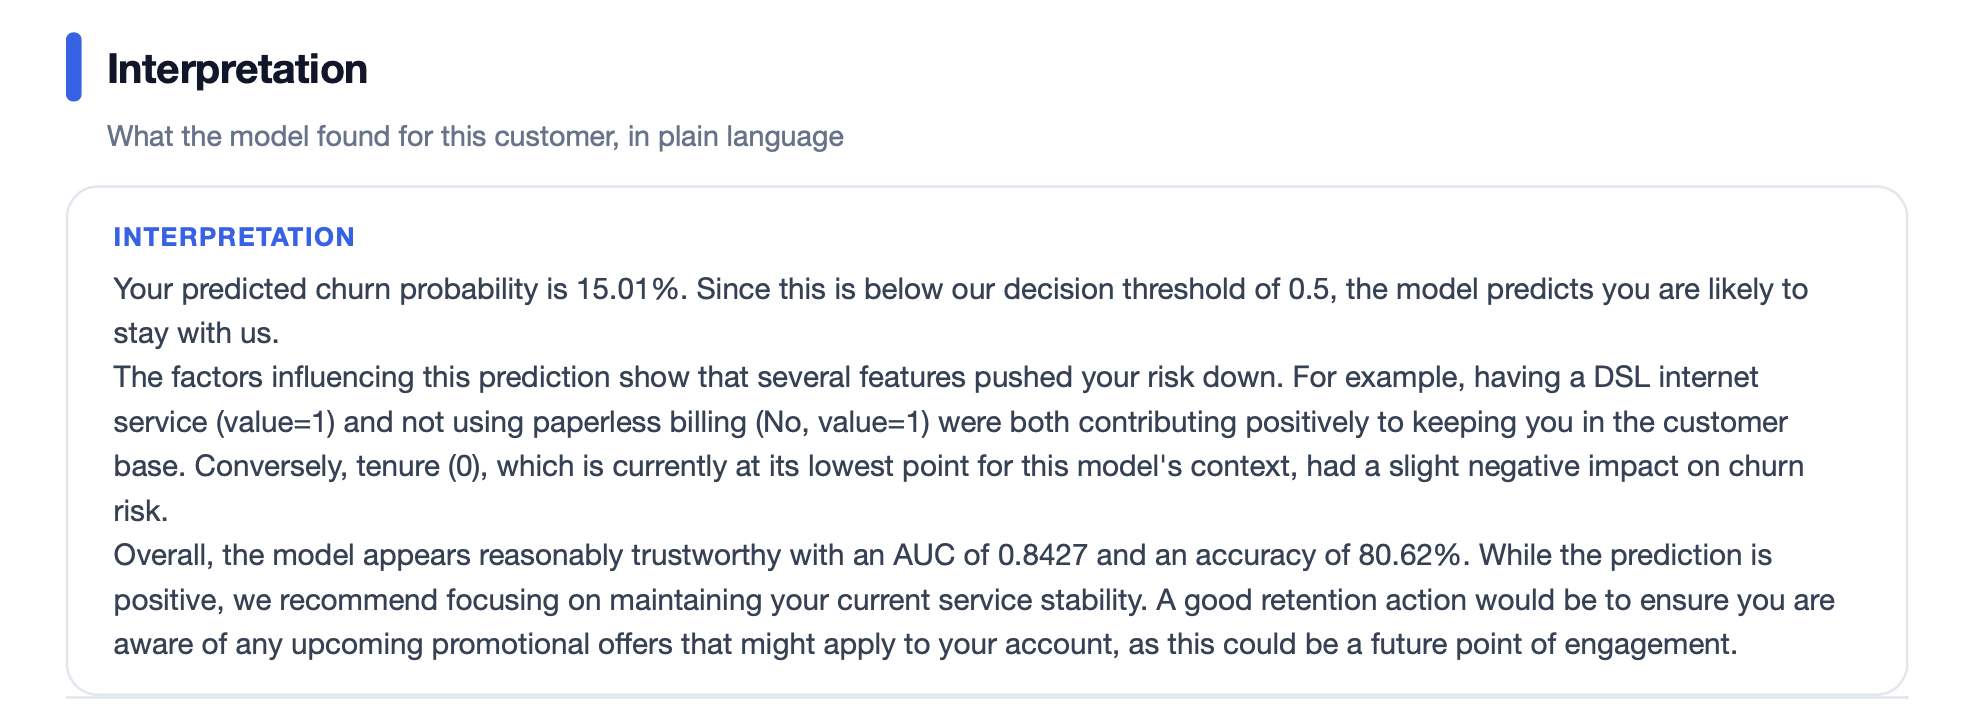
This is where today's star, "Gemma 4 E2B QAT," steps in. As shown below, it explains the "basis for the decision" and the "model's accuracy" in plain, easy-to-understand English. With this, even a SHAP beginner can use it with absolute confidence.

        Explanation of Decision Basis and Model Accuracy (English)

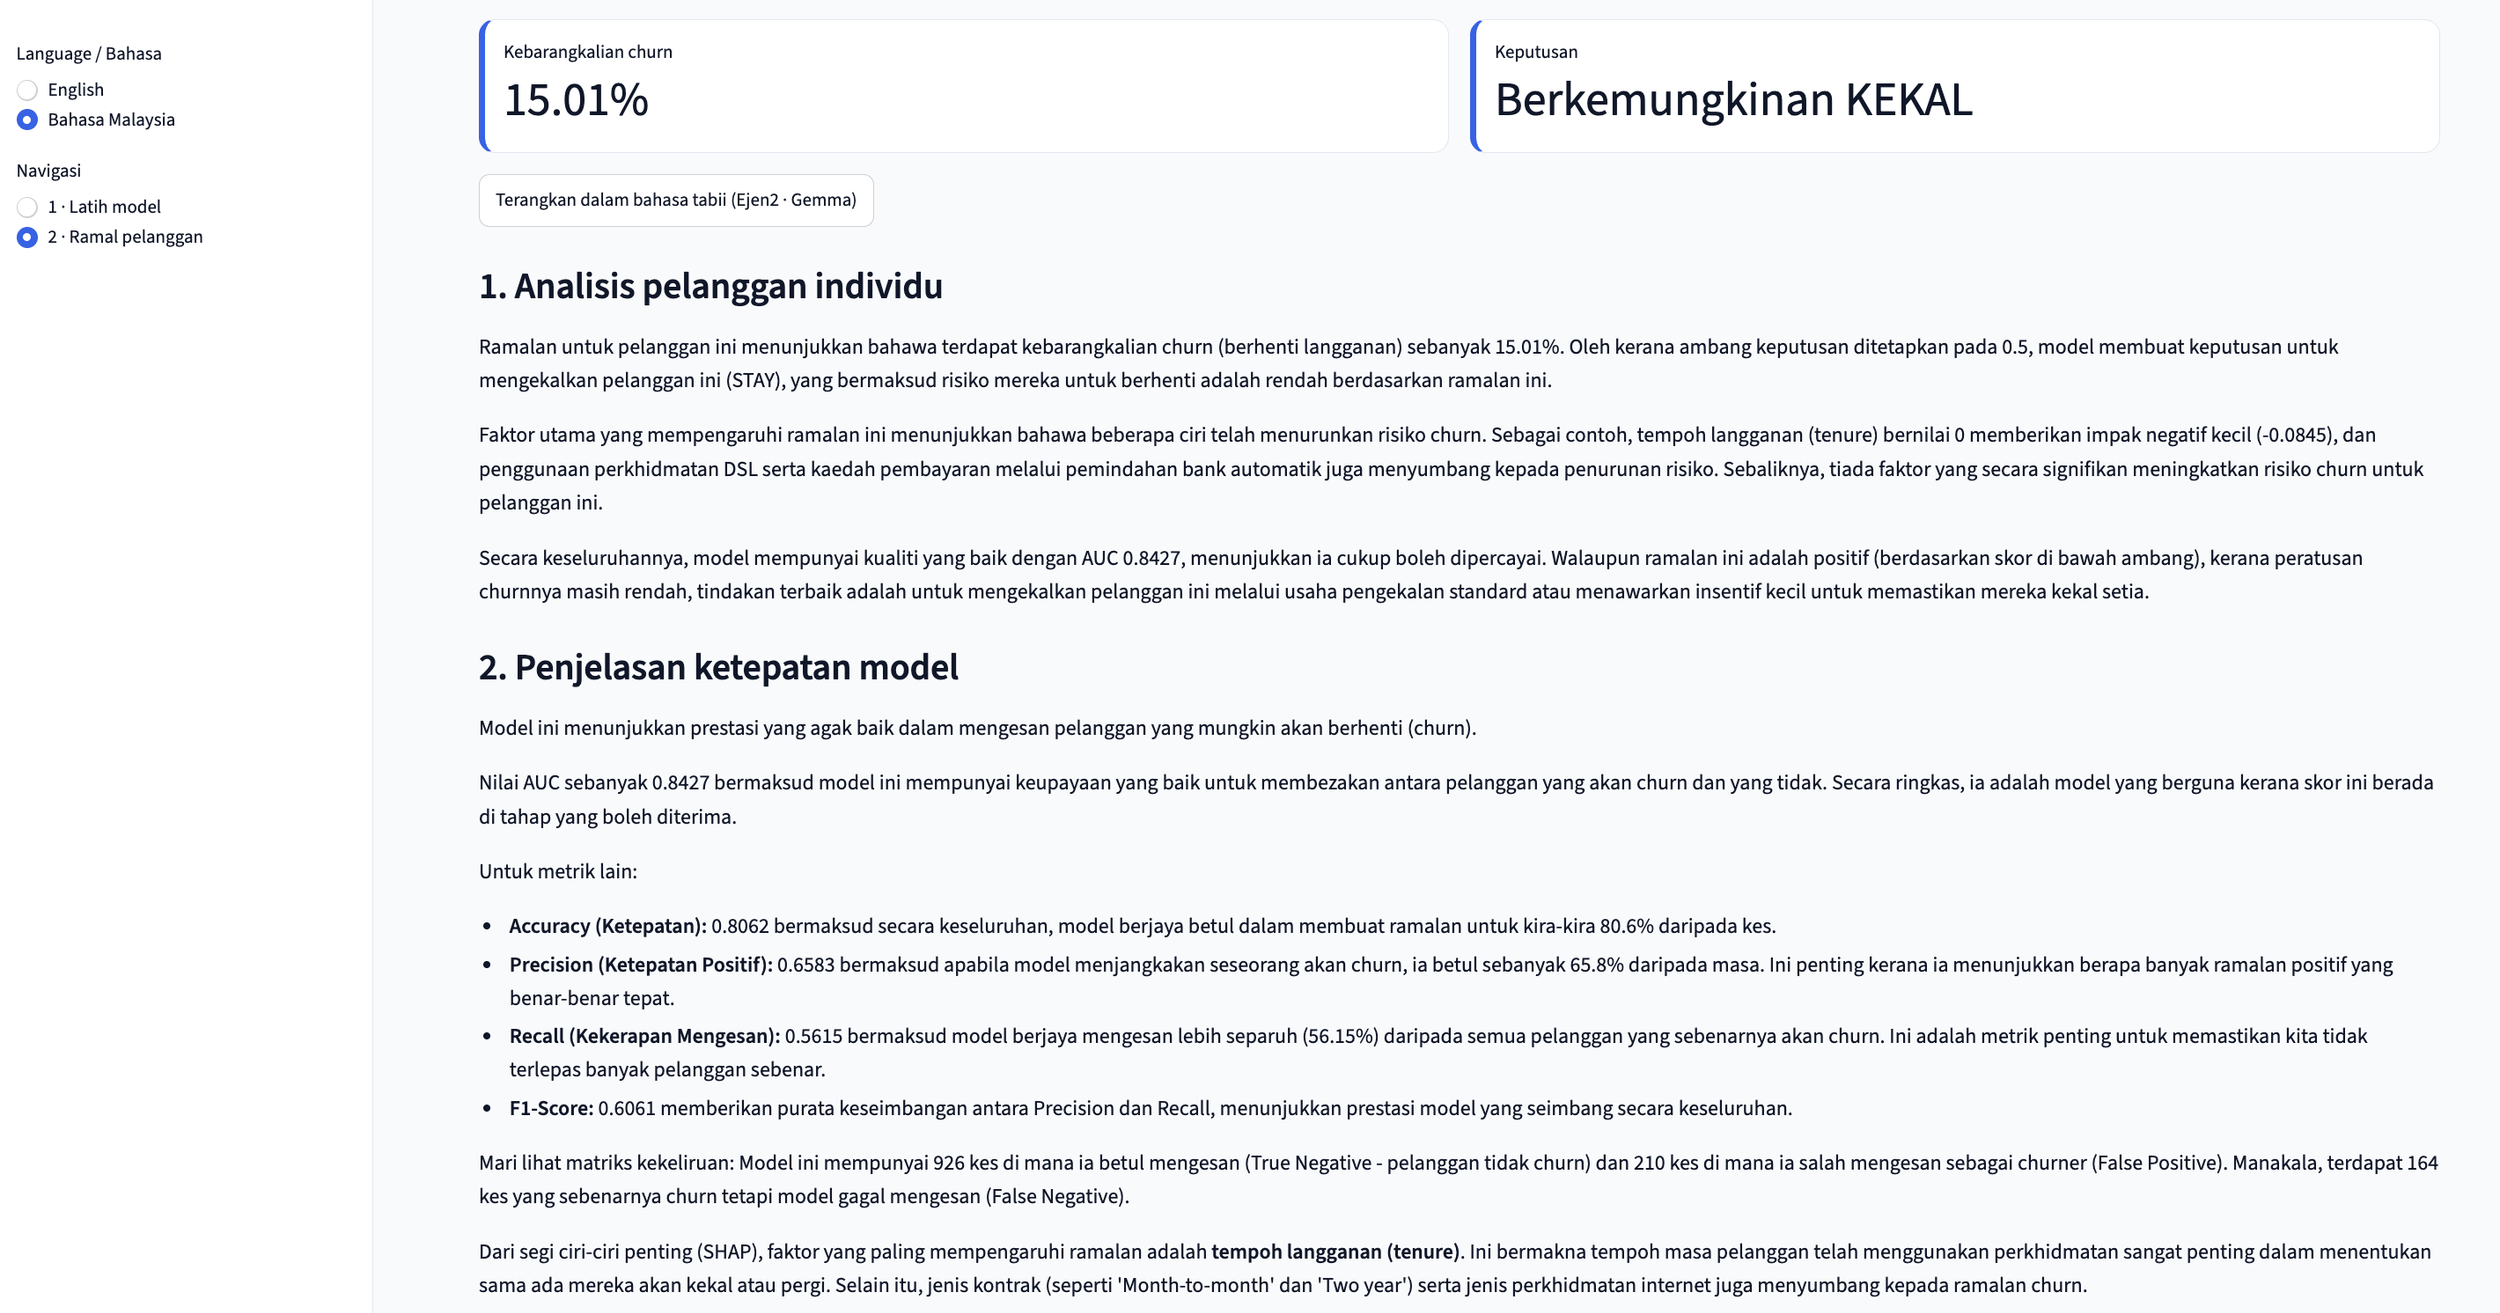
Of course, you can switch this to Malay. Generating this much explanatory text in two languages takes only about 35 seconds on a MacBook Air (M4 24GB). Even on a standard Windows PC, it can often be generated in under 5 minutes. Since "Gemma 4 E2B QAT" is compact, its processing speed is incredibly fast. It is well within practical levels for real-world use.

        Explanation of Decision Basis and Model Accuracy (Malay)


3. The Quality of the Explanatory Text is Also Excellent

The most important point today is: "How accurate is the text generated by Gemma 4 E2B QAT?"

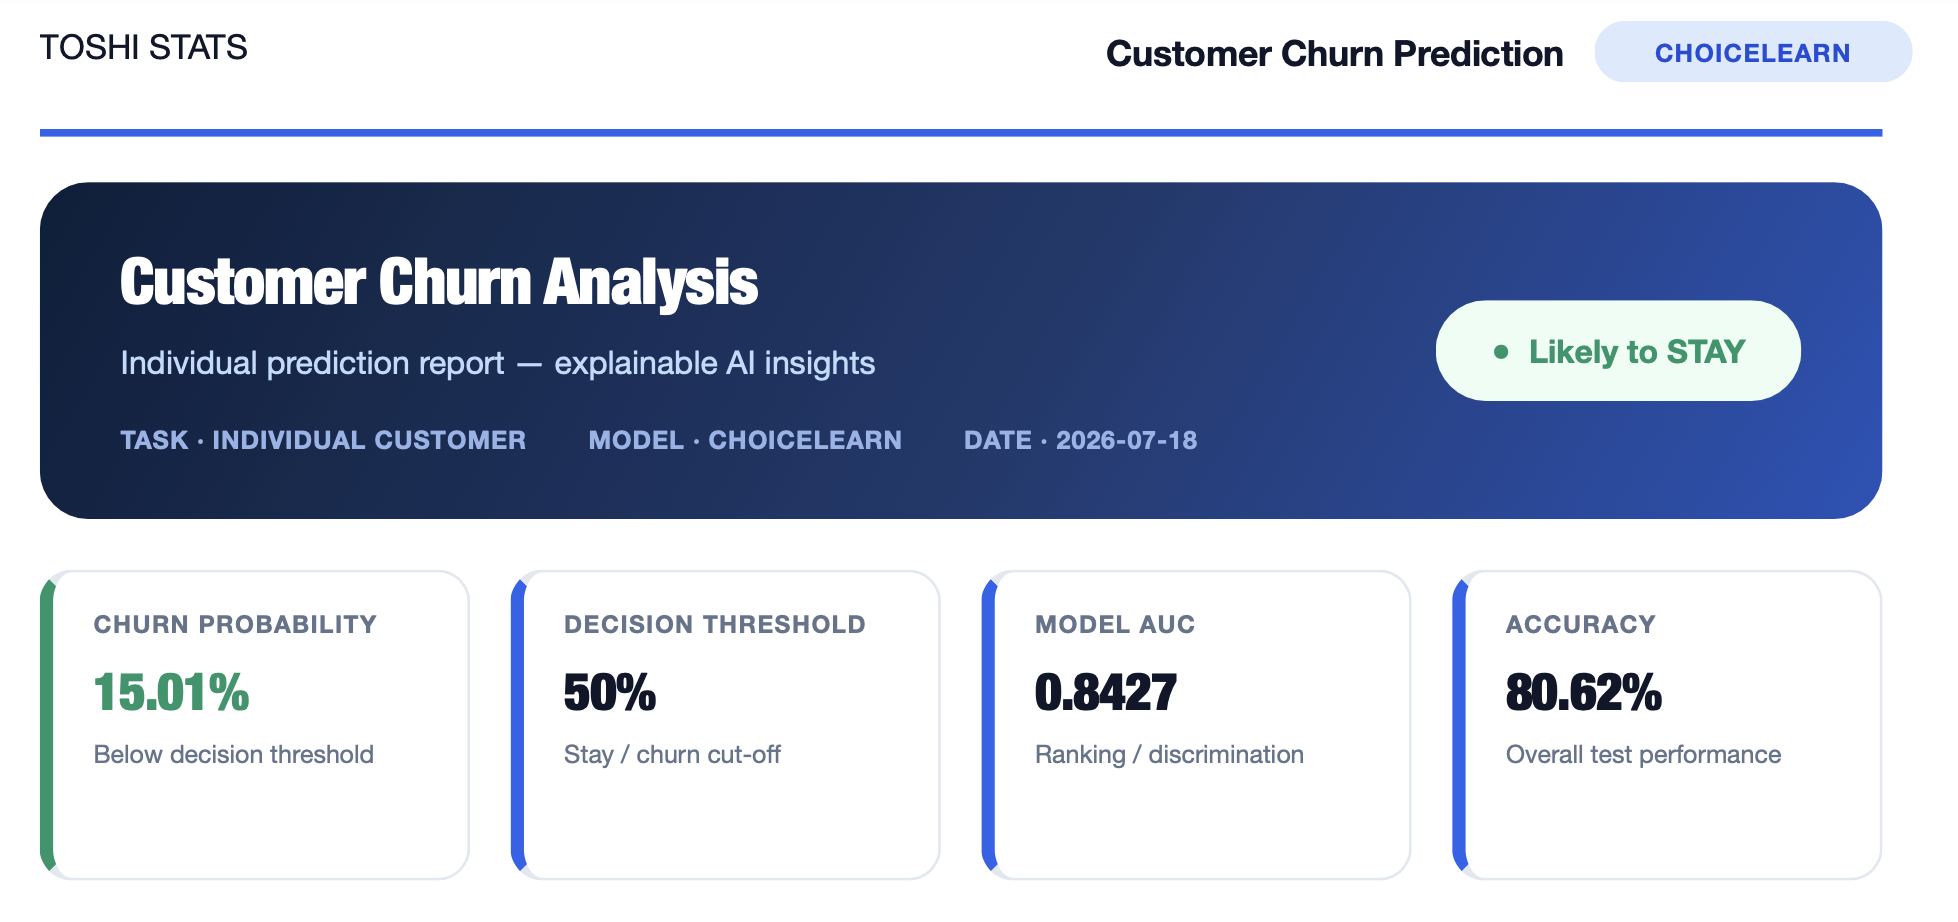
Small-scale generative AIs often lack the accumulated internal information compared to massive frontier models, so in my past experience, I frequently felt they were difficult to use practically in business. However, with "Gemma 4 E2B QAT," such worries were completely unnecessary. This app can output the prediction results as a PDF, so let's use that to take a closer look.

Here is the SHAP graph that served as the basis for the decision. We naturally want to explain this graph in easy-to-understand English, right?

Here is the explanatory text. What do you think? It's written in clear English, with absolutely no grammatical errors or spelling mistakes. I believe it provides a highly logical explanation based on the SHAP data above. When I first read it myself, I was actually a bit moved, thinking, "Can this little generative AI really do this much?"


So, what do you think? There are zero fees for using generative AI in this app. No invoices will be generated. You can use it freely for as many hours as you like. Isn't that fantastic!

Of course, "Gemma 4 E2B QAT" is not omnipotent, so it is necessary to use it strategically in combination with frontier models like Fable5 depending on the situation. However, I am beyond delighted that this ultra-compact generative AI has become a viable option. I feel we should actively use it while fully leveraging its major advantages: being entirely free and allowing highly confidential information to remain securely locked within your PC.

At Toshi Stats, we will continue to tackle tasks in the marketing field using the power of "Machine Learning + Generative AI." Stay tuned!


1)  Gemma 4 QAT models: Optimizing model compression for mobile and laptop efficiency, 5 June 2026, Olivier Lacombe, Omar Sanseviero, Google DeepMind

2) Welcome to the SHAP documentation

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Beyond the Obvious: Unleashing the Fable5 AI's Blind Spot Pass as a Strategic Secret Weapon!

Anthropic’s new generative AI, Fable5, is available again and is currently being trialed worldwide. I have been taking on new challenges myself, but I often feel that even with ultra-high-performance generative AI, things don't go well if the user's prompts are vague. Rework occurs every single time, and I've constantly wondered, "Isn't there a better way to do this?" Recently, Anthropic engineer Thariq Shihipar shared a brilliant idea (1). This time, I would like to introduce the "Blind Spot Pass"—a method that helps us identify our blind spots in advance—and actually try using it.


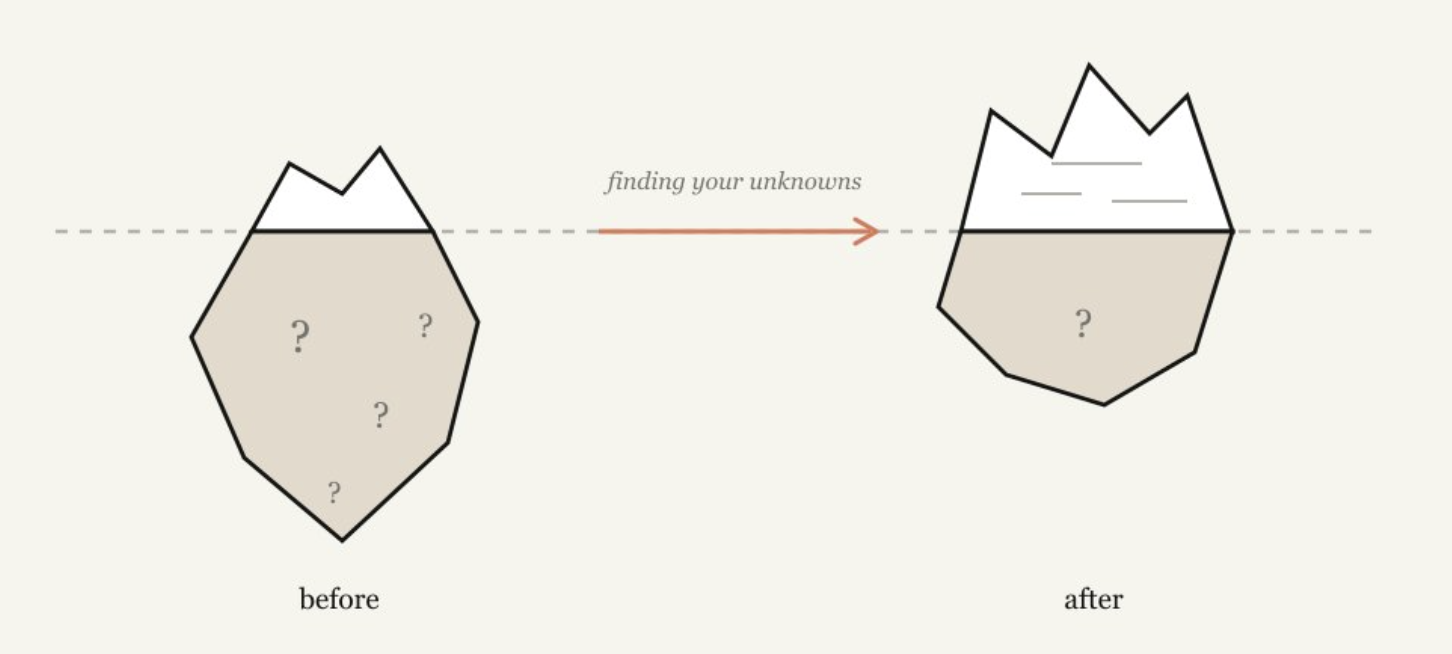
1. Reduce the Unknowns

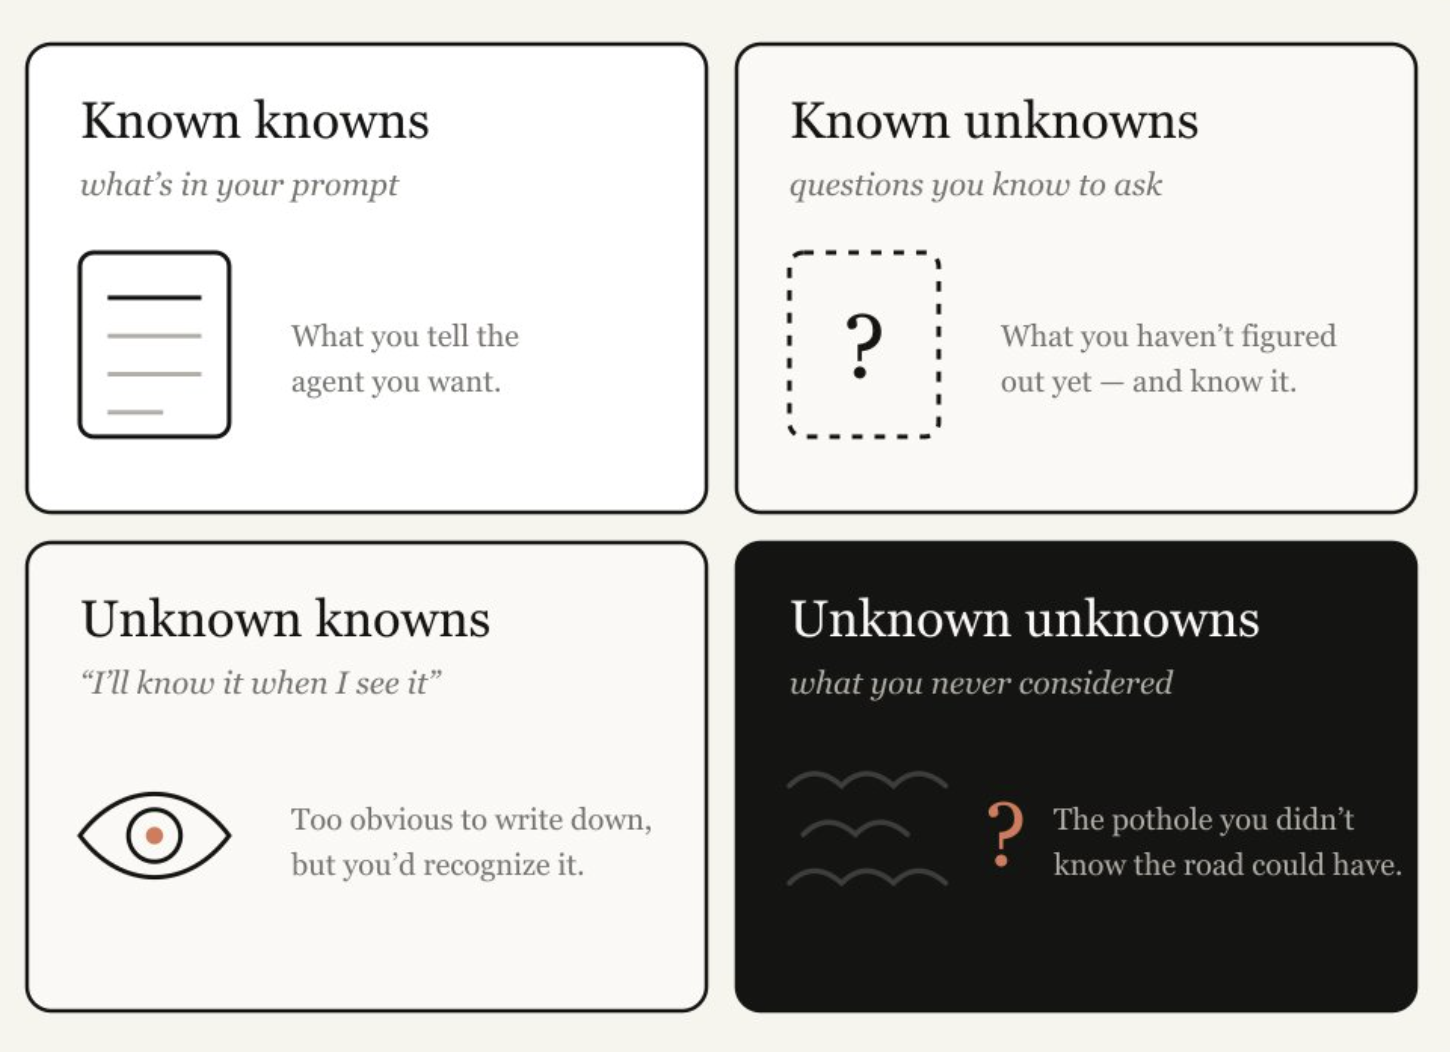
I believe the core of Thariq Shihipar's argument is the "unknown." When starting a project, we don't understand everything from the outset, and there are many unknowns. He categorizes our knowledge as follows:

  • Known Knowns: This is essentially what is in my prompt. What do I tell the agent that I want?

  • Known Unknowns: What haven't I figured out yet, but I’m aware that I haven’t?

  • Unknown Knowns: What's so obvious I’d never write it down, but would recognize it if I saw it?

  • Unknown Unknowns: What haven't I considered at all? What knowledge am I not aware of? Do I know how good something can be?

No matter how high-performing Fable5 is, if we—the ones giving the instructions—don't clearly understand what we want to do, we won't be able to push its capabilities to the limit. Therefore, before starting a project, we need to transition from a state of "many unknowns" on the left to a state of "few unknowns" on the right. He outlines a detailed process for this, but I would like to focus specifically on the "Blind Spot Pass," which reduces the "Unknown Unknowns."


2. How to Strategically Use a Customer Churn Prediction Model

Currently, I am developing a "customer churn prediction model" combining machine learning and generative AI, but I am pondering how best to apply it to actual business scenarios. I have thought about various approaches, but that doesn't mean there are no blind spots. So, I would like to immediately apply the "Blind Spot Pass" to Fable5 and uncover these blind spots. The actual method just requires using the following prompt. It's very simple!

“I am looking to develop a new customer churn prediction model to improve my business, but I have no prior knowledge of customer churn prediction or how to practically apply it in a business setting. Please conduct a 'Blind Spot Pass' to identify the relevant 'unknown unknowns' and help me write a better prompt.”

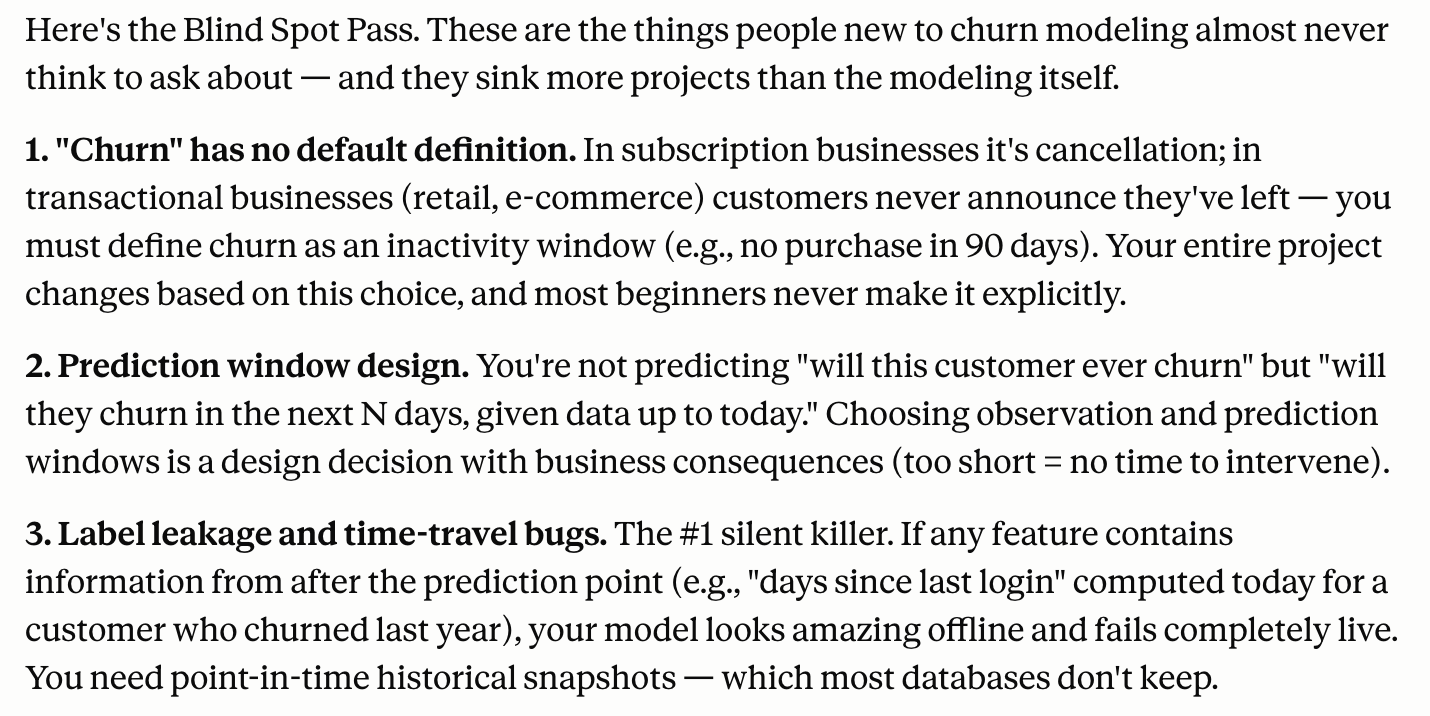
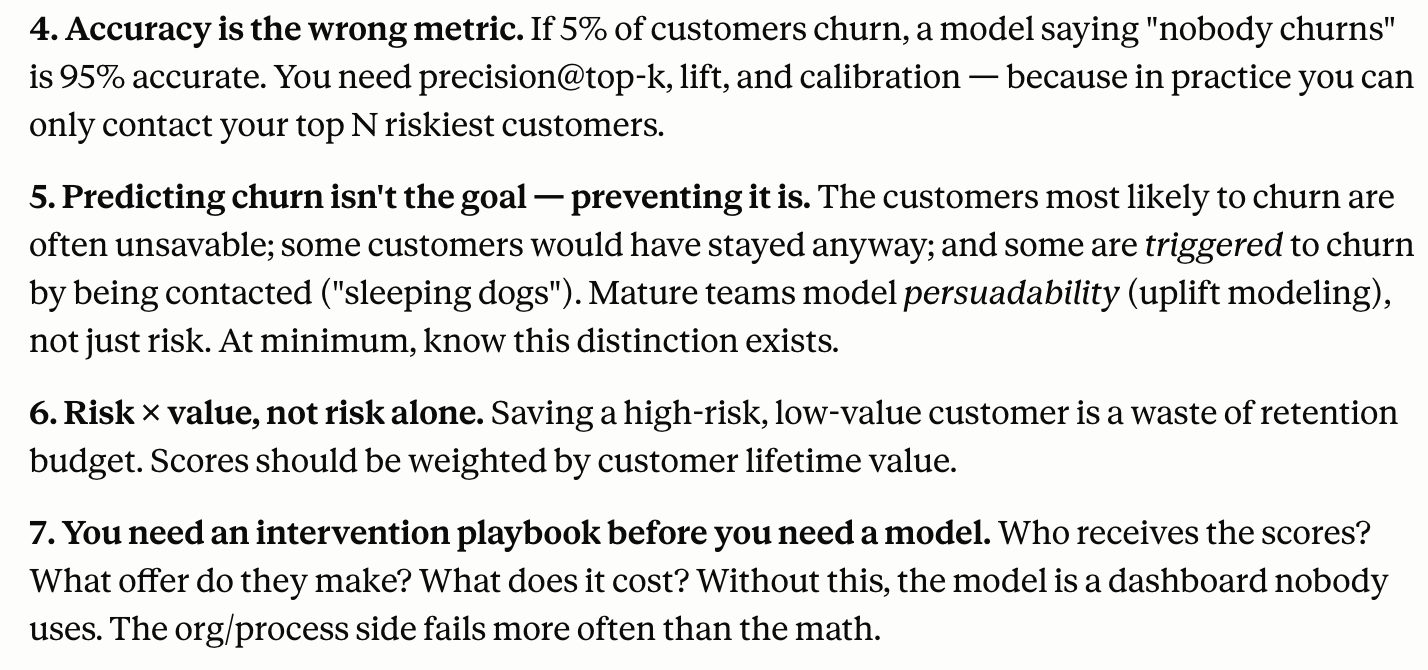
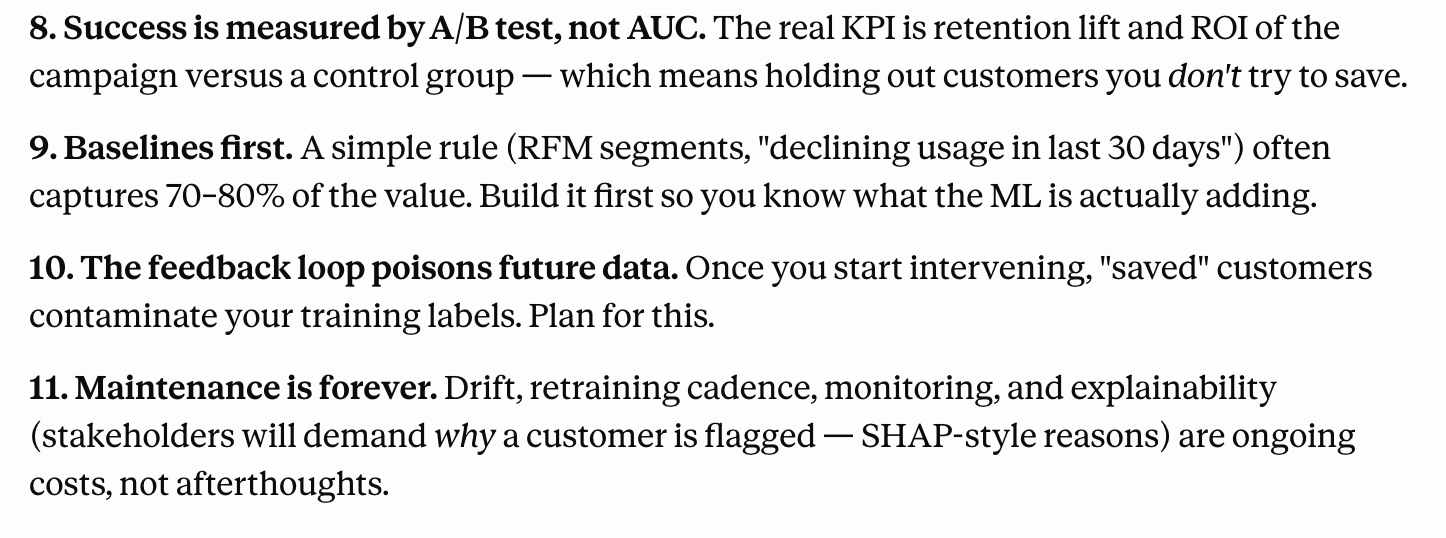
Within minutes, I received the following response. It's amazing!

With blind spots identified in such detail, I can proactively grasp potential stumbling blocks before actually writing the prompts, allowing me to write them much more clearly and effectively. Furthermore, when feedback comes from Fable5, I will be able to respond more accurately. Because the unknowns have been reduced, I can move forward with the project with confidence.


3. The "Blind Spot Pass" is Also Effective for Formulating Management Strategies

Because Thariq Shihipar is an engineer, his discussion centered around coding, but reducing unknowns is crucial in a variety of fields. Especially in management strategy formulation, where uncertainty is high, eliminating blind spots as early as possible is extremely important to prevent failures caused by "unforeseen circumstances." The development of the customer churn prediction model mentioned above shouldn't be viewed merely as a coding task, but rather as an action responding to the major management challenge of "increasing customer retention," making it a significant pillar of management strategy. If we consider management strategy after grasping the 11 points raised earlier, we will undoubtedly be able to build a more effective and refined strategy. I want to actively keep using this. The "Blind Spot Pass" serves as an incredibly reassuring partner, especially when taking on new challenges in uncharted territories.


What do you think? Just by tweaking your prompts slightly, the "Blind Spot Pass" seems poised to deliver tremendous results. Let me conclude with a quote from Thariq Shihipar:

"Fable is the first model where I find the quality of the work is bottlenecked by my ability to clarify its unknowns."

Here at Toshi Stats, we plan to take on various tasks using Fable5. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1)  A Field Guide to Fable: Finding Your Unknowns, 4,July 2026, Thariq Shihipar, Anthropic PBC

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Maximizing Customer Retention: Churn Prevention Strategies Using AI and Machine Learning

It is always sad when customers who have taken the time to purchase our products or services end up leaving. If possible, we want to catch the signs early and take action to prevent them from churning. However, identifying customers who are likely to churn beforehand is no easy task. That is why, this time, I tried creating a customer churn prediction model. I would like to take on the challenge of predicting and countering customer churn using machine learning and generative AI. For formulating the key churn prevention strategies, I used Gemini 3.5 Flash (1), which offers a fantastic balance of performance and cost. Let's get started.

Gemini 3.5 Flash


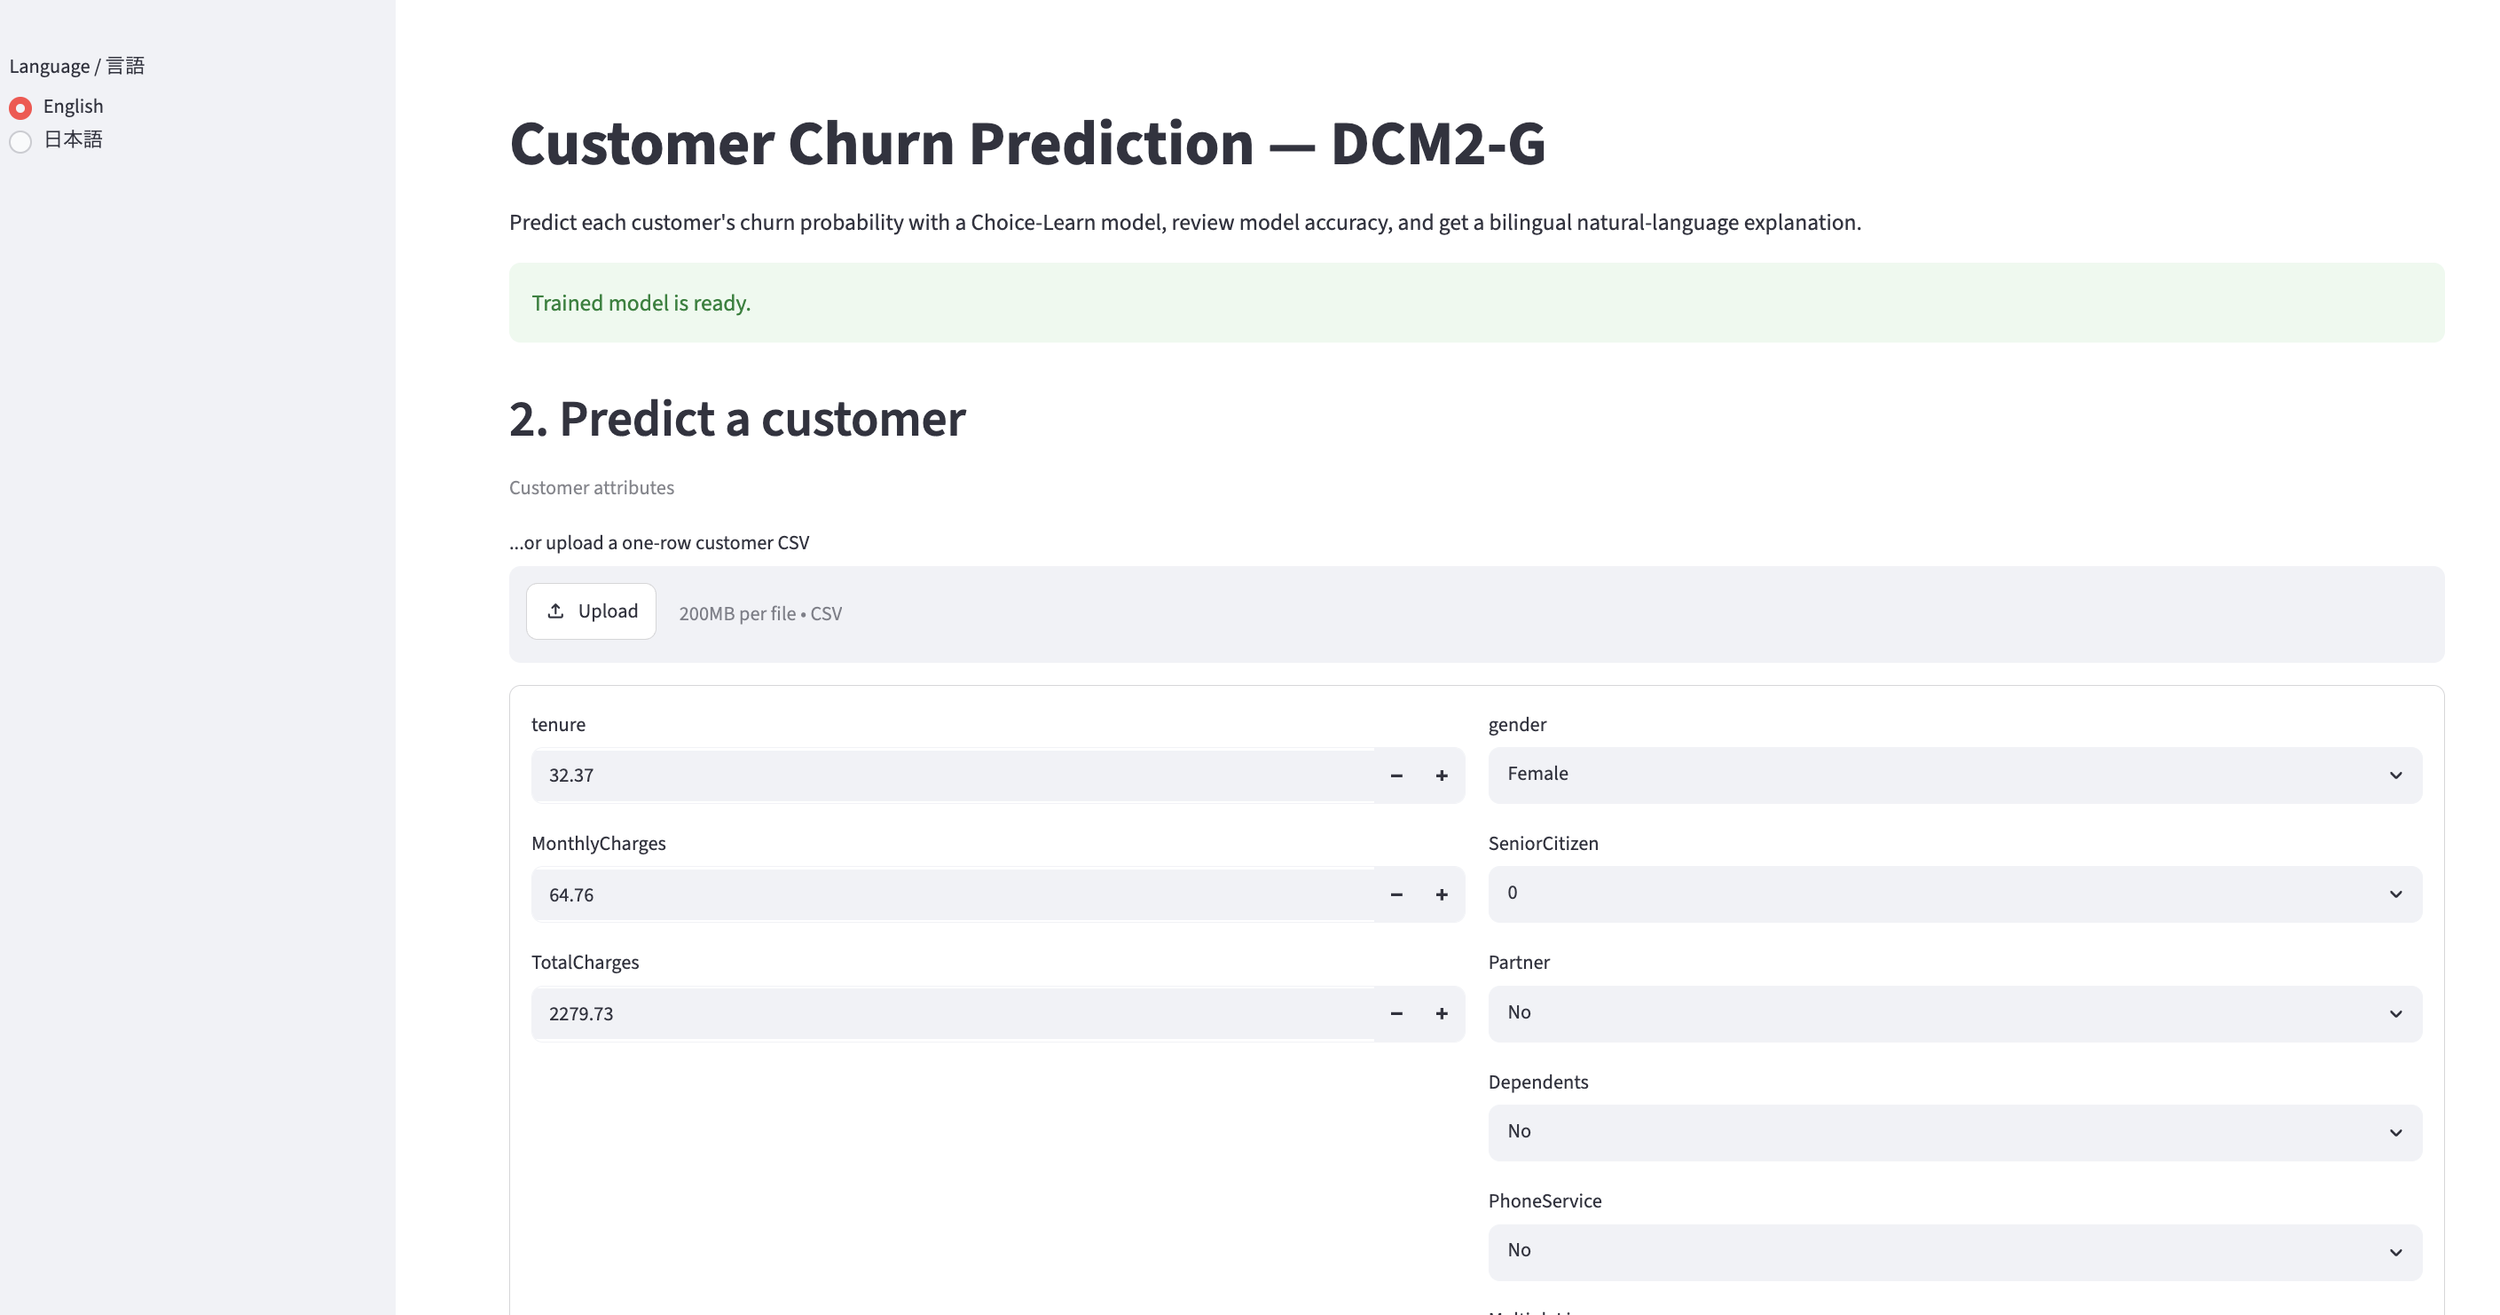
1. Customer Churn Prediction Model

Using the created customer churn prediction model, let's first take a look at a general customer.

General Customer

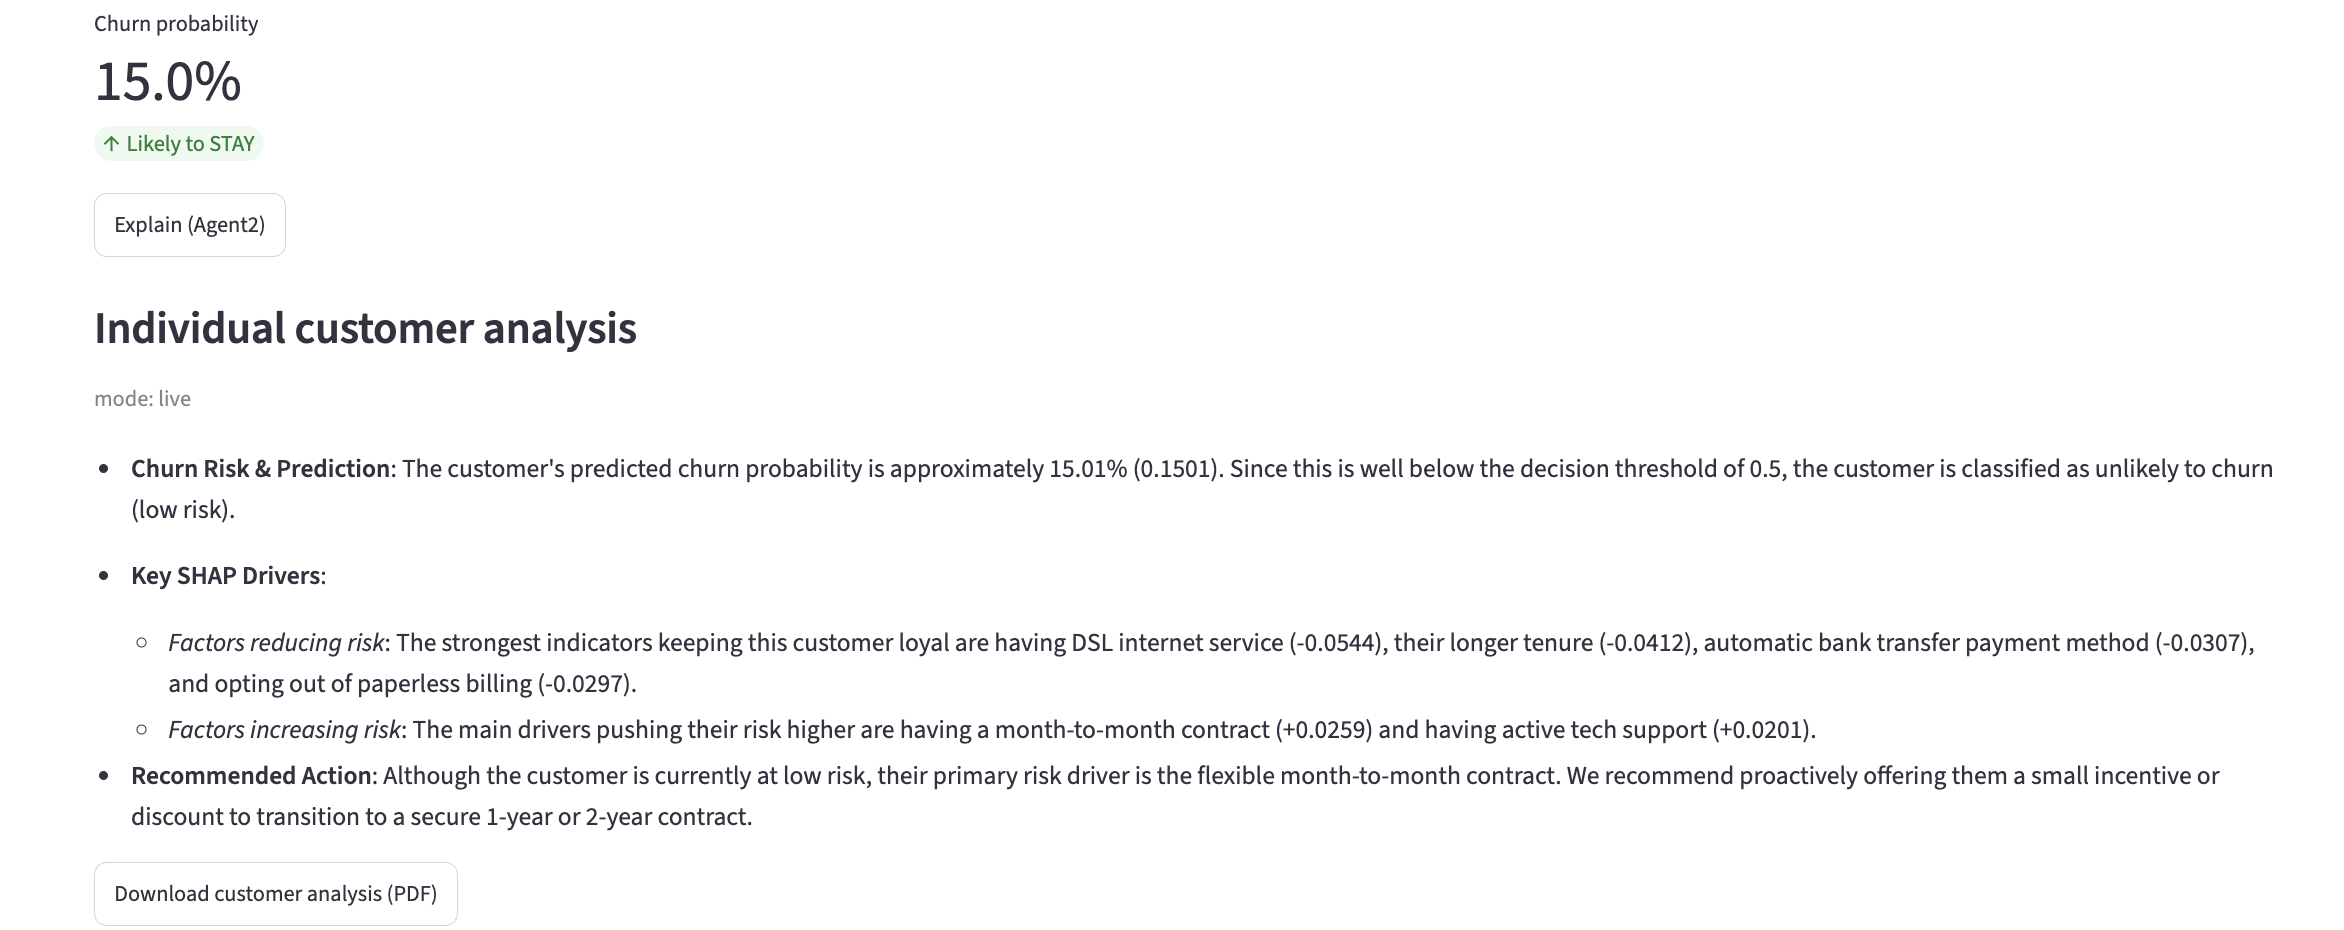
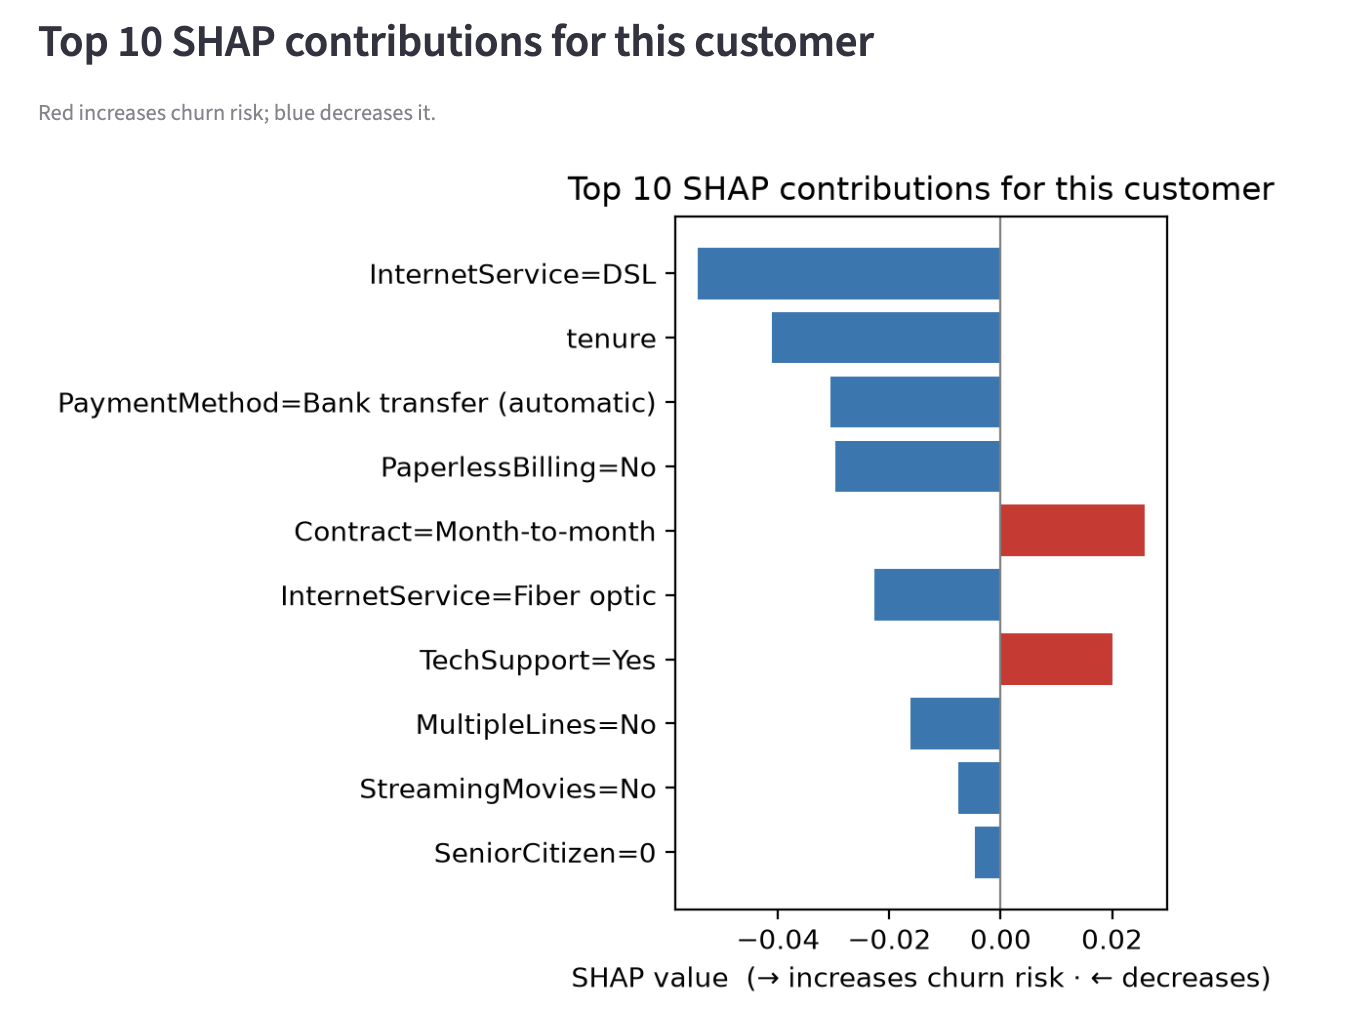
The churn probability is 15.0%, indicating a "high likelihood of continuation," so no countermeasures are needed at this time. That's a relief.

SHAP Analysis of a General Customer

At this point, some of you might be wondering, "But why did the model decide that the likelihood of continuation is high?" This is where "SHAP" (2), shown in the figure above, comes into play. Simply put, it is a "value that indicates which data influenced the model's decision and to what extent." The SHAP graph for this customer extends significantly to the left in the negative direction, indicating that the churn probability is low. SHAP values are assigned to individual customers and show why the model made its decision for each specific customer. It is very helpful for us when trying to understand the results.


2. How to Prevent Customer Churn

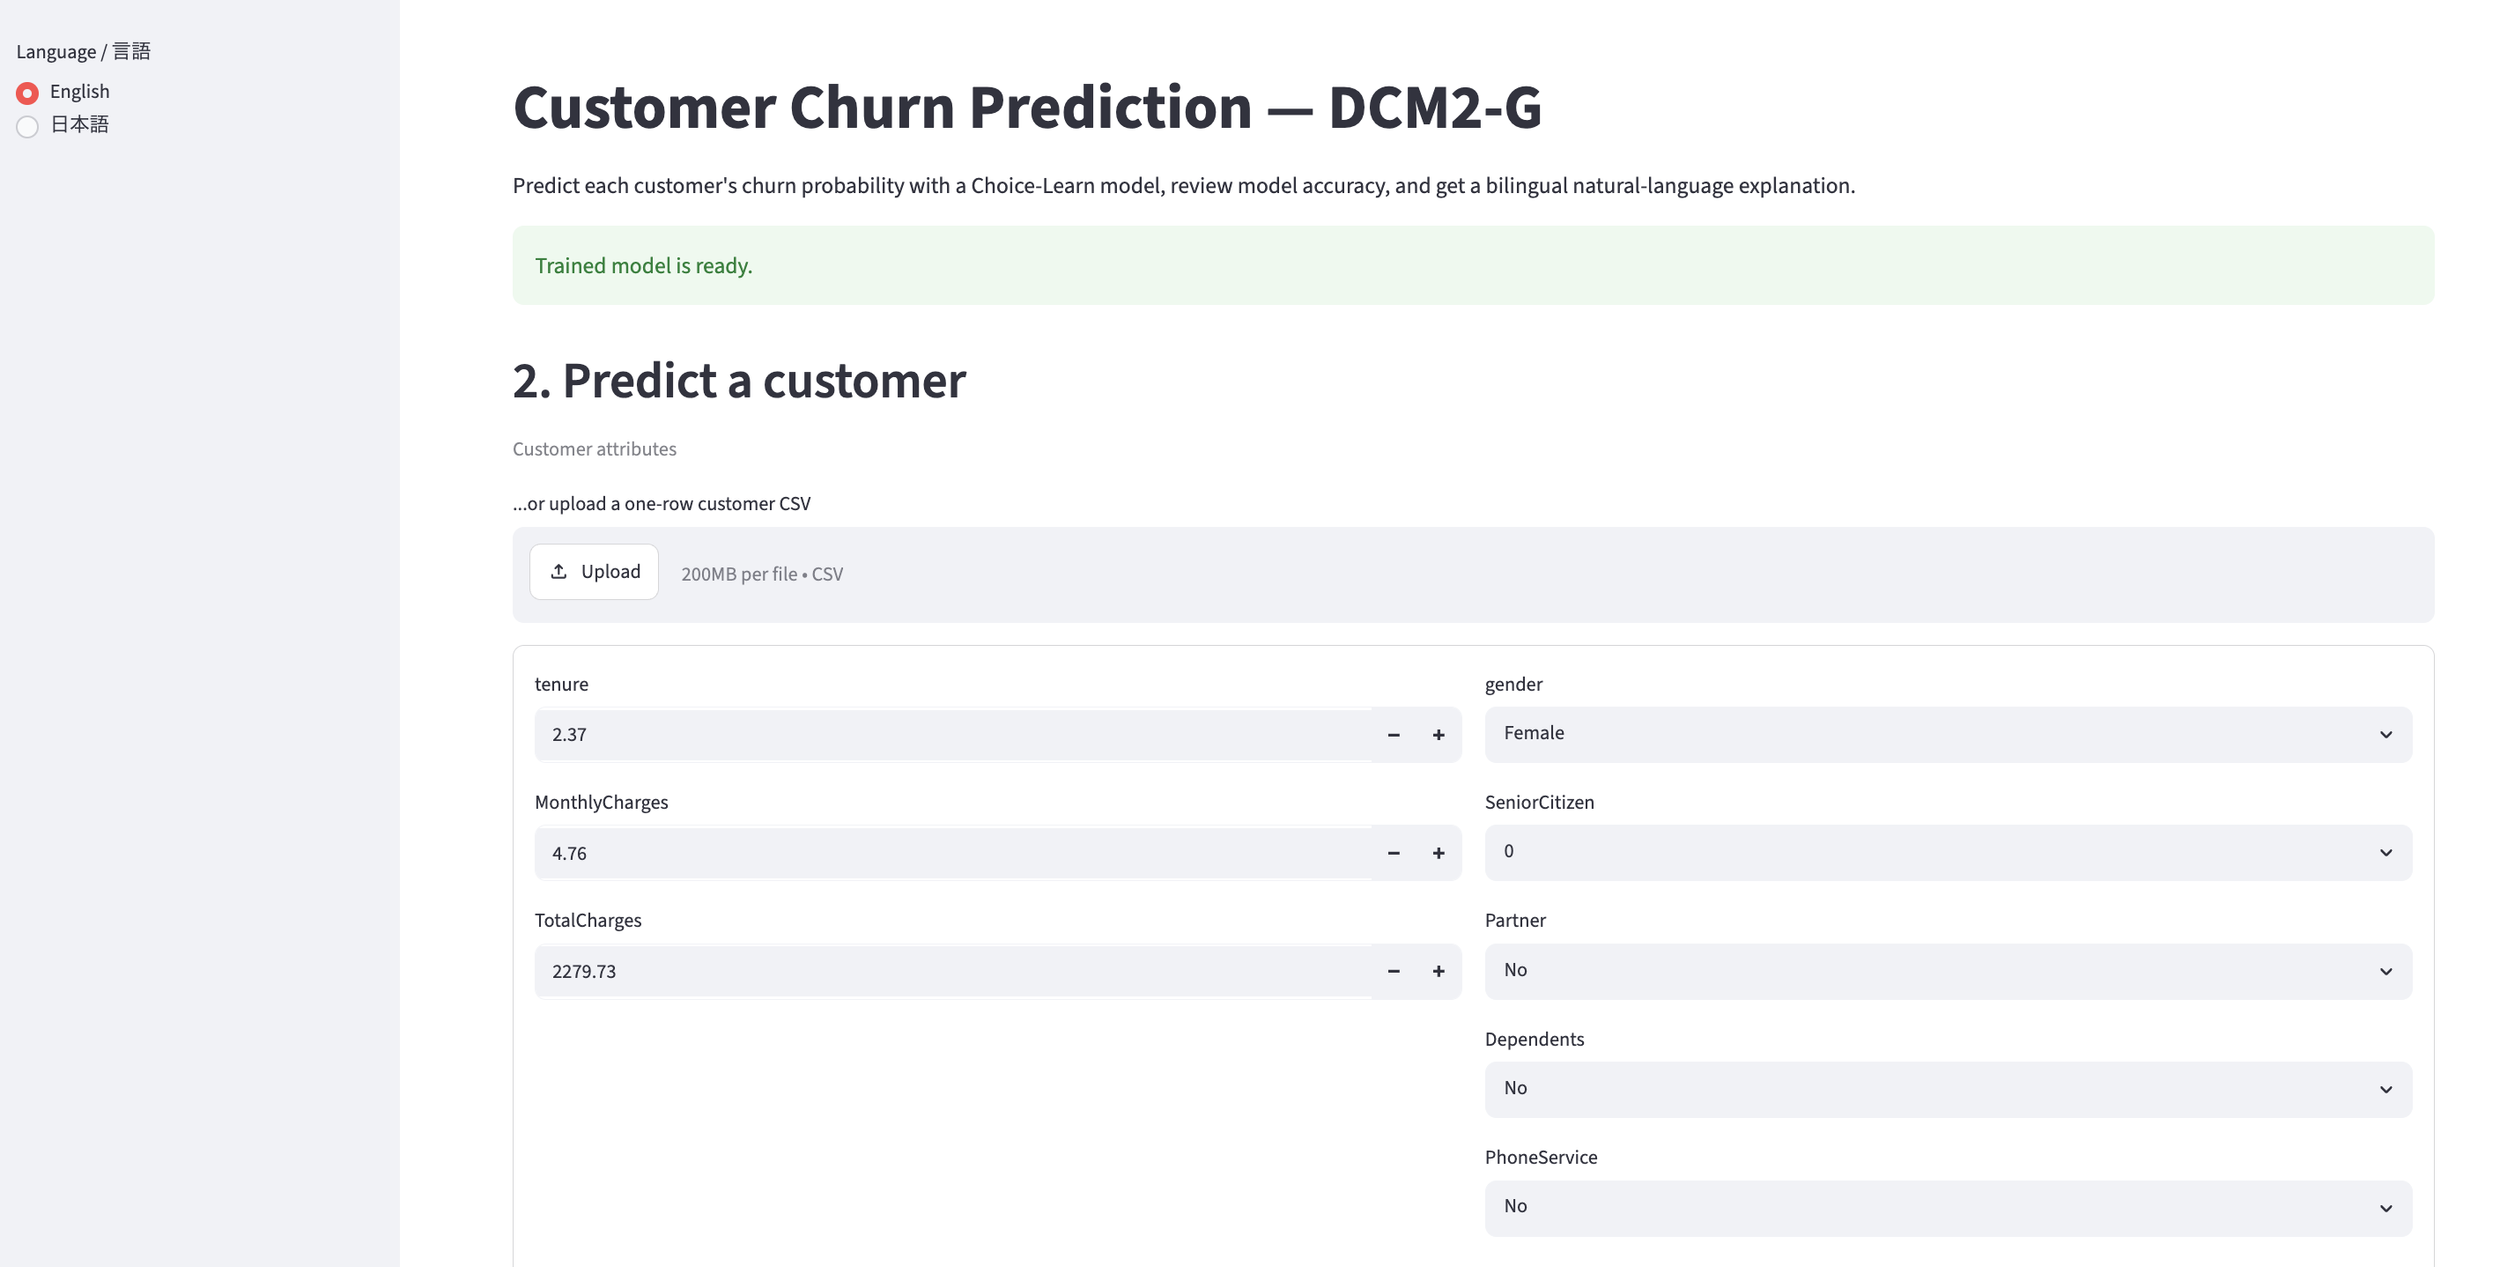
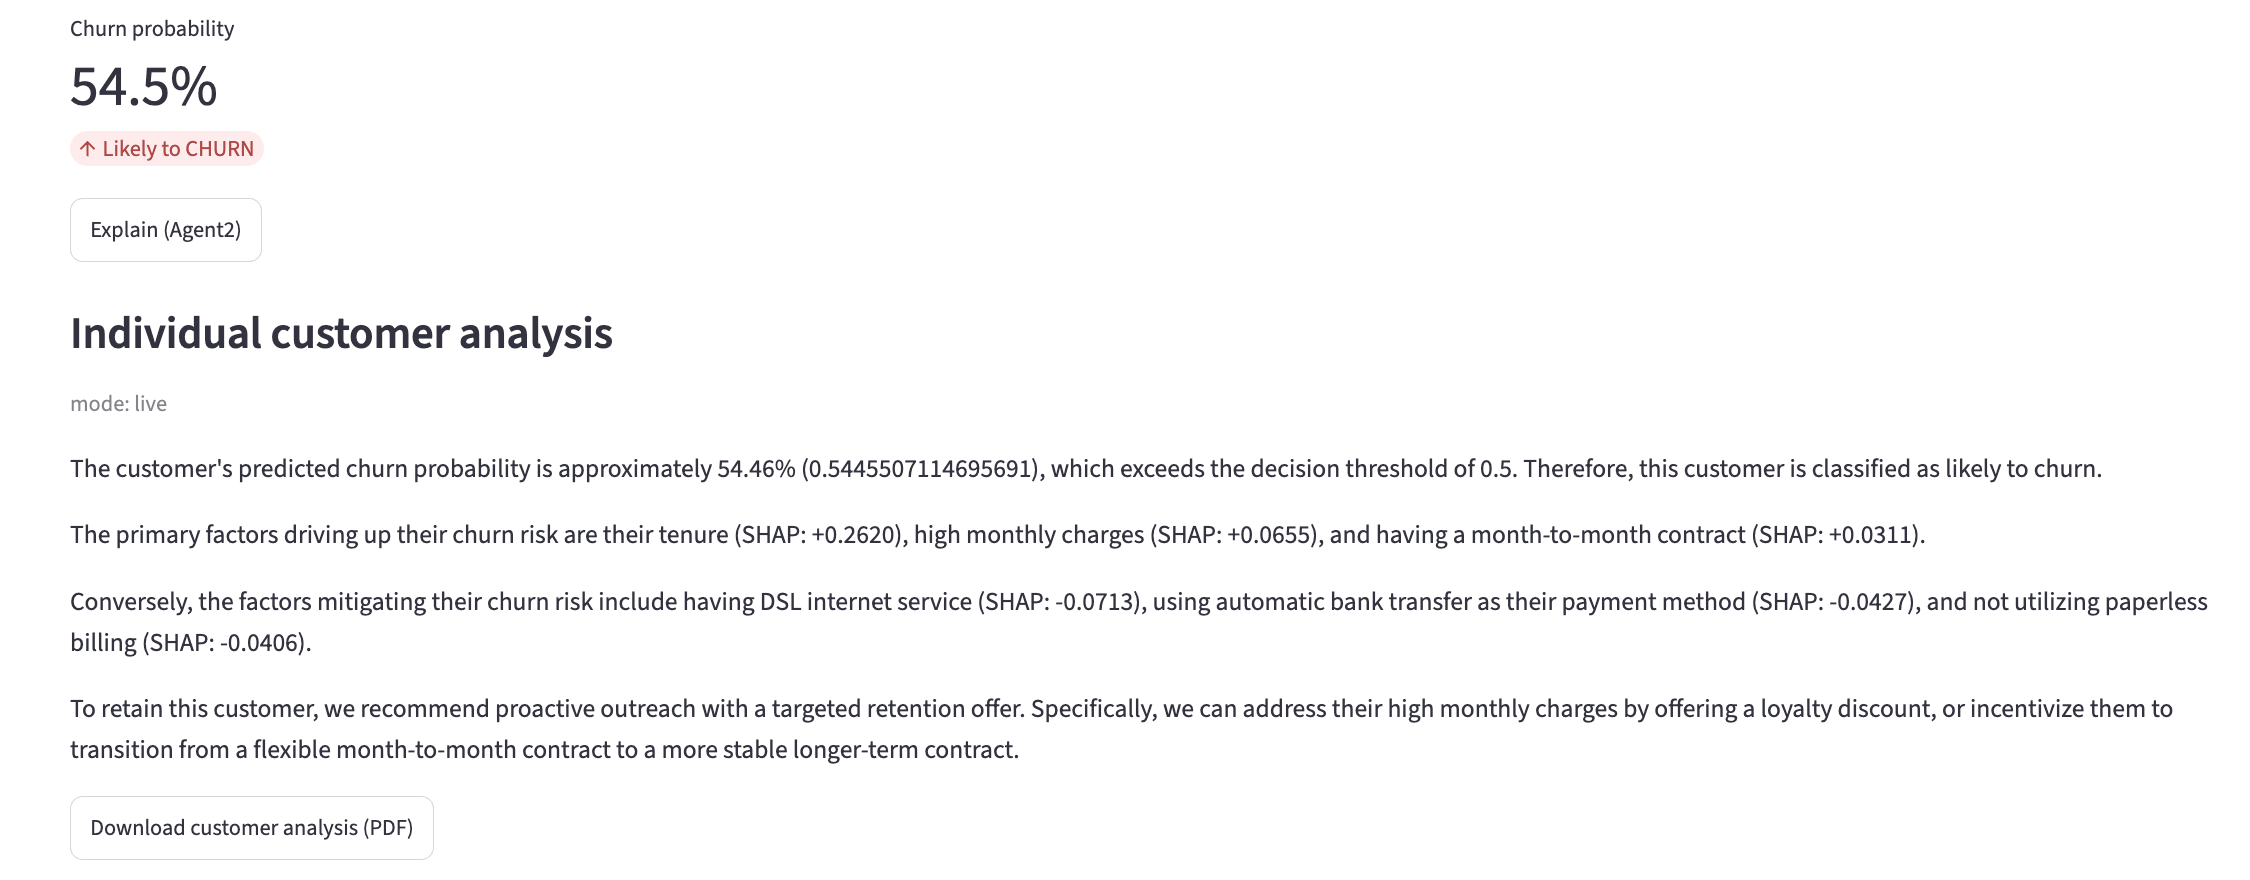
Now, let's look at a customer who is on the verge of churning. Unlike before, the churn probability is 54.5%, indicating a "high likelihood of churning," which suggests that some countermeasures are necessary.

Customer Likely to Churn

Analysis of a Customer Likely to Churn

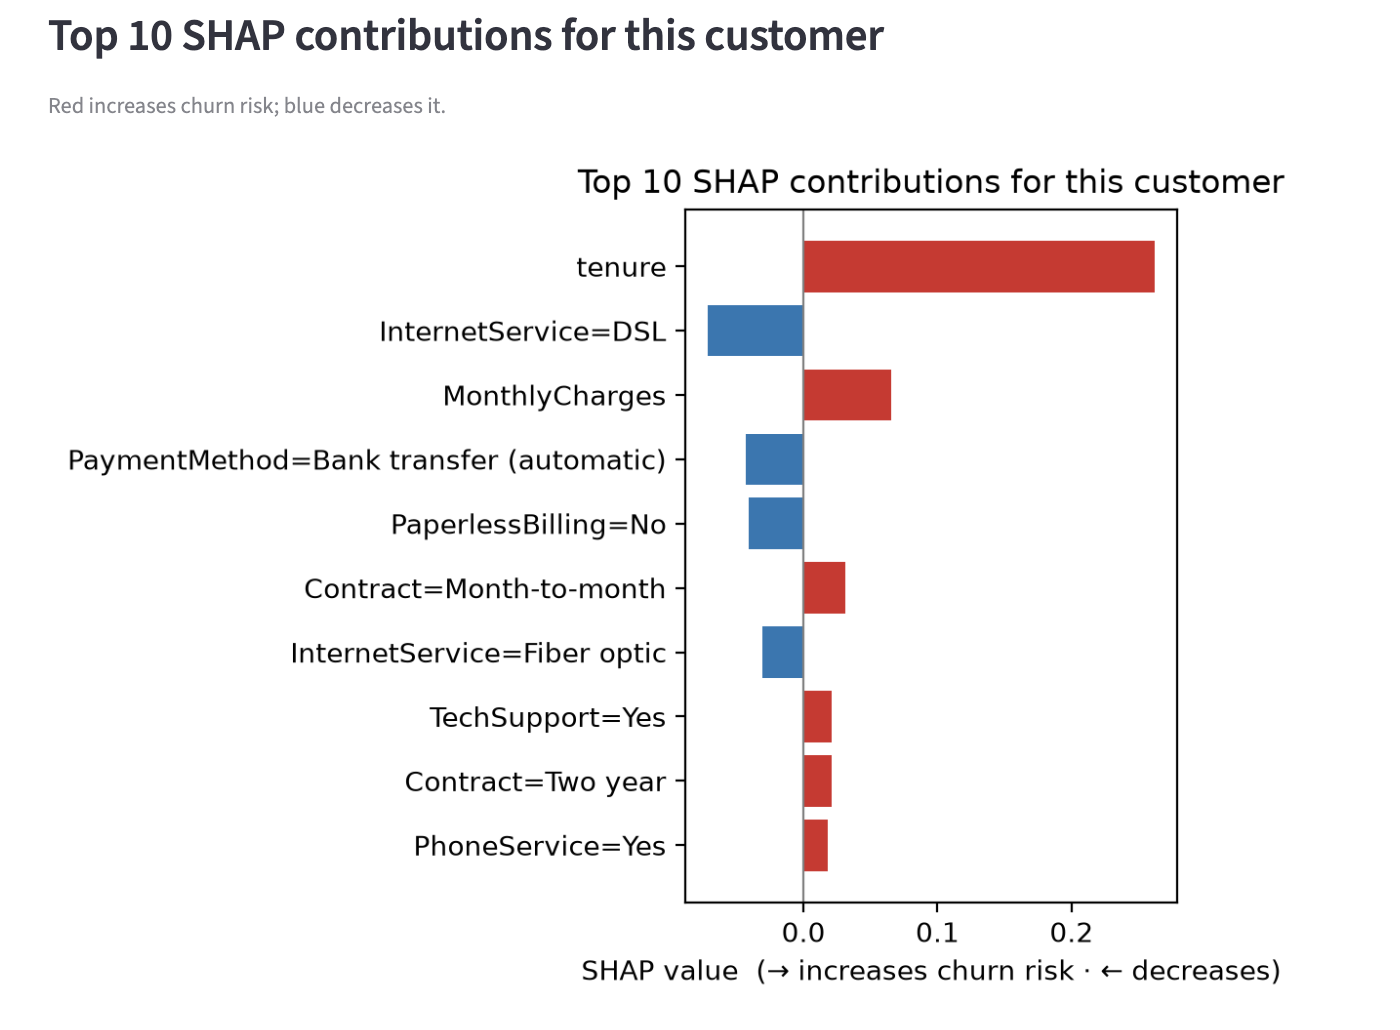
SHAP Analysis of a Customer Likely to Churn

You can see that the SHAP graph, unlike the previous one, extends significantly to the right. In particular, tenure and MonthlyCharges are large, serving as the main factors that increased this customer's churn probability.

Also, in the explanatory text for "Individual Customer Analysis," it states:

“To retain this customer, we recommend proactive outreach with a targeted retention offer. Specifically, we can address their high monthly charges by offering a loyalty discount, or incentivize them to transition from a flexible month-to-month contract to a more stable longer-term contract.”

This is a personalized retention measure for this specific customer. It is not a generic strategy. This is because, as stated in the explanation, it was created by the generative AI, Gemini 3.5 Flash, based on the individual customer's analysis results:

“The primary factors driving up their churn risk are their tenure (SHAP: +0.2620), high monthly charges (SHAP: +0.0655), and having a month-to-month contract (SHAP: +0.0311).”

It is trustworthy precisely because it is a measure tailored to the individual customer's situation. Fantastic!


3. For Further Development

In machine learning and AI, the quantity and quality of the input data are always the key. As these increase, diverse analyses become possible, and accuracy improves. In other words, I believe it is possible to elevate this into a marketing analytics platform in the future. I am really looking forward to its future developments. As the core technologies for this product development, I used Google Gemini 3.5 Flash for natural language processing, Choice-Learn for machine learning, and Google ADK for AI agent implementation. For app development, I am using ClaudeCode. These core technologies do not need to be fixed forever; I think it is best to flexibly use or replace them as needed. Since technological advancement is fast, I plan to adopt the optimal tools available at any given time.


What did you think? I felt that with "Machine Learning + AI," we can create fantastic products where they complement each other perfectly. I'm excited about future developments. Here at Toshi Stats, we plan to continue tackling tasks in the marketing field using "Machine Learning + AI." Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) Gemini 3.5 Flash Best for frontier performance across agents and coding,  Google DeepMind
2) Welcome to the SHAP documentation

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Can AI Agents Invent New Economics? The Future of Theory Generation

Economics offers many theories that are highly useful in business. For example, the economic theory awarded the 2020 Nobel Prize in Economics (1) actually made a massive contribution to the design of spectrum allocation auctions in the United States, successfully creating a market worth over 100 billion dollars. Therefore, this time, I created a simple app using the mathematical proof program LEAN (2) to experiment and see if an AI agent using LEAN can be applied to economics. Let's get right into it.


1. Overview of the Developed App

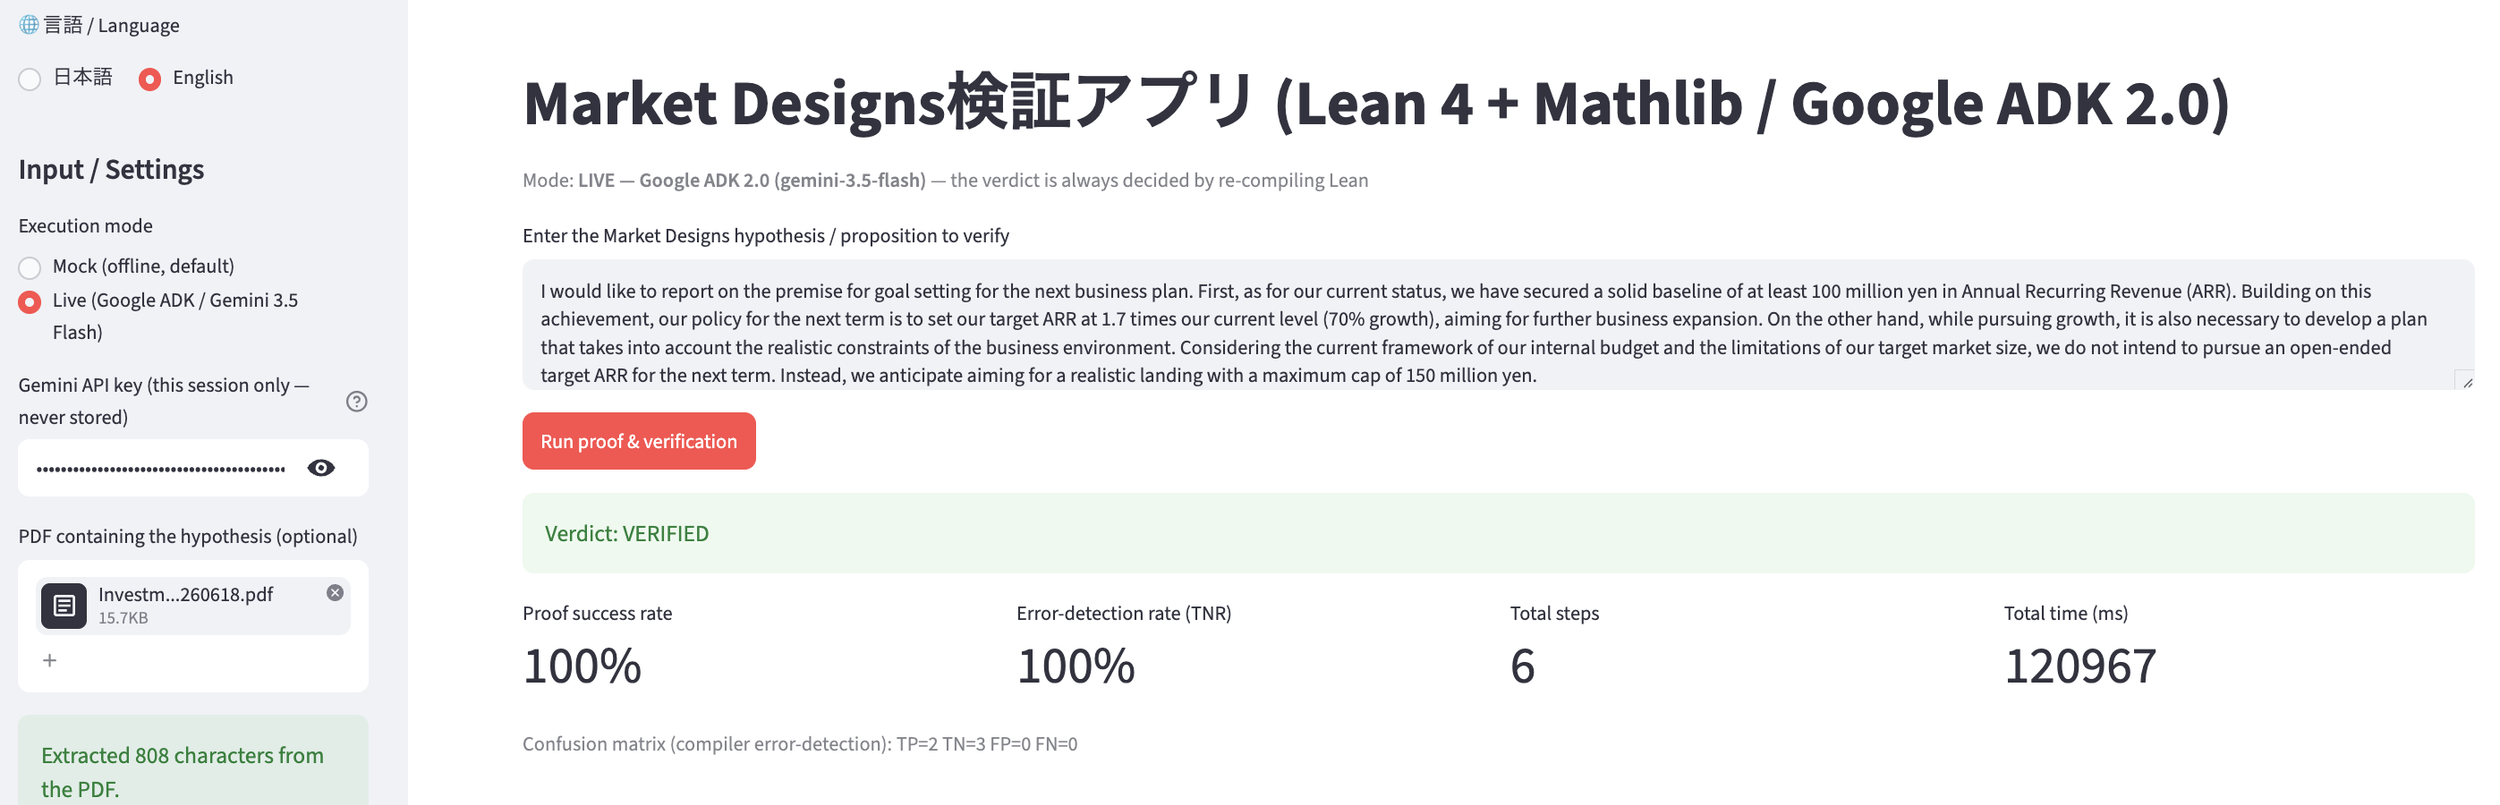
Here is the app's screen. Because of my interest in building new markets, I named it the "Market Designs Verification App." It takes economic propositions and hypotheses and uses LEAN to automatically determine if there are any logical contradictions. I used Google Gemini 3.5 Flash for the natural language processing and Google ADK for the AI agent implementation. For the app development itself, I used Claude Code.

               Market Designs Verification App

The proposition provided this time is as follows. It serves as an example of a simple business plan.

"I would like to report on the premise for goal setting for the next business plan. First, as for our current status, we have secured a solid baseline of at least 100 million yen in Annual Recurring Revenue (ARR). Building on this achievement, our policy for the next term is to set our target ARR at 1.7 times our current level (70% growth), aiming for further business expansion.

On the other hand, while pursuing growth, it is also necessary to develop a plan that takes into account the realistic constraints of the business environment. Considering the current framework of our internal budget and the limitations of our target market size, we do not intend to pursue an open-ended target ARR for the next term. Instead, we anticipate aiming for a realistic landing with a maximum cap of 150 million yen."

I want to verify this hypothesis using LEAN to confirm whether it is feasible. Of course, I want to avoid any hallucinations caused by the LLM.


2. Looking at the Analysis Report

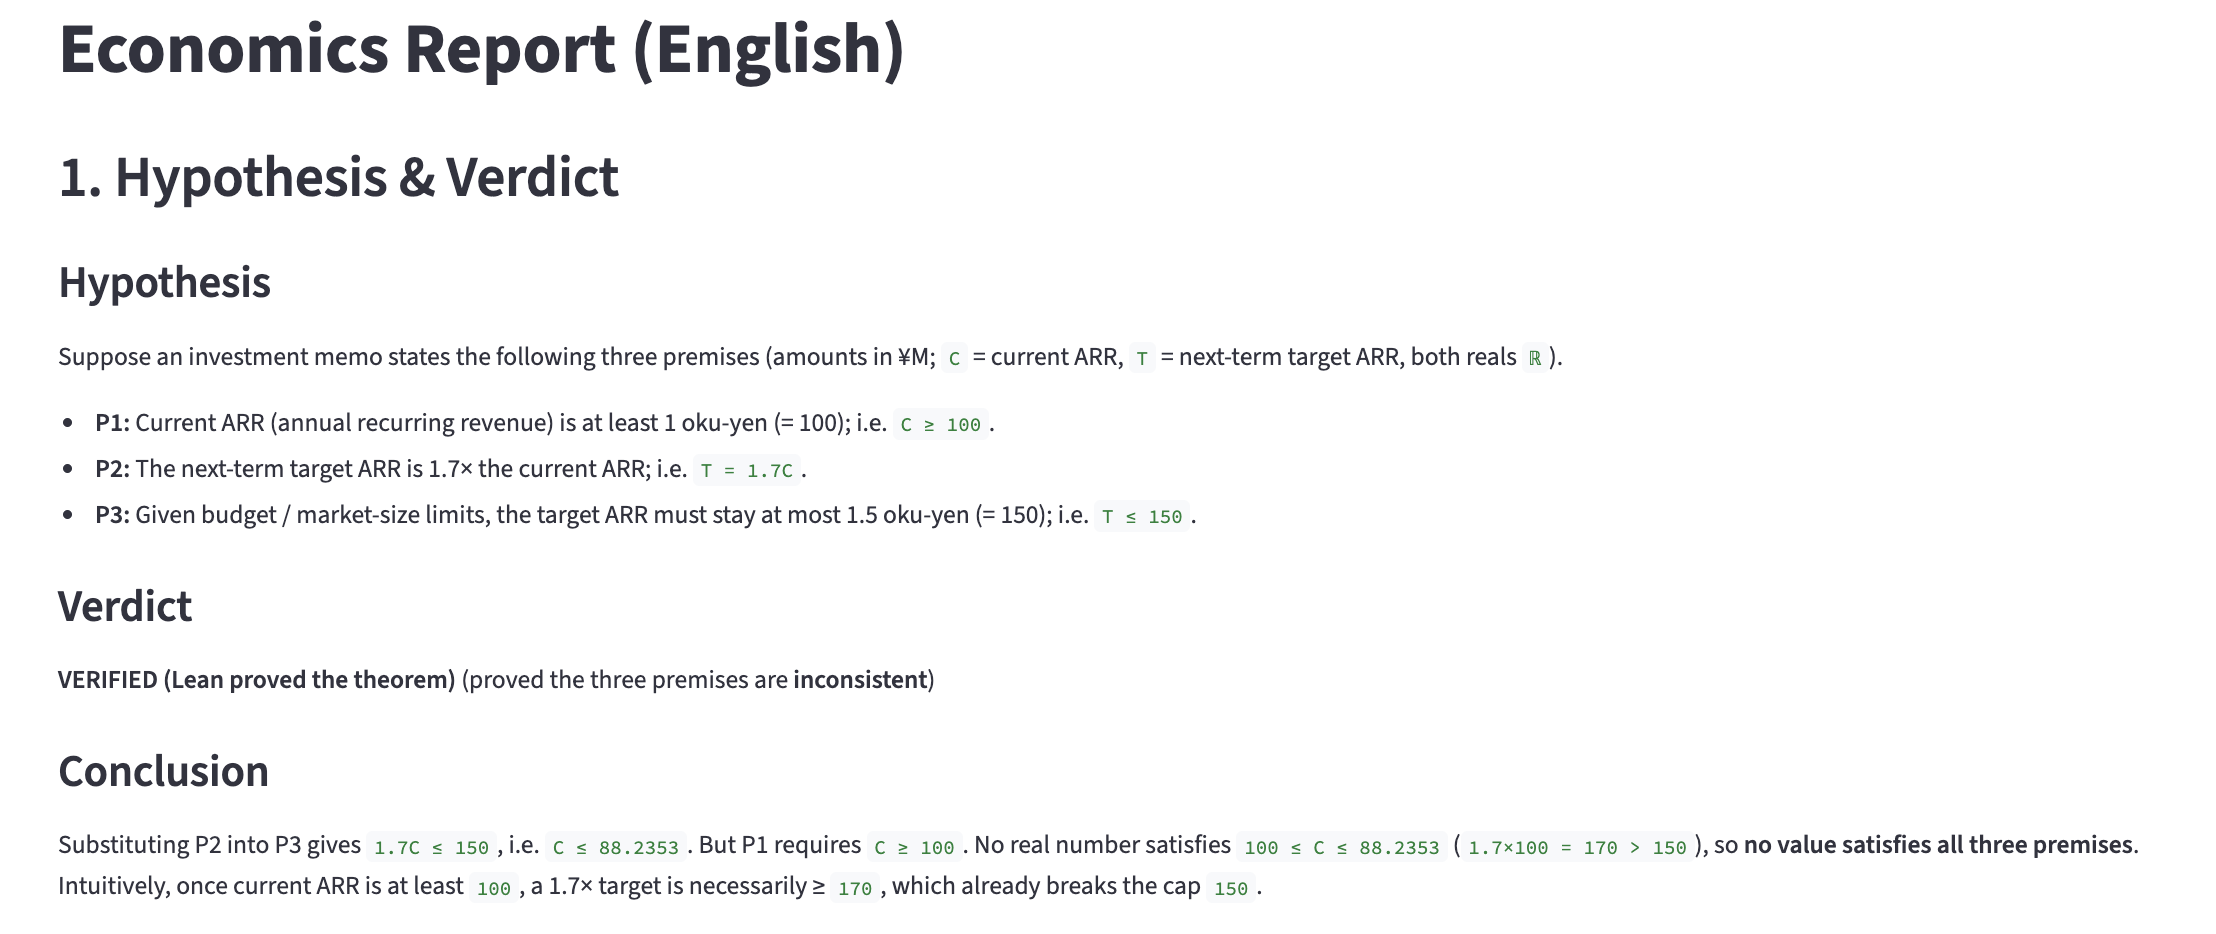
When executing this app, the following report was generated in about 3 minutes. Let's take a look. First, the hypothesis, judgment, and conclusion are summarized. The bottom line is that the growth target exceeds the constraints, meaning execution is impossible.

Final Report

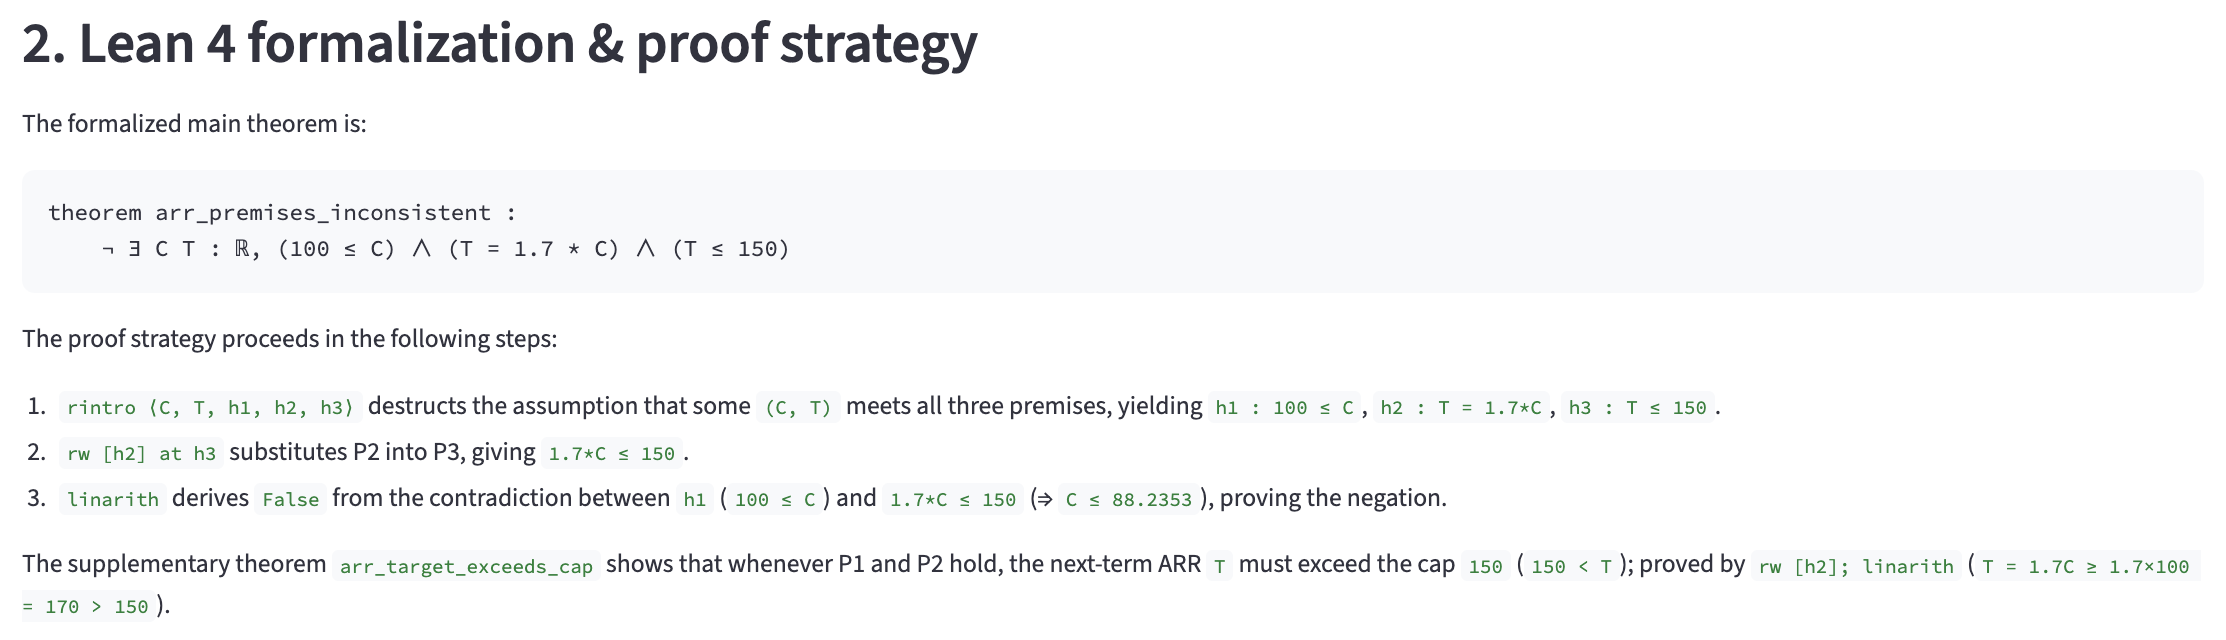
The actual verification process using LEAN is displayed. It is a bit complex.

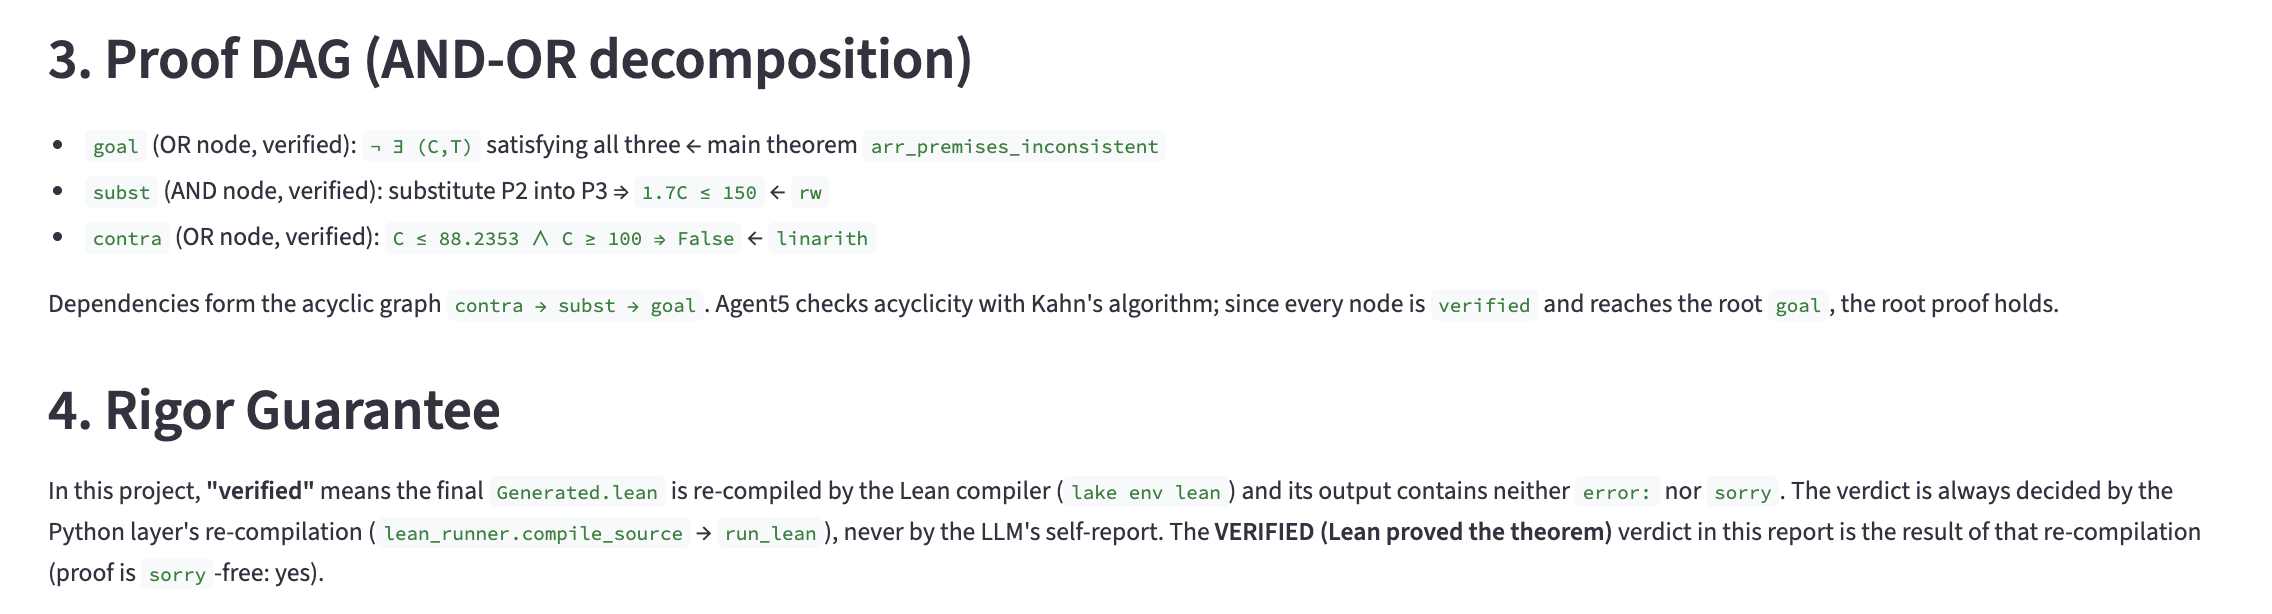
A DAG (Directed Acyclic Graph) is also used. In LEAN, once the compilation finishes, the verification is complete, meaning the proof has been established. Because it is executed strictly, the results are reliable. It is reassuring because there are no hallucinations like those seen with LLMs.


3. Implications Obtained

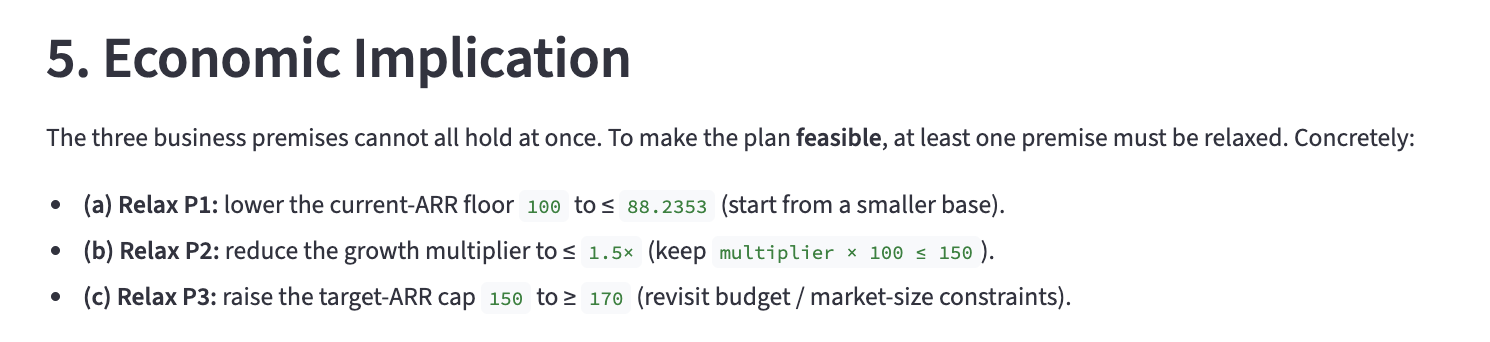
The implications obtained are as follows:

5. Economic Implication

The three business premises cannot all hold at once. To make the plan feasible, at least one premise must be relaxed. Concretely:

  • (a) Relax P1: lower the current-ARR floor 100 to ≤ 88.2353 (start from a smaller base).

  • (b) Relax P2: reduce the growth multiplier to ≤ 1.5× (keep multiplier × 100 ≤ 150).

  • (c) Relax P3: raise the target-ARR cap 150 to ≥ 170 (revisit budget / market-size constraints).

Based on these results, we must leverage them for business decision-making. This time, the results are well summarized, making them easy to understand. This is where the flexibility of LLMs comes into play. It is reassuring that if we can verify even complex management strategies with LEAN, we can automatically determine whether they can be executed without contradictions. In the future, this is expected to become an excellent advisor in boardroom meetings.


What did you think? It was a simple hypothesis verification, but I believe it is entirely possible to apply LEAN to economics. I felt that combining the flexibility of LLMs with the strictness of LEAN creates a wonderful system where they beautifully complement each other. I am looking forward to future developments. At Toshi Stats, we plan to continue tackling tasks in the field of economics using LLM + LEAN. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!


1) Stanford Economists Paul Milgrom and Robert Wilson Win the Nobel in Economic Sciences, Stanford Graduate School of Business, Oct 12, 2020
2) LEAN


Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Logic-Powered Agents: How LLMs Evolution in Math is Shaping the Future of AGI

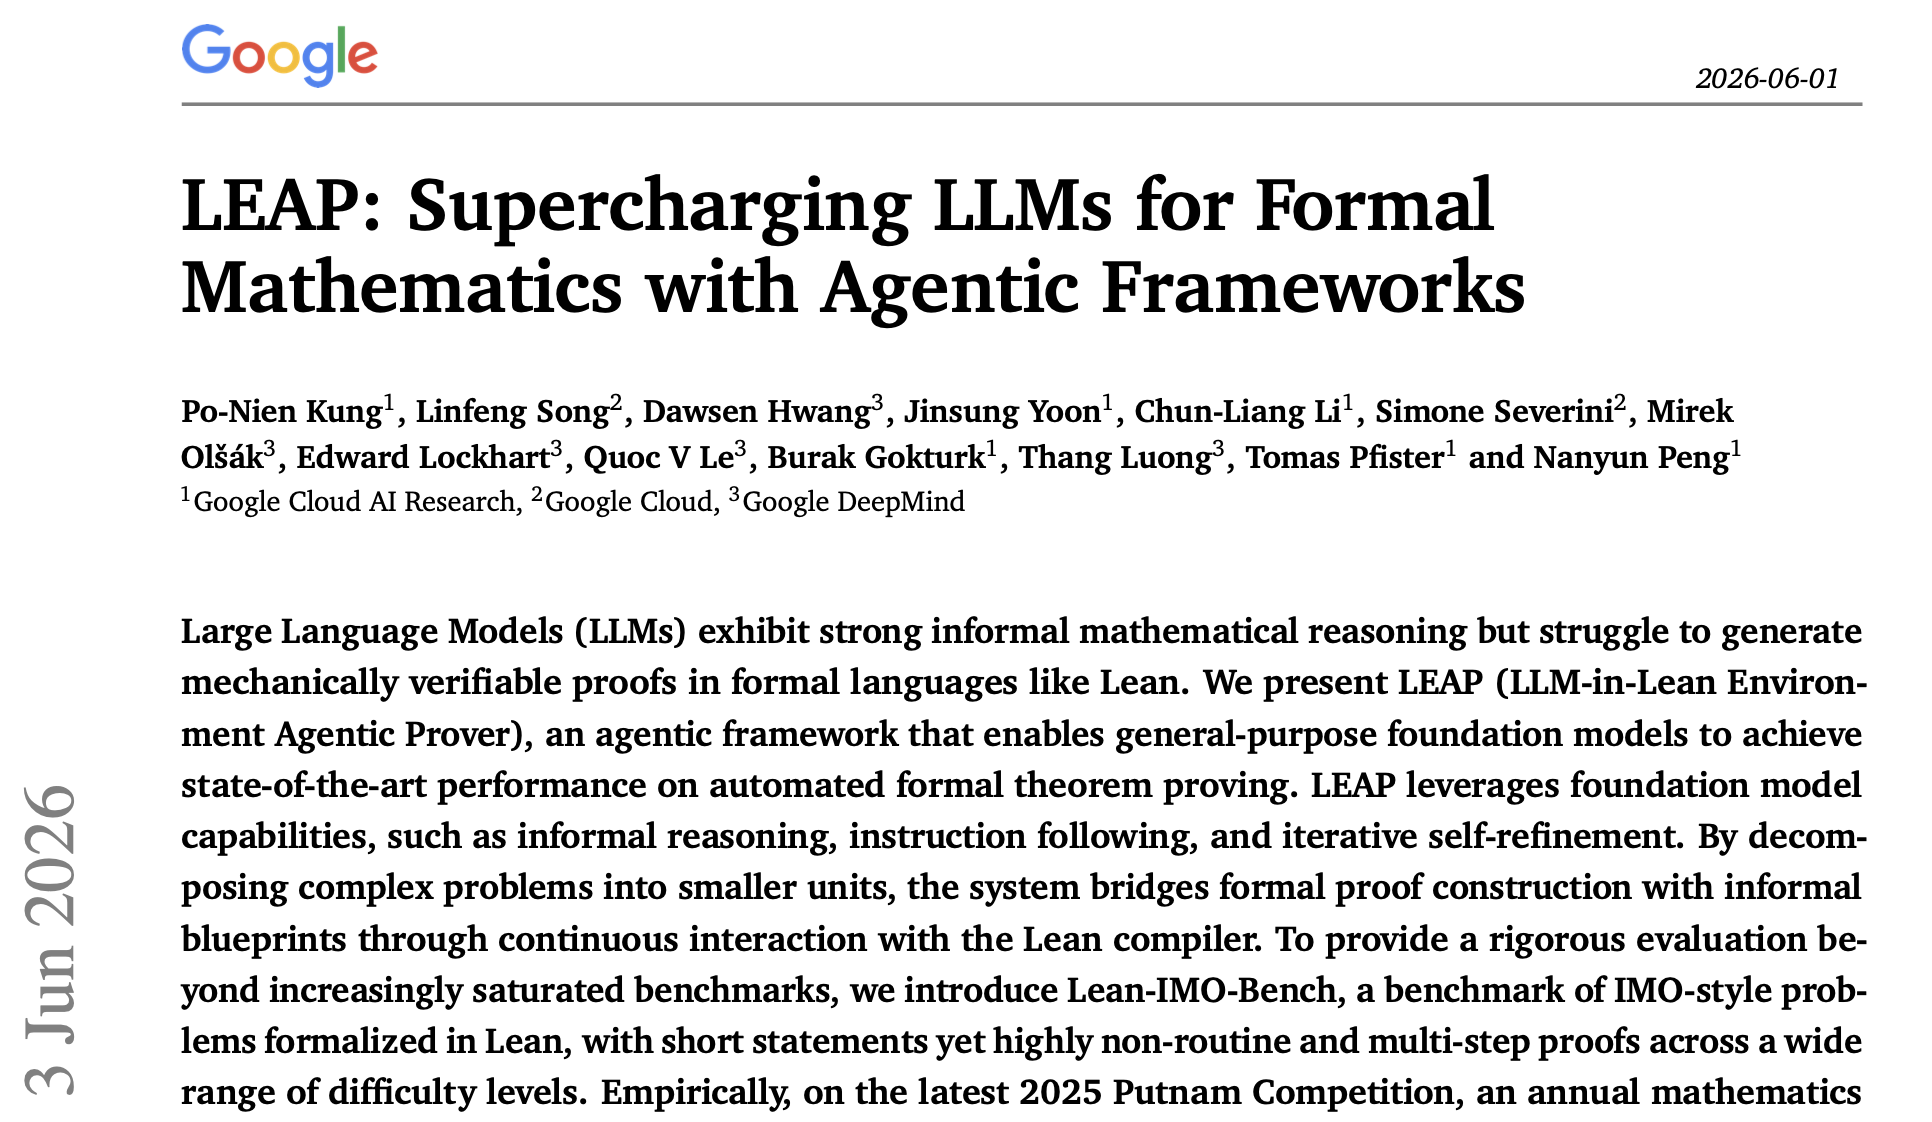
On June 3rd, a new research paper (1) was released by Google. It states that difficult mathematical proofs were solved by combining the LLM Gemini 3.1-pro with a mathematical proof language called LEAN (2). This time, I would like to delve into this paper and consider what kind of developments we can expect from this new AI agent in the future, beyond the framework of mathematics.


1. The Synergistic Effect of the LLM's Flexibility and LEAN's Strictness

Here is the paper, featuring an active AI agent called LEAP. It only uses Gemini 3.1-pro as the LLM, and no specific fine-tuning has been performed. It is being used straight out of the box. Even so, it is reported to demonstrate outstanding exploration capabilities in mathematical proofs. Since it doesn't require any particular additional training, it can be used immediately without doing anything, which is very convenient for practical use. Furthermore, by using LEAN in conjunction, if a proof with contradictory logic due to hallucinations is produced, an error occurs during compilation, creating a mechanism where it is automatically rejected.

         LEAP (LLM-in-Lean Environment Agentic Prover)

Since LLM responses can fluctuate probabilistically, humans need to verify them in detail when conducting rigorous arguments. However, by introducing LEAN, this process has been automated. This is very reassuring. It seems that this fantastic result was achieved by combining the flexibility of the LLM and the strictness of LEAN in this way. Let's look closer.


2. The Structure and Accuracy of LEAP

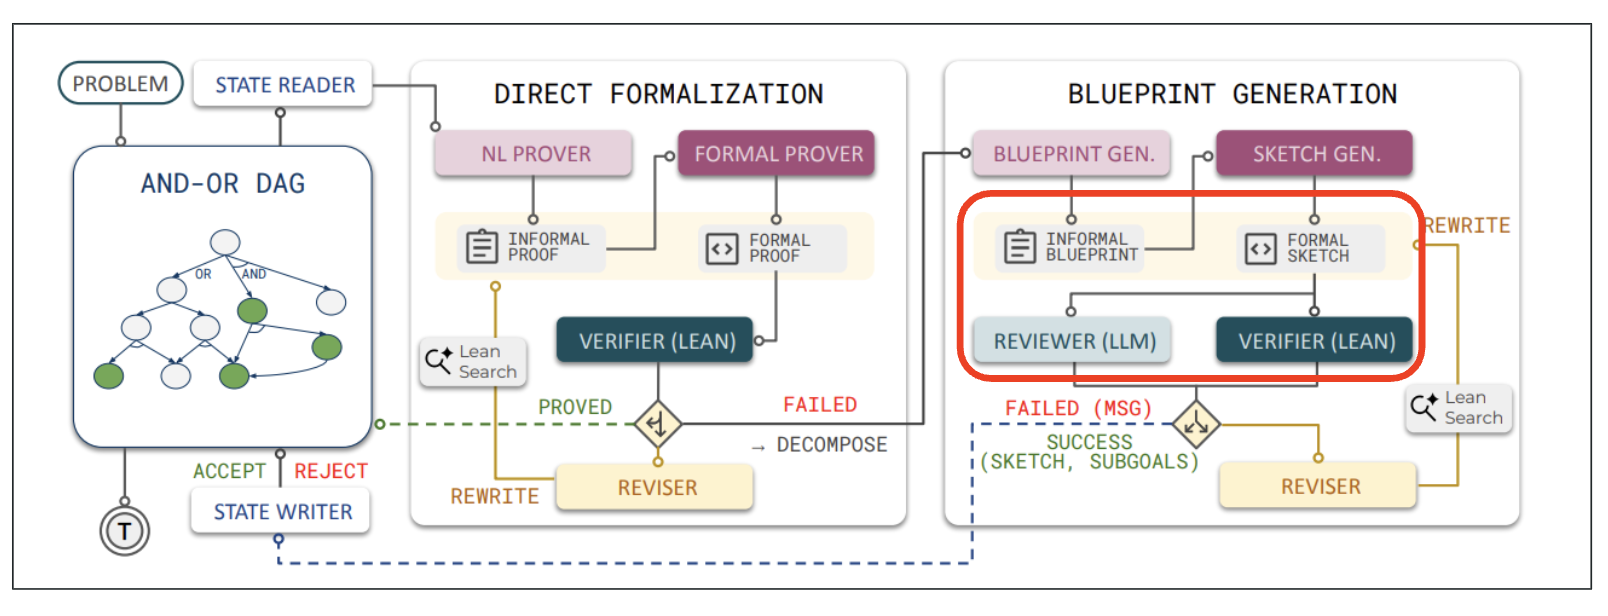
Here is the structure of LEAP. The figure on the left is the roadmap for the theorem to be proved using LEAN. Technically, it forms a structure called a DAG (Directed Acyclic Graph). Complex mathematical proofs are not completed in a single attempt; the proof progresses by going back and forth between the LLM and LEAN several times. The key here is the section in the red frame, where the LLM describes an INFORMAL BLUEPRINT in natural language and converts it into a FORMAL SKETCH in LEAN. Furthermore, a two-tier review by LEAN and the LLM awaits. LEAN verifies whether the new proof method has any contradictions, and the LLM's review verifies whether that method is genuinely effective. In other words, the LLM acts as a pilot in the search for proof methods. Even though it's just using Gemini 3.1-pro as is, its potential is truly surprising.

                LEAP workflow

Now, let's look at the results of applying LEAP to an actual task. It tackled the notoriously difficult Putnam 2025. Putnam 2025 contains twelve undergraduate-level problems from the 86th William Lowell Putnam Mathematical Competition, a highly challenging North American mathematics competition.

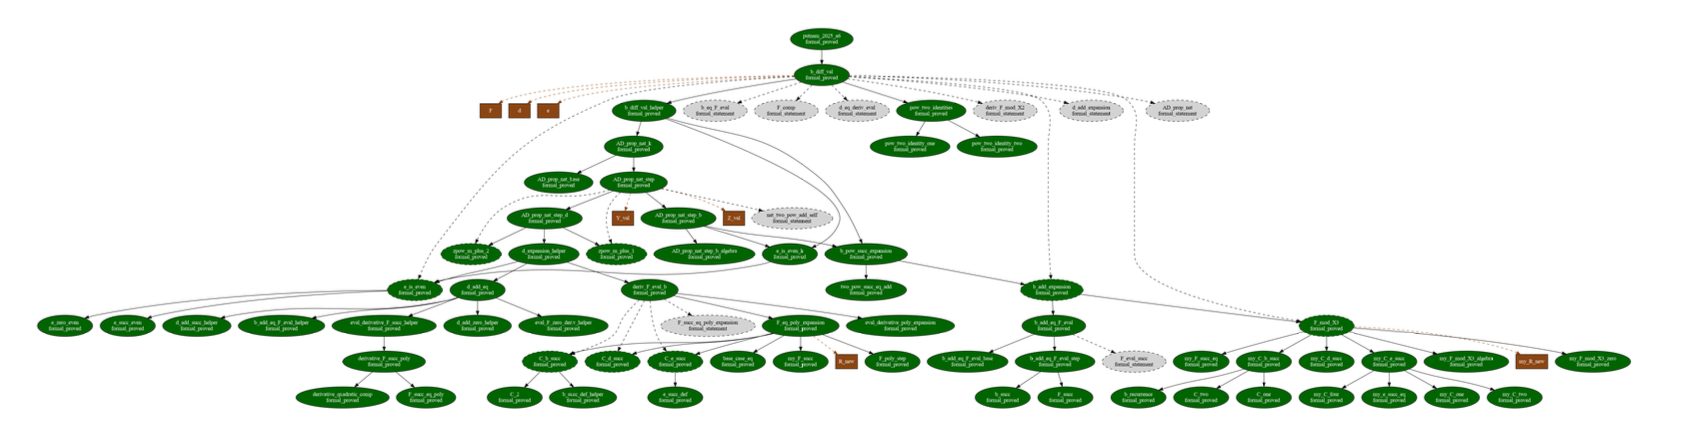
Looking at the DAG, you can see how the proof actually progresses. In this example of Putnam 2025 Problem A6, you can see layers upon layers of connected proofs. It's certainly a difficult problem. The green indicates the parts that have already been proven.

            DAG example for Putnam 2025 Problem A6

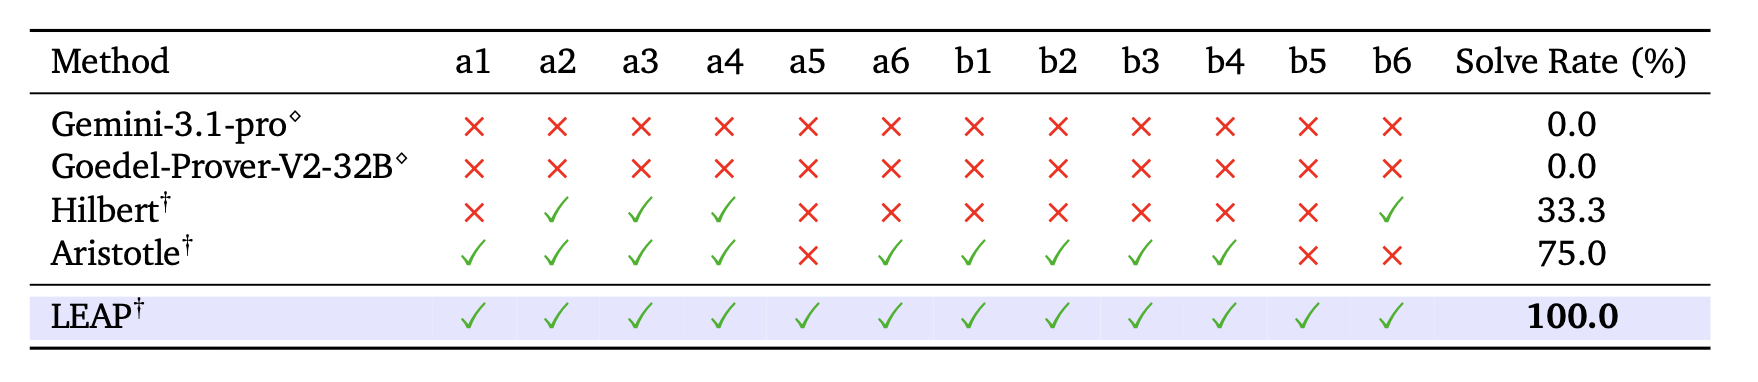
The results, as shown below, were that LEAP answered all questions correctly. An overwhelming accuracy.

                Results on Putnam 2025

You can see that while the original Gemini 3.1-pro couldn't score at all, it was able to demonstrate tremendous capabilities by combining it with LEAN. I think it is truly a breakthrough.


3. Beyond Mathematical Proofs into Various Fields

What we have seen so far were tasks related to mathematical proofs. With LEAP being able to construct such perfect logic, I felt it would be a waste to keep it confined solely to mathematics. In particular, its application to economics, which is directly linked to business practices, has immense scope and depth, and I believe it can contribute to expanding the areas where LLMs can be active. Economics is also generally described using mathematical formulas, so I think it has a high affinity with LEAP. A paper (3) on its application to economics has already been published, so if you are interested, please do give it a try.


What did you think? I believe the combination of LLMs and LEAN will be expanded and improved in various ways in the future. It might be stepping closer to AGI. It's very exciting.

At Toshi Stats, we plan to take on tasks in the field of economics moving forward. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, too!

1) LEAP: Supercharging LLMs for Formal Mathematics with Agentic Frameworks, 3 Jun 2026, Google
2) LEAN
3) We Can't Agree to Disagree, Formally: Aumann's Theorem and Assumption Accounting in Lean, May 27, 2026, Ruize Chen, Ben Eltschig, Ken Ono, Jujian Zhang  Axiom Math,  Scott Duke Kominers Harvard University; a16z crypto

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
"Root Cause Analysis" is All You Need !

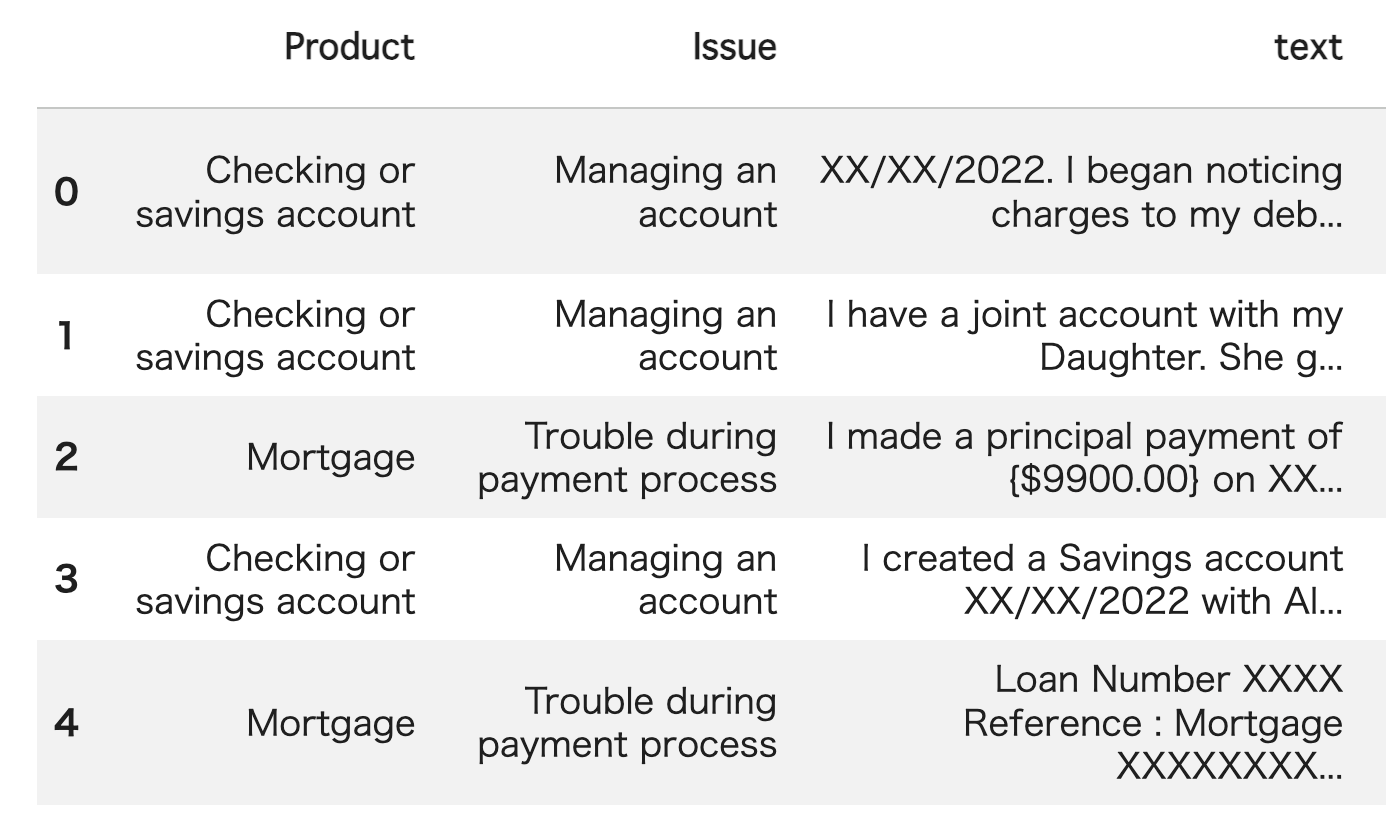
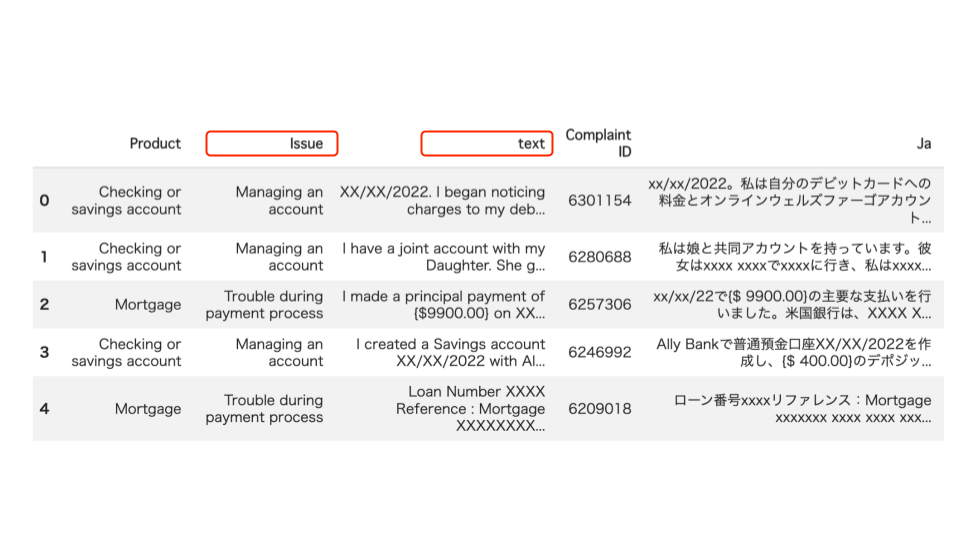
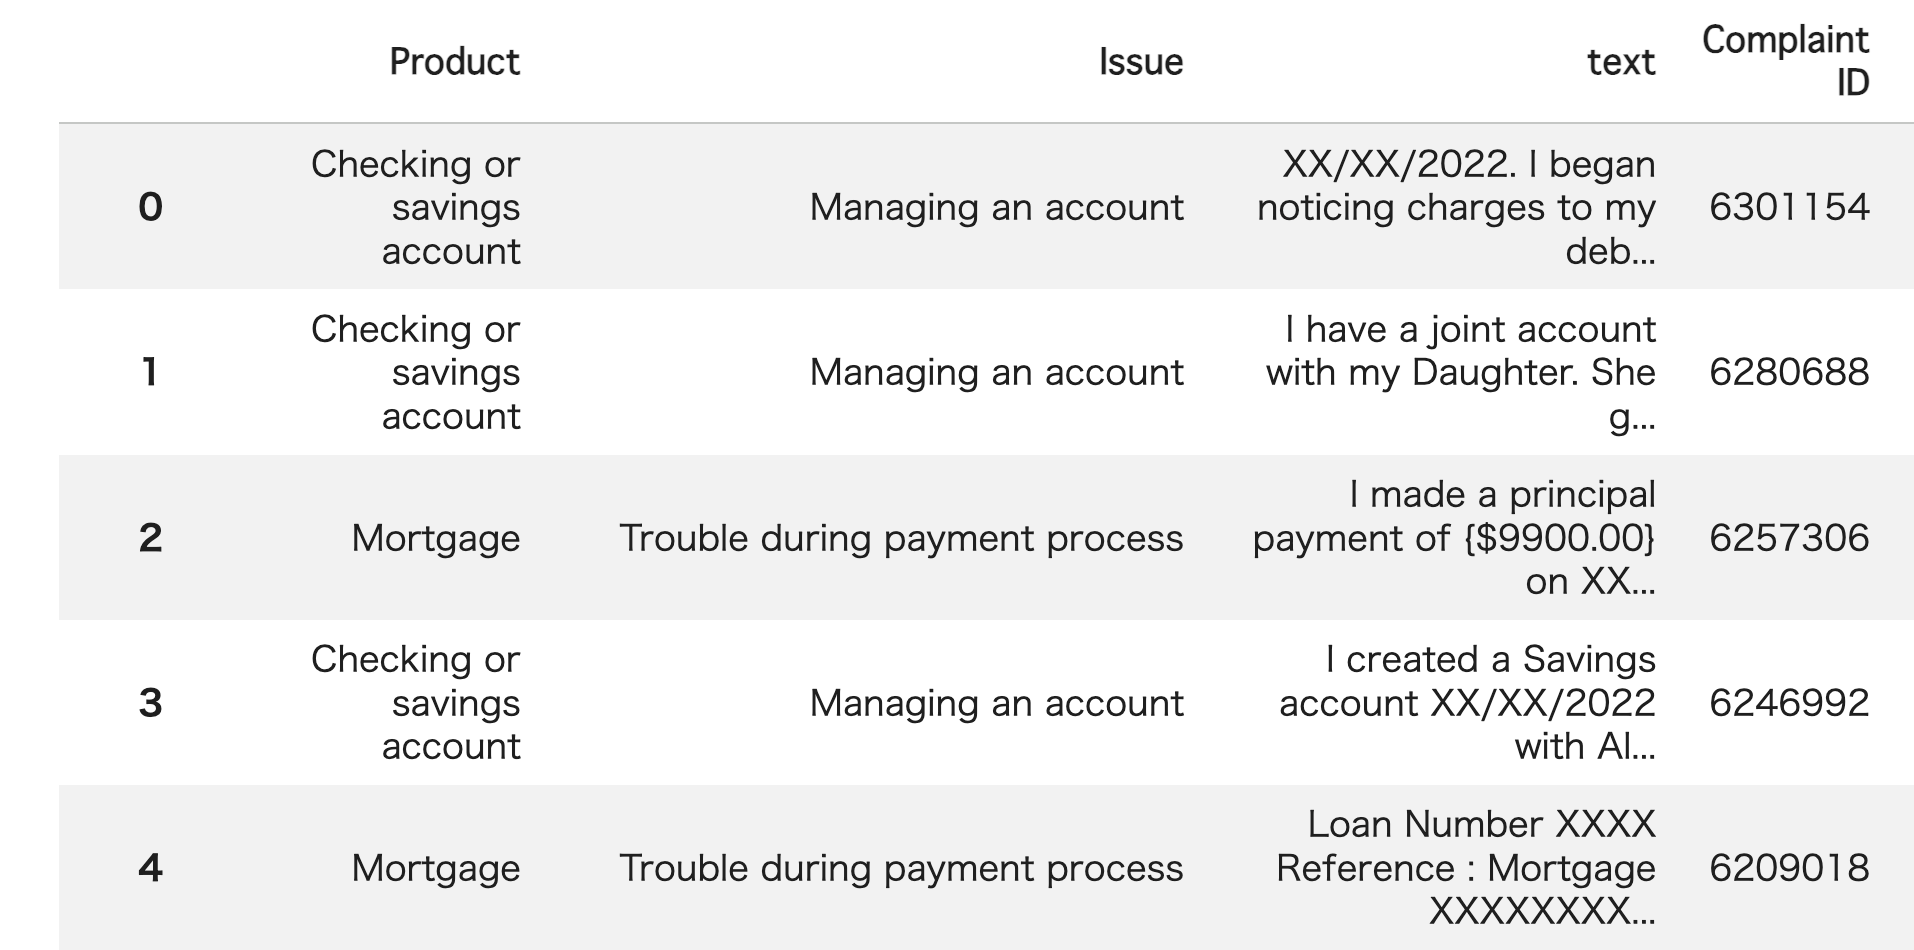
Have you ever tried to automate any classification tasks using Generative AI? I do this quite often, but occasionally, as the number of classification classes increases, the accuracy gradually drops to a point where it is no longer viable for practical business use. So, this time, I will tackle the task of classifying bank customer complaints (1) based on their root causes. There are 20 cause classes in total, making it a difficult problem where a random guess would yield only about a 5% accuracy rate. In the example below, the "text" column contains the customer complaint, and the "Issue," which is the underlying cause, is classified by an AI agent.

              Bank Customer Complaints

We are provided with a mere 100 samples. I would like to implement Root Cause Analysis (RCA) during the classification process to see just how crucial RCA is for improving accuracy. Let's get started right away.


1. What is RCA?

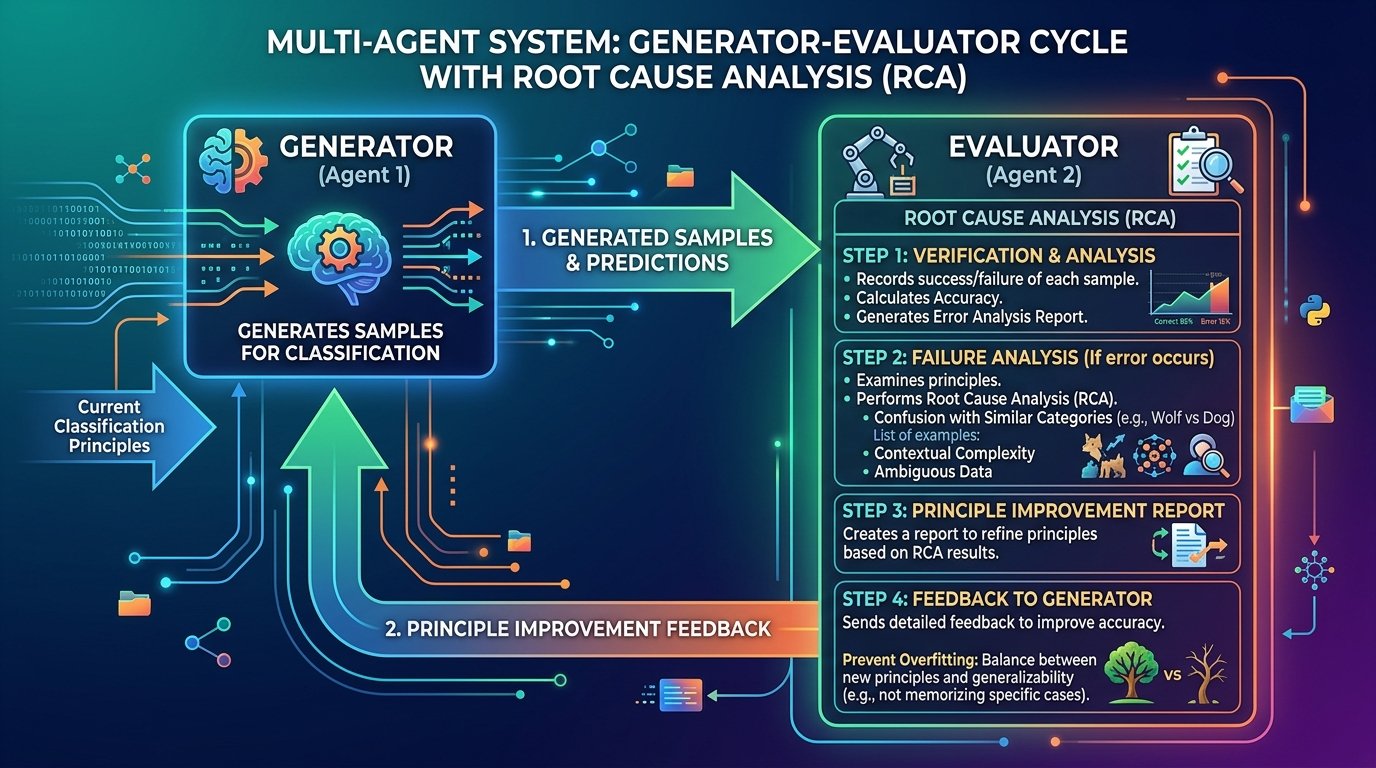
RCA stands for "Root Cause Analysis". When a problem occurs, it is a method used not just to resolve the superficial events (symptoms) you see, but to pinpoint the "true cause (root cause)" in order to prevent a recurrence. This time, I have designed the following RCA approach for classification failures:

Root Cause Analysis (RCA):

  • Record the success/failure of each sample.

  • Verification: Calculate the accuracy and generate an error analysis report.

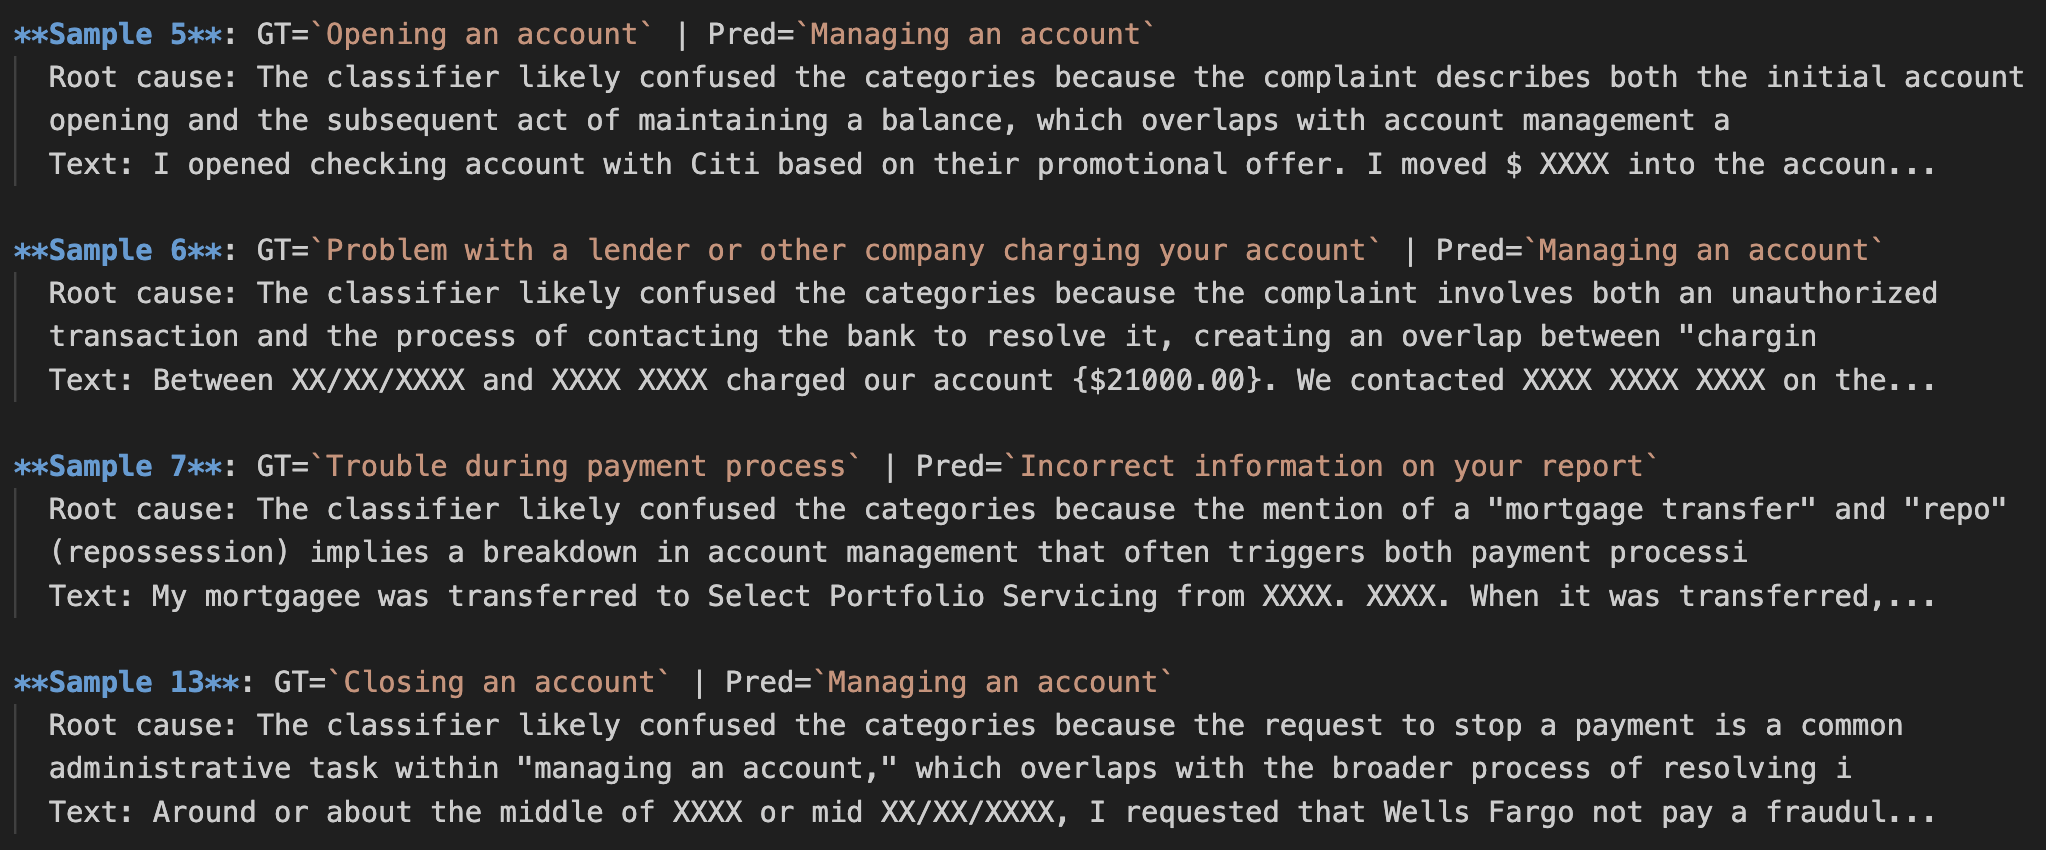
  • Failure Analysis: If a classification error occurs, scrutinize the principle and conduct a Root Cause Analysis (RCA) on why it failed (e.g., confusion with similar categories, context complexity, etc.).

  • Create a principle improvement report based on the failure analysis results. Send this feedback to the generator. Take care to ensure the generator does not overfit.

Now, as shown in the infographic below, let's actually take on the bank customer complaint classification task using an AI agent equipped with RCA capabilities.

               AI Agent with RCA Capabilities

Note that I referenced this paper (2) for this experiment. If you are interested, please definitely check it out.


2. Implementing the Bank Customer Complaint Classification AI Agent using Claude Code

Once again, I used Anthropic's Claude Code to implement and analyze the AI agent as follows. First, I set it to Plan Mode, compiled what I wanted to accomplish into a PRD (Product Requirements Document), handed it over to Claude Code, and formulated an implementation plan. This PRD incorporates the Root Cause Analysis (RCA) explained above.

              Claude Code's Plan Mode

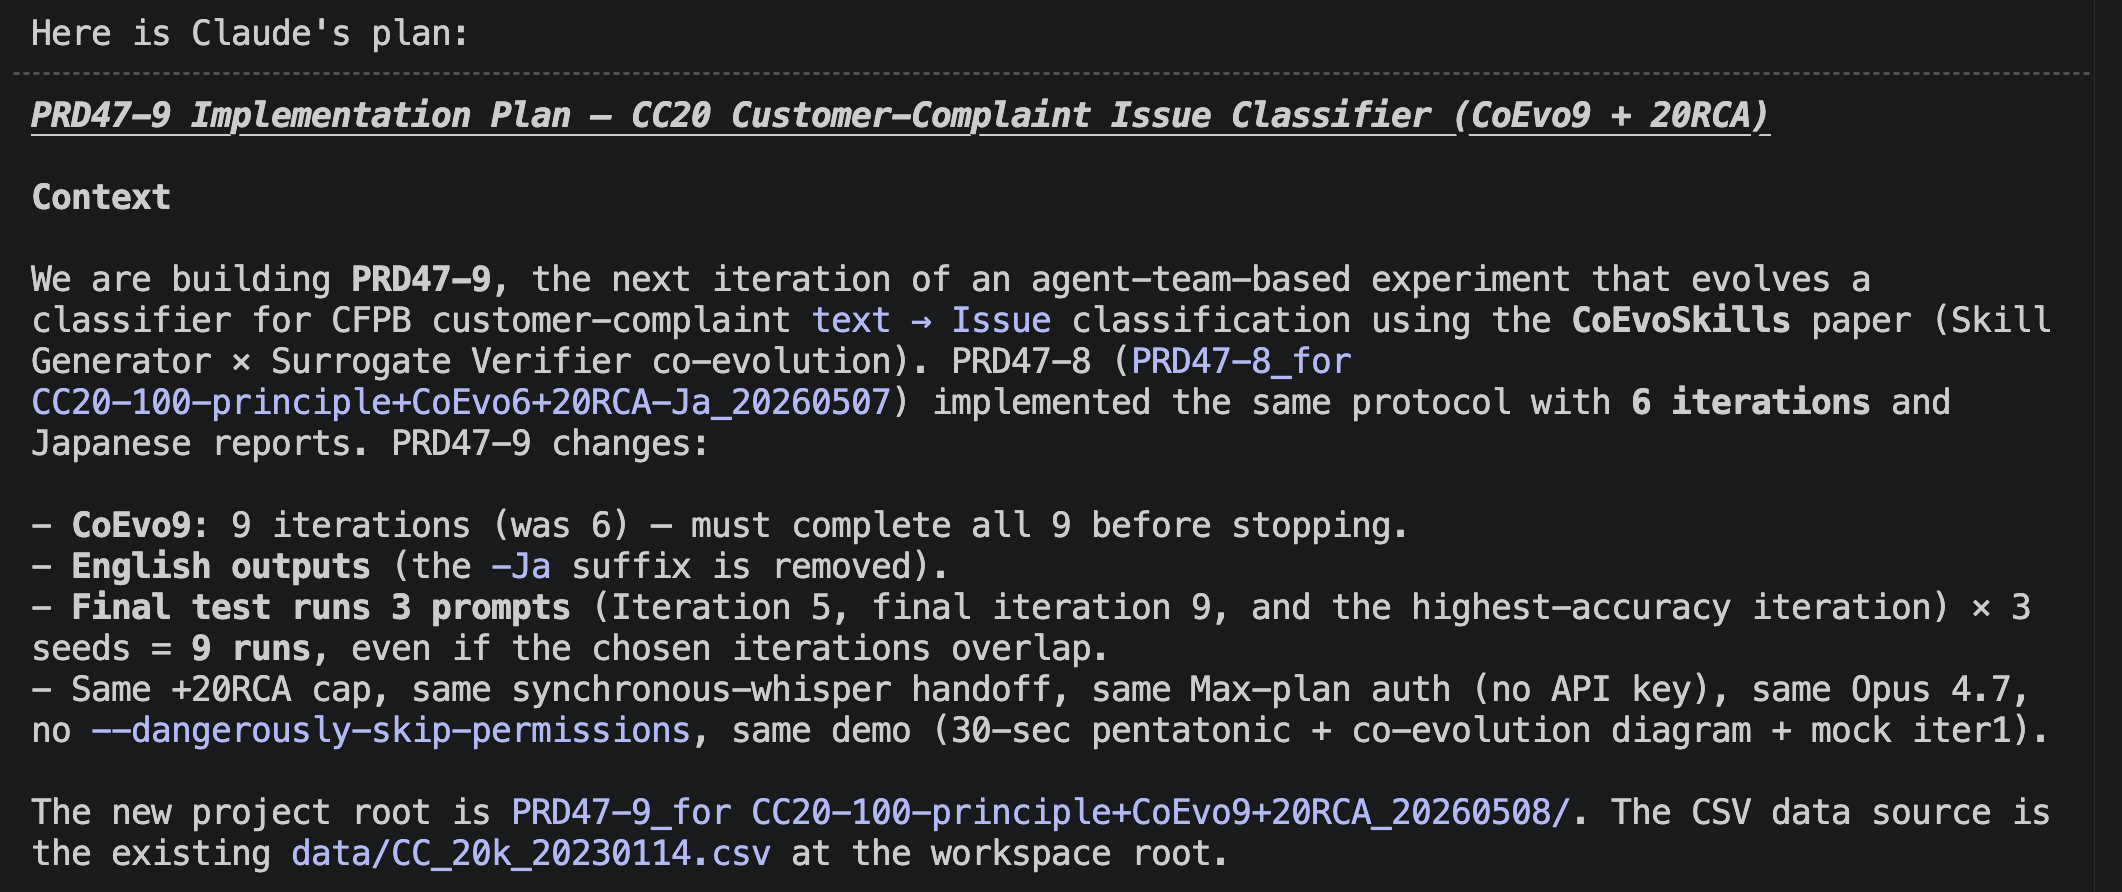
An implementation plan like the one below is formulated in about 5 minutes. The actual document is much longer, but I will only show the first part here. The important thing is to thoroughly review this implementation plan. It is long and can be tedious, but this stage allows you to confirm whether it aligns with the task's objectives before actually diving into coding. Anthropic's generative AI, Opus 4.7, is extremely high-performing; once it enters the implementation phase, it runs non-stop until the end. Since it is difficult for humans to intervene midway, the accuracy of the implementation plan holds the key to solving the task.

               Implementation Plan via Plan Mode

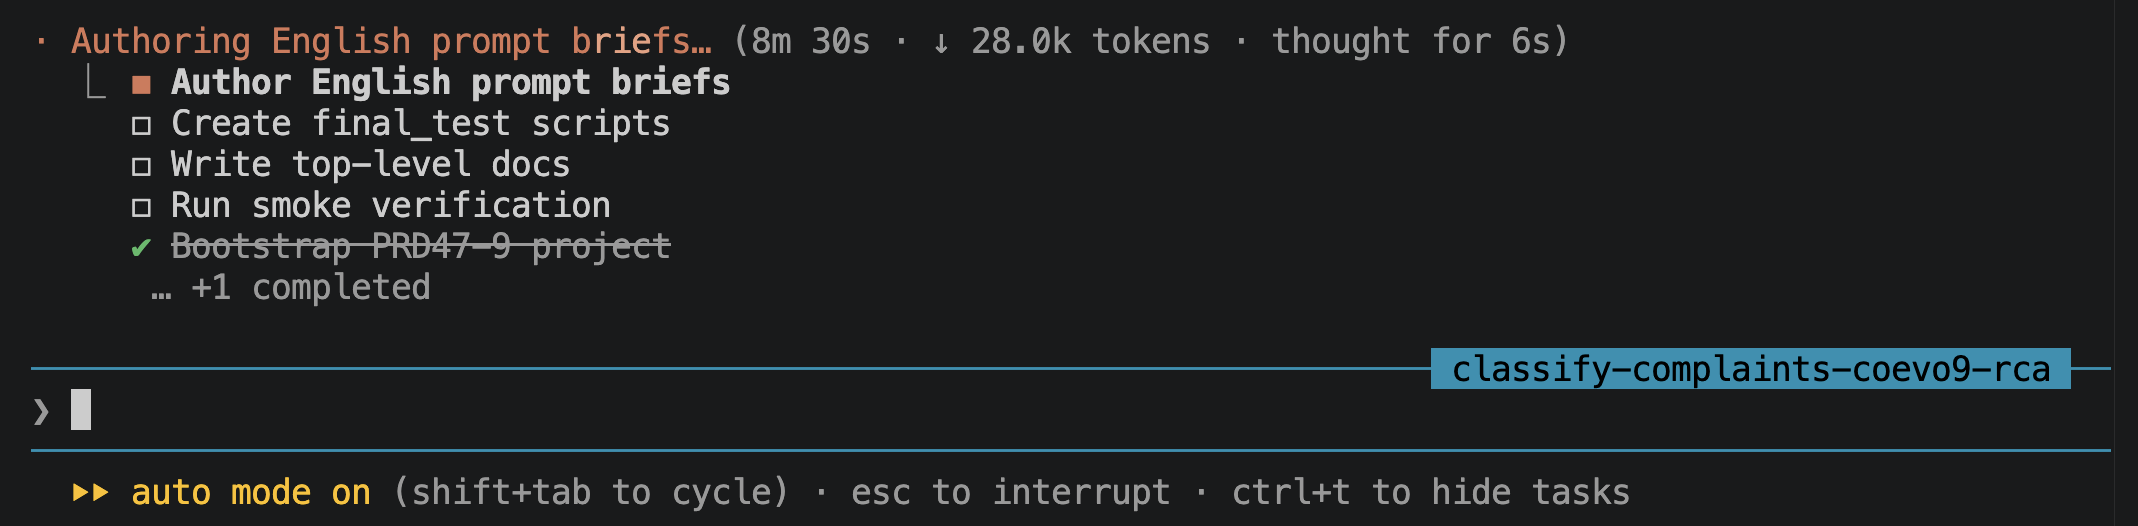
Since this implementation plan was well-crafted, I will proceed directly to implementation. I switch to Auto Mode as shown below and start coding. You can see the AI agent completing the implementation process step by step.

              Implementation via Auto Mode

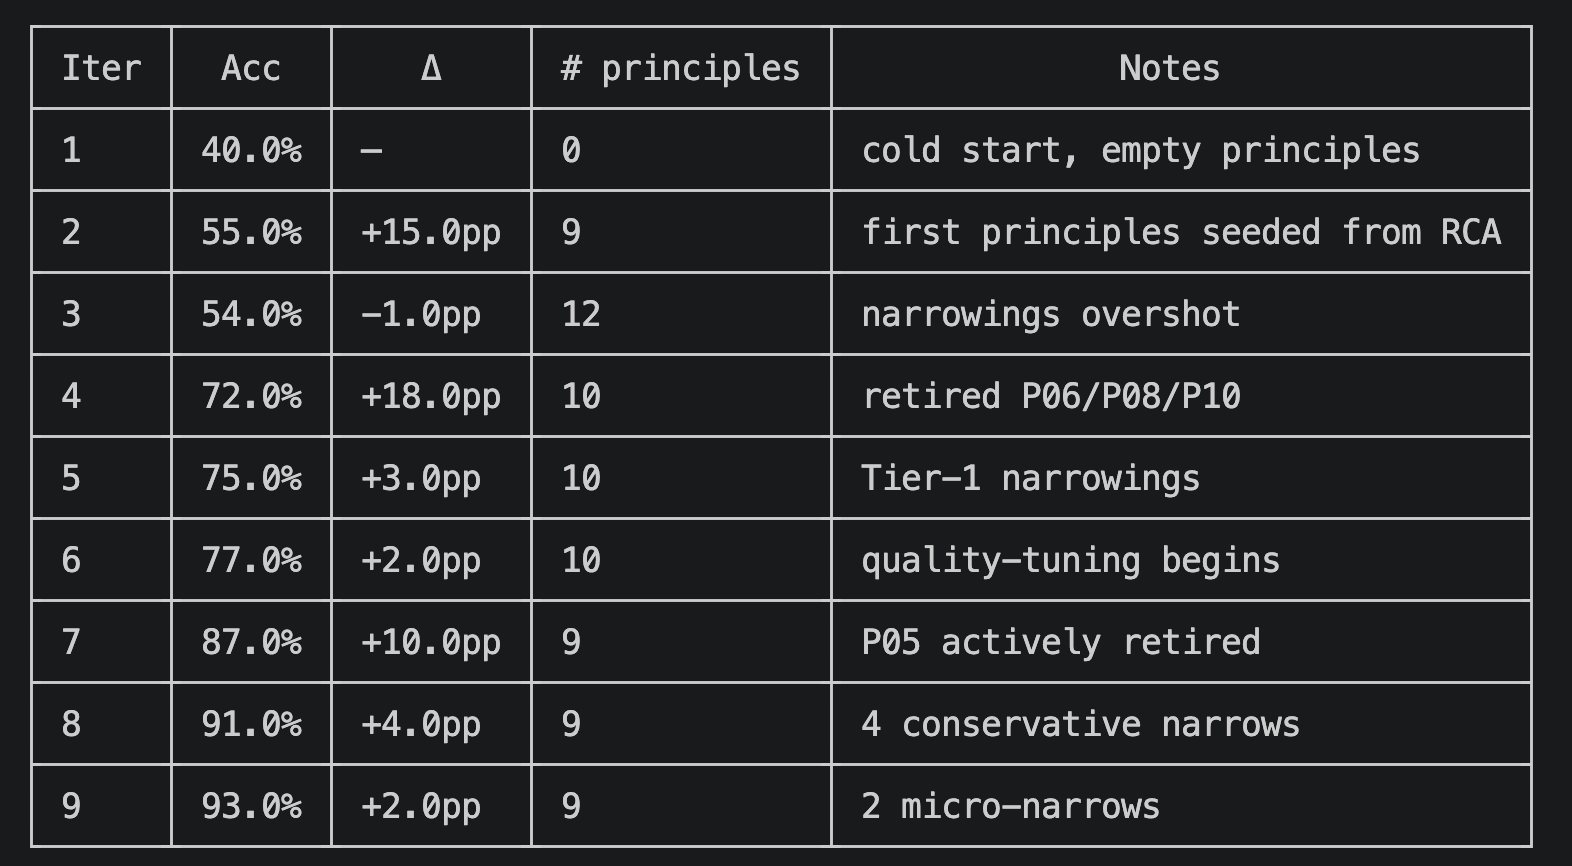
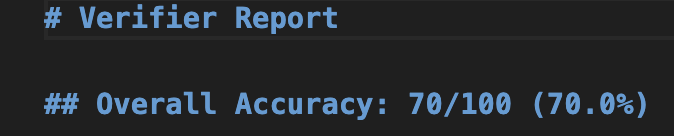
This time, we iterated on the analysis and improvement 9 times, which ultimately took over 10 hours, but we obtained the results below. This is the result of classifying 100 randomly sampled customer complaints into 20 classes. You can see that the accuracy gradually improves thanks to the RCA feedback.

               Accuracy at Each Iteration

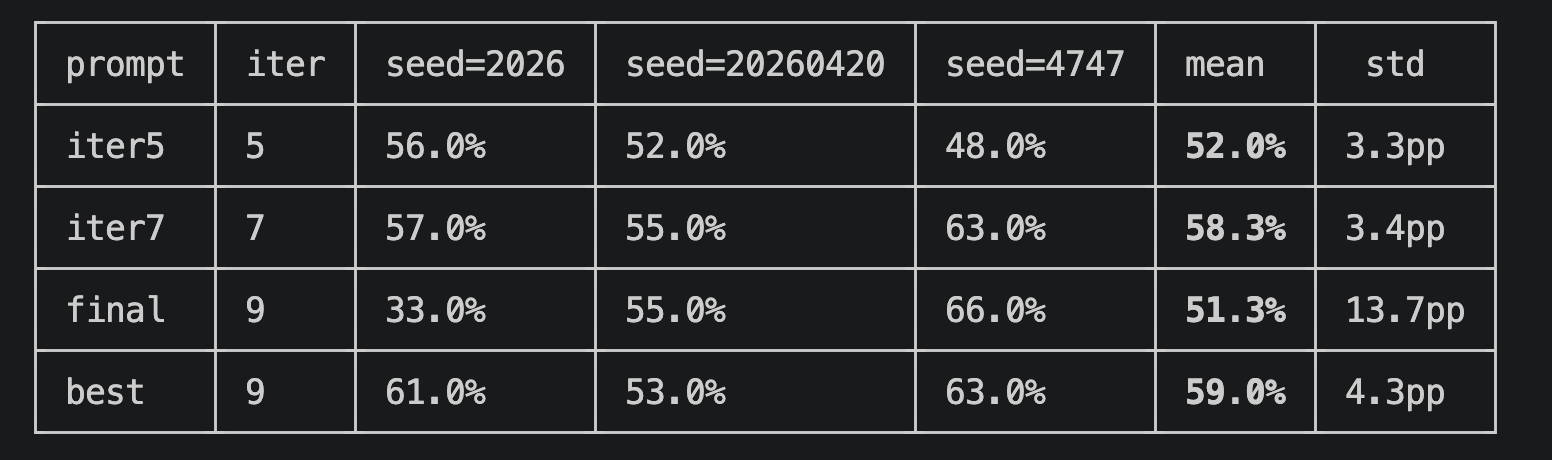
However, it seems to have overfitted due to repeating the process for far too long. I validated it with newly sampled data, but saw no improvement from iteration 7 onwards.

                 Accuracy on New Data


3. Results and Challenges This Time

In this bank customer complaint classification task, the baseline accuracy using a generative AI "out of the box" without doing anything special was under 40%. By adopting a multi-agent system with a generator and an evaluator, and incorporating RCA feedback, we achieved just under 60% accuracy even on new data, so I believe the RCA was effective. However, once the accuracy on the original data exceeded 80%, overfitting occurred, so figuring out how to improve this is a future challenge.


What did you think? This time, I explicitly stated the RCA in the PRD, implemented it as a multi-agent system, and tackled the task of classifying bank customer complaints based on their causes. While the accuracy improved from 40% to about 60%, overfitting remained an issue. To aim for an accuracy of 70% or higher on new data, another breakthrough might be necessary.

At ToshiStats, we plan to further develop RCA. Please look forward to it. Stay tuned!


You can enjoy our video news ToshiStats AI Weekly Review from this link, too!

1) Consumer Complaint Database
2) CoEvoSkills: Self-Evolving Agent Skills via Co-Evolutionary Verification, Hanrong Zhang1∗ Shicheng Fan1∗ Henry Peng Zou1 Yankai Chen2,3
Zhenting Wang2
Jiayu Zhou4 Chengze Li1 Wei-Chieh Huang1 Yifei Yao5
Kening Zheng1 Xue (Steve) Liu2,3 Xiaoxiao Li6 Philip S. Yu1
1University of Illinois Chicago 2MBZUAI 3McGill University
4Columbia University 5Zhejiang University 6University of British Columbia, April 12 2026

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
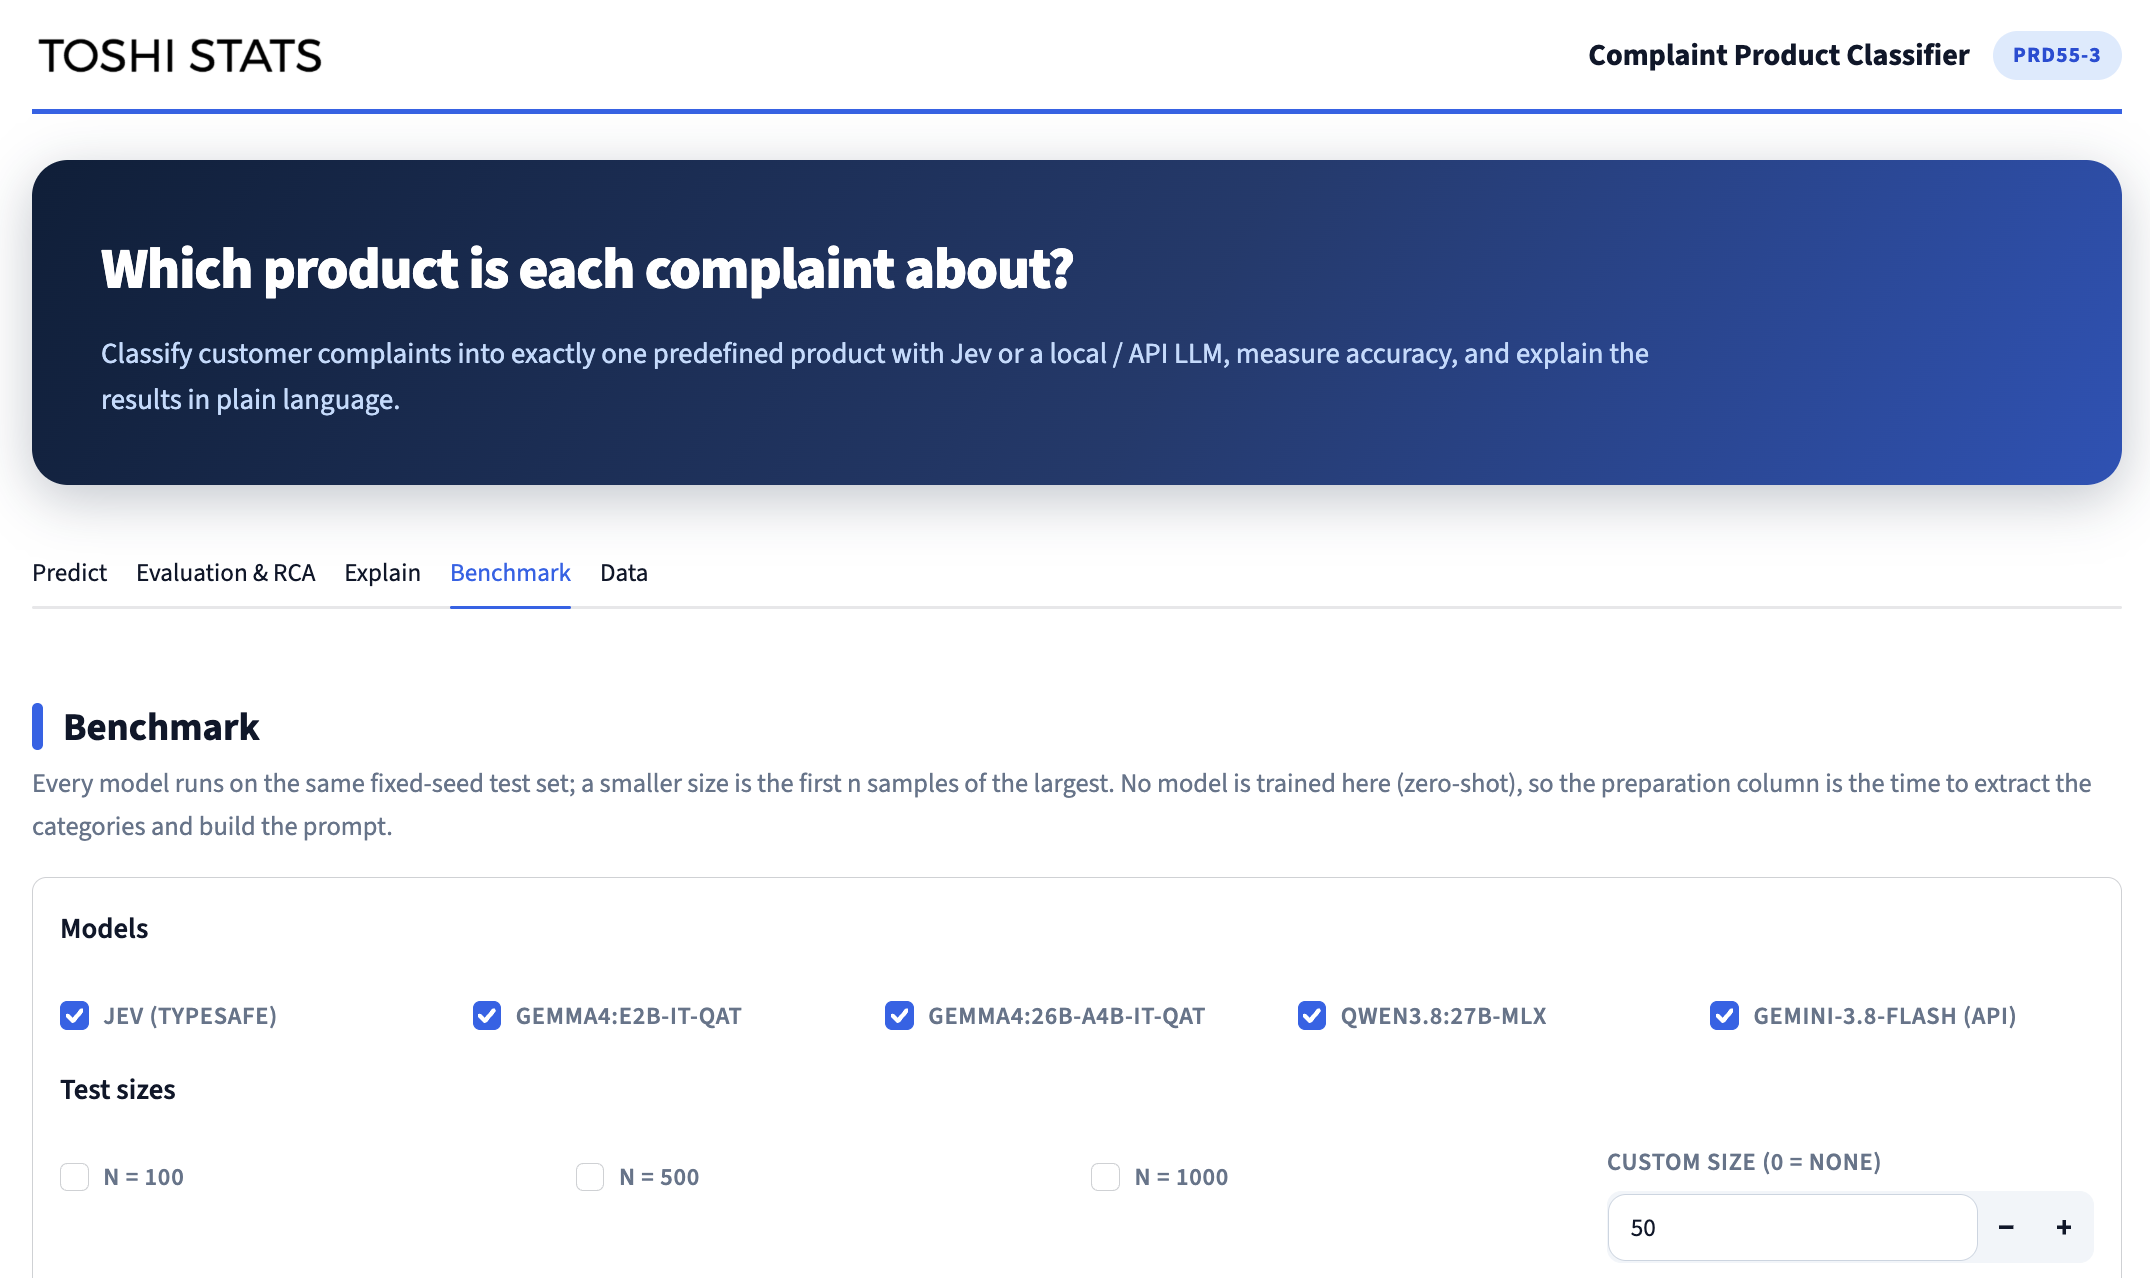
Unlocking Recursive Self-Improvement via Meta-Harness

Recently, discussions on how to significantly improve AI agent performance by optimizing "what information is provided to the agent and at what timing" have been gaining momentum. In this post, based on a recent research paper, we will explore the possibility of "Recursive Self-Improvement of AI Agents," where agents improve their own performance. Let’s dive in.


1. Meta-Harness: A New Methodology for Harness Construction

A paper (1) from Stanford University has introduced a novel approach that significantly boosts accuracy. I believe the two major features are as follows:

  • Full access to past information

  • Adoption of Claude Code

The paper defines a "harness" as follows:

The performance of large language model (LLM) systems depends not only on model weights, but also on their harness: the code that determines what information to store, retrieve, and present to the model.

Simply put, a harness is the mechanism surrounding the generative AI that controls data to maximize its performance. To build this harness using an AI agent, it seems that maximum data access is required.

By running a loop as shown below, "Recursive Self-Improvement"—where the agent learns from past failures to improve itself—becomes possible.

                   Meta-Harness


2. Full Access to Information: The Secret to Improved Accuracy

Previously, there were various methods for constructing harnesses, but humans had to summarize or compress large amounts of information in some form. Consequently, critical information was often lost during the process, creating a bottleneck when aiming for higher accuracy.

"Meta-Harness" addresses this by granting the proposer access to all past logs and files. By allowing the agent to see all information without concealment, this structure eliminates the bottleneck. As a result, it achieved excellent performance on the Pareto frontier, as shown below.

‍  ‍                Pareto Frontier

This graph illustrates the relationship between additional information (context) and accuracy. The closer a point is to the top-left, the higher the accuracy achieved with less information, which signifies superior performance.


3. The Emergence of Claude Code

The proposer plays a central role in "Meta-Harness." Let’s look at the details through pseudo-code, where P represents the proposer. Looking at the section outlined in red, we can see that a new harness is being created by the proposer.

‍  ‍                 Pseudo-code

In this context, the proposer specifically refers to Claude Code. In other words, the new harness is created based on the latent capabilities of Claude Code. While Claude Code is proving active in various fields, it appears here again in a leading role. It is truly impressive. This demonstrates that future AI research will be driven by AI agents like Claude Code at its core. We are truly at the cutting edge of the era.


Conclusion

As we have seen, providing Claude Code with maximum information access enables the construction of high-performance harnesses. Of course, detailed tuning is necessary, so I highly recommend reading the full paper.

At ToshiStats, we will continue to cover harness design, which is the key to improving AI agent accuracy. Stay tuned!


You can enjoy our video news ToshiStats AI Weekly Review from this link, too!

1) Meta-Harness: End-to-End Optimization of Model Harnesses,  Yoonho Lee, Roshen Nair, Qizheng Zhang, Kangwook Lee, Omar Khattab, Chelsea Finn,  Mar 30, 2026


Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
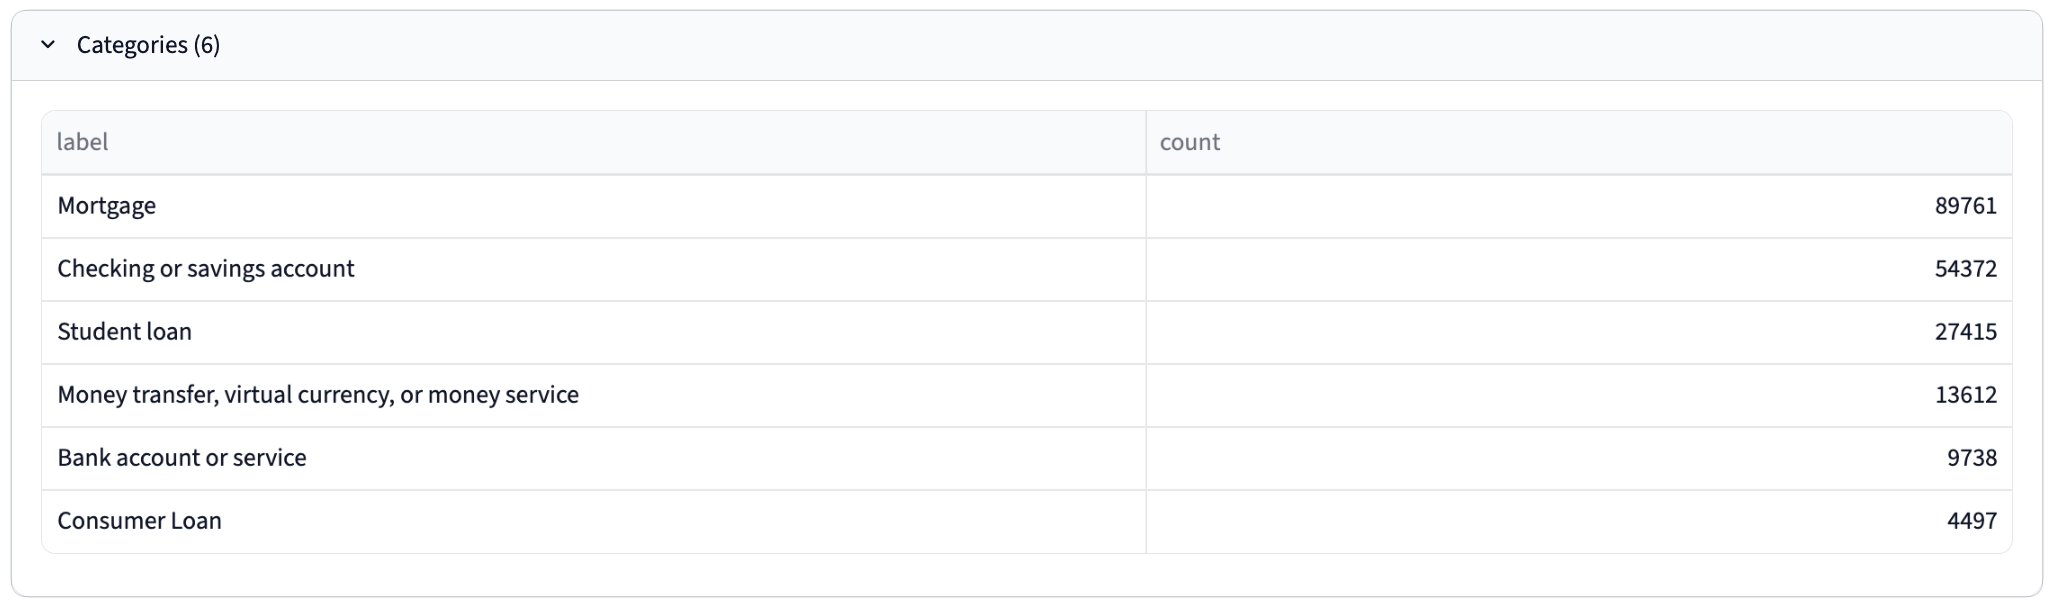
 

The Secret Sauce for Mastering Agentic Coding !

Since the beginning of this year, we've been hearing a lot about "agentic coding"—where AI agents handle the coding—everywhere. While we no longer write programs ourselves and instead focus entirely on giving instructions to AI agents via prompts, many people likely find themselves wondering, "What exactly should I learn to write good prompts?" So, today, I'd like to explore this topic using an experiment conducted at ETH Zurich as our guide.


1. Overview of the Experiment

The reference for this discussion is the paper titled "Computer Science Achievement and Writing Skills Predict Vibe Coding Proficiency (1)." They gathered 100 students who first took tests to measure their writing skills, computer science achievement, and general cognitive abilities. I've summarized these three foundational skills below.

‍  ‍        Three Foundational Skills

Afterward, to measure their "agentic coding" proficiency, the participants reviewed a sample application, drafted prompts for an LLM-based agent, tested the generated application, and then further refined it. The final applications were evaluated by human graders.

         Measuring "Agentic Coding" Proficiency

This process reveals the relationship between the three foundational skills and agentic coding proficiency.


2. As Expected, Computer Science Skills Mattered

As the results below show, computer science skills were most strongly correlated with agentic coding proficiency, showing a correlation coefficient of 0.39. Writing skills also showed a significant correlation, with a coefficient of 0.29. Here is a summary of the results.

‍  ‍        Skills Correlated with Agentic Coding Proficiency

Now, some of you might find this a bit puzzling. Computer science skills are primarily centered around programming, whereas in agentic coding, humans don't actually write code directly. So, why did computer science skills show such a high correlation? The research paper explains it as follows:

"It may have contributed through problem decomposition or mental models of control flow and state."

It's certainly true that people hone these kinds of abilities through the practice of programming. If that's the case, it makes perfect sense that individuals with strong computer science skills would perform well, even in natural language-driven agentic coding.


3. How Those with No Programming Experience Can Become Excellent Agentic Coders

Based on our discussion so far, I'd like to explore a new approach on "how people with no programming experience can become excellent agentic coders." As agentic coding becomes more widespread, it might be inevitable that the incentive to learn traditional programming will fade. However, the following skills are still absolutely essential for mastering agentic coding:

  • The ability to decompose tasks

  • The ability to understand system flows

  • The ability to expand your vocabulary and accurately define requirements in writing

For those without programming experience, deliberately focusing on and studying these specific points alongside your regular prompt writing practice will likely accelerate your improvement. This is something you can start doing right away today. I highly recommend it!


What do you think? While we focused on "agentic coding" today, the insights we've gained go far beyond just "coding"—they can be seen as universal skills for unlocking the true potential of AI agents. As AI agents become integrated into various fields in the future, these skills will essentially become mandatory subjects for all of us. Here at ToshiStats, we will continue to discuss the collaboration between business professionals and AI agents. Stay tuned!


You can enjoy our video news ToshiStats AI Weekly Review from this link, too!


1) Computer Science Achievement and Writing Skills Predict Vibe Coding Proficiency, Sverrir Thorgeirsson, Theo B. Weidmann, Zhendong Su. 14 Mar 2026


Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
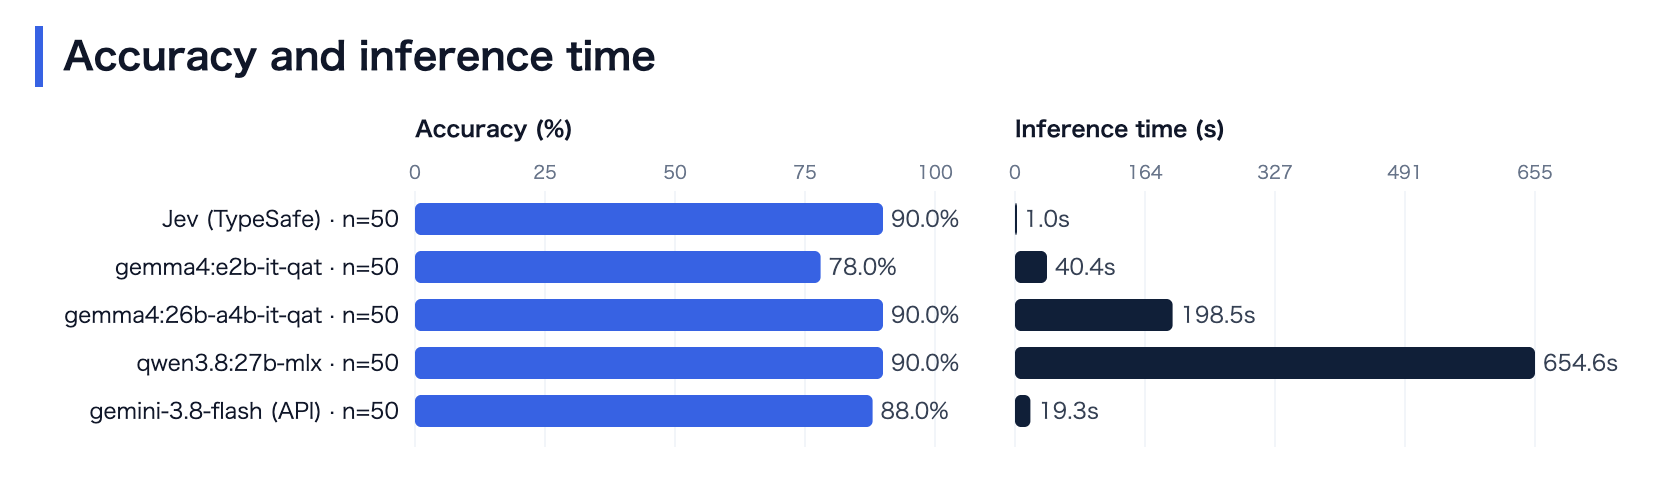
The End of Traditional Research: How "autoresearch" is Changing Everything

"It would be wonderful to have a system where you could give instructions to an AI agent before going to bed, and while you sleep, the AI agent executes the program so that a finished product is ready by the time you wake up in the morning." This is not a story about the future. It is an application called "autoresearch" (1) released on March 6, 2026, and anyone can use it for free. Let’s take a look right away.


1. What is "autoresearch"?

This is a project by the renowned AI researcher Andrej Karpathy. According to his GitHub, it is described as "AI agents running research on single-GPU nanochat training automatically," meaning he has created AI agents that automatically train nanochat (2). Nanochat is a small yet high-performance large language model (LLM) that he developed. Usually, he trains nanochat while manually tuning it, but this is a very ambitious project to automate that process using "autoresearch." According to him, even though it has just begun, "autoresearch" has worked very well. For details, please see his post on X (3).


2. Simple is Best

When you hear about automating the training of a large language model, you might imagine a very complex system, but there are only three basic files. Furthermore, the only file a human needs to write directly is program.md. In this file, you write in natural language, such as English or Japanese, "what kind of research team we want to form by launching multiple AI agents and what we want them to do." No programming is required. The AI agent that receives these instructions autonomously writes code in train.py to improve the accuracy of nanochat. The final file, prepare.py, is never updated during training. It serves as the foundation for the experiment, so it remains the same until the end. It is a very simple structure. I highly recommend checking Andrej Karpathy’s GitHub for the contents of each file; it will be very informative. I have summarized the overview briefly below.

This is the autoresearch repository for Mac that I executed this time. You can certainly see the three files I introduced. The file structure is extremely simple, and I believe anyone can handle it.


3. Running on a MacBook Air

Now, let's run it on my MacBook Air. This Mac was purchased exactly one year ago and is equipped with an M4 chip and 24GB of RAM. Claude Code is active as the development environment once again. It is on duty at our company almost every day.

Claude Code

When I asked Claude Code to draw a diagram, it looked like the one below. It is simple and easy to understand. On the second from the right, it says MLX Train 5m, which means repeating a 5-minute training session many times. It can be executed about 12 times in one hour. On the far right, Evaluate val_bpb means "evaluate the metric val_bpb (validation bits per byte) and check if the value is steadily decreasing." If the value decreases, it means the accuracy is improving. If not, that session is discarded, and training continues from the previous state. If you let this run while you sleep, you can conduct 100 experiments in a single night.

autoresearch Training Process

Andrej Karpathy describes this design as follows: ‘Self-contained. No external dependencies beyond PyTorch and a few small packages. No distributed training, no complex configs. One GPU, one file, one metric.‘

Since I wanted to confirm if it would work properly this time, I ran the loop only three times. As seen below, the evaluation metric did indeed decrease, showing that the training progressed smoothly. During this time, I gave no instructions at all. It’s amazing. It truly is "autoresearch"!

Trends in Evaluation Metric Values


What did you think? Andrej Karpathy stated on his X (3) account:

“All LLM frontier labs will do this. “,

“any metric you care about that is reasonably efficient to evaluate (or that has more efficient proxy metrics such as training a smaller network) can be autoresearched by an agent swarm. It's worth thinking about whether your problem falls into this bucket too.”

You, too, might be able to create your own AI lab using a Mac. It is a wonderful thing. At ToshiStats, we will continue to conduct experiments incorporating cutting-edge technology. Stay tuned!.

You can enjoy our video news ToshiStats AI Weekly Review from this link, too!

1) autoresearch, Andrej karpathy, March 6, 2026
2) nanochat, Andrej karpathy, Oct13,2025
3) https://x.com/karpathy/status/2031135152349524125

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
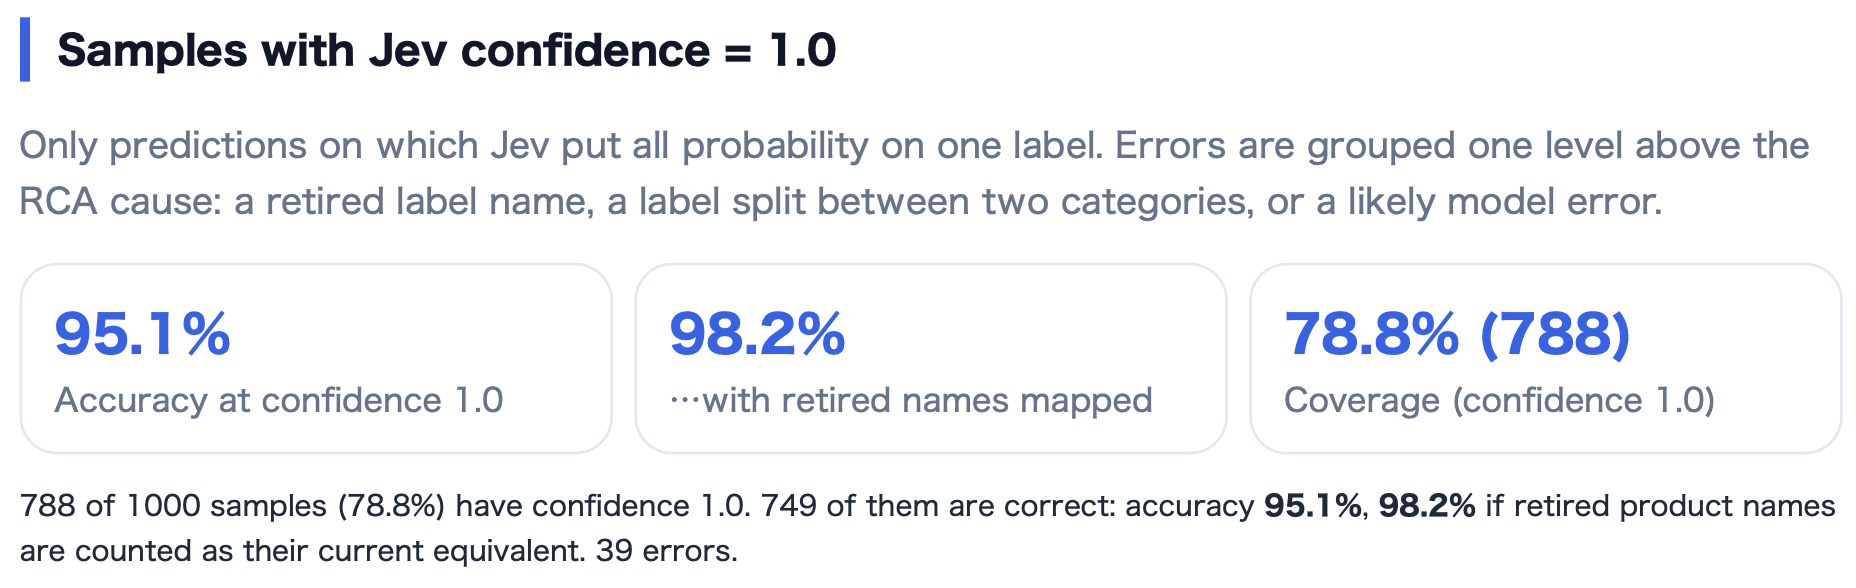
Many-Shot In-Context Learning: The Game Changer of the Long-Context AI Era

Recently, OpenAI released its newest AI model, GPT-5.4 (1). While much of the praise has focused on its overall performance, I want to highlight its context window length. The context window refers to the amount of information a generative AI can process in a single go. GPT-5.4 now supports 1M (one million) tokens. With its rival Opus 4.6 also at 1M and Google Gemini having achieved 1M two years ago, all frontier models from the "Big Three" now possess 1M-token context windows. We can officially say that AI has entered the Long-Context Era.

How will this impact the development of AI agents? Let’s explore.


1. What is Many-Shot In-Context Learning?

When you ask ChatGPT, "What is the capital of Japan?" and it replies, "Tokyo," that question or instruction is called a prompt. However, you can input much more than just a short prompt.

For example, if you provide examples first—such as "Where was the World Expo held in Japan?" followed by "Osaka"—and then ask your actual question, the accuracy is known to improve. This technique is called In-Context Learning. When the number of examples exceeds roughly 10 and you provide a massive amount of data, it is referred to as Many-Shot In-Context Learning. Here is a brief summary.

In-Context Learning


2. Challenging a 20-Class Classification Task Using Bank Complaint Data

To measure the effectiveness of Many-Shot In-Context Learning, I decided to tackle a difficult 20-class classification task using bank complaint data (2). This dataset contains an "issue" column describing why a complaint occurred. The goal is to read the "text" column and select the correct cause from 20 possible categories. For this, I used Gemini 3.1 Flash-Lite (3).

     Banking complaints dataset

Rather than using a simple prompt like "Please classify this," I asked the AI itself to "create the optimal prompt," resulting in a highly detailed set of instructions—what you might call a "Prompt Powered by AI."

prompt powered by AI

I first attempted this using Zero-shot (providing no examples), even with this enhanced prompt. Unfortunately, the accuracy was only 46%. Since it gets it wrong more than half the time, it isn't yet viable for practical business use.

Zero-Shot accuracy


3. Executing Many-Shot In-Context Learning with 1,000 Samples

Next, I implemented Many-Shot In-Context Learning by providing 1,000 examples alongside the prompt. While the underlying process remains the same as the Zero-shot approach, the volume of information is massive. The following are the first five examples.

Many-Shot samples

The results were dramatic: accuracy jumped to 70%. This clearly demonstrates the sheer power of the "Many-Shot" approach.

Many-Shot accuracy

However, with a 30% error rate, there is still room for improvement. I had an AI Agent analyze why the errors occurred and generate a report. The insights gained from this analysis are highly valuable for further refinement.

Root cause analysis


Conclusion

There are several ways to improve the accuracy of generative AI, but as 1M-token context windows become the standard, Many-Shot In-Context Learning is set to become a major focal point. At ToshiStats, we plan to continue evolving this methodology.

Stay tuned!

You can enjoy our video news ToshiStats AI Weekly Review from this link, too!


1) Introducing GPT‑5.4, Open AI, March 5, 2026
2) Consumer Complaint Database
3 )Gemini 3.1 Flash-Lite: Built for intelligence at scale, Google, Mar 03, 2026

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
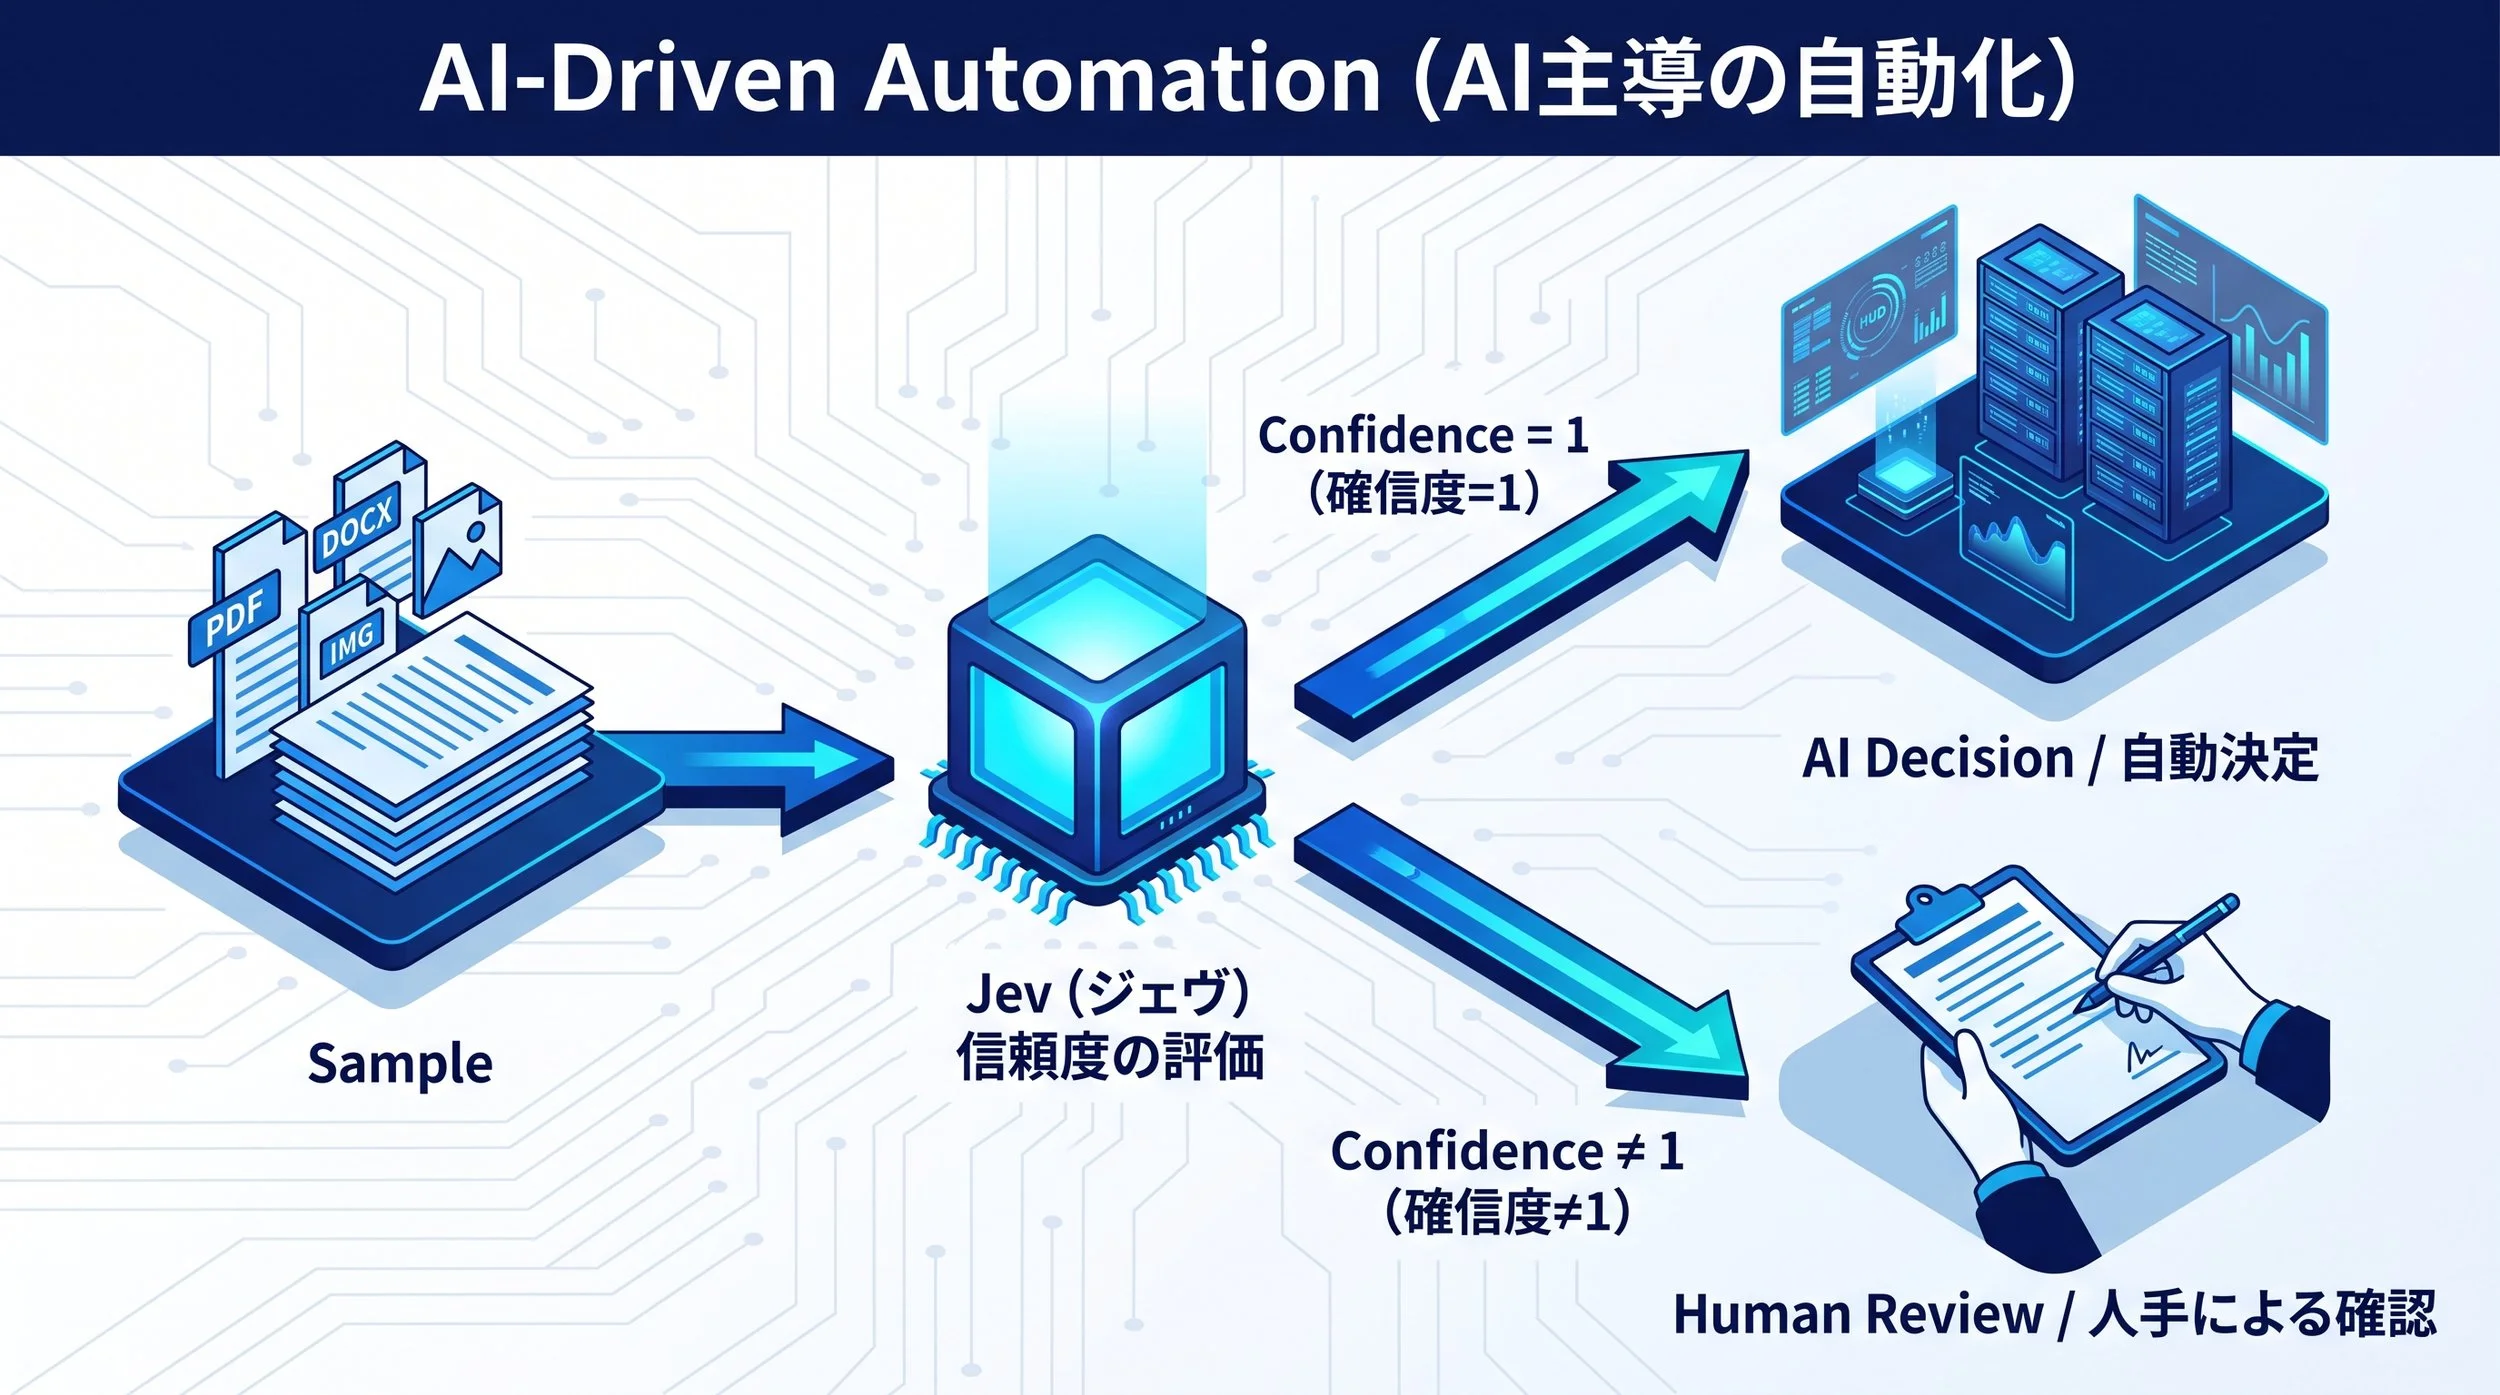
Which AI Model Should You Use Daily? Why Gemini 3.1 Flash-Lite is the Top Choice!

I’ve been using Opus 4.6 for coding lately, but I've realized that the costs can really add up when running it via API. This led me to think that for tasks where absolute peak precision isn't the only priority, a more budget-friendly model would be a better fit. Right on cue, Google announced the gemini-3.1-flash-lite-preview—a model built for speed and affordability (1). I decided to put it to the test immediately.


1. The Perfect Balance of Speed, Cost, and Performance

The Flash-Lite series is the most affordable tier in the Gemini lineup. It’s likely the engine behind many of Google’s own internal services. Speed, in particular, seems to be its standout feature.

When compared to its rivals, the processing speed is remarkably fast. Its cost-efficiency is equally impressive: at $0.25 per 1 million input tokens, it is poised to be a powerhouse for tasks involving massive amounts of data. For a startup like ours, this is incredibly encouraging.

               Comparison with Rival AI Models

Affordability hasn't come at the expense of performance, however. As shown in the Leaderboard (2), it boasts a score exceeding 1430. Given that the top-tier frontier models are currently competing around the 1500 mark, a score of 1430 for a lightweight model is truly outstanding.

                 Leaderboard Standings


2. Performance Evaluation: Banking Complaint Classification

To see what it can really do, I tested the model on a banking complaint classification task. Using this dataset (3), I provided the model with customer complaints from the "text" column and asked it to select the most relevant category from six financial products listed in the "Product" column. I ran this test on 100 samples to see how accurately it could categorize each complaint.

                 Banking Complaint Data

Here is the detailed prompt I used.

The Prompt

The results were fantastic, achieving a 92% accuracy rate. The entire process finished in about 60 seconds, demonstrating its high-speed processing capabilities. I’ve attempted this specific task several times in the past, but this is the first time a model has exceeded 90% accuracy without any fine-tuning. Truly impressive!

Task Accuracy Results


3. A High-Speed Model You Can Use Without Budget Anxiety

For the past few months, I’ve relied on Opus 4.6 for its sheer coding power. While its performance is top-notch, the costs are substantial. When you want to run various experiments where success isn't guaranteed, the budget can become a significant hurdle.

That’s where gemini-3.1-flash-lite-preview shines. Its balance of performance and cost makes it easy to iterate and experiment freely. It’s the perfect "partner" for development, and I plan to integrate it into my workflow even more moving forward.


What do you think? It looks like Google will continue to roll out new AI models one after another. We might even see some open-source models soon, so it's definitely something to keep an eye on. Here at ToshiStats, we’ll keep testing and integrating various AI models into our workflow. Stay tuned!


You can enjoy our video news ToshiStats-AI from this link, too!

1) Gemini 3.1 Flash-Lite: Built for intelligence at scale,  Google,  Mar 03, 2026
2) Arena
3) Consumer Complaint Database

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
The Rise of the AI Strategist: Can AI Agents Master Corporate Strategy?

Claude Code, the coding assistant that's exploding in popularity worldwide—did you know you can use Agent teams (1) to run AI agents as a team? The idea is to run multiple AI agents simultaneously according to their purpose, achieving performance that a single agent couldn't deliver. This time, we'd like to test whether we can use Agent Teams to develop corporate strategy. Let's get started!


1. Implementing Five Forces Analysis with Agent Teams

There's a well-known framework in competitive strategy called Five Forces Analysis (2). This time, we'd like to apply it to the Japanese digital payment market and explore the possibility of market entry. We'll analyze from the following five perspectives, setting up an AI agent for each one.
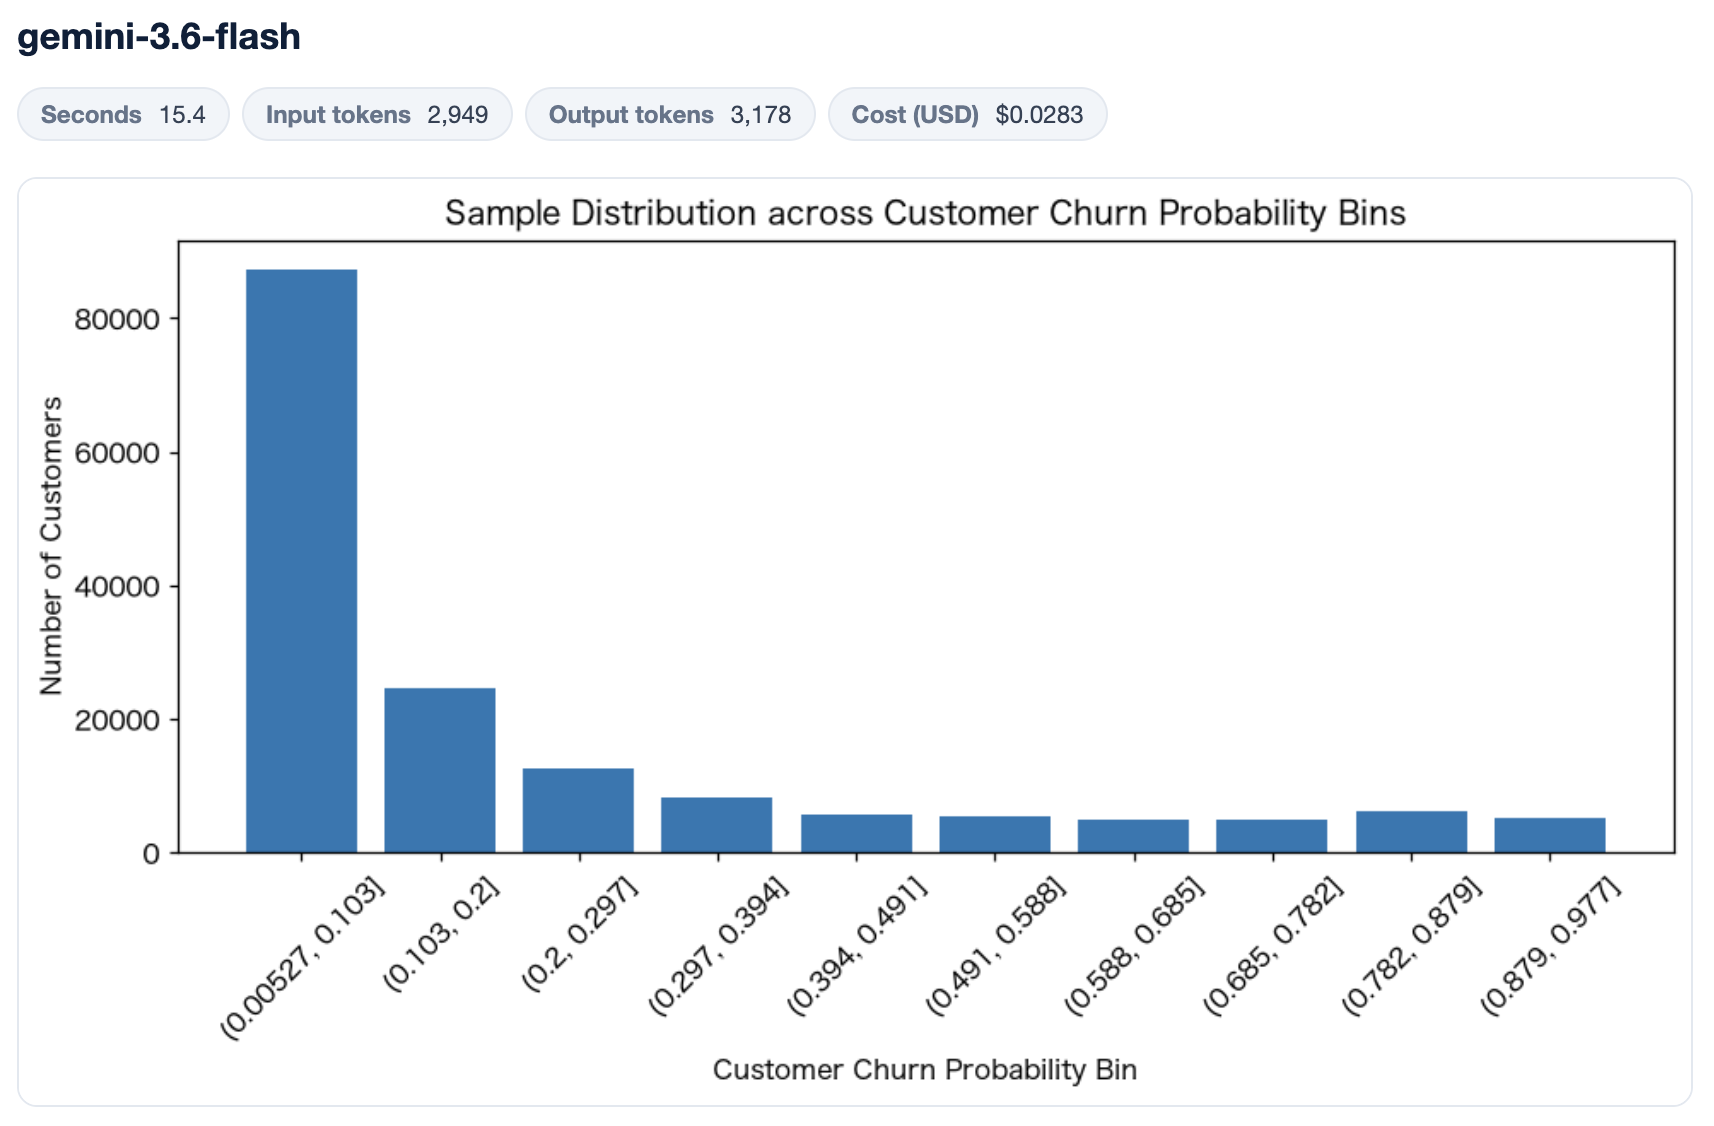
                  Five Forces Analysis

We entered the following prompt into Claude Code, which you're all familiar with by now. There's nothing particularly difficult about it. Of course, no programming is required. However, if this is your first time using Agent Teams, you'll need to configure the settings, so don't forget (1).
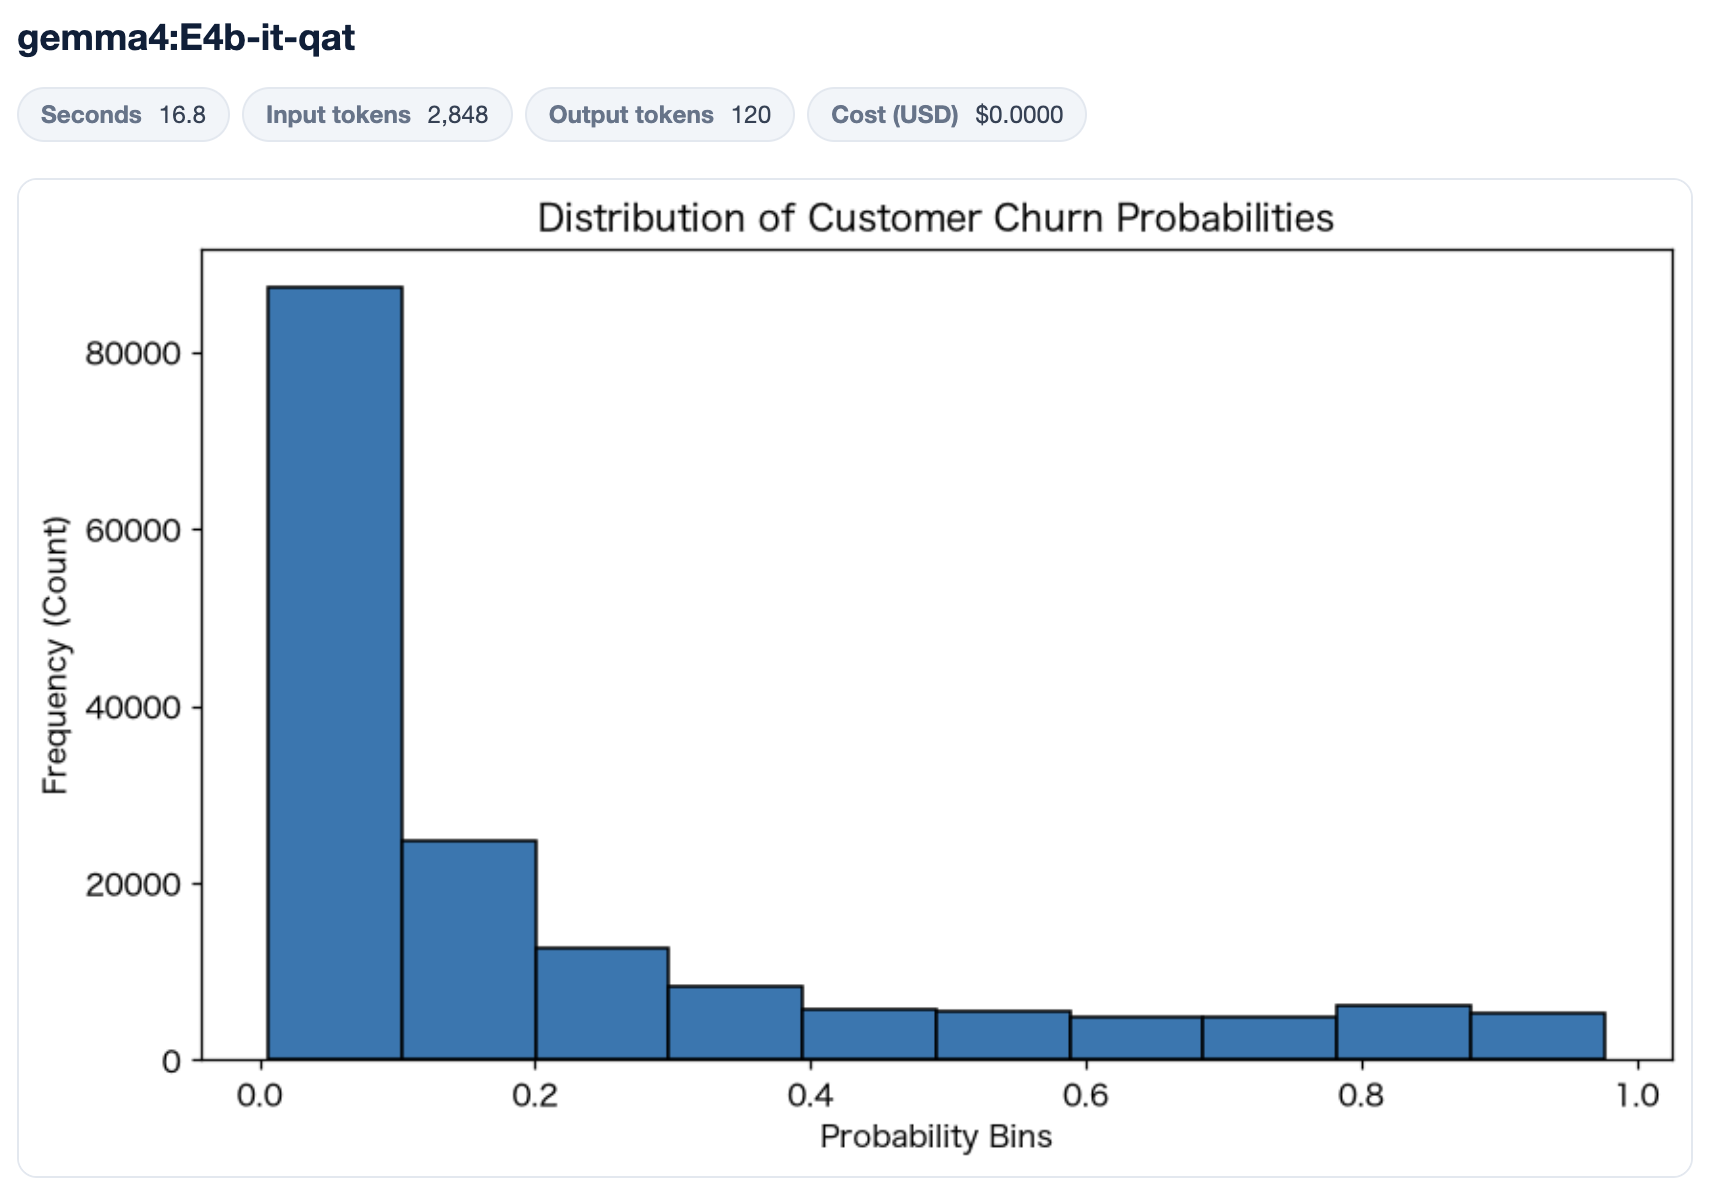
                    Claude Code

The multi-agent system we'll actually build looks like the following. A total of seven AI agents will be running, but the key point is the loop involving Agent 6 and Agent 7. After Agent 6 creates a report summarizing the research findings, Agent 7, positioned independently, verifies that report. The report isn't complete until Agent 7 approves it and gives the go-ahead. Quite rigorous, isn't it?

                Strategic Analysis Multi-Agent System


2. The Report Creation Process

Now let's follow the report creation process on the actual screen. As you can see below, seven AI agents have indeed been configured. You can also see that the crucial verification loop has been created.

                    Seven AI Agents

First, Phase 1. The five research AI agents begin by pulling information from the web. They gather information about the Japanese digital payment market from the five perspectives of Five Forces Analysis. Each AI agent operates independently and processes in parallel, making it very efficient.

Work has progressed, and it appears four of the research tasks are complete. The competitive landscape from each perspective is documented as well. Just a little more to go.
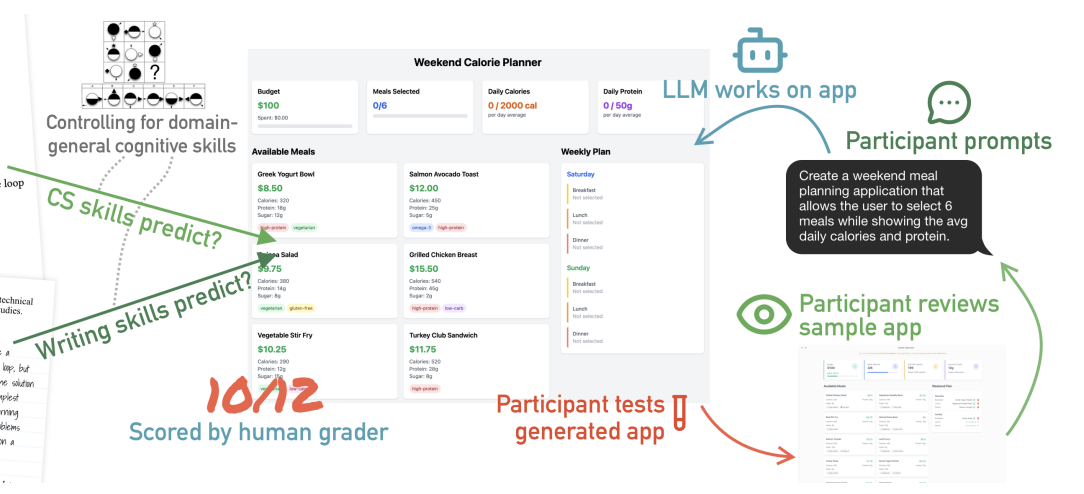
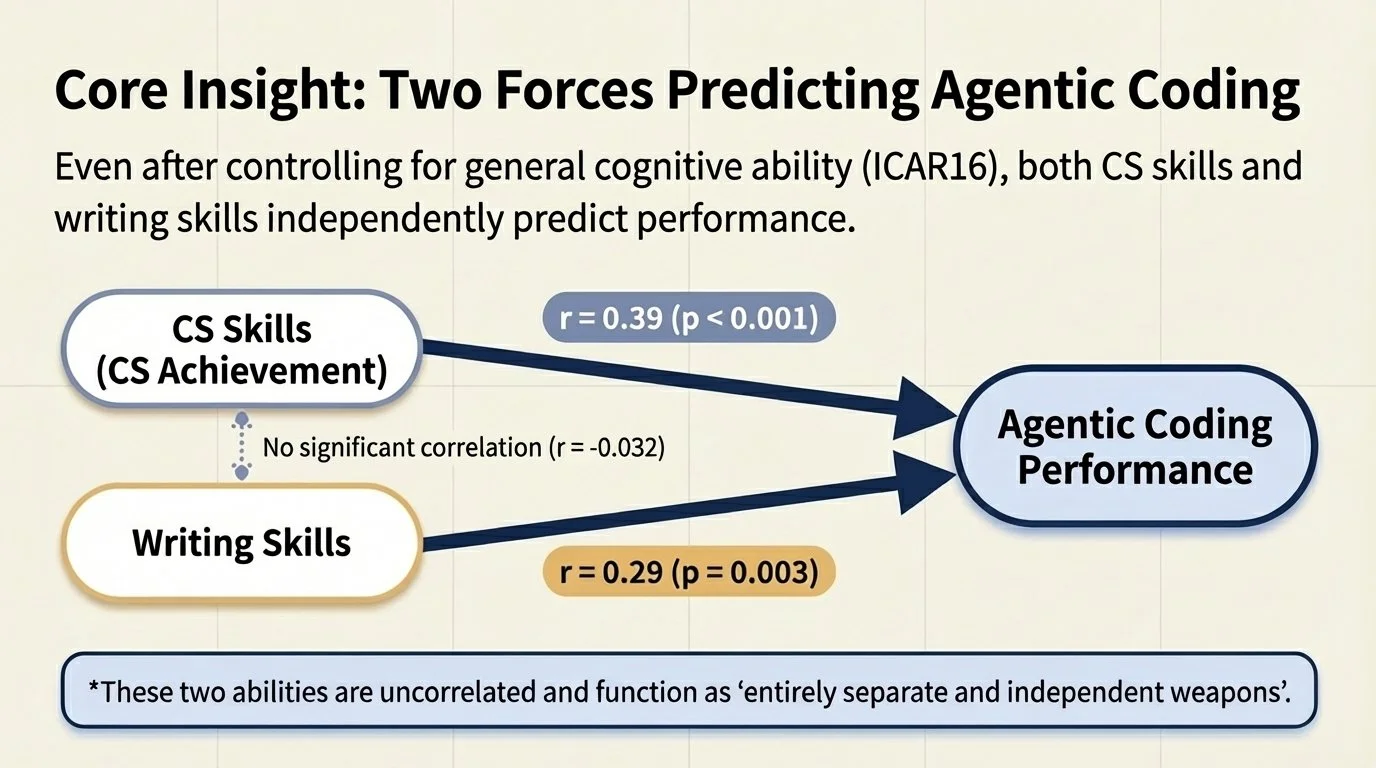
The research by all five AI agents is complete, and we move into Phase 2: creating the integrated report. I'm excited to see what kind of report it will be.

Then we enter the most important phase—Phase 3: the verification loop. Here, the goals are: 1) fact-checking through search, 2) identifying logical inconsistencies, and 3) identifying hallucinations, all aimed at improving the quality of the integrated report.

It appears eight errors were identified and corrected.

The report is finally complete. As shown below, there are six types of reports. We compiled all six into a single PDF file, and it spans 60 pages of content. Impressive, isn't it?


3. Structure of the Generated Analysis Report

The structure of the consolidated report is as follows. It's written in accordance with the Five Forces Analysis framework.

Structure of the analysis Report

We can't present everything here, but the summary in Chapter 1 looks like the following—I think it's very clearly organized. Please note that this summary is for educational purposes only and should not be directly applied to business decisions or the like.

              notice : This is for educational purpose only


So, what did you think? We carried out corporate strategy development using Five Forces Analysis, and the AI agents produced an excellent report. While further verification is needed, it could potentially be used as a starting point for discussion. I should note that Agent Teams is currently in an experimental phase, so changes to specifications are possible going forward (1). At Toshi Stats, we'll continue applying multi-agent systems across various fields. Stay tuned!


You can enjoy our video news ToshiStats-AI from this link, too!

1) Orchestrate teams of Claude Code sessions, Anthropic
2) Porter's five forces analysis, Wikipedia

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.