Nearly a month has passed since the new type of AI, "Jev," was announced on September 15, 2026 (1). Since then, various companies have introduced similar AIs, and momentum around this Jev-like-AI category has been growing rapidly. Therefore, in this article, we would like to unpack the wonderful research paper below (2) and explore ways to achieve automation by mastering this AI called Jev.
1. Humans, LLMs, and Jev
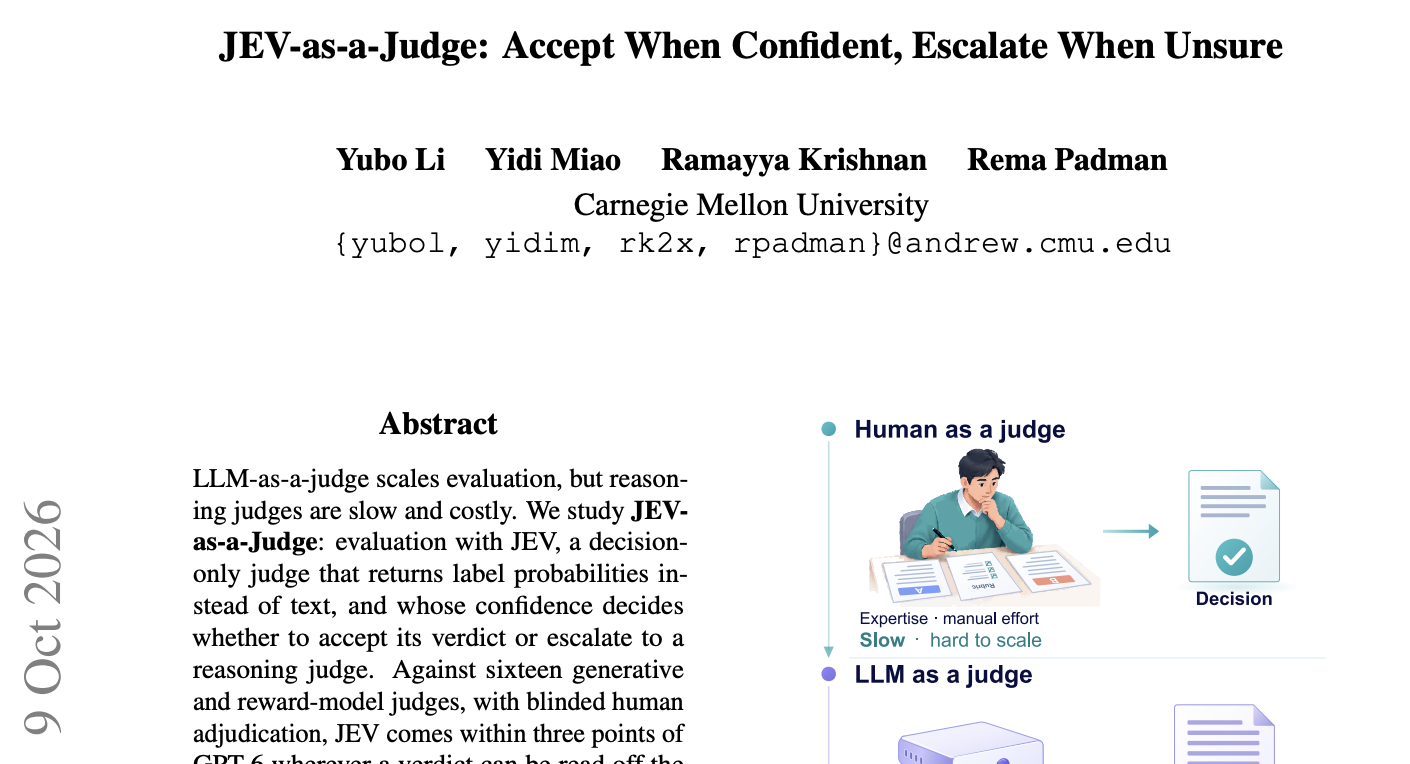
First, let us compare judgments made by humans, LLMs (Large Language Models), and Jev to examine their respective characteristics. The research report also summarizes them as shown in the chart below.
Here, let’s consider a task where you read an internal approval request and decide whether you can sign off on it. With the expertise you have cultivated fully on display, the accuracy of your discernment would undoubtedly be outstanding. Unfortunately, however, your resource is limited to single-person manpower, making it impossible to scale up all at once. For this reason, it has recently become common practice to delegate your tasks to AI agents powered by LLMs. The capabilities of cutting-edge LLMs are remarkable, with cases emerging where their accuracy surpasses that of humans. Yet, LLMs also have shortcomings that make them ill-suited for automation.
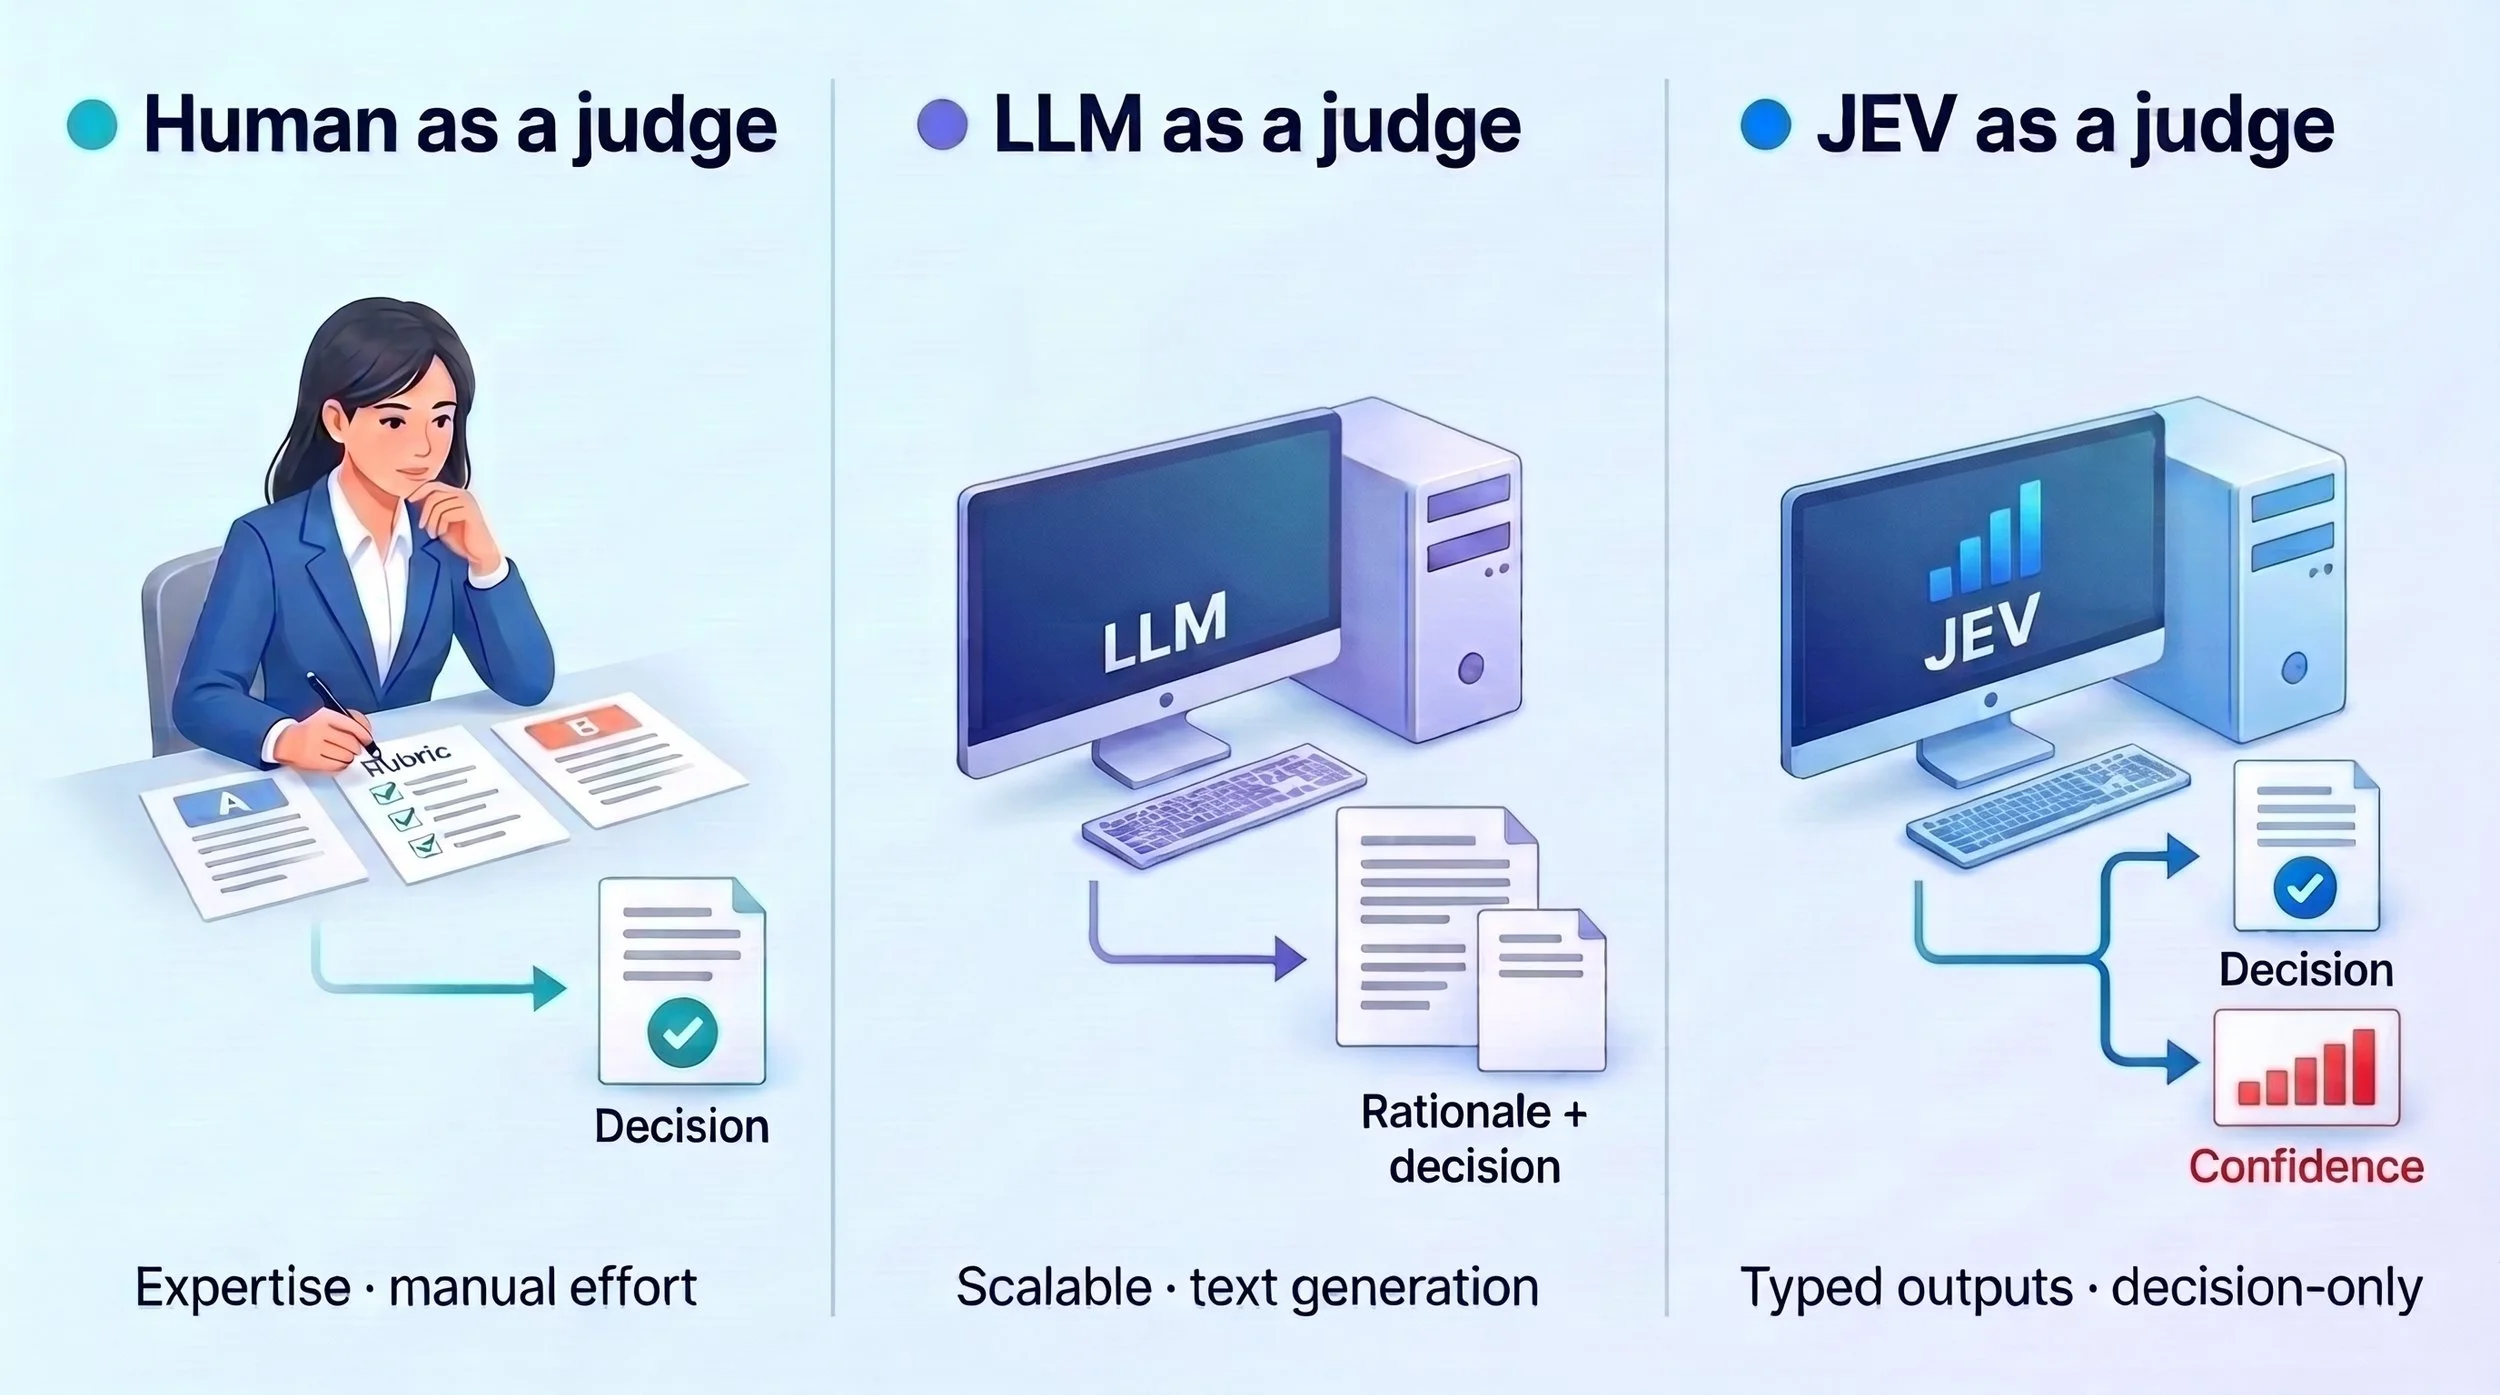
Distinction between Humans and AI
It is true that more and more LLMs can achieve high accuracy; however, they inevitably suffer from two persistent drawbacks:
Slow computation speed
High computation cost
Because they perform inference using a massive number of tokens—a process known as Chain of Thought—to achieve high accuracy, they are structurally disadvantaged in terms of both computation speed and cost.
That is where Jev comes in. Jev overcomes these shortcomings of LLMs. We will explain this in detail in the next section.
2. The Capabilities of Jev
Here, let us directly compare Jev with GPT6 Astra, one of the pinnacle LLMs. The parts enclosed in red frames are Jev and GPT6 Astra.
First, looking at latency (computation time), handling the exact same task took 0.15 seconds for Jev, whereas GPT6 Astra took 1.89 seconds—more than 10 times longer. Next, regarding cost, when performing 1,000 classifications, Jev cost 0.04 USD, whereas GPT6 Astra cost 12.18 USD—over 200 times more expensive. While this is just one example, it is more than sufficient to understand Jev's strengths.
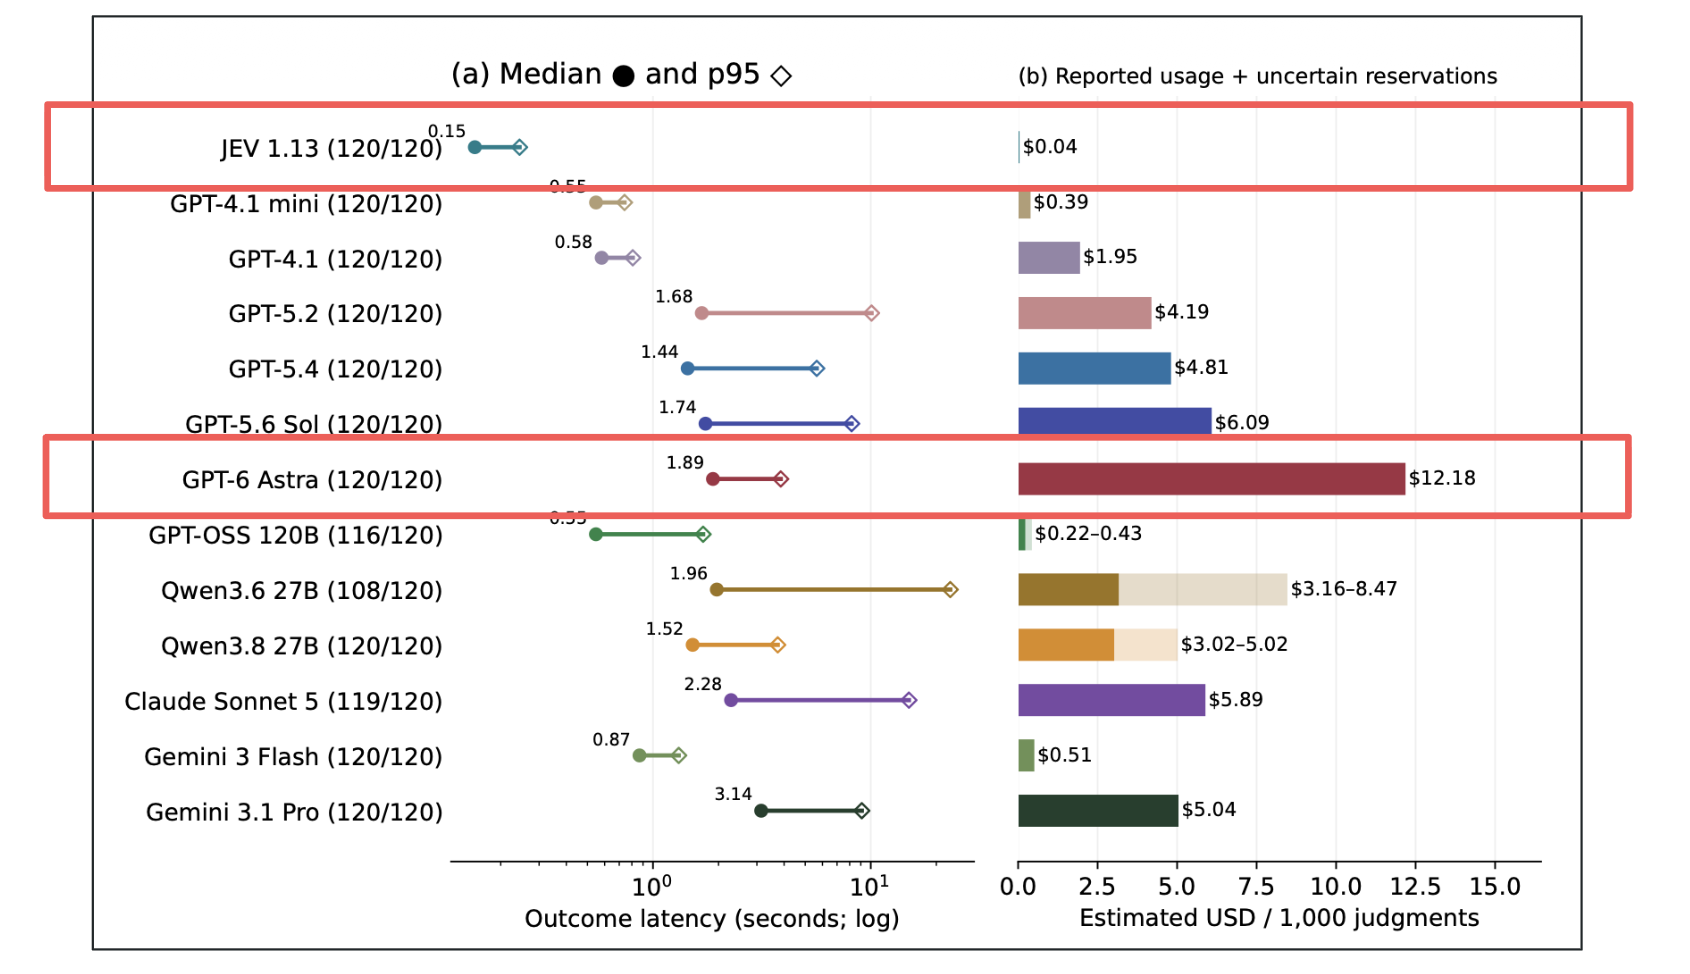
Latency and Cost Comparison
Although Jev may seem flawless, it naturally has weaknesses. As shown below, Jev is clearly inferior to GPT6 Astra on JudgeBench.
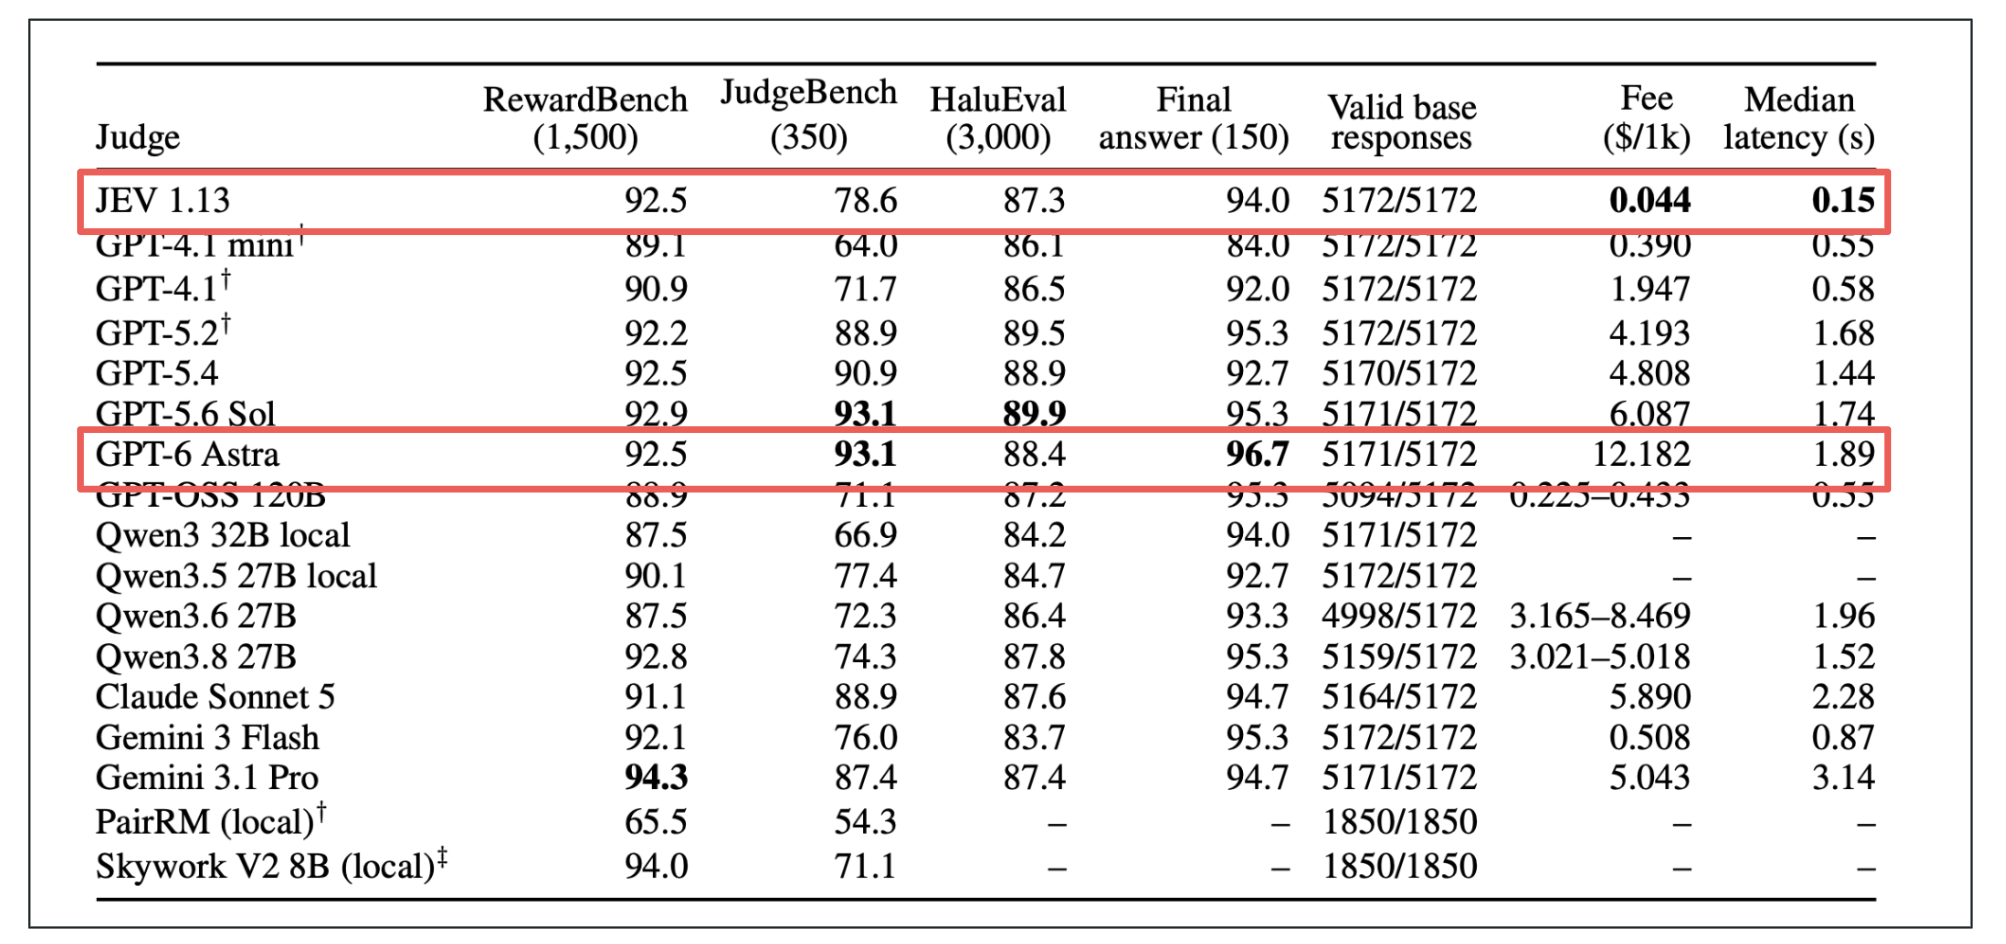
AI Performance Comparison
Let’s look into this in more detail. Jev is visibly inferior to GPT6 Astra across the domains of coding, knowledge, math, and reasoning. These are considered "System 2" thinking tasks that require deep reasoning capabilities. Jev was originally referred to as a "System 1 model"—a model adept at tasks that a human could answer intuitively. Therefore, based on these results, it is safe to say that the domains where Jev can be applied are limited to "System 1" thinking tasks. There is still no all-powerful AI that can cover everything. As expected, using Jev and LLMs selectively according to the use case is essential.
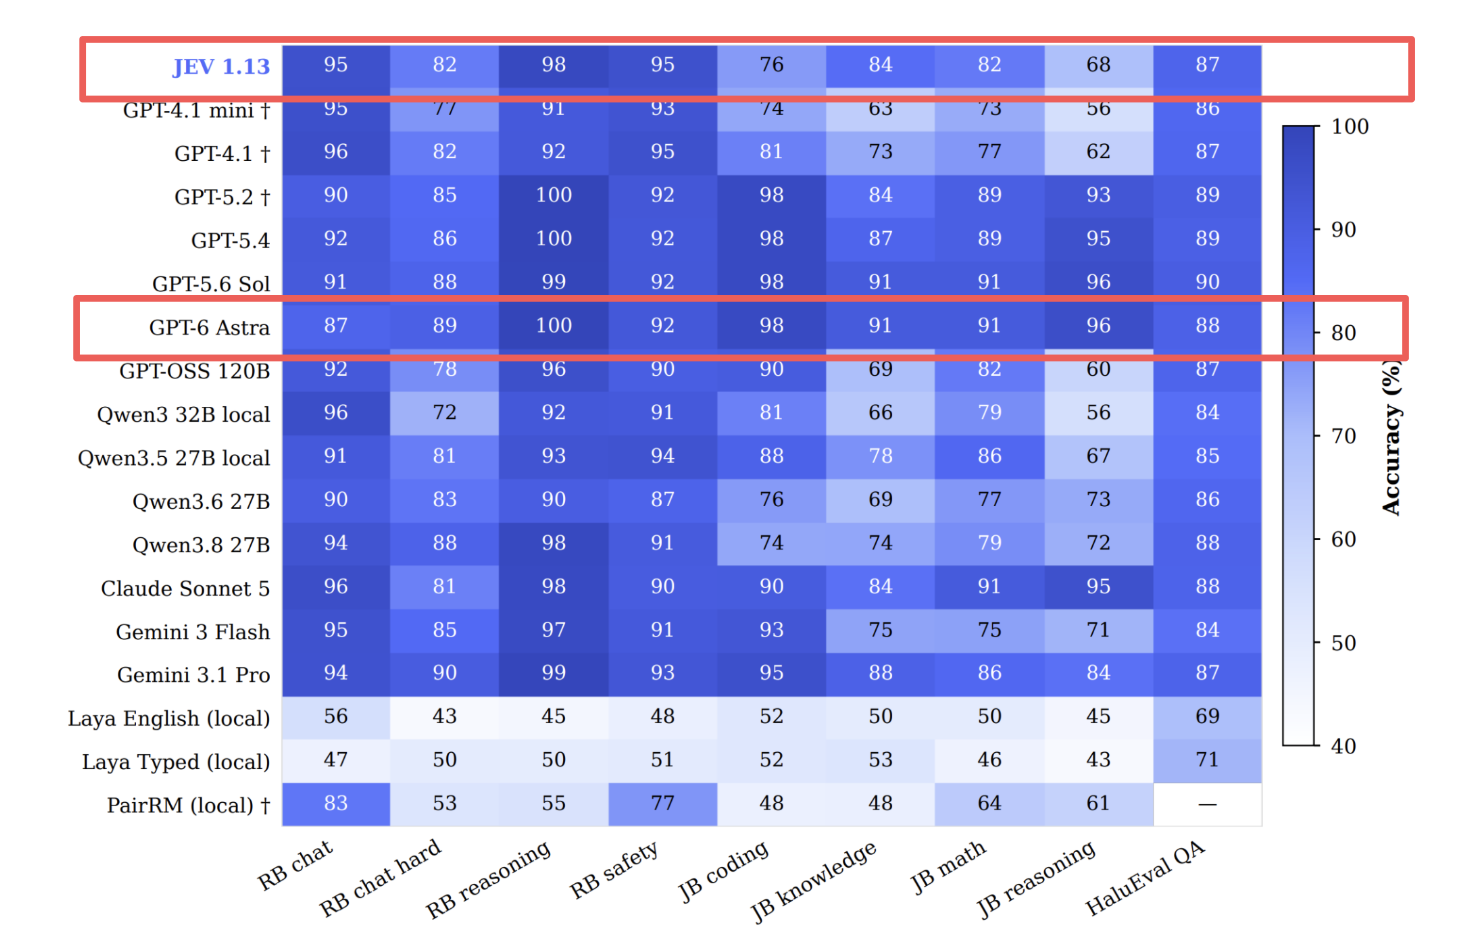
AI Performance Comparison Across Domains
3. Automation with LLMs and Jev
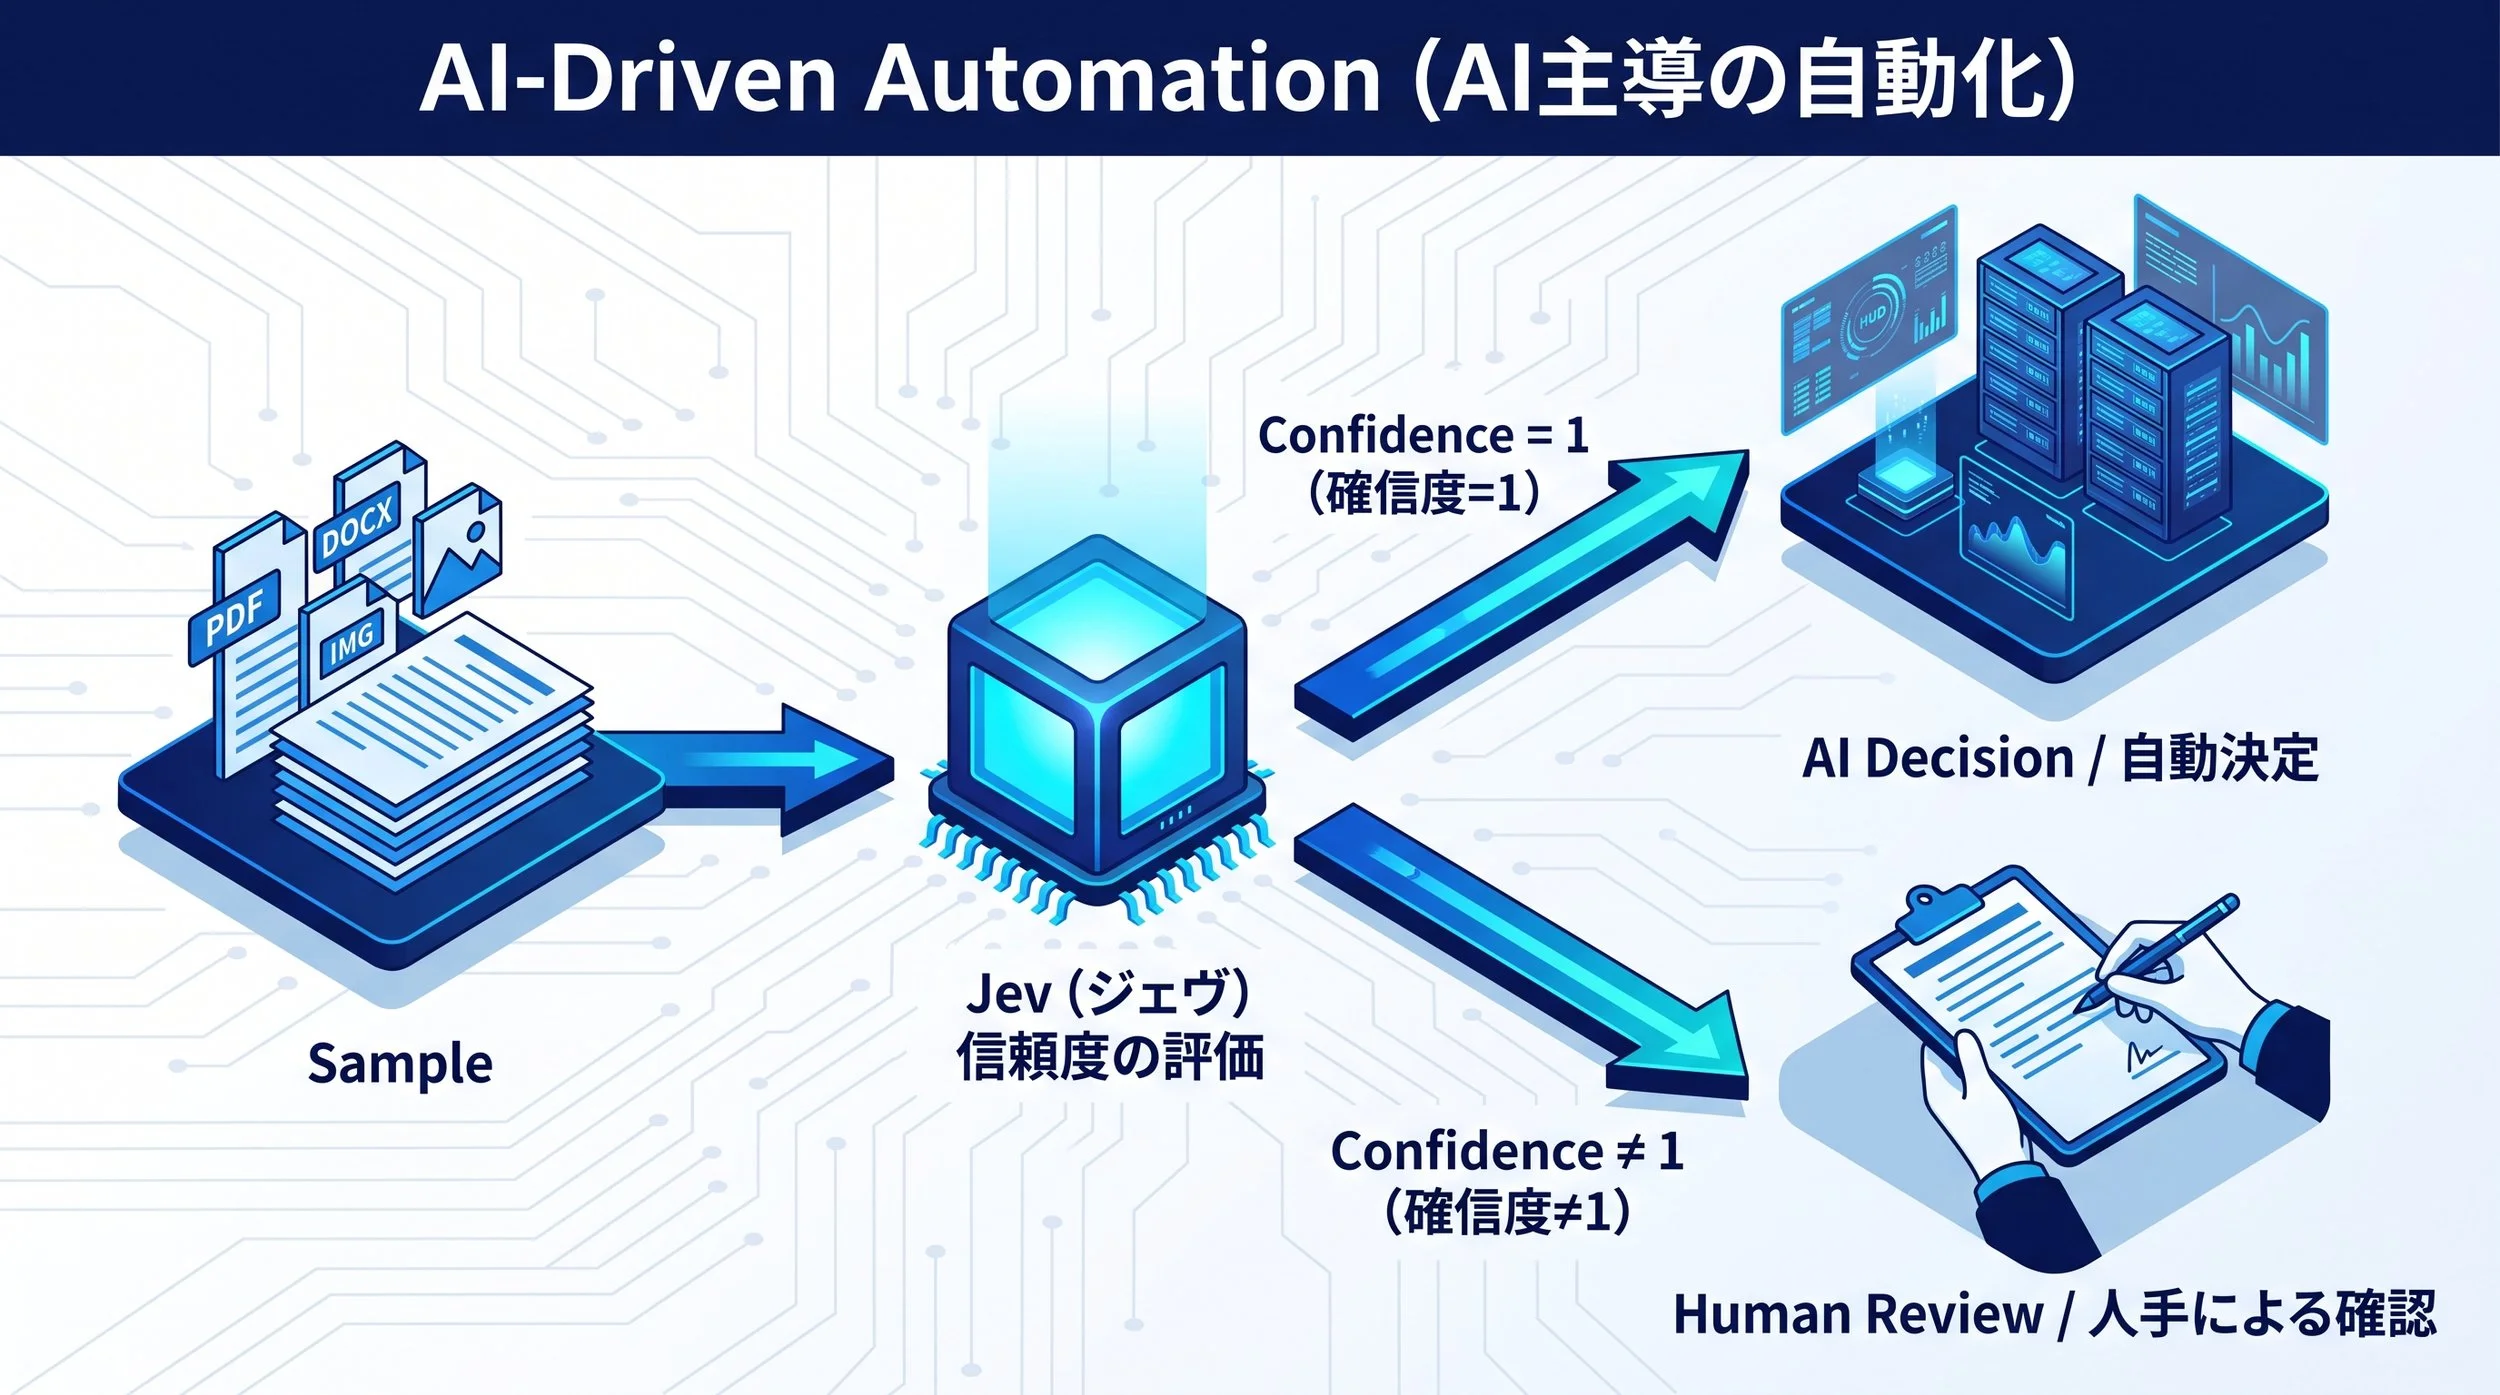
Now that we understand the pros and cons of Jev, let us finally consider a mechanism for automation. As highlighted in the research paper, the fundamental concept is: "Use Jev to triage samples to be evaluated, identify samples where Jev's judgment lacks high confidence, and forward them to a high-performance LLM." This triaging is performed based on the confidence score generated by Jev.
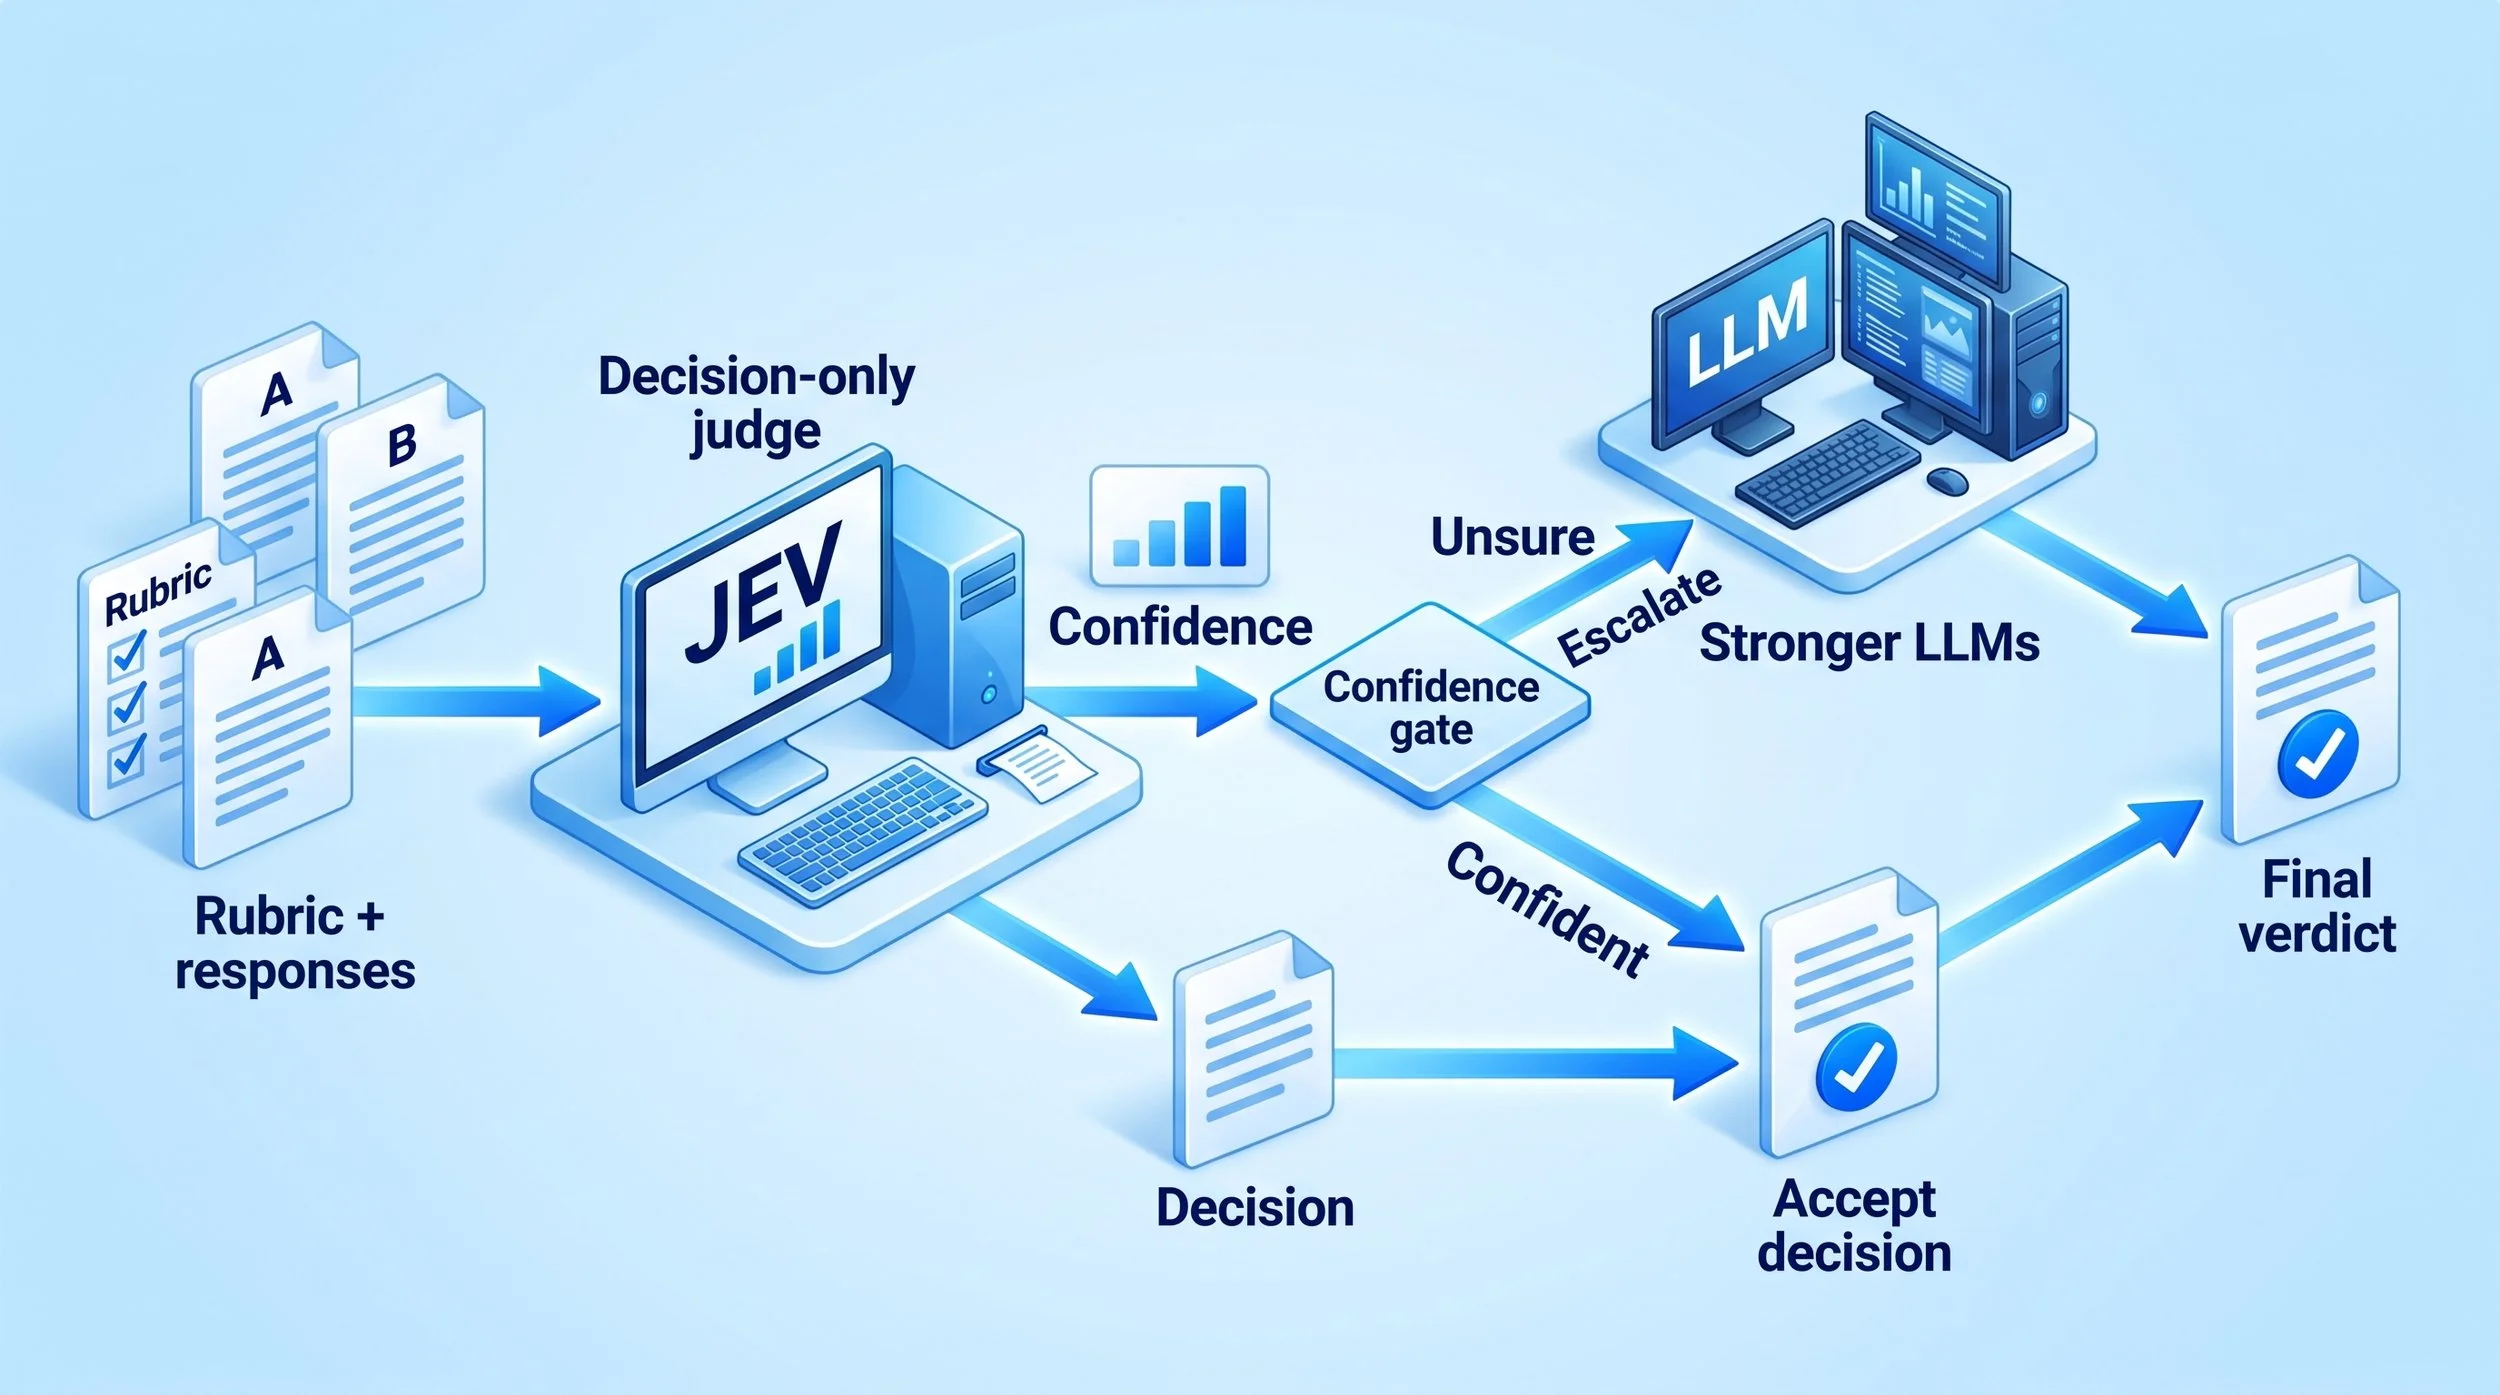
Automation Process Using Jev
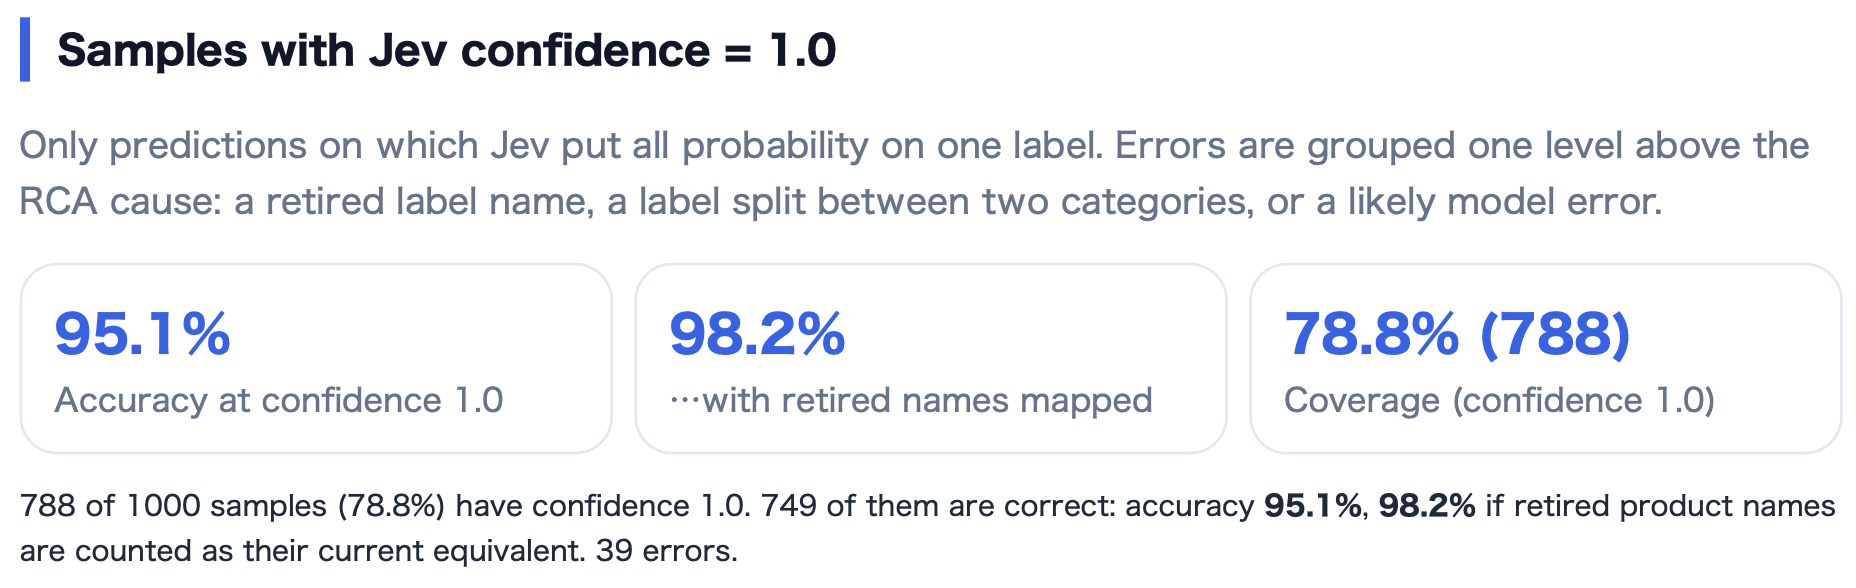
Specifically, it works as follows: Jev outputs the classification result along with confidence scores for each label. In this example, the confidence score is 0.91. With this level of certainty, Jev's output "Classification Label 1" can be accepted. However, if the confidence score is low, such as 0.6, it is better to route it to a powerful LLM and adopt the judgment from there. Furthermore, that threshold is configured based on the target labeled dataset. Through this approach, automation that eliminates the "Human in the loop" is achieved. It is truly remarkable.
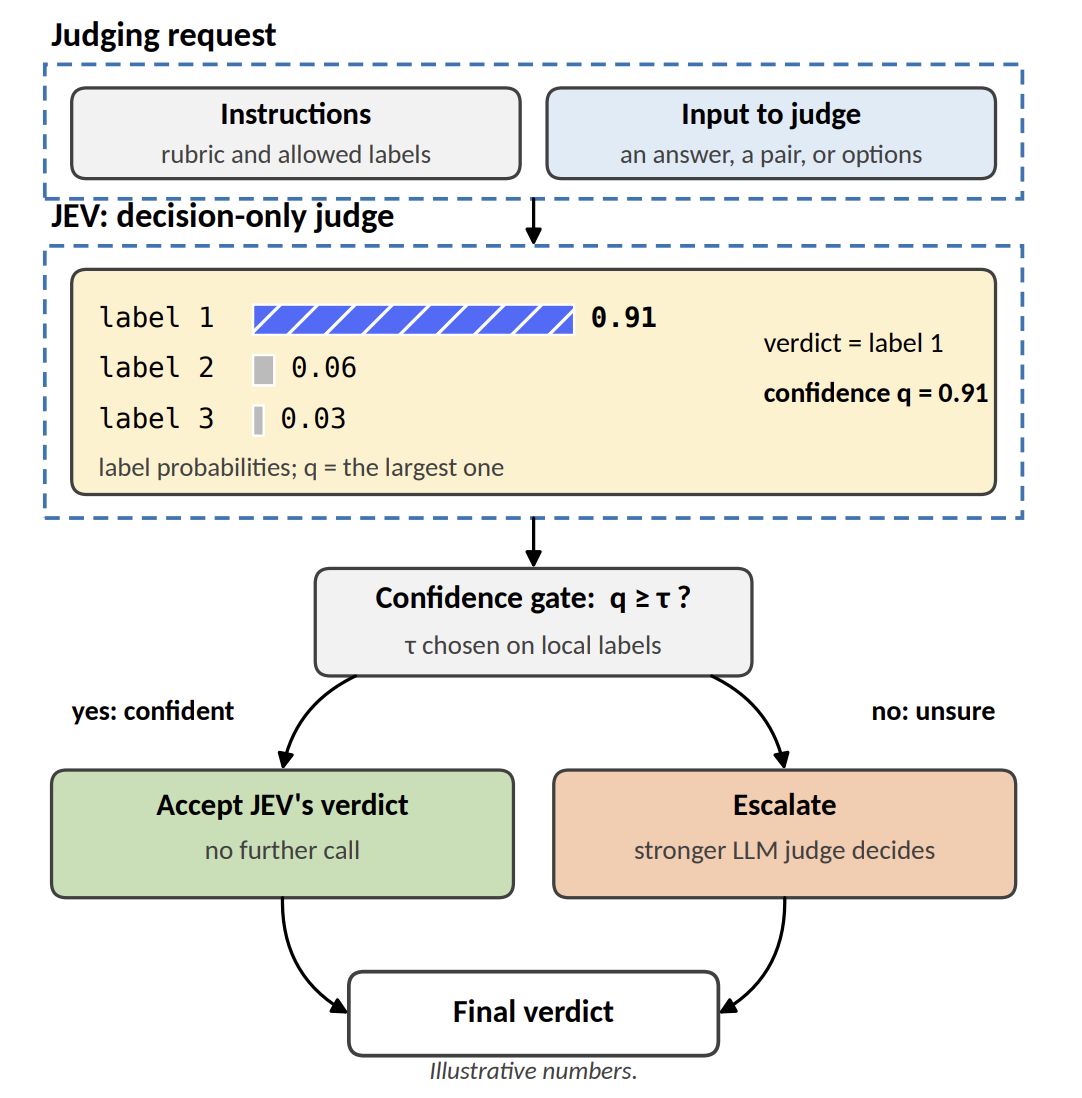
Automation Combining LLMs and Jev
What did you think? By combining LLMs with Jev, we can see a clear path to breaking through the barriers of computation speed and cost—the traditional drawbacks of LLMs—while maintaining accuracy.
Here at Toshi Stats, we intend to continue taking on the challenge of business automation through AI. Stay tuned!
You can enjoy our video news “ToshiStats AI Weekly Review” from this link.
1) Introducing System One Models & Jev, Sep 15 2026, Diogo Almeida, founder, TypeSafe
2) JEV-as-a-Judge: Accept When Confident, Escalate When Unsure
Yubo Li, Yidi Miao. Ramayya Krishnan, Rema Padman
Carnegie Mellon University, Oct 9 2026
Copyright © 2026 ToshiStats Co., Ltd. All right reserved.
Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.