Automation

Testing AI-Driven Workflow Automation: Simulation and Key Takeaways

It has been about a month since the release of the "system one" model, a new AI specialized in judgment and decision-making (1). In this article, I would like to explore how we can advance business process automation using this system one model. To that end, I developed an AI automation simulation app. Using this app, I will run simulations and take a concrete look at how automation can be implemented.


1. How Workflow Automation Works

First, let me briefly explain how simulations are conducted in the application I developed. Fundamentally, various cases are fed into the system one model to make judgments and decisions, which then determine the downstream actions. However, for judgments where the system one model lacks confidence, the task is routed to an LLM (Large Language Model) to ensure a more careful decision.

The screen below shows the application's GUI. On the left, there are selection buttons for the system one model and the LLM. When the confidence score of the system one model is low, the decision is delegated to the LLM, and you can adjust the threshold for this using a slider. For this simulation, I set it to 0.95. Furthermore, you can input the actual workflow to be automated in natural language into the box on the right. Here, the system one model which financial product a bank customer's complaint refers to, which department should handle it, and what subsequent actions to take. For this run, I set the number of cases to 20.
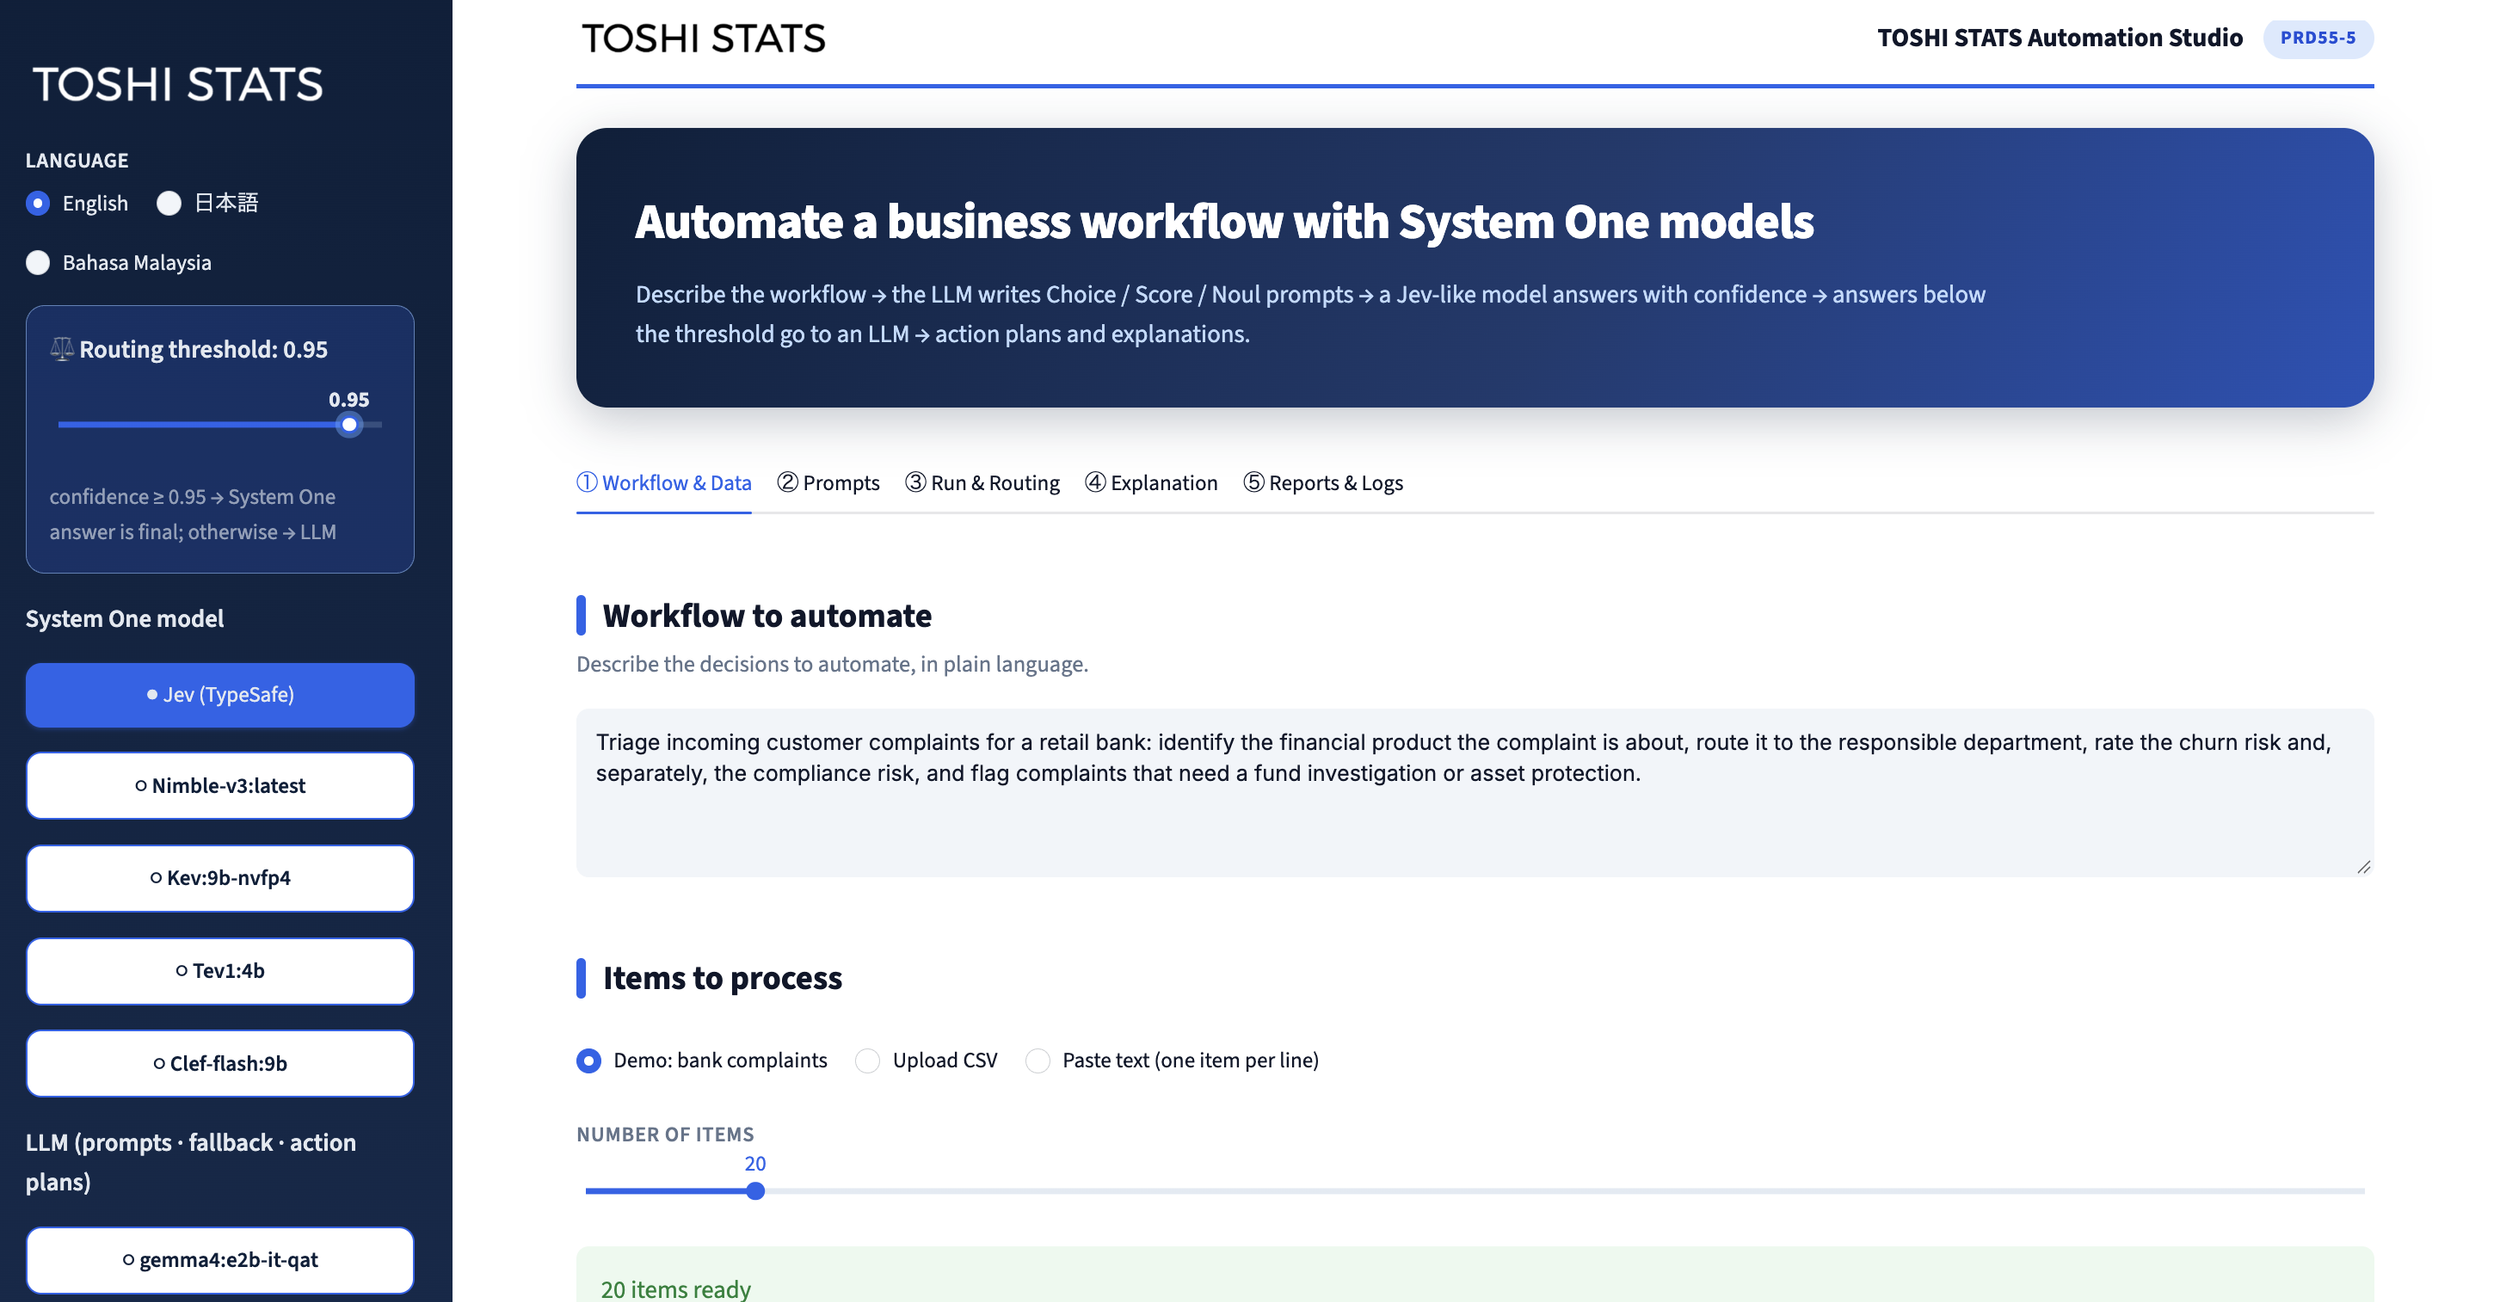
GUI of the Simulation App

You can also input specific instructions, or "prompts," for the system one model to make judgments on. This time, I used a pre-prepared demo prompt. The system one model can make three types of judgments: "Choice" (selecting from a set of candidates), "Score" (rating on a scale, such as 1 to 10), and "Noul" [Boolean/Yes-or-No] (answering Yes or No). Here, I set it to respond to the five instructions illustrated below. Since there are 20 cases and 5 instructions per case, it will respond to a total of 100 instructions.
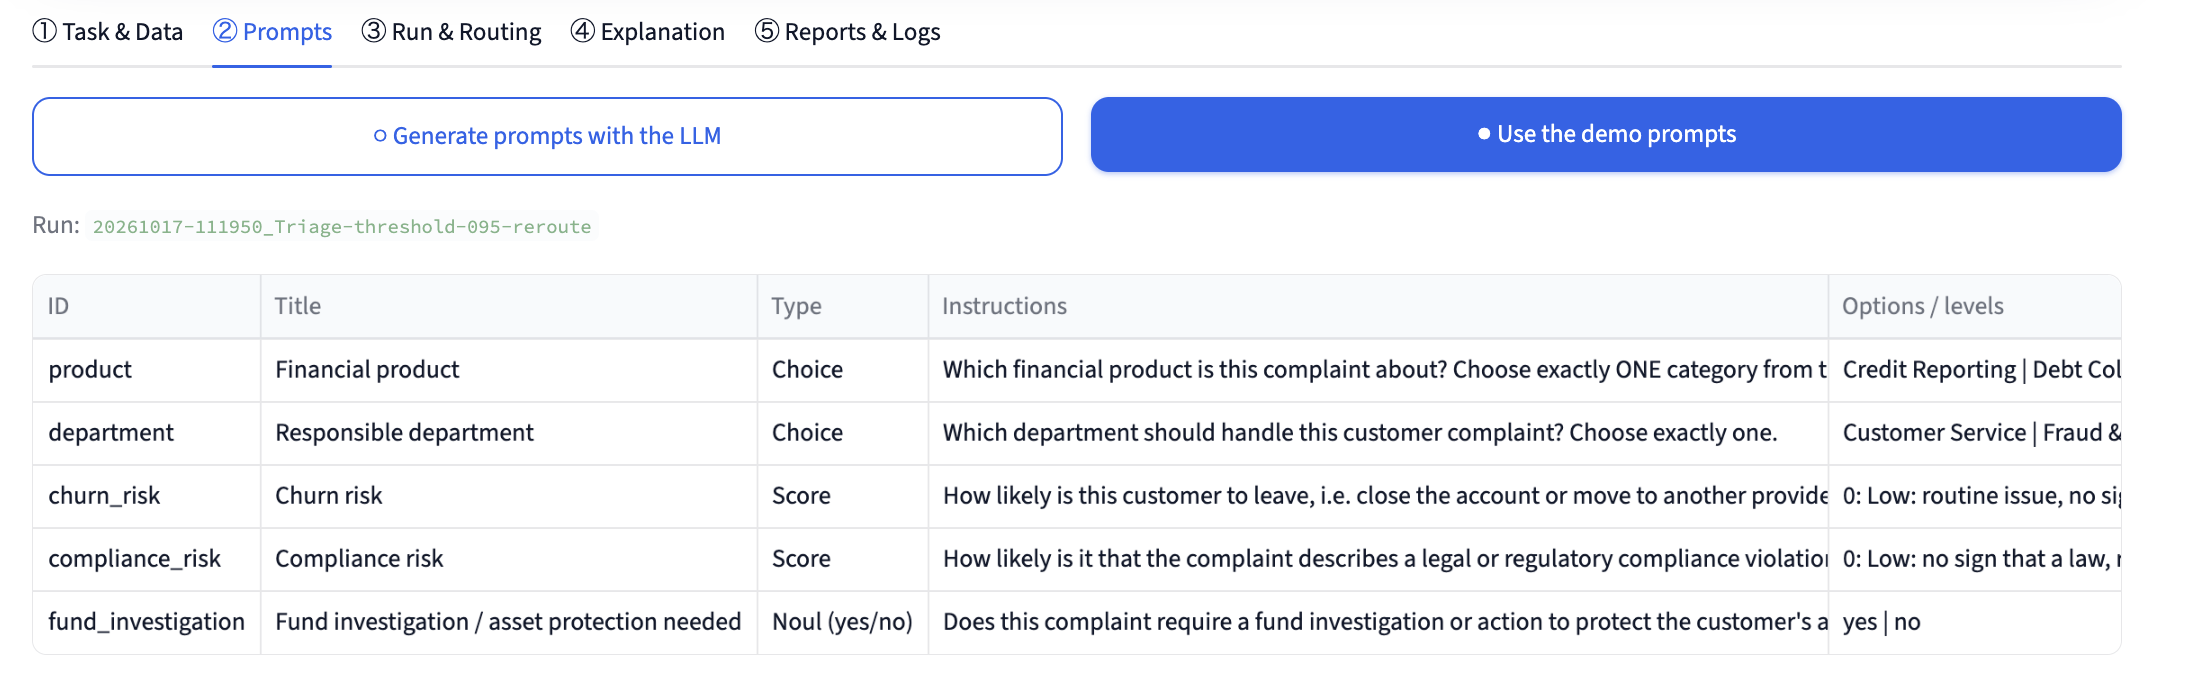
‍ Prompts for the system one model

The overall automation flow is shown in the chart below. Pay particular attention to the branching point after the initial system one model judgment: depending on whether the confidence score exceeds the threshold, the judgment is either adopted as-is or routed to the LLM for further evaluation.
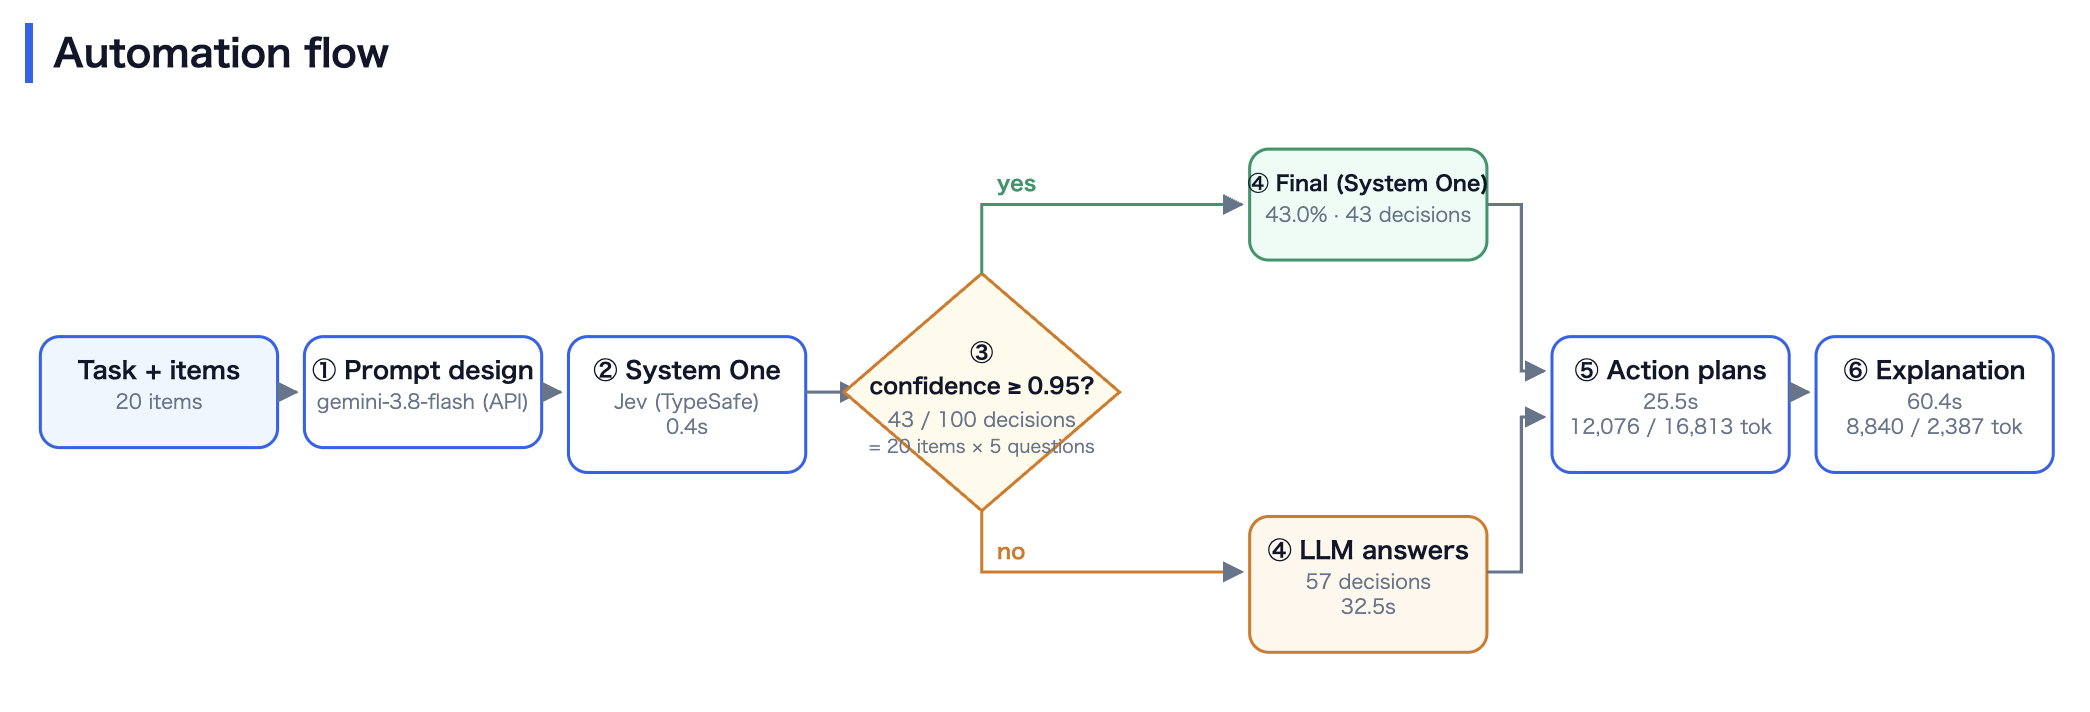
‍ ‍Automation Flow


2. Verification of Simulation Accuracy

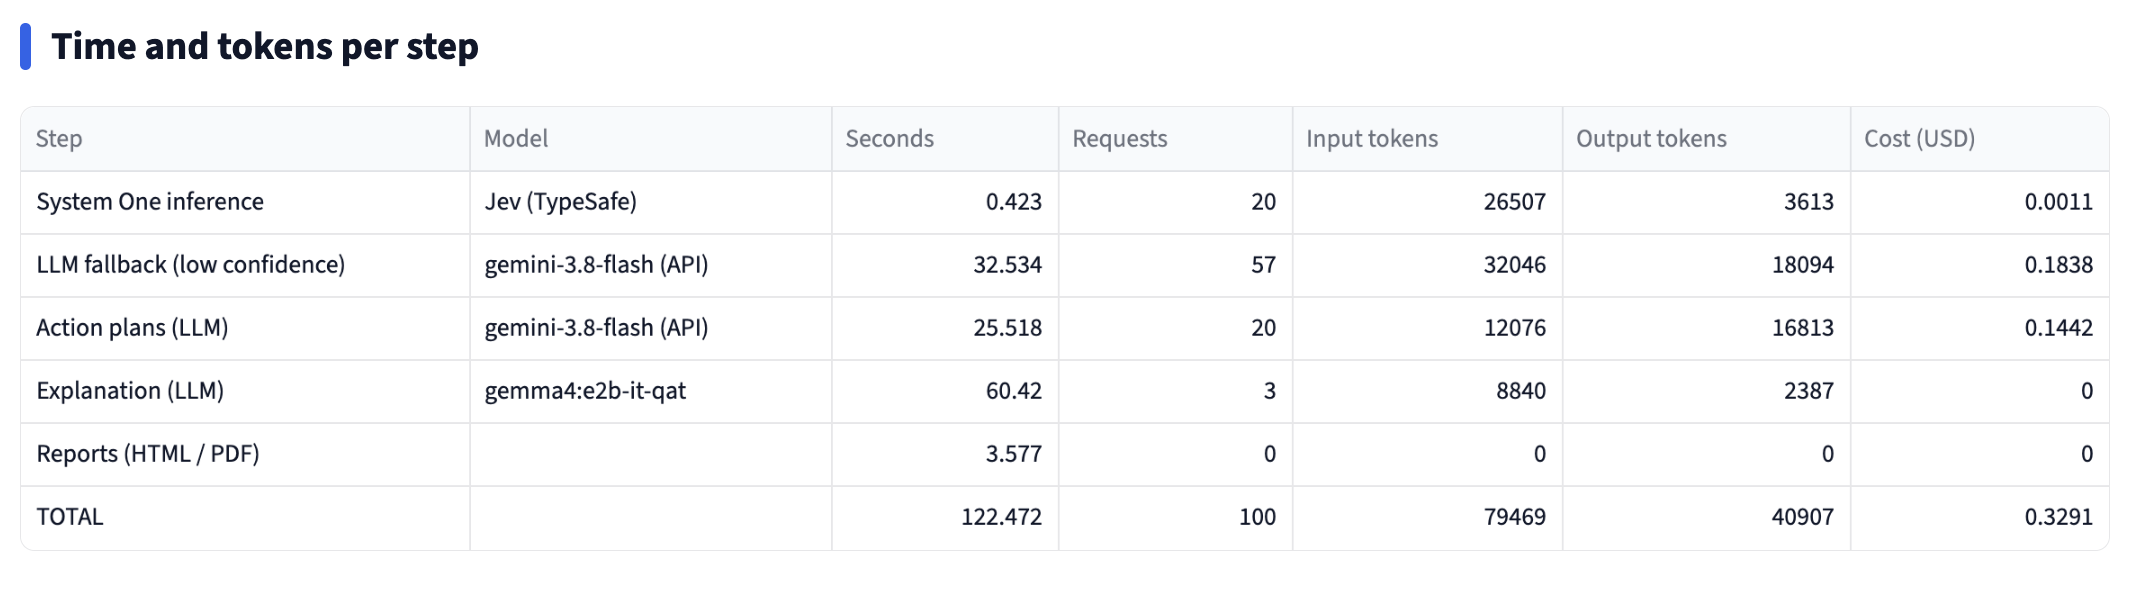
In this simulation, I used "Jev" for the system one model and "Gemini 3.8 flash" for the LLM. The results showed that 43% of the total tasks were resolved solely by the system one model, while the remaining 57% were routed to the LLM. The total computation time was about 2 minutes, and the cost was approximately $0.32 USD. Since both Jev and Gemini 3.8 flash are accessed via APIs, they are paid services.
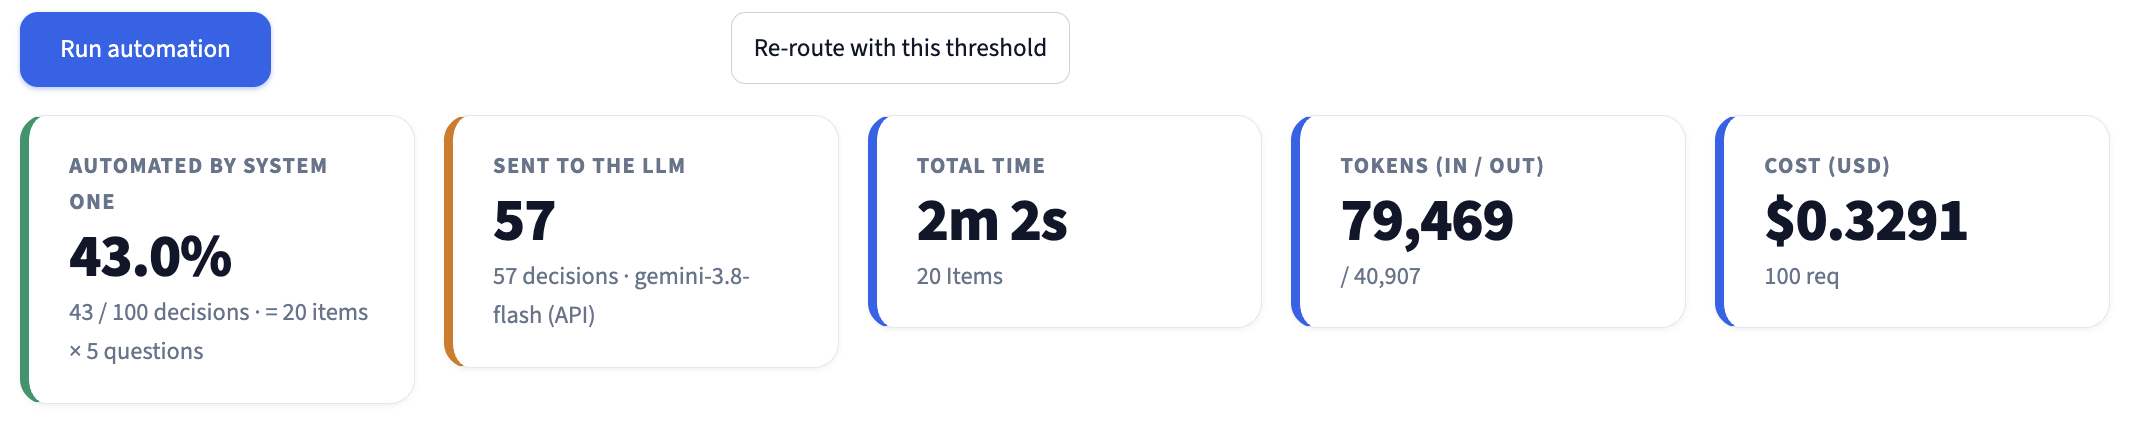
‍ ‍Simulation Results

Additionally, one of the instructions in this test includes ground-truth labels indicating which financial product each customer complaint pertains to, allowing us to verify accuracy. As shown below, the accuracy when judged solely by the system one model was 85%. By routing samples that fell below the threshold to the LLM to improve performance, the overall accuracy rose to 90%. Furthermore, for cases where the system one model had a confidence score of 0.95 or higher, the accuracy reached 93.8%, demonstrating that the system one model's judgments are highly accurate when its confidence is high. On the other hand, the accuracy for cases below the threshold that were delegated to the LLM was 75%, indicating that these were inherently difficult cases to judge.
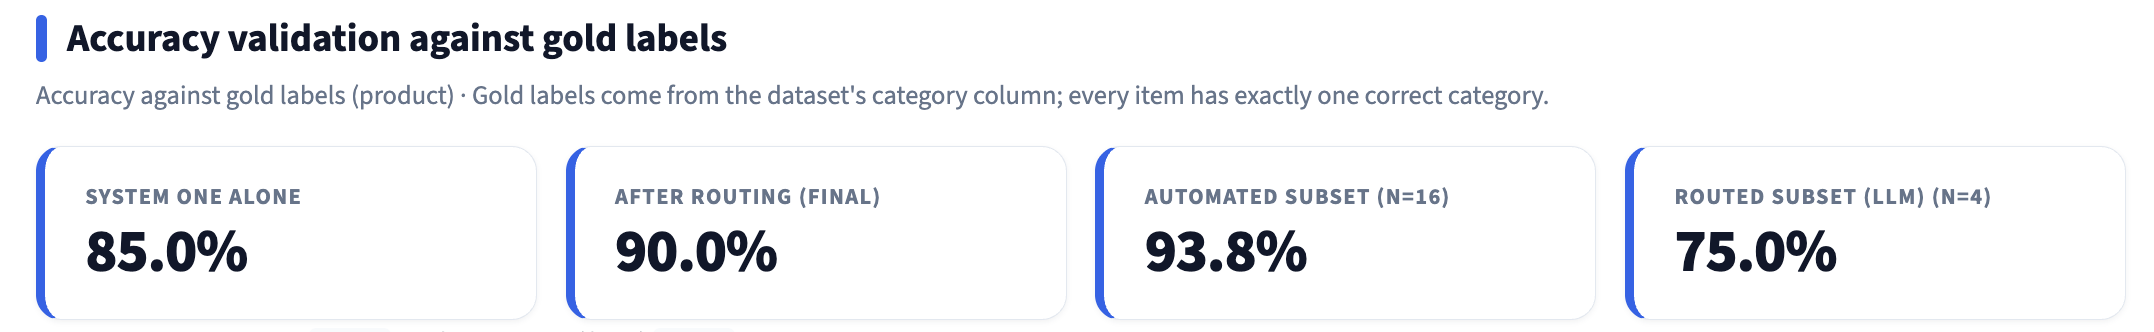
‍ Accuracy Verification

The details per step are provided here
Now, let's look at the accuracy for each category using a confusion matrix. When judged solely by the system one model on the left, "Credit Card Services" could not be identified well. However, when routed to the LLM on the right, "Credit Card Services" was correctly identified. In a confusion matrix, the diagonal elements represent correct predictions, so you can clearly see that routing to the LLM improved the accuracy.
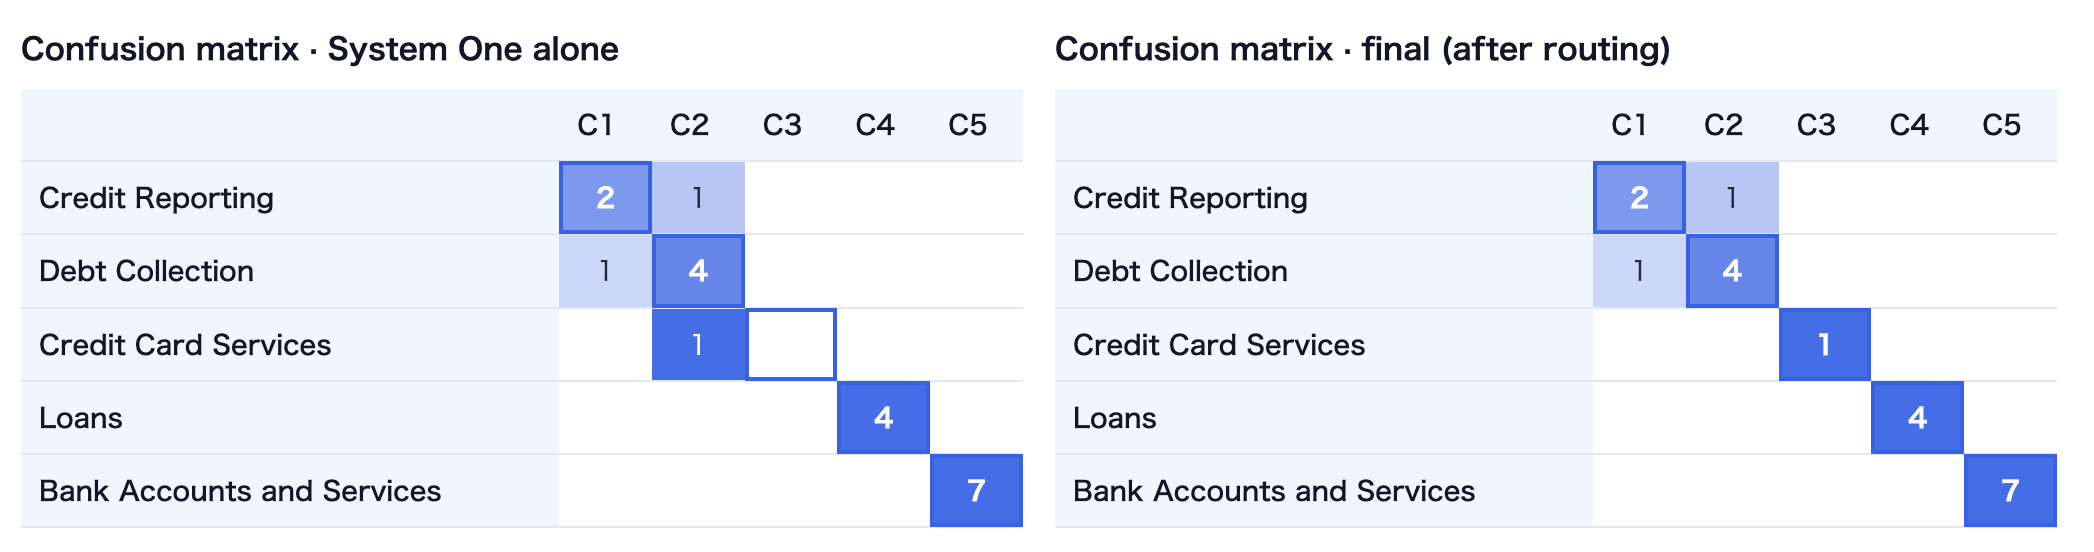
Confusion Matrix (Rows = True Categories, Columns = Predicted Categories. Diagonal elements represent correct answers)


3. Effectiveness of Workflow Automation

Ultimately, the effectiveness of workflow automation using a system one model depends on having a high proportion of high-confidence cases. The chart below shows the distribution of confidence scores for each instruction. Those in green, close to a confidence score of 1, can be considered highly accurate in their classifications. Among these, "Compliance Risk" has a distribution extending toward lower confidence scores, indicating that it was a difficult instruction for the system one model to judge. For such instructions, further refinements to the prompt will likely be needed to boost confidence scores.
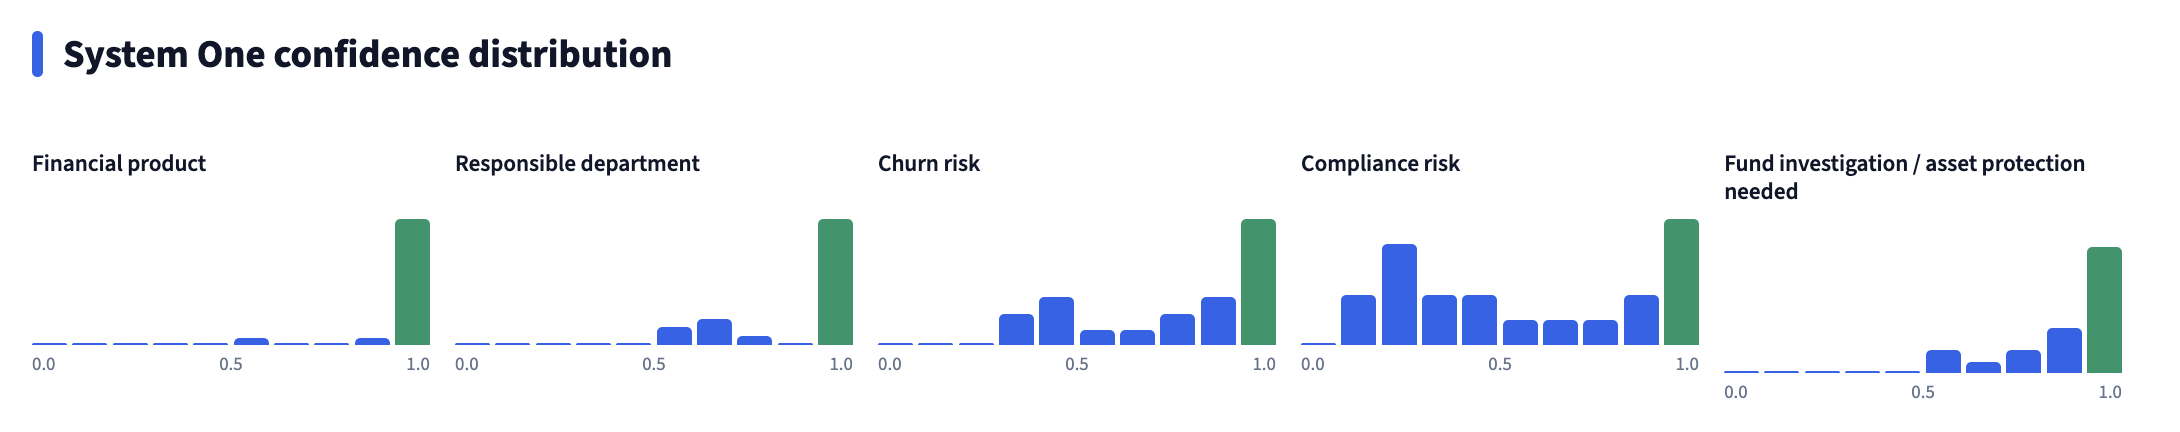
‍ ‍Distribution of Confidence Scores


What did you think? In this test, I automated a workflow for processing bank customer complaints using Jev. Because this app is flexibly designed, you can easily swap the system one model for an open-weight model or adapt the workflow to other industries. At ToshiStats, I plan to explore and simulate various other use cases in the future. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link


1) Introducing System One Models & Jev,  Sep 15 2026, Diogo Almeida, founder, TypeSafe

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Building Resilient Automation: How to Combine LLMs and Jev for Production-Grade Workflows   

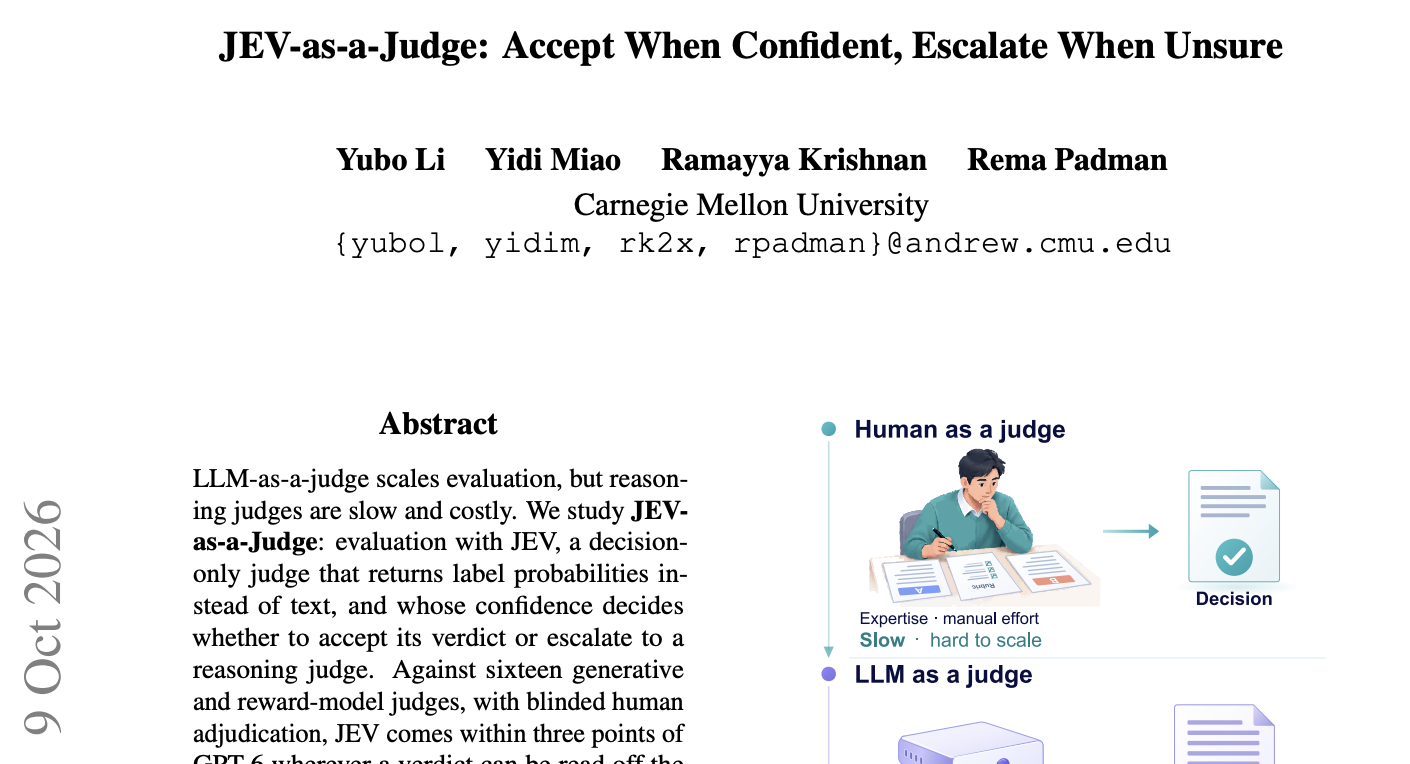
Nearly a month has passed since the new type of AI, "Jev," was announced on September 15, 2026 (1). Since then, various companies have introduced similar AIs, and momentum around this Jev-like-AI category has been growing rapidly. Therefore, in this article, we would like to unpack the wonderful research paper below (2) and explore ways to achieve automation by mastering this AI called Jev.


1. Humans, LLMs, and Jev

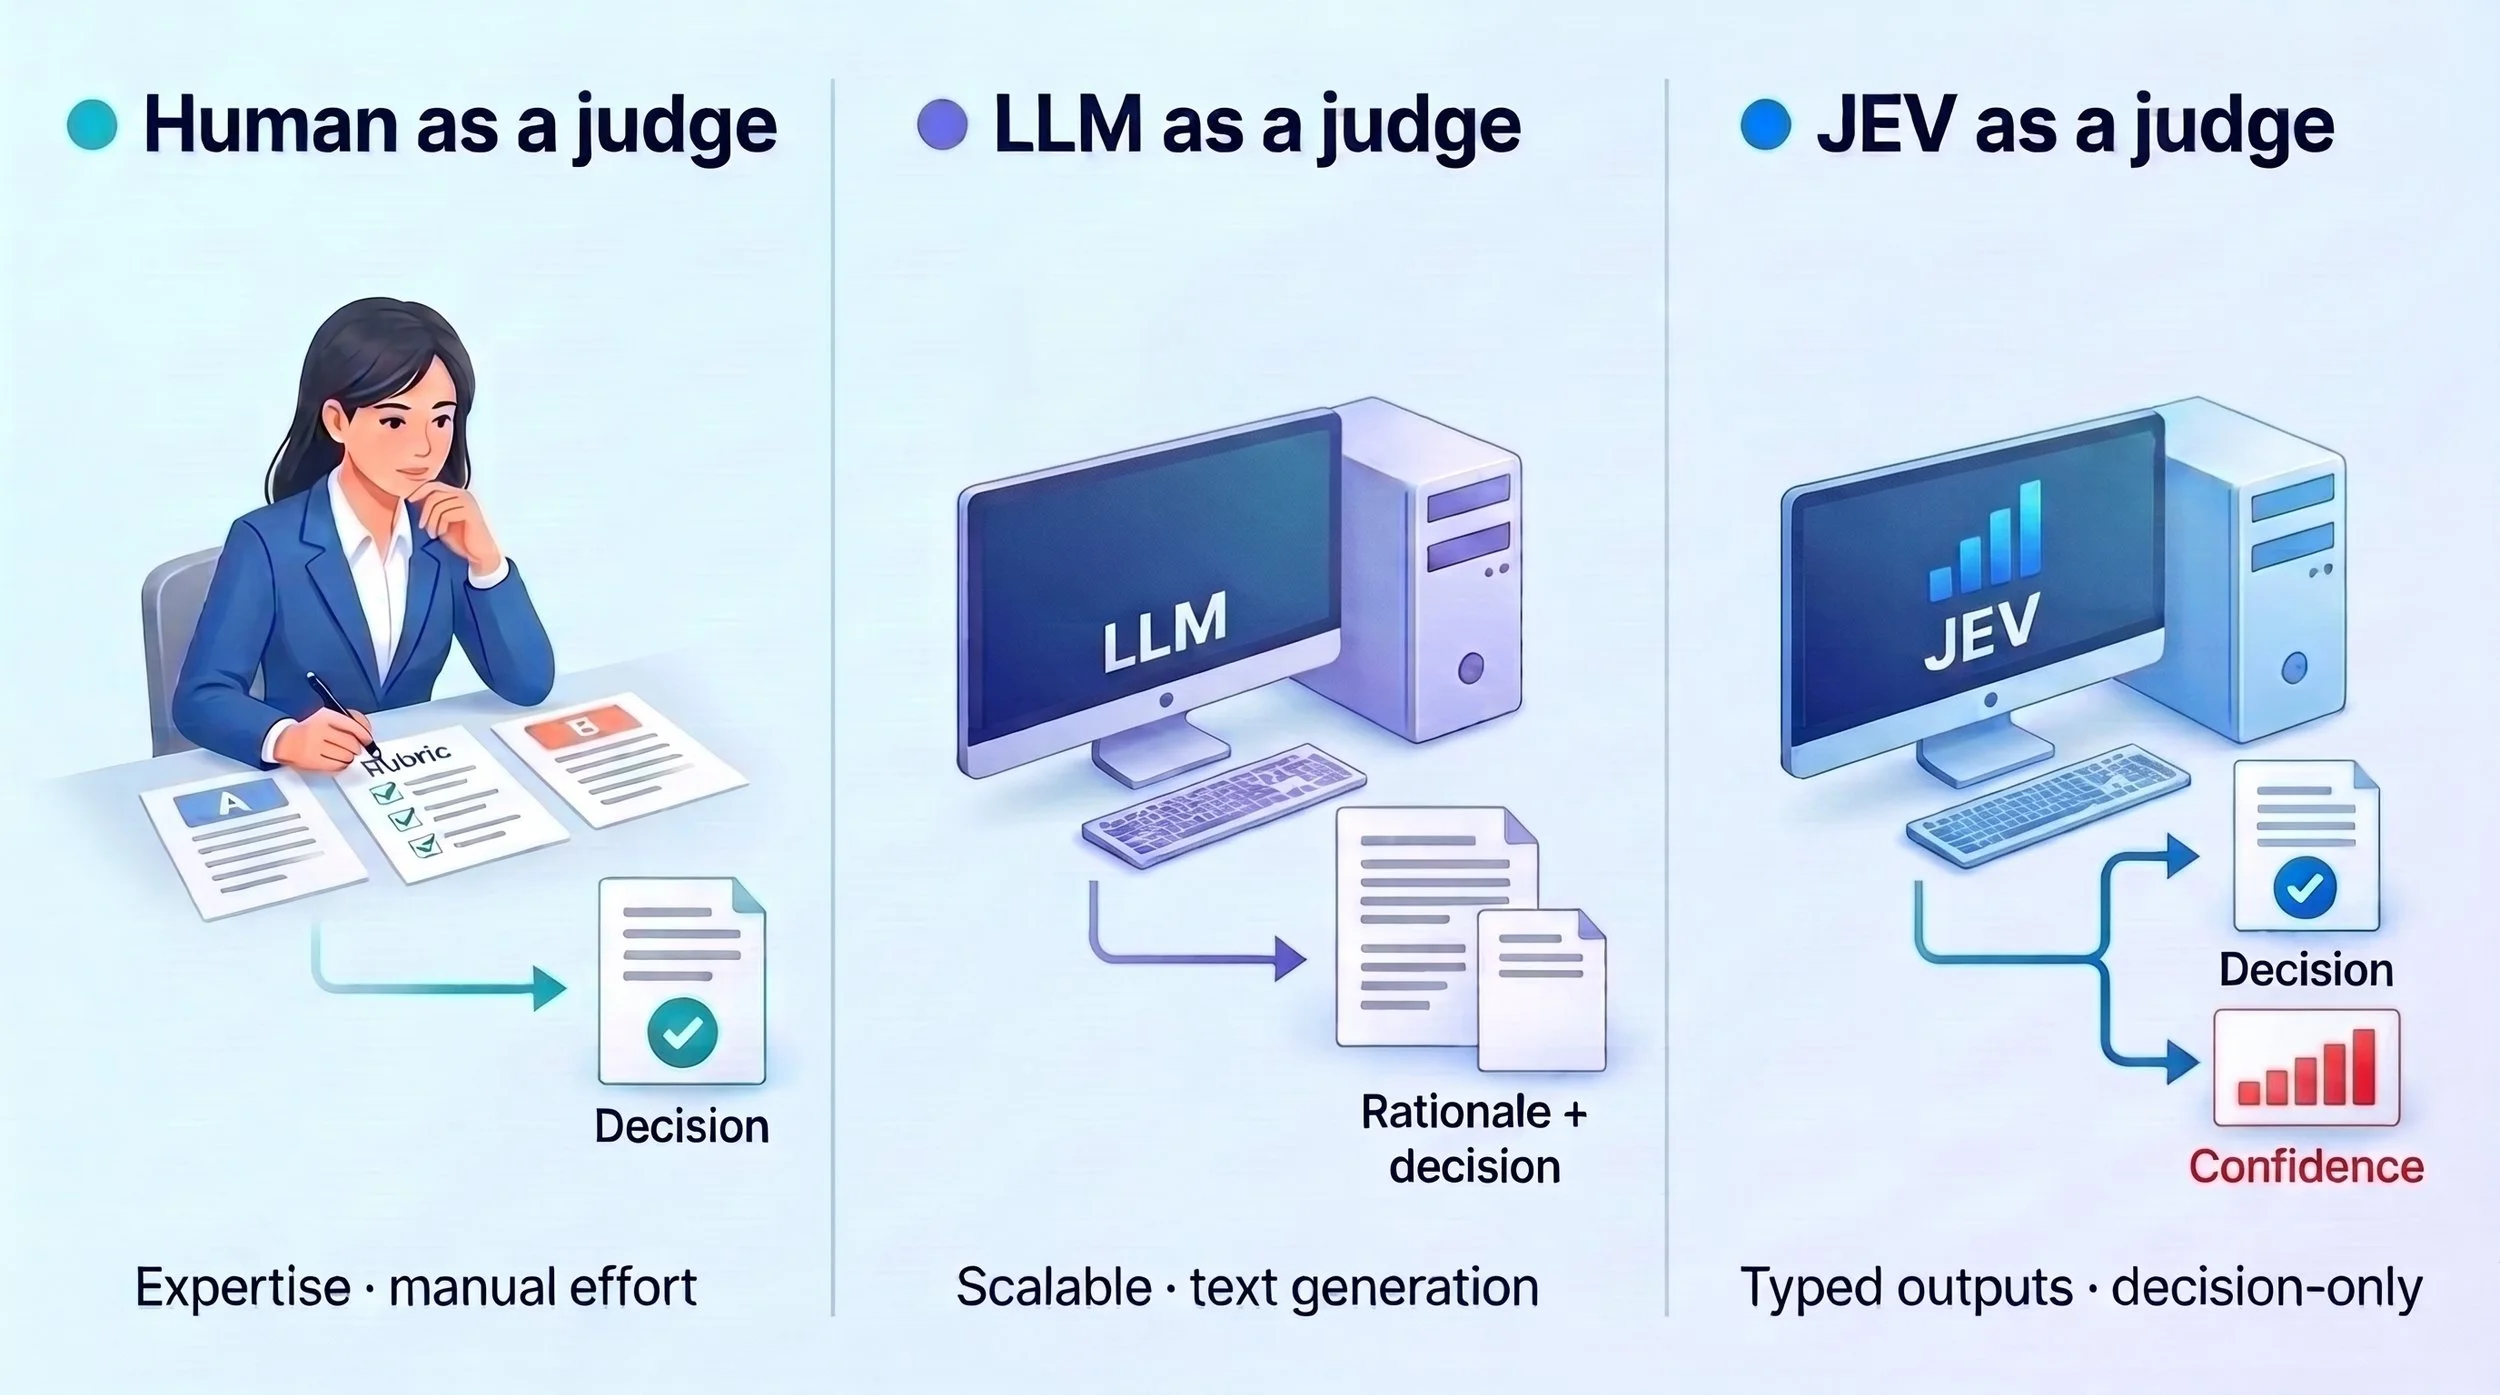
First, let us compare judgments made by humans, LLMs (Large Language Models), and Jev to examine their respective characteristics. The research report also summarizes them as shown in the chart below.

Here, let’s consider a task where you read an internal approval request and decide whether you can sign off on it. With the expertise you have cultivated fully on display, the accuracy of your discernment would undoubtedly be outstanding. Unfortunately, however, your resource is limited to single-person manpower, making it impossible to scale up all at once. For this reason, it has recently become common practice to delegate your tasks to AI agents powered by LLMs. The capabilities of cutting-edge LLMs are remarkable, with cases emerging where their accuracy surpasses that of humans. Yet, LLMs also have shortcomings that make them ill-suited for automation.

‍              ‍Distinction between Humans and AI

It is true that more and more LLMs can achieve high accuracy; however, they inevitably suffer from two persistent drawbacks:

  1. Slow computation speed

  2. High computation cost

Because they perform inference using a massive number of tokens—a process known as Chain of Thought—to achieve high accuracy, they are structurally disadvantaged in terms of both computation speed and cost.

That is where Jev comes in. Jev overcomes these shortcomings of LLMs. We will explain this in detail in the next section.


2. The Capabilities of Jev

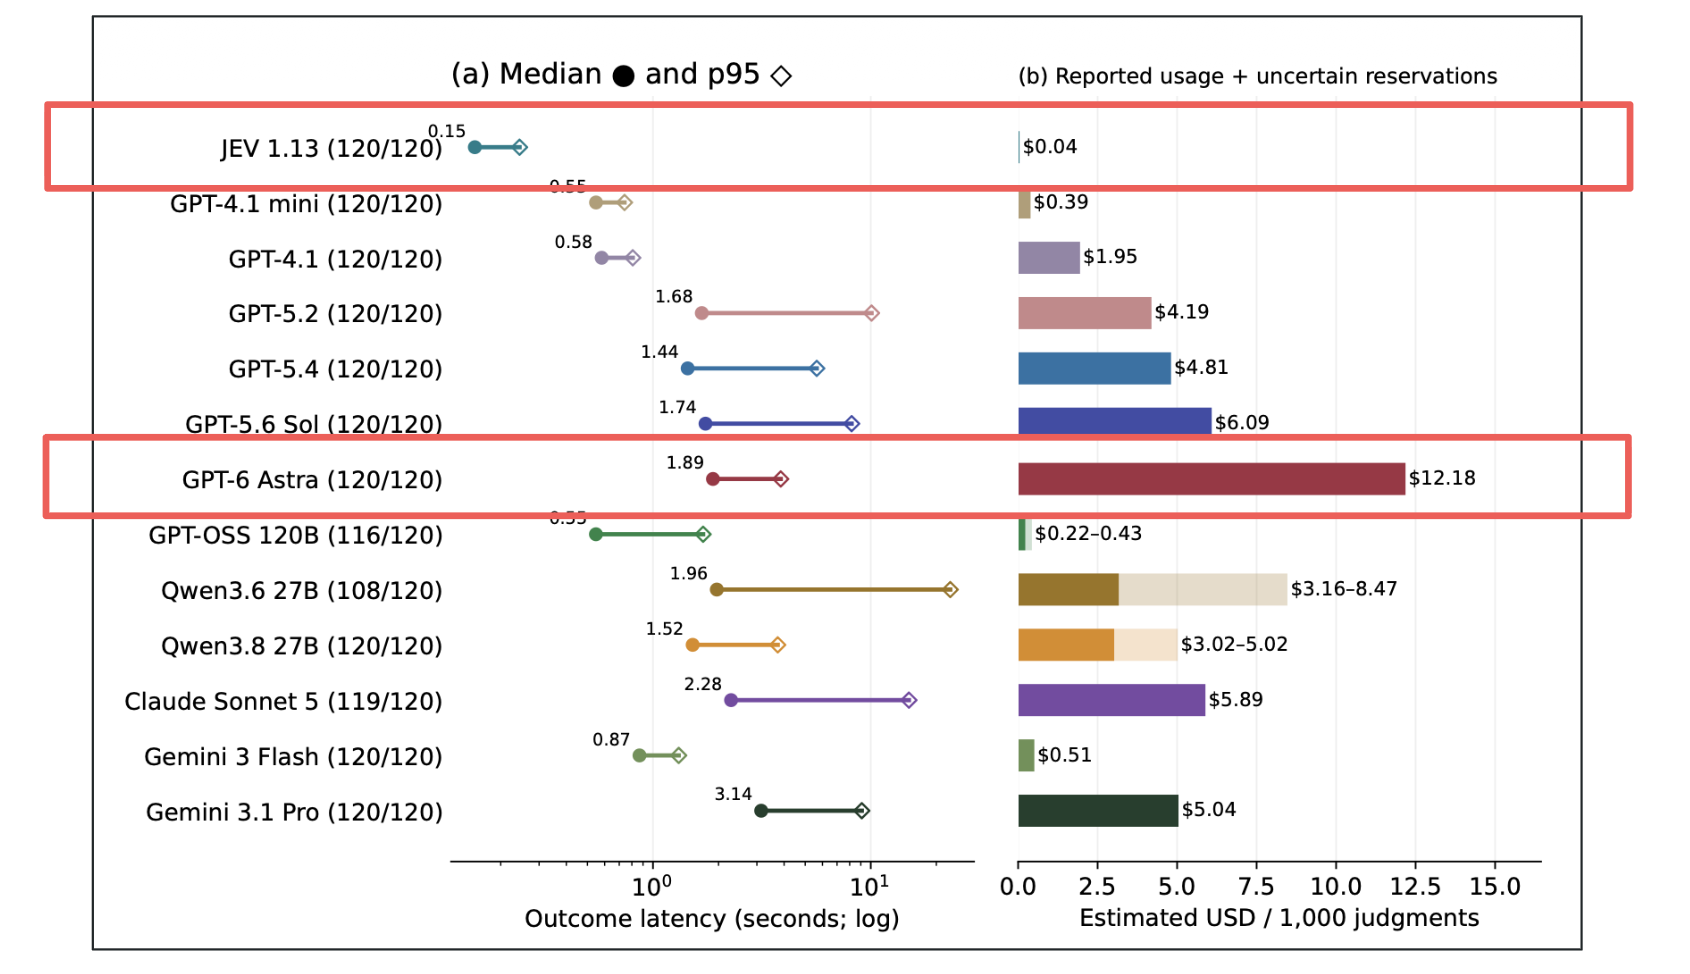
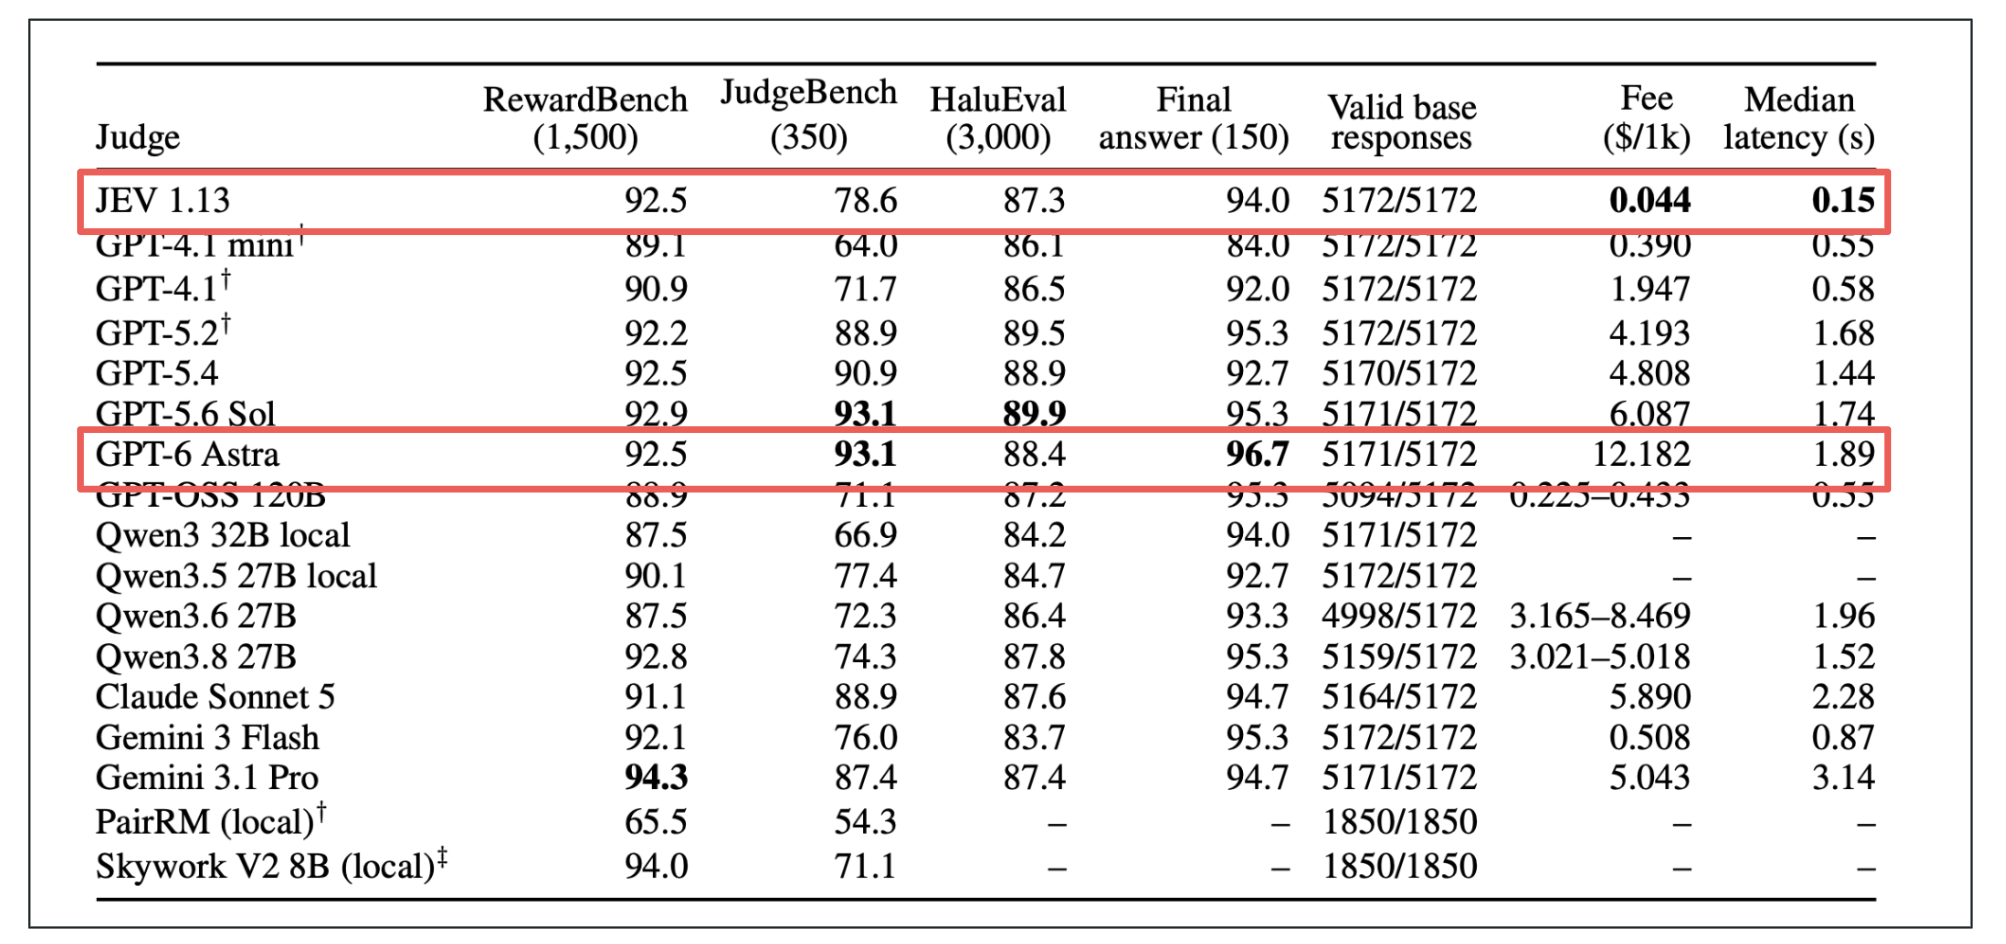
Here, let us directly compare Jev with GPT6 Astra, one of the pinnacle LLMs. The parts enclosed in red frames are Jev and GPT6 Astra.

First, looking at latency (computation time), handling the exact same task took 0.15 seconds for Jev, whereas GPT6 Astra took 1.89 seconds—more than 10 times longer. Next, regarding cost, when performing 1,000 classifications, Jev cost 0.04 USD, whereas GPT6 Astra cost 12.18 USD—over 200 times more expensive. While this is just one example, it is more than sufficient to understand Jev's strengths.

‍  ‍              Latency and Cost Comparison

Although Jev may seem flawless, it naturally has weaknesses. As shown below, Jev is clearly inferior to GPT6 Astra on JudgeBench.

‍  ‍               AI Performance Comparison

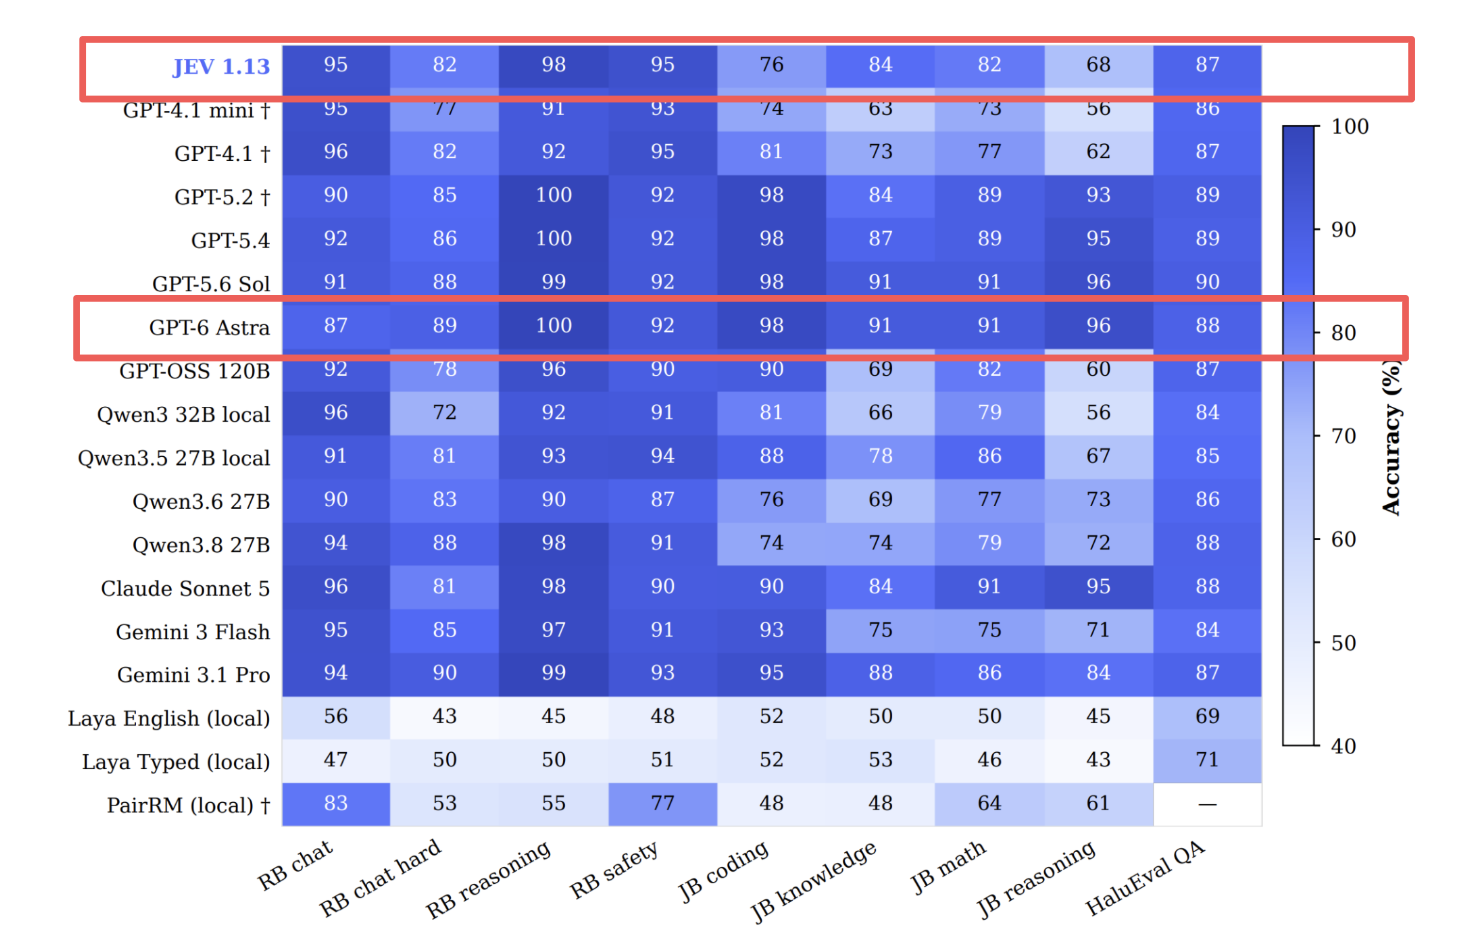
Let’s look into this in more detail. Jev is visibly inferior to GPT6 Astra across the domains of coding, knowledge, math, and reasoning. These are considered "System 2" thinking tasks that require deep reasoning capabilities. Jev was originally referred to as a "System 1 model"—a model adept at tasks that a human could answer intuitively. Therefore, based on these results, it is safe to say that the domains where Jev can be applied are limited to "System 1" thinking tasks. There is still no all-powerful AI that can cover everything. As expected, using Jev and LLMs selectively according to the use case is essential.

             AI Performance Comparison Across Domains


3. Automation with LLMs and Jev

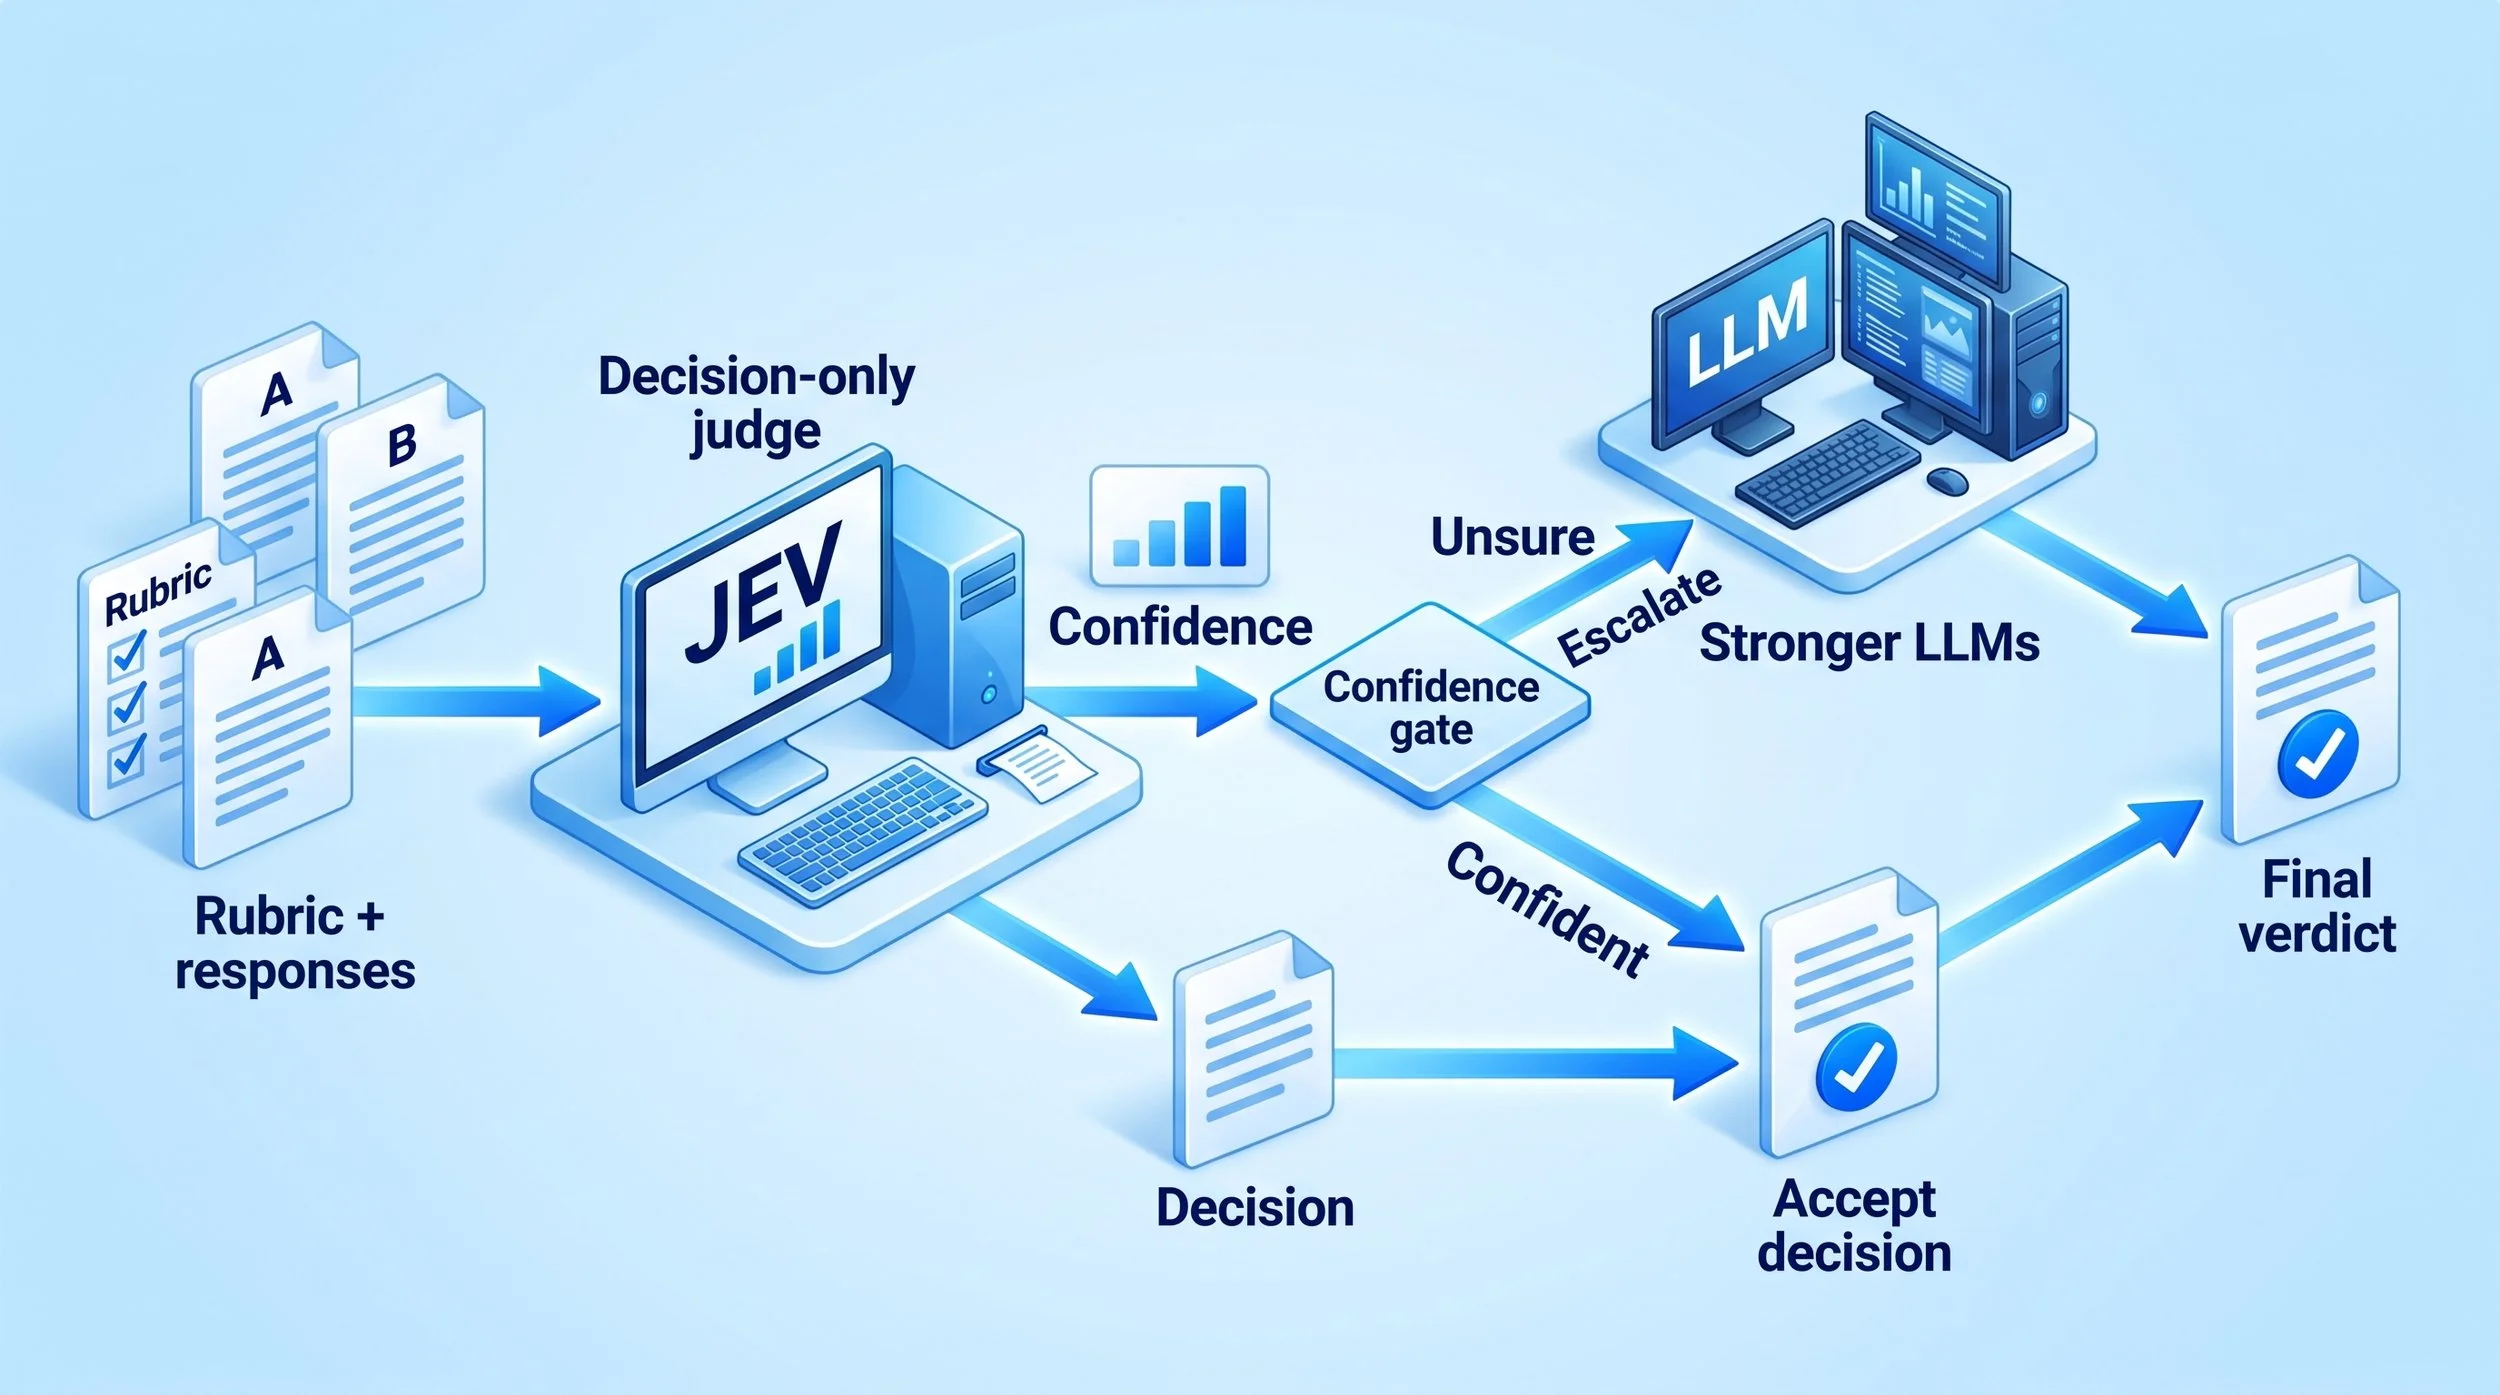
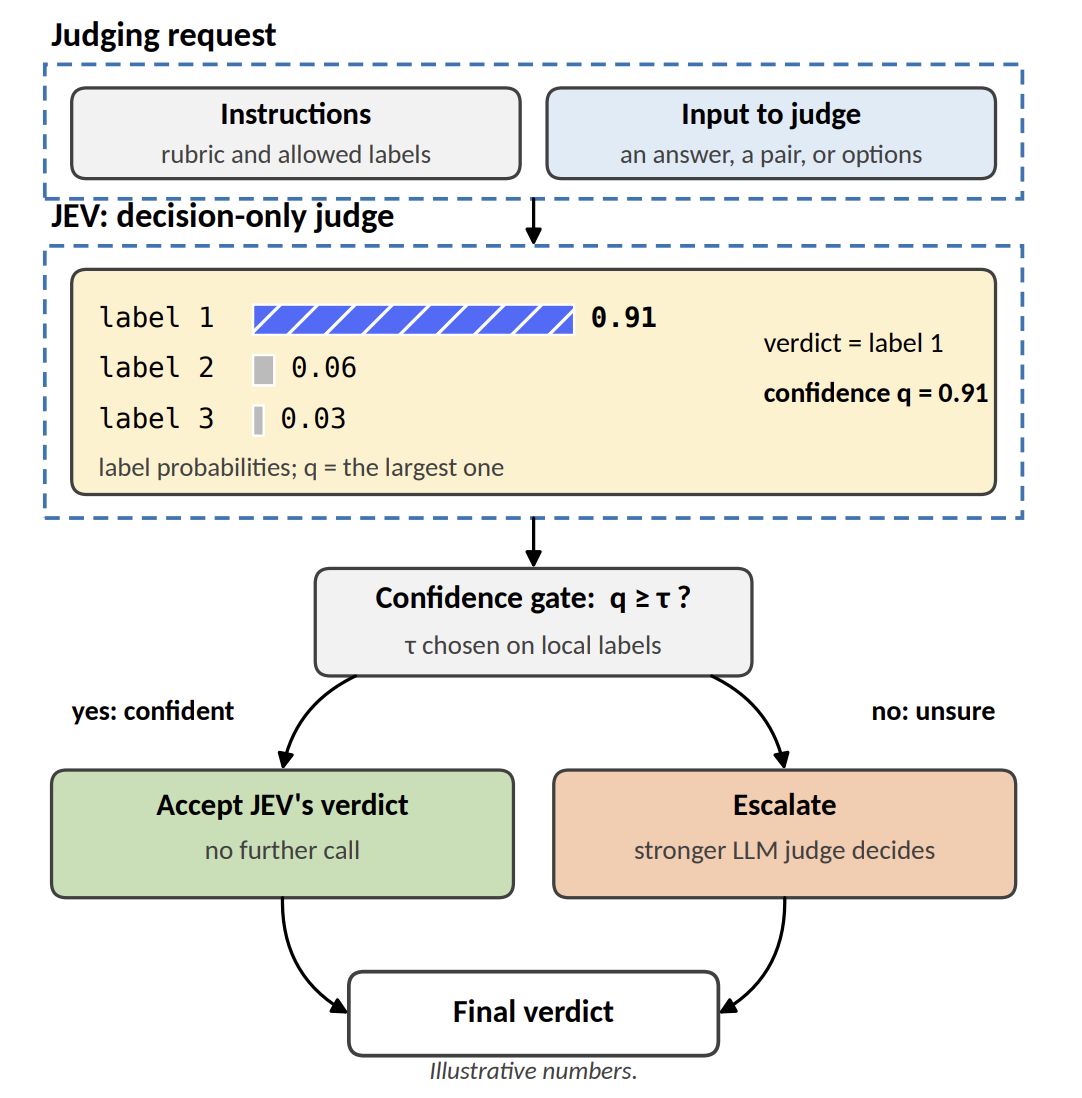
Now that we understand the pros and cons of Jev, let us finally consider a mechanism for automation. As highlighted in the research paper, the fundamental concept is: "Use Jev to triage samples to be evaluated, identify samples where Jev's judgment lacks high confidence, and forward them to a high-performance LLM." This triaging is performed based on the confidence score generated by Jev.

‍  ‍              Automation Process Using Jev

Specifically, it works as follows: Jev outputs the classification result along with confidence scores for each label. In this example, the confidence score is 0.91. With this level of certainty, Jev's output "Classification Label 1" can be accepted. However, if the confidence score is low, such as 0.6, it is better to route it to a powerful LLM and adopt the judgment from there. Furthermore, that threshold is configured based on the target labeled dataset. Through this approach, automation that eliminates the "Human in the loop" is achieved. It is truly remarkable.

‍  ‍              Automation Combining LLMs and Jev


What did you think? By combining LLMs with Jev, we can see a clear path to breaking through the barriers of computation speed and cost—the traditional drawbacks of LLMs—while maintaining accuracy.


Here at Toshi Stats, we intend to continue taking on the challenge of business automation through AI. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link.


1) Introducing System One Models & Jev,  Sep 15 2026, Diogo Almeida, founder, TypeSafe
2) JEV-as-a-Judge: Accept When Confident, Escalate When Unsure
Yubo Li, Yidi Miao. Ramayya Krishnan, Rema Padman
Carnegie Mellon University, Oct 9 2026

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.
Is the Era of True AI Automation Already Upon Us?

"Jev," a frontier model developed with business workflow automation in mind, has been released by TypeSafe AI (1) and has become a hot topic in the AI community. Rather than generating text like traditional LLMs, it is designed from the ground up to be used for classification and discriminative tasks aimed at decision-making. Today, I'd like to take a look at it right away and explore how it can be utilized in practical business operations.


1. Features of "Jev"

First, let’s take a look at TypeSafe AI's website:

TypeSafe AI is releasing our first System One Model: a new class of frontier models built to make fast, structured decisions that software can use directly.

Our first public model is Jev, available today in early access.

As stated, "fast, structured decisions" appears to be the key phrase. When considering workflow automation, the required output for each task is often not a paragraph of text, but rather a determination of "whether it meets specific requirements or not," along with a confidence score. For example, when a financial institution receives a document from a customer, it needs to determine whether it is a complaint. The outcome is a binary choice: "Complaint" or "Not a Complaint." Special handling is required only if it is classified as a "Complaint." No generated prose is needed in the output. In this way, "Jev" is a frontier model specialized for decision-making and is optimized for business process automation.

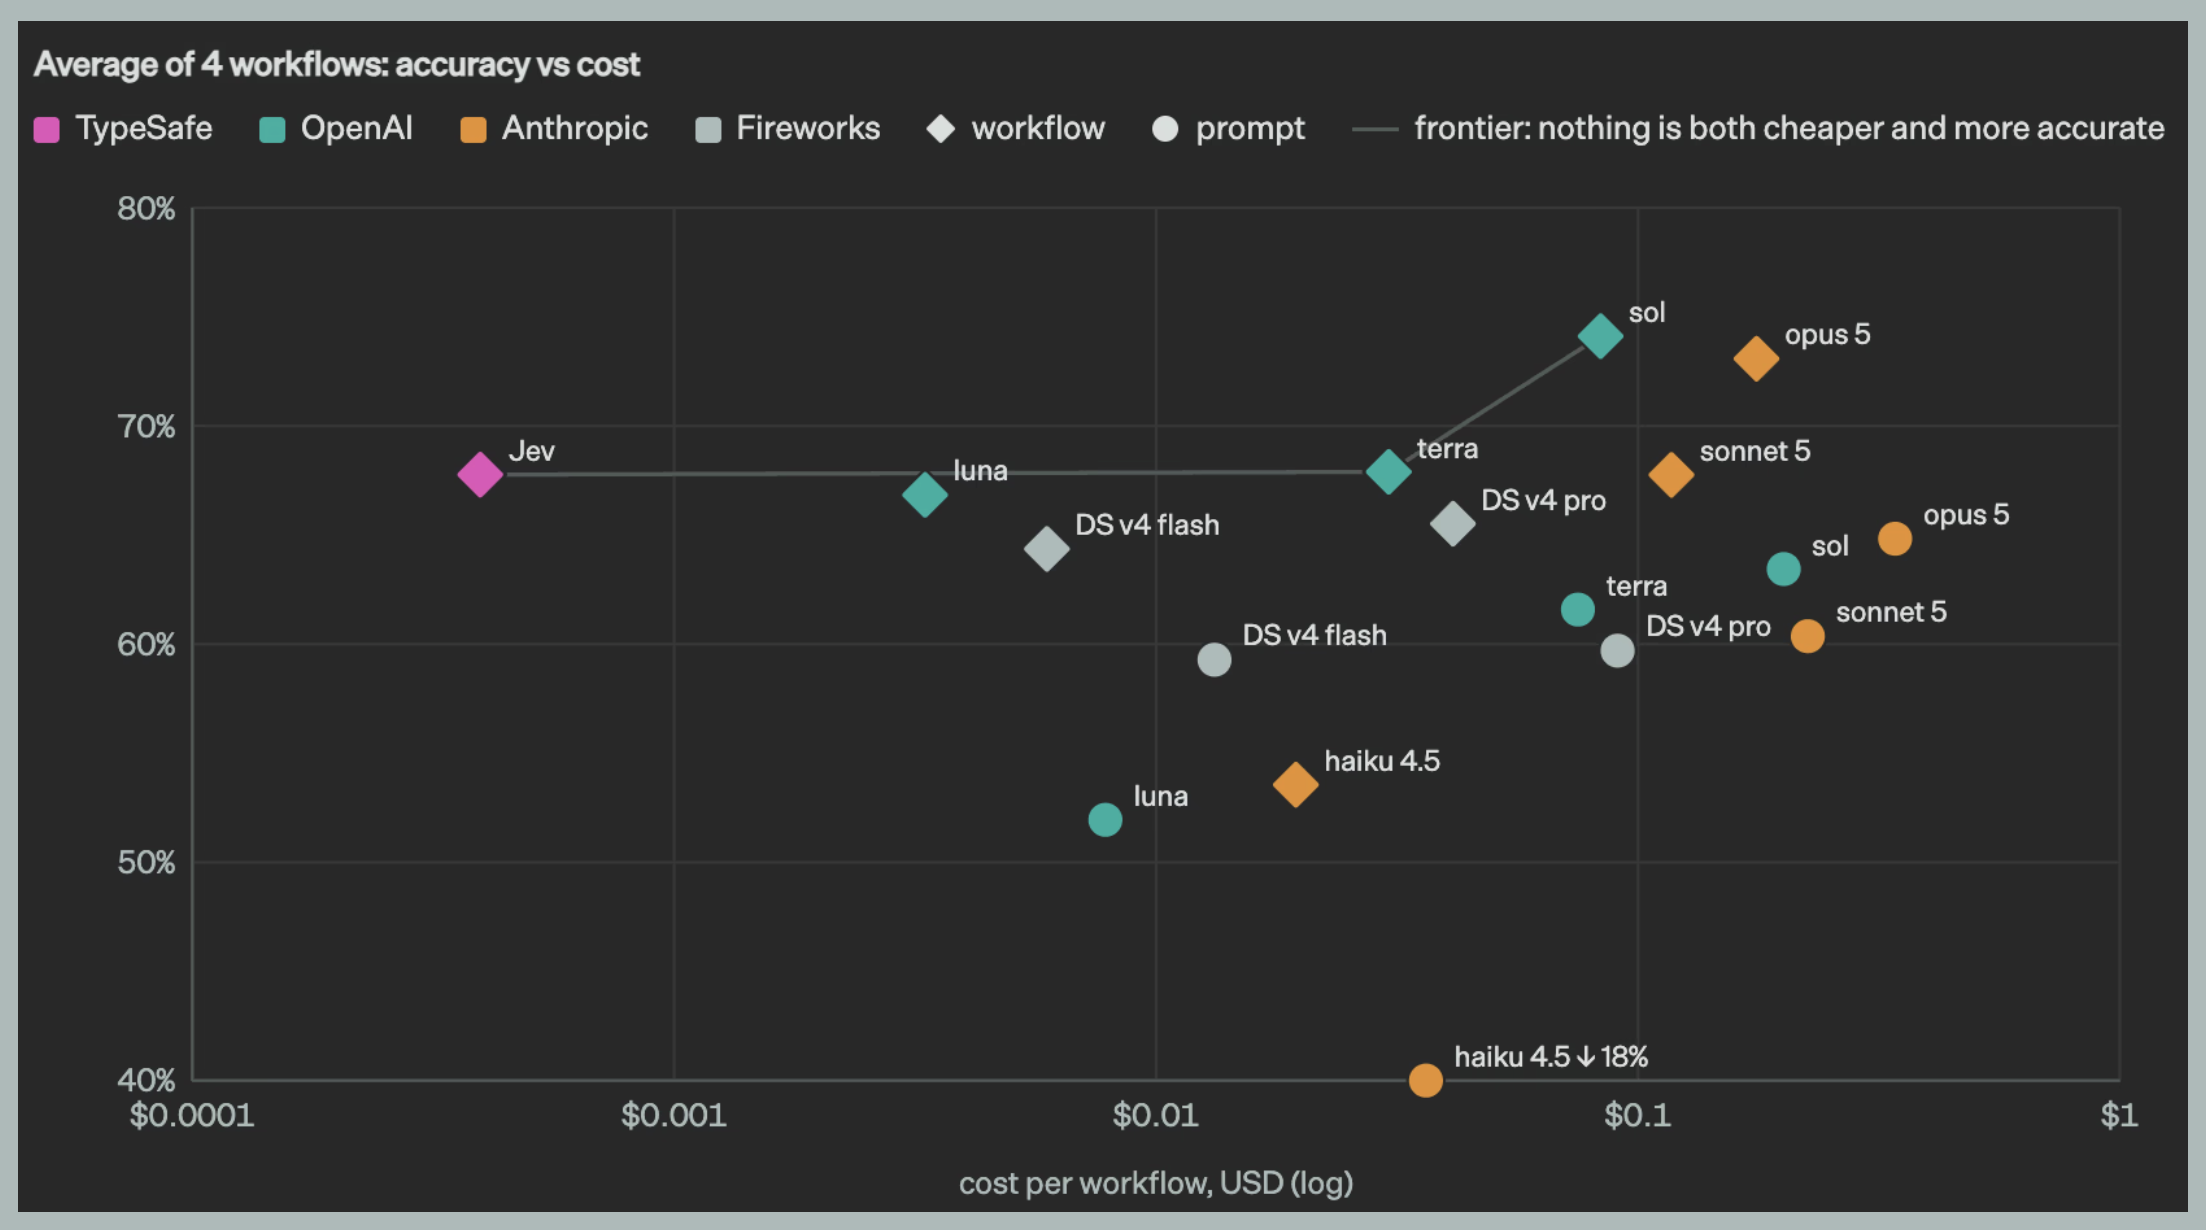
So, how accurate is "Jev"? TypeSafe AI ran several models, including "Jev," through identical workflows to evaluate how they perform compared to the average of the most capable models (in this case, Astra and Fable). Below is the comparison chart. You can see that "Jev" is positioned at the far top-left, indicating that it maintains high performance at a very low cost.

Accuracy and Cost


2. Reliability Is Key to Full Automation

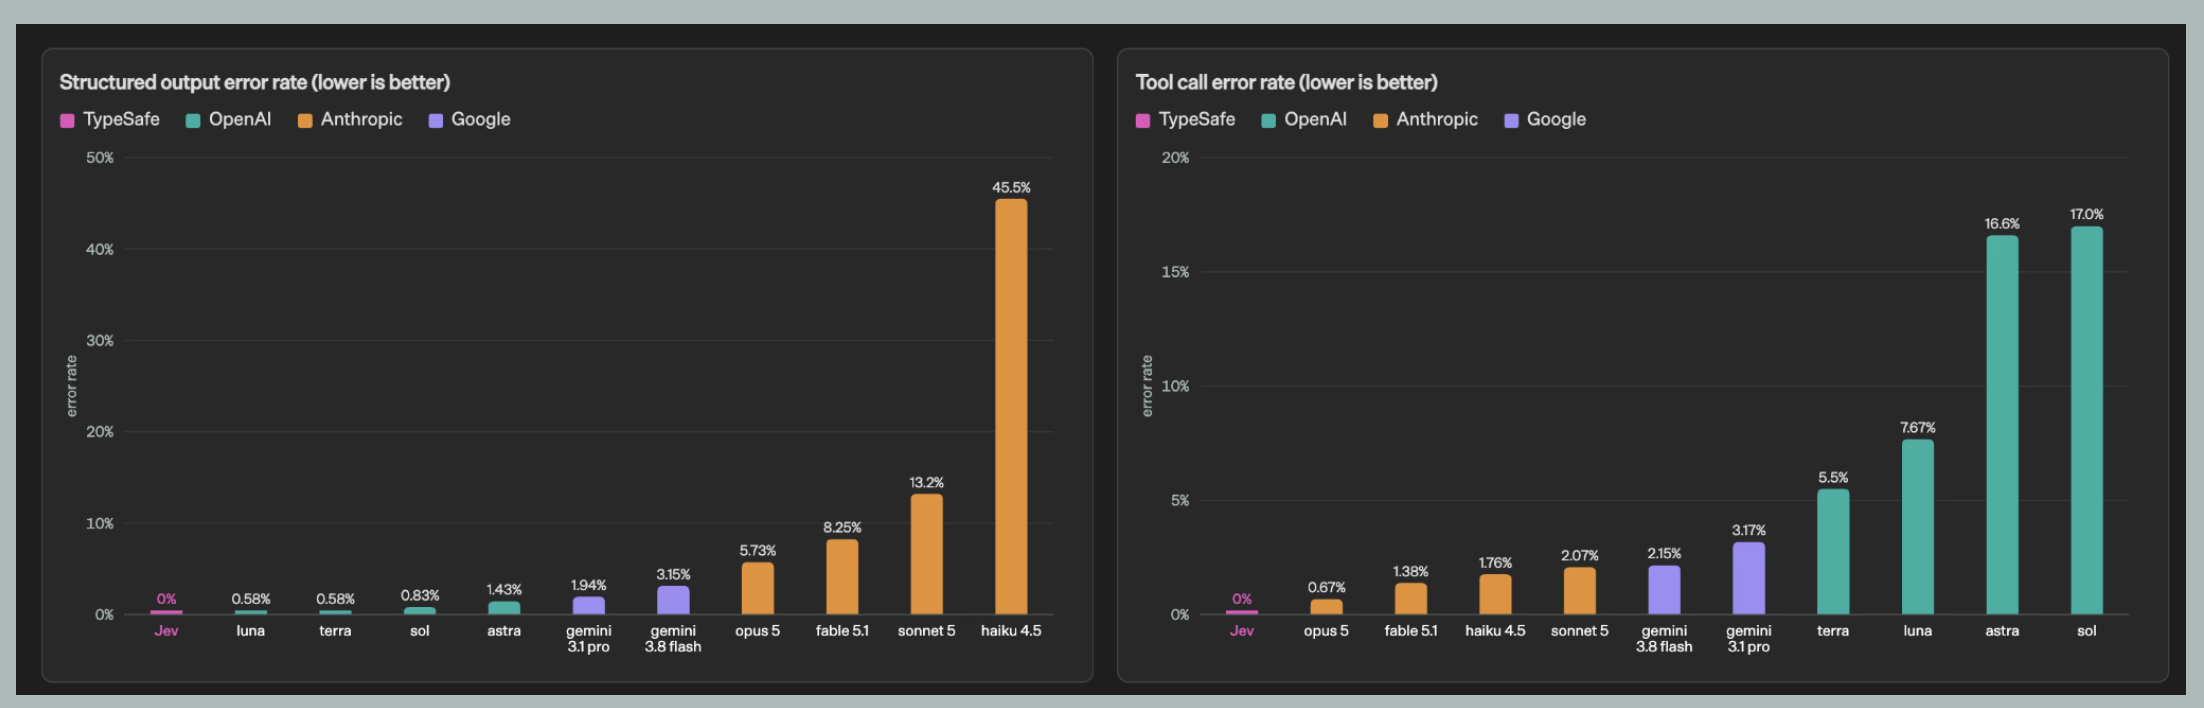
High performance at low cost makes it ideal for workflow automation. However, to achieve full automation without human intervention, the issue of "hallucinations" must be resolved. This refers to generative AI unintentionally producing false information. Although recent LLMs have seen improvements, hallucinations have not dropped to zero. As things stand, human review remains indispensable. TypeSafe AI claims that "Jev" can reduce errors to zero, as outlined below. The following note appears on TypeSafe AI’s website:

Our number is not empirical. Schema matching is guaranteed, thus we can confidently add 0% into the plots.

Error Rate Comparison

If this is true, it will be a game changer for workflow automation. Feedback and evaluations from various users will be eagerly anticipated going forward. It certainly looks promising.


3. Applying Workflow Automation to Any Scenario

Conventional workflow automation has traditionally been "rule-based," inevitably requiring human intervention whenever rules were ambiguous or judgment was necessary. "Jev," however, is a frontier model capable of making decisions autonomously. Furthermore, because it can also calculate confidence scores, uncertain judgments can be routed to humans. While approaches like "LLM as a judge" have previously delegated decisions to language models, human review was always mandatory, keeping a "Human-in-the-loop" structure strictly in place. With the arrival of "Jev," however, expectations for full automation are rising. Application examples of automation highlighted by TypeSafe AI include:

  • Recruiting

  • Lead generation

  • Customer support

  • Insurance claims

  • Financial crime

  • Legal and compliance

  • E-commerce marketplaces

  • Advertising

  • Risk assessment

  • Demand forecasting

...and more. It will be exciting to see how "Jev" evolves.


What do you think? This new type of frontier model could dramatically advance business process automation across enterprises. To close, I'd like to leave you with the words of TypeSafe AI:

“Think of Jev as a frontier-intelligence function call: unstructured state in, typed probabilistic decisions out.“

Here at Toshi Stats, we look forward to continuing our exploration of various applications for frontier models. Stay tuned!


You can enjoy our video news “ToshiStats AI Weekly Review” from this link, to

1) Introducing System One Models & Jev, August 15 2026, Diogo Almeida, founder, TypeSafe

Copyright © 2026 ToshiStats Co., Ltd. All right reserved.

Notice: This is for educational purpose only. ToshiStats Co., Ltd. and I do not accept any responsibility or liability for loss or damage occasioned to any person or property through using materials, instructions, methods, algorithms or ideas contained herein, or acting or refraining from acting as a result of such use. ToshiStats Co., Ltd. and I expressly disclaim all implied warranties, including merchantability or fitness for any particular purpose. There will be no duty on ToshiStats Co., Ltd. and me to correct any errors or defects in the report, the codes and the software.